G. DSGE Modeling with Python

Mind map of Appendix G: DSGE Modeling with Python

Open In Colab Open Lecture Slides

Learning goals

Chapter 15 showed what dynamic stochastic general equilibrium (DSGE) models say about business cycles. This appendix opens the machine. With Snowdrop, a free Python package written at the International Monetary Fund (Goumilevski and Otterson, 2025), you will write, solve, simulate and estimate DSGE models yourself. By the end of this appendix you will be able to:

  • explain what makes a model dynamic, stochastic and general equilibrium, and what it means to solve and to estimate one;
  • solve a model with rational expectations by hand, and say why it needs the Blanchard–Kahn condition;
  • read and write a Snowdrop model file, and simulate three models with it: the AS/AD model of Chapter 13, the monetary policy model of the Snowdrop paper, and a real business cycle model;
  • read impulse responses and contribution charts, and check that a numerical solution is right;
  • explain how the Kalman filter turns a model into a likelihood, and estimate a parameter by maximum likelihood with a few lines of NumPy;
  • estimate Ireland’s (2004) New Keynesian model on U.S. data by maximum likelihood and by Bayesian posterior mode, and judge how much the priors matter.

The appendix assumes Chapters 12, 13 and 15 and Appendices A and C. Everything else is explained as it comes.

A map of the appendix

Section What you do Model Snowdrop tools Builds on
G.1 Learn what DSGE models are and what estimating one means — — Chapters 12, 13, 15
G.2 Read the Snowdrop paper — an overview —
G.3 Install Snowdrop and set up — importModel Appendix A
G.4 Solve a model with expectations by hand one equation (NumPy, SciPy) Appendix C.9–C.10
G.5 Take a model file apart the paper’s model YAML files, importModel —
G.6 Write your first model file AS/AD run, plot Chapter 13
G.7 Replicate the paper’s Fig. 1 the paper’s model run, plotDecomposition Chapter 12
G.8 Simulate a real business cycle model RBC findSteadyStateSolution, random shocks Chapters 15–17
G.9 Build a Kalman filter AR(1) plus noise (NumPy) Appendix C.13
G.10 Estimate one parameter by maximum likelihood AR(1) plus noise (SciPy) —
G.11 Estimate a New Keynesian model by maximum likelihood Ireland (2004) estimate Chapters 12, 13, 15
G.12 Add priors: the Bayesian posterior mode Ireland (2004) estimate —
G.13 Go further — sampling, smoothing, other models Appendix B

G.1 What a DSGE model is, and what estimating one means

Each word of the name says something about the model.

  • Dynamic. Decisions link the periods. Households save today to consume tomorrow, firms invest today to produce tomorrow, and what people expect about the future changes what they do today.
  • Stochastic. Random shocks hit the economy: to productivity, to preferences, to the costs of firms, to monetary policy. The shocks are what make the economy fluctuate; without them it would sit in its steady state.
  • General equilibrium. All markets clear at once, and every household’s and firm’s plans are consistent with each other and with the resource constraint of the economy.

The ingredients

A DSGE model is a list of equations. Most of them come from one of five ingredients:

  1. Optimizing households and firms. The Euler equation for consumption (Chapter 16), the demand for capital (Chapter 17) and price setting by firms are first-order conditions of optimization problems.
  2. Expectations. Today’s choices depend on what people expect tomorrow. DSGE models assume rational expectations: people’s forecasts are the model’s own forecasts, so they make no systematic mistakes.
  3. Constraints and market clearing. Output is consumed or invested; the capital stock carries over from one period to the next.
  4. Shocks. Each shock follows a simple random process, usually an AR(1): \(z_t=\rho z_{t-1}+\varepsilon_t\).
  5. Policy rules. The central bank follows a rule for the interest rate, like the rule of Chapter 13.

To solve the model is to find decision rules: formulas that give every variable today as a function of the past (the state of the economy) and of today’s shocks. With the decision rules we can simulate the economy for any sequence of shocks.

From equations to numbers: the workflow

Step What happens In this appendix
1. Write equations, variables, shocks and parameters go into a model file G.5, G.6
2. Calibrate choose parameter values from long-run facts and other studies G.6–G.8
3. Steady state find the values that the model settles at when no shocks hit G.8
4. Solve find the decision rules (linear models) or the whole path (nonlinear models) G.4, G.7, G.8
5. Simulate impulse responses, scenarios, contribution charts G.6–G.8
6. Take to data write the solution in state-space form; the Kalman filter gives the likelihood G.9–G.11
7. Estimate choose the parameters that make the data most likely, with or without priors G.10–G.12

Calibration versus estimation

There are two ways to choose the parameters. Calibration, the approach of the real business cycle school (Chapter 15), takes each value from outside evidence: the capital share from the national accounts, the discount factor from average interest rates. Estimation lets the model’s own time series pick the values: the parameters that make the observed data most likely win (maximum likelihood). Bayesian estimation combines the two: outside evidence enters as a prior distribution for each parameter, and the data update it. Most central banks estimate their DSGE models this way (Smets and Wouters, 2007; Del Negro et al., 2013).

The toolboxes

Economists rarely code solvers from scratch. Three toolboxes dominate: Dynare (free, runs on MATLAB or the free Octave), IRIS (free, runs on MATLAB) and TROLL (commercial). MATLAB itself is commercial software. A Python package removes the license cost and connects DSGE modeling to the data tools of Appendices A and B. That is the gap Snowdrop wants to fill.

G.2 The Snowdrop paper

The paper is Goumilevski, A., and Otterson, J. (2025), “Snowdrop: Python Package for DSGE Modeling,” Journal of Open Source Software 10(112), 8197 (doi:10.21105/joss.08197). The code is on GitHub at gumilevskij/Framework. Both authors work at the International Monetary Fund. The Journal of Open Source Software (JOSS) publishes short papers about research software: the paper is a summary, and the software itself goes through peer review (installation, documentation, tests). The details are in the package’s 56-page User Guide and its notes on numerical algorithms, which come with the code.

Why Snowdrop exists

The paper’s statement of need makes four points:

  • DSGE models are a basic tool of central banks for monetary policy and forecasting (it cites work at the IMF, the ECB, the Federal Reserve Bank of New York and the Japanese Ministry of Finance).
  • Python, for all its scientific libraries, lacked an integrated DSGE toolbox.
  • Each existing toolbox has a strength: Dynare is easy to use but handles only stationary models, so users must rewrite growing variables as ratios; IRIS handles non-stationary models; TROLL solves very large systems. But all of them are commercial or run on commercial software.
  • Snowdrop is free (GNU General Public License) and handles a wide range of models. Benchmarked against Dynare and IRIS on models with several hundred equations, it runs about as fast and needs less memory.

What the package does

Feature In Snowdrop Where you meet it
Model files human-readable YAML; also Python scripts, Dynare, IRIS and Sirius XML files G.5–G.8, G.11
Nonlinear models perfect-foresight paths by Newton’s method: the stacked ABLR method and the forward–backward LBJ method (Juillard et al., 1998) G.4, G.7, G.8
Linear models Binder–Pesaran, Anderson–Moore, and two generalized Schur methods that reproduce Dynare and IRIS G.8, G.11
Time-varying parameters a parameter can follow a path G.5
Estimation maximum likelihood, and a Bayesian version with priors G.11, G.12
Sampling Markov chain Monte Carlo: the emcee ensemble sampler of Goodman and Weare, and adaptive Metropolis–Hastings G.13
Filters Kalman (several versions), unscented Kalman, particle, Hodrick–Prescott, band-pass G.9–G.11
Output plots, contribution charts, Excel and SQLite files throughout

It runs on Windows, macOS and Linux, on CPUs and, through the CuPy library, on GPUs.

The paper’s three examples

  1. A monetary policy model with four equations: a Phillips curve, a real interest rate, a policy rule and an IS curve. The paper prints its model file and, in its Fig. 1, the forecast of inflation, the real and nominal interest rates and the output gap after a 2 percent output shock in period 1 and a 3 percentage point revision of the policy rate in period 4, split into the contribution of each term. Section G.7 replicates Fig. 1.
  2. Ireland’s (2004) New Keynesian model, estimated on U.S. data. Sections G.11 and G.12 estimate it.
  3. The Eichenbaum–Rebelo–Trabandt (2020) model of the macroeconomics of epidemics, with two strains of a virus, sticky- and flexible-price economies linked by a Taylor rule, and 64 equations. It is highly nonlinear, and Snowdrop solves it by a homotopy: it moves the parameters step by step from an easy case to the real one. The paper’s Figs. 2 and 3 forecast infections, deaths and the economy for 2020–2022. This model is too big for an introduction; Section G.13 tells you where its files are.

How the paper runs a model

The paper gives three steps: write or edit a YAML model file, open the test script tests/test_toy_models.py and set fname to the file’s name, then run the script. In a notebook we do the same with two functions: importModel reads the file, and run solves and simulates the model.

Reading research software with care

A short paper cannot document everything, and research code changes faster than its documentation. As we go, we will meet a few places where the paper, the User Guide and the code disagree, or where a function needs help. None of them is serious, but each one teaches the habit that matters most in computational economics: check every result. Compare it with a case you can solve by hand, look at the residuals of the equations, and try more than one starting point. The appendix shows how.

G.3 Setup

Installing Snowdrop

Snowdrop is not part of Colab, so we install it. One detail matters. The package asks for old versions of NumPy (1.26) and SciPy (1.11), which do not exist for Colab’s Python 3.13: a plain install would fail. Everything this appendix uses runs on Colab’s own, newer NumPy and SciPy, so we install Snowdrop without its version requirements (--no-deps), together with the three small libraries it needs and Colab lacks: particles (probability distributions), ruamel.yaml (it reads YAML files; Snowdrop needs version 0.17.21) and that library’s C helper. We install a fixed version of Snowdrop: the GitHub commit of 3 October 2026, which corrected the standard errors of estimated parameters. The install takes about 20 seconds. pip then prints a note that you may need to restart the kernel; you do not, because the install changes nothing that Colab has already loaded.

Python note. %pip install is a notebook command, not Python: it installs packages into the computer that runs the notebook. -q keeps it quiet, and --no-deps installs exactly the packages named, nothing else. A GitHub address ending in .tar.gz is a compressed copy of the code at one commit.

# Snowdrop at the commit of 3 October 2026, without its old NumPy/SciPy pins, plus three small libraries
%pip install -q --no-deps "https://github.com/gumilevskij/Framework/archive/47a63b2b780e1876898229c09f7f1e8644462692.tar.gz"
%pip install -q --no-deps particles==0.4 "ruamel.yaml==0.17.21" ruamel.yaml.clib
Note: you may need to restart the kernel to use updated packages.

Libraries and the work folder

Snowdrop writes files next to each model file it reads (a cache of the parsed model) and into an output folder. We keep all of that in one work folder, dsge. Two lines need a word of explanation. Snowdrop first tries the GPU library CuPy; we tell Python that CuPy is not available, so Snowdrop always uses the CPU. And importing Snowdrop moves Python into Snowdrop’s own folder, so we move back to ours right after.

# Libraries used in this appendix
import os, sys, io, re, shutil, contextlib
import numpy as np                          # numbers and arrays
import pandas as pd                         # data tables
import matplotlib.pyplot as plt             # Snowdrop's charts, and ours
from scipy import optimize, stats           # numerical solvers and probability distributions
from IPython.display import HTML, display

sys.modules["cupy"] = None                  # no GPU library: Snowdrop uses the CPU
WORK = os.path.abspath("dsge")              # our work folder: model files, data, Snowdrop's output
os.makedirs(WORK, exist_ok=True)
os.environ["PLATFORM_OUTPUT_FOLDER"] = os.path.join(WORK, "output")

import snowdrop.src                         # importing Snowdrop moves Python into its own folder ...
from snowdrop.src import driver             # driver: importModel, run, estimate, ...
from snowdrop.src.graphs.util import plot, plotDecomposition
os.chdir(WORK)                              # ... so we move back to ours
print("Working in:", os.getcwd())
Working in: /Users/carlosmendez/Documents/GitHub/macro102/.work/appG/run/dsge

Snowdrop comes with example models and data. We copy the files we need into the work folder, so that Snowdrop’s cache files land there too.

SUPP = os.path.join(os.path.dirname(snowdrop.src.__file__), "..", "..", "supplements")
SUPP = os.path.abspath(SUPP)                # Snowdrop's example models and data
print("Example models:", sorted(os.listdir(os.path.join(SUPP, "models", "TOY"))))

for name in ["JLMP98.yaml", "RBC.yaml", "RBC1.yaml", "Ireland2004.yaml"]:
    shutil.copy(os.path.join(SUPP, "models", "TOY", name), WORK)
shutil.copy(os.path.join(SUPP, "data", "gpr_1948.csv"), WORK)
print("Copied to the work folder:", sorted(os.listdir(WORK)))
Example models: ['Ireland2004.yaml', 'JLMP98.yaml', 'MVF_US.yaml', 'RBC.model', 'RBC.yaml', 'RBC1.yaml']
Copied to the work folder: ['Ireland2004.yaml', 'JLMP98.yaml', 'RBC.yaml', 'RBC1.yaml', 'gpr_1948.csv', 'graphs', 'output']

The book’s chart style, in light and dark

Snowdrop draws its charts with matplotlib. The four helper cells below give every chart of this appendix, Snowdrop’s and ours, the colors of the book, and save each chart twice: a light version (Colab, and the website’s light theme) and a dark version (the website’s dark theme). You do not need to read them. You only use four functions:

  • show(fig, "a description") shows a chart; add snowdrop=True for a chart that Snowdrop drew;
  • load_model(file) reads a model file quietly (load_model(file, verbose=True) prints Snowdrop’s report);
  • simulate(model) solves and simulates a model quietly and returns a table;
  • set_values(model, "parameters", {...}) changes values in a model.
Show the helper code
# @title Helper code: the book's colors, and their versions for the dark theme
import math, base64, matplotlib, matplotlib.collections, matplotlib.patches
from matplotlib.colors import to_rgba, to_hex
BLUE, TEAL, GREEN, GRAY, ORANGE, RUST = "#16528c", "#008070", "#7fb23a", "#8a96a3", "#e0a33b", "#c4651a"
SERIES = [BLUE, "#5aa0d8", TEAL, GREEN, ORANGE, "#b04a5a", "#8e5ea2", GRAY, RUST, "#0b4f47"]
INK, GRID, AXIS, TOTAL, NAVY = "#2a3f5f", "#e3e9f1", "#b8c4d2", "#1b2733", "#06253e"
DARK = {"#16528c": "#5eb1f2", "#008070": "#3dd6c4", "#7fb23a": "#a6d85b", "#8a96a3": "#97a9bd",
        "#5aa0d8": "#a9d3f7", "#0b4f47": "#22a08d", "#e0a33b": "#f2c14e", "#c4651a": "#f08c4a",
        "#b04a5a": "#f07a8c", "#8e5ea2": "#c39be0", INK: "#d8e3ee", TOTAL: "#e6edf5",
        "#000000": "#e6edf5", "#ffffff": NAVY}

def _lin(v): return v / 12.92 if v <= 0.04045 else ((v + 0.055) / 1.055) ** 2.4
def _gam(v): return min(1.0, max(0.0, 12.92 * v if v <= 0.0031308 else 1.055 * v ** (1 / 2.4) - 0.055))
def oklab(rgb):
    r, g, b = (_lin(x) for x in rgb[:3])
    l, m, s = [(u * r + v * g + w * b) ** (1 / 3) for u, v, w in ((0.4122214708, 0.5363325363, 0.0514459929),
               (0.2119034982, 0.6806995451, 0.1073969566), (0.0883024619, 0.2817188376, 0.6299787005))]
    return (0.2104542553 * l + 0.7936177850 * m - 0.0040720468 * s,
            1.9779984951 * l - 2.4285922050 * m + 0.4505937099 * s,
            0.0259040371 * l + 0.7827717662 * m - 0.8086757660 * s)
def from_oklab(L, A, B):
    for k in np.arange(1.0, -0.01, -0.05):                     # lower the chroma until the color fits sRGB
        a, b = A * k, B * k
        l, m, s = (L + 0.3963377774 * a + 0.2158037573 * b) ** 3, (L - 0.1055613458 * a - 0.0638541728 * b) ** 3, \
                  (L - 0.0894841775 * a - 1.2914855480 * b) ** 3
        rgb = (4.0767416621 * l - 3.3077115913 * m + 0.2309699292 * s, -1.2684380046 * l + 2.6097574011 * m
               - 0.3413193965 * s, -0.0041960863 * l - 0.7034186147 * m + 1.7076147010 * s)
        if k < 0.05 or all(-0.002 < v < 1.002 for v in rgb):
            return tuple(_gam(v) for v in rgb)
NAVY_LAB = oklab(to_rgba(NAVY))
def dark_color(c, role="ink"):
    """The dark-theme version of a color: the same rules as the website's Plotly charts."""
    r, g, b, a = to_rgba(c)
    if a == 0:
        return (r, g, b, a)
    L, A, B = oklab((r, g, b)); chroma = math.hypot(A, B); hexc = to_hex((r, g, b))
    if role == "rule" and chroma >= 0.035: role = "ink"
    if role == "ink" and hexc in DARK:
        return to_rgba(DARK[hexc], a * 0.85 if a < 1 else 1)
    if chroma < 0.035 or (role != "ink" and L > 0.6):          # neutrals: swap light and dark
        hi, lo = (0.78 if role == "rule" else 0.93), (NAVY_LAB[0] + 0.08 if role == "ink" and L < 0.985 else NAVY_LAB[0])
        L2 = hi - (hi - lo) * L; f = max(0.0, (1 - L2) / (1 - NAVY_LAB[0]))
        A, B = A * 0.6 + NAVY_LAB[1] * f, B * 0.6 + NAVY_LAB[2] * f
    else:
        L2 = 0.66 + L * 0.175 if (role == "ink" and L < 0.8) else L   # lift dark ink above the navy
    return (*from_oklab(L2, A, B), a * 0.85 if (role == "ink" and a < 1) else a)
Show the helper code
# @title Helper code: restyle a chart (Snowdrop's colors to the book's; light to dark)
def recolor(fig, fn):
    """Apply fn(color, role) to every color of a matplotlib figure; role is paper, rule or ink."""
    fig.patch.set_facecolor(fn(fig.patch.get_facecolor(), "paper"))
    for t in fig.texts: t.set_color(fn(t.get_color(), "ink"))
    for ax in fig.axes:
        ax.set_facecolor(fn(ax.get_facecolor(), "paper"))
        for sp in ax.spines.values(): sp.set_edgecolor(fn(sp.get_edgecolor(), "rule"))
        for axis in (ax.xaxis, ax.yaxis):
            for gl in axis.get_gridlines(): gl.set_color(fn(gl.get_color(), "rule"))
            for lab in axis.get_ticklabels(which="both"): lab.set_color(fn(lab.get_color(), "ink"))
            axis.label.set_color(fn(axis.label.get_color(), "ink"))
            axis.set_tick_params(which="both", color=fn(AXIS, "rule"))
        for t in [ax.title, ax._left_title, ax._right_title] + ax.texts: t.set_color(fn(t.get_color(), "ink"))
        for ln in ax.lines:
            role = "rule" if ln.get_gid() == "rule" else "ink"
            ln.set_color(fn(ln.get_color(), role))
            ln.set_markerfacecolor(fn(ln.get_markerfacecolor(), role)); ln.set_markeredgecolor(fn(ln.get_markeredgecolor(), role))
        for p in ax.patches:
            p.set_facecolor(fn(p.get_facecolor(), "ink")); p.set_edgecolor(fn(p.get_edgecolor(), "ink"))
        for col in ax.collections:
            col.set_facecolors([fn(c, "ink") for c in col.get_facecolors()])
            col.set_edgecolors([fn(c, "ink") for c in col.get_edgecolors()])
        leg = ax.get_legend()
        if leg is not None:
            leg.get_frame().set_facecolor(fn(leg.get_frame().get_facecolor(), "paper"))
            leg.get_frame().set_edgecolor(fn(leg.get_frame().get_edgecolor(), "rule"))
            for t in leg.get_texts(): t.set_color(fn(t.get_color(), "ink"))
            for h in leg.legend_handles:
                if isinstance(h, matplotlib.lines.Line2D):
                    h.set_color(fn(h.get_color(), "ink"))
                    h.set_markerfacecolor(fn(h.get_markerfacecolor(), "ink")); h.set_markeredgecolor(fn(h.get_markeredgecolor(), "ink"))
                elif isinstance(h, matplotlib.collections.Collection):
                    h.set_facecolors([fn(c, "ink") for c in h.get_facecolors()])
                    h.set_edgecolors([fn(c, "ink") for c in h.get_edgecolors()])
                elif isinstance(h, matplotlib.patches.Patch):
                    h.set_facecolor(fn(h.get_facecolor(), "ink")); h.set_edgecolor(fn(h.get_edgecolor(), "ink"))
Show the helper code
# @title Helper code: Snowdrop's colors to the book's colors
def to_book_colors(fig):
    """Snowdrop's colors -> the book's: black lines stay dark, red data dots become rust, others follow SERIES."""
    seen = {}
    def book(c, role):
        r, g, b, a = to_rgba(c); L, A, B = oklab((r, g, b)); chroma = math.hypot(A, B)
        if role == "paper": return to_rgba("white")
        if role == "rule": return to_rgba(GRID if L > 0.7 else AXIS)
        if chroma < 0.035: return to_rgba(TOTAL if L < 0.3 else (INK if L < 0.6 else "white"), a)
        if r > 0.9 and g < 0.15 and b < 0.15: return to_rgba(RUST, a)
        key = to_hex((r, g, b))
        if key not in seen: seen[key] = SERIES[len(seen) % len(SERIES)]
        return to_rgba(seen[key], a)
    recolor(fig, book)
    for ax in fig.axes:
        ax.grid(True, color=GRID, linewidth=0.8); ax.set_axisbelow(True)
        for p in ax.patches: p.set_edgecolor("white"); p.set_linewidth(0.6)
        leg = ax.get_legend()
        if leg is not None:
            for h in leg.legend_handles:
                if isinstance(h, matplotlib.patches.Patch): h.set_edgecolor("white")
Show the helper code
# @title Helper code: draw a chart in the book's style, and show it in both themes
BOOK_RC = {"figure.facecolor": "white", "axes.facecolor": "white", "axes.edgecolor": AXIS, "axes.labelcolor": INK,
           "axes.grid": True, "grid.color": GRID, "grid.linewidth": 0.8, "axes.spines.top": False,
           "axes.spines.right": False, "xtick.color": INK, "ytick.color": INK, "text.color": INK,
           "axes.titlesize": 13, "axes.titleweight": "normal", "axes.labelsize": 11, "legend.frameon": False,
           "axes.prop_cycle": matplotlib.cycler(color=SERIES), "lines.linewidth": 2.2, "font.size": 11}

def book_figure(rows=1, cols=1, width=8.6, height=4.6):
    """A new matplotlib figure in the book's style (Snowdrop's plots change the global style, so reset it)."""
    plt.rcdefaults(); plt.rcParams.update(BOOK_RC)
    fig, axes = plt.subplots(rows, cols, figsize=(width, height), squeeze=False)
    return fig, (axes[0, 0] if rows * cols == 1 else axes.ravel())

def _png(fig):
    buf = io.BytesIO()
    fig.savefig(buf, format="png", dpi=110, facecolor=fig.get_facecolor(), bbox_inches="tight")
    return base64.b64encode(buf.getvalue()).decode()

def show(fig, alt, snowdrop=False):
    """Show a chart twice, light and dark; the website picks the one that matches its theme."""
    if snowdrop:
        to_book_colors(fig)
    light = _png(fig)
    recolor(fig, dark_color)
    dark = _png(fig)
    plt.close(fig)
    alt = alt.replace('"', "'")
    display(HTML(f'<div class="book-mpl"><img class="book-mpl-light" alt="{alt}" src="data:image/png;base64,{light}">'
                 f'<img class="book-mpl-dark" alt="{alt}" style="display:none" src="data:image/png;base64,{dark}"></div>'))
Show the helper code
# @title Helper code: run Snowdrop quietly, change model values, read its estimation tables
import snowdrop.src.numeric.estimation.estimate as sd_estimate
os.chdir(WORK)                                    # this import also moves Python into Snowdrop's folder
ANSI = re.compile(r"\x1b\[[0-9;]*m")              # Snowdrop prints colored text; we strip the colors

def quietly(function, *args, **kwargs):
    """Call a Snowdrop function and keep its printout; return (result, text)."""
    buf = io.StringIO()
    with contextlib.redirect_stdout(buf):
        result = function(*args, **kwargs)
    return result, ANSI.sub("", buf.getvalue())

def load_model(file, verbose=False, **options):
    """Read a model file with importModel; print Snowdrop's report only if verbose."""
    model, text = quietly(driver.importModel, fname=os.path.join(WORK, file), **options)
    if verbose:
        print(text.strip())
    return model

def simulate(model, **options):
    """Solve and simulate a model with run(); return a table, one row per period, one column per variable."""
    (y, dates), text = quietly(driver.run, model=model, Plot=False, **options)
    y = np.asarray(y)
    return pd.DataFrame(y[:len(dates)], index=dates, columns=model.symbols["variables"])

def set_values(model, kind, values):
    """Change parameters or starting values: kind is 'parameters' or 'variables', values a dict name -> number."""
    names = model.symbols[kind]
    new = np.array(model.calibration[kind], dtype=float)  # Snowdrop's arrays are read-only: change a copy
    for name, value in values.items():
        new[names.index(name)] = value
    model.calibration[kind] = new

def estimate(model, **options):
    """Run Snowdrop's estimate() quietly; print its results table and return it as a DataFrame, with the output."""
    sd_estimate.est_shocks_names.clear()          # Snowdrop keeps a list here between runs; start afresh
    out, text = quietly(driver.estimate, model=model, Output=False, Plot=False, **options)
    start = text.find("Estimation\n+")
    print(text[text.rfind("\n", 0, start - 30) + 1: text.find("Estimation time")].strip())
    rows = re.findall(r"\|\s*(\w+)\s*\|\s*([-0-9.e]+)\s*\|\s*([-0-9.e]+)\s*\|\s*([-0-9.e]+)\s*\|", text)
    table = pd.DataFrame(rows, columns=["parameter", "start", "estimate", "std. error"]).set_index("parameter")
    table = table.astype(float)
    table.attrs["log value"] = float(re.findall(r"function value: ([-0-9.]+)", text)[-1])
    return table, out

G.4 Rational expectations from small pieces

Before Snowdrop does it for us, let us solve the smallest possible model with expectations by hand. It shows what “solving a DSGE model” means, and why a solution exists and is unique.

A model with one equation

Take the New Keynesian Phillips curve of Ireland’s model in Section G.11, stripped to its core:

\[x_t = a\,\mathbb{E}_t[x_{t+1}] + b\,z_t, \qquad (G.1)\]

\[z_t = \rho\, z_{t-1} + \varepsilon_t. \qquad (G.2)\]

Read \(x_t\) as inflation and \(z_t\) as a cost shock that fades at rate \(\rho\). Inflation today depends on the shock today and on the inflation that people expect for tomorrow; \(a\) is close to 1 (it is the discount factor of price setters), and \(b\) is the slope of the curve. The problem is that tomorrow’s inflation depends on the day after, and so on forever: today’s inflation depends on all expected future shocks.

Guess and verify. Since only \(z_t\) moves the economy, guess that inflation is proportional to it: \(x_t=\phi\,z_t\). Then \(\mathbb{E}_t[x_{t+1}]=\phi\,\mathbb{E}_t[z_{t+1}]=\phi\rho z_t\), and equation (G.1) becomes \(\phi z_t = a\phi\rho z_t + b z_t\). This holds for every \(z_t\) only if

\[\phi = \frac{b}{1-a\rho}. \qquad (G.3)\]

The guess works, and (G.3) is the decision rule. A shock that lasts longer (larger \(\rho\)) moves inflation more, because price setters expect it to raise their costs for longer.

We use teaching values: \(a=0.9\), \(b=0.14\) and \(\rho=0.8\), so that \(\phi=0.5\). A shock of 1 hits in period 1, and after that the economy is left alone. With no more shocks, the expectation of tomorrow is simply tomorrow, so we can check (G.1) period by period.

a, b, rho = 0.9, 0.14, 0.8           # discount factor, slope, persistence of the cost shock
phi = b / (1 - a * rho)              # equation (G.3)
T = 30
z = np.zeros(T + 1)                  # periods 0, 1, ..., 30
z[1] = 1.0                           # a cost shock of 1 in period 1
for t in range(2, T + 1):
    z[t] = rho * z[t - 1]            # equation (G.2) with no new shocks
x = phi * z                          # the decision rule

residual = x[1:T] - a * x[2:T + 1] - b * z[1:T]  # equation (G.1), period by period
print(f"phi = b / (1 - a rho) = {phi:.3f}")
print(f"largest error in equation (G.1): {np.abs(residual).max():.1e}")
phi = b / (1 - a rho) = 0.500
largest error in equation (G.1): 5.6e-17
fig, ax = book_figure()
ax.plot(range(T + 1), z, color=GRAY, linestyle="--", label="cost shock $z_t$")
ax.plot(range(T + 1), x, color=BLUE, marker="o", markersize=4, label="inflation $x_t = \\phi z_t$")
ax.set_title("A cost shock and the inflation it causes")
ax.set_xticks(range(0, T + 1, 5))
ax.set_xlabel("period")
ax.legend()
show(fig, "Inflation follows the cost shock at half its size and fades at the same rate")
Inflation follows the cost shock at half its size and fades at the same rate

What to notice. Inflation jumps in period 1 and then fades at the rate of the shock, always at half its size (\(\phi=0.5\)). Nothing else moves inflation: the decision rule has turned a forward-looking equation into a simple formula.

Why the solution is unique: stable and unstable paths

The decision rule is not the only path that satisfies (G.1) each period. Write the equation forward: \(x_{t+1}=(x_t-b\,z_t)/a\). Suppose inflation starts a little off the rule, by a gap \(d_1=x_1-\phi z_1\). Subtracting the rule from both sides gives

\[d_{t+1} = \frac{1}{a}\,d_t. \qquad (G.4)\]

Because \(a<1\), the factor \(1/a\) is larger than 1: any gap explodes. Of all the paths that satisfy (G.1), only the one with no gap stays bounded. Inflation is a jump variable: nothing ties it to the past, so it jumps in period 1 to the one value that keeps the economy on the stable path. This is the Blanchard–Kahn condition in its simplest form. A linear model has a unique stable solution when the number of unstable roots (here \(1/a>1\)) equals the number of jump variables (here one: \(x_t\)). Snowdrop counts both for every model it solves (Section G.5).

fig, ax = book_figure()
gaps = [-0.1, -0.05, 0.0, 0.05, 0.1]          # how far inflation starts from the decision rule
for d in gaps:
    path = np.zeros(T + 1)
    path[1] = phi * z[1] + d
    for t in range(1, T):
        path[t + 1] = (path[t] - b * z[t]) / a  # equation (G.1) solved for next period's inflation
    if d == 0:
        ax.plot(range(1, T + 1), path[1:], color=BLUE, linewidth=3, label="the decision rule (gap 0)")
    else:
        ax.plot(range(1, T + 1), path[1:], color=GRAY, linewidth=1.3)
ax.plot([], [], color=GRAY, linewidth=1.3, label="starting gaps of ±0.05 and ±0.1")
ax.set_ylim(-1.5, 2.0)
ax.set_title("Only one path stays bounded: every other path explodes")
ax.set_xticks(range(0, T + 1, 5))
ax.set_xlabel("period")
ax.set_ylabel("inflation $x_t$")
ax.legend(loc="upper left")
show(fig, "Paths of inflation that start off the decision rule explode; only the rule stays bounded")
print(f"Unstable root 1/a = {1 / a:.3f} > 1, one jump variable: a unique stable solution.")
Paths of inflation that start off the decision rule explode; only the rule stays bounded
Unstable root 1/a = 1.111 > 1, one jump variable: a unique stable solution.

Perfect foresight: the whole path as one system of equations

There is a second way to solve the model, and it is the one Snowdrop uses for nonlinear models. Look at all the periods at once. Equation (G.1) for periods \(1, 2, \dots, T\) gives \(T\) equations in the \(T\) unknowns \(x_1,\dots,x_T\), if we add a terminal condition: far in the future the economy is back at its steady state, \(x_{T+1}=0\). Solve the \(T\) equations together and you have the whole path.

Newton’s method solves such systems. Start from a guess for the path, compute the residuals (how far each equation is from holding), and correct the guess with the matrix of derivatives (the Jacobian \(J\)): \(x \leftarrow x - J^{-1}\,\text{residuals}(x)\). For a linear model one step is enough; a nonlinear model needs a few. Snowdrop’s ABLR method stacks all periods into one large sparse system like this one, and its LBJ method solves the same system period by period, forward and then backward.

Python note. rho ** np.arange(80) gives \(1, \rho, \rho^2, \dots\): the shock in periods 1 to 80. np.append(x[1:], 0.0) shifts the path one period ahead and adds the terminal value \(x_{T+1}=0\). np.eye(T) is the identity matrix and np.eye(T, k=1) has ones just above the diagonal, so J @ x gives \(x_t - a\,x_{t+1}\) for every \(t\). np.linalg.solve(J, r) computes \(J^{-1}r\).

T_long = 80                                     # a long horizon, so that x_81 = 0 does no harm
z_long = rho ** np.arange(T_long)               # the cost shock in periods 1, ..., 80

def residuals(x_path):
    """Equation (G.1) for t = 1, ..., 80, with the terminal condition x_81 = 0."""
    x_next = np.append(x_path[1:], 0.0)
    return x_path - a * x_next - b * z_long

J = np.eye(T_long) - a * np.eye(T_long, k=1)    # the Jacobian of the residuals
guess = np.zeros(T_long)                        # start from "nothing happens"
for step in range(1, 4):
    guess = guess - np.linalg.solve(J, residuals(guess))
    print(f"Newton step {step}: largest residual {np.abs(residuals(guess)).max():.1e}")

print(f"Largest gap to the decision rule in periods 1-{T}: {np.abs(guess[:T] - x[1:T + 1]).max():.1e}")
Newton step 1: largest residual 2.8e-17
Newton step 2: largest residual 2.8e-17
Newton step 3: largest residual 2.8e-17
Largest gap to the decision rule in periods 1-30: 4.1e-11

What to notice. Newton’s method converges in one step, because the model is linear; the later steps change nothing. Its path matches the decision rule. The terminal condition \(x_{81}=0\) is slightly wrong (the rule gives \(0.5\times0.8^{80}\)), but 80 periods later that error no longer matters. With a short horizon it would: this is why Snowdrop simulates models over many periods.

Your turn. Set \(a=1.1\). What is the unstable root \(1/a\) now? Run the cell with the five starting gaps again: do the other paths still explode? What does this mean for the uniqueness of the solution?

Show the answer

With \(a=1.1\) the root is \(1/a\approx 0.91<1\): there is no unstable root but still one jump variable, so the Blanchard–Kahn condition fails. Every gap now shrinks, so every starting value of inflation gives a bounded path. The model has many stable solutions (it is indeterminate): it cannot tell us what inflation will be. Expectations alone can then move the economy (economists call these sunspots). In New Keynesian models, a central bank that raises the interest rate by more than one for one with inflation (the Taylor principle of Chapter 13) rules this out.

a = 1.1
phi = b / (1 - a * rho)       # the decision rule changes too
print(f"1/a = {1 / a:.3f}, phi = {phi:.3f}")   # then rerun the cell that draws the five paths

Set a = 0.9 and phi = b / (1 - a * rho) again before you go on.

# Your turn: try it here

G.5 Anatomy of a Snowdrop model file

YAML in five minutes

Snowdrop’s model files are written in YAML, a plain-text format for structured data. Four rules cover almost everything:

  • key: value pairs, one per line;
  • nesting by indentation with spaces (never tabs);
  • lists either in brackets, [x, z], or one item per line starting with -;
  • # starts a comment.

Python reads YAML into dictionaries and lists. Here is a tiny example:

import yaml
text = """
name: A tiny example          # the model's name
symbols:
   variables: [x, z]
   parameters: [a, b, rho]
calibration:
   a: 0.9
   b: 0.14
"""
print(yaml.safe_load(text))
{'name': 'A tiny example', 'symbols': {'variables': ['x', 'z'], 'parameters': ['a', 'b', 'rho']}, 'calibration': {'a': 0.9, 'b': 0.14}}

The blocks of a model file

Here is the model file of the paper’s monetary policy model, as it comes with Snowdrop. (Its name, JLMP98, points to Juillard, Laxton, McAdam and Pioro, 1998, the paper behind Snowdrop’s LBJ method.)

print(open("JLMP98.yaml").read())
name:  Monetary policy model example 
# For details, please see https://link.springer.com/article/10.1057/imfsp.2008.11

symbols:
   variables: [PDOT,RR,RS,Y]
   exogenous: [exo]
   shocks: [ey,err,ers,epdot]
   parameters: [g,p_pdot1,p_pdot2,p_pdot3,p_rs1,p_y1,p_y2,p_y3]

equations:
      - PDOT = p_pdot1*PDOT(+1) + (1-p_pdot1)*PDOT(-1) + p_pdot2*(g^2/(g-Y) - g) + p_pdot3*(g^2/(g-Y(-1)) - g) + epdot
      - RR = RS - p_pdot1*PDOT(+1) - (1-p_pdot1)*PDOT(-1) + err
      - RS = p_rs1*PDOT + Y + ers + exo 
      - Y = p_y1*Y(-1) - p_y2*RR - p_y3*RR(-1) + ey

calibration:
    # parameters
    g: 0.049
    p_pdot1: 0.414
    # User can set time varying parameters.  The last value will be used for the rest of array
    #p_pdot1: [0.4,0.5,0.6,0.7] 
    p_pdot2 : 0.196
    p_pdot3: 0.276
    p_rs1: 3
    p_y1: 0.304
    p_y2: 0.098
    p_y3: 0.315
    # initial values
    PDOT: 0
    RR: 0
    RS: 0
    Y: 0
    X: 1
    Z: 1
    R: 1
    std: 0.02
    
    # exogenous variables
    #ers: [0,0,0,0,0.01,0]
    #file: [../../data/exog.csv]

    
# steady_state:    
#     PDOT: 0.0
#     RR: 0.0
#     RS: 0.0
#     Y: 0.0
    
labels:
   PDOT: "Inflation"
   PDOT(-1): "Lag of Inflation"
   PDOT(+1): "Lead of Inflation"
   RR:  "Real Interest Rate"
   RR(-1): "Lag of Real Interest Rate"
   RS:  "Monetary Policy Rate"
   Y:   "Output Gap"
   Y(-1): "Lag of Output Gap"
   ey:  "Production Shock"
   err:  "Real Interest Rate Shock"
   ers:  "Monetary Policy Shock"
   epdot:  "Inflation Shock"
   exo: "Exogenous Process"
   
options:
    T : 14
    periods: [1]
    shock_values: [std]
Block What it holds
name a description of the model
symbols the names of the variables (endogenous), the exogenous variables (paths given from outside), the shocks and the parameters
equations one equation per line, left side = right side; one equation per endogenous variable
calibration parameter values, and starting values of the variables
labels readable names for charts, also for leads and lags such as PDOT(-1)
options simulation settings: T (number of periods), periods (when shocks hit), shock_values (their sizes)

Models that are estimated have four more blocks: measurement_variables, measurement_shocks, measurement_equations and estimated_parameters. We meet them in Section G.11.

Timing, shocks and exogenous variables

  • PDOT(-1) is last period’s value (a lag), and PDOT(+1) (or PDOT(1)) is the value people expect for next period (a lead). An equation with a lead is forward-looking.
  • Shocks are listed under symbols: shocks. options: periods: [1] and shock_values: [0.02] mean “in period 1, the shocks take these values”, in the order of the shock list: here the first shock, ey, equals 0.02. Values not given are zero.
  • Exogenous variables follow a path set from outside, period by period (G.7 uses one for the policy-rate revision).
  • A parameter can change over time: in calibration, p_pdot1: [0.4, 0.5, 0.6] would mean 0.4 in period 1, 0.5 in period 2 and 0.6 from period 3 on.

From file to model object

importModel reads the file, checks its syntax, and writes Python functions for the equations and their derivatives. Its report lists the equations; the number in front of each one is its residual at the starting values. A residual of 0.000 means the starting values satisfy that equation, which is a quick check that you start from a steady state.

jlmp = load_model("JLMP98.yaml", verbose=True)
=============================
Monetary policy model example
=============================


Model:
------
name: "Monetary policy model example"
file: "/Users/carlosmendez/Documents/GitHub/macro102/.work/appG/run/dsge/JLMP98.yaml

Non-Linear Model

Transition Equations:
---------------------

 1   0.000 :  PDOT = p_pdot1*PDOT(+1) + (1-p_pdot1)*PDOT(-1) + p_pdot2*(g**2/(g-Y) - g) + p_pdot3*(g**2/(g-Y(-1)) - g) + epdot
 2   0.000 :  RR = RS - p_pdot1*PDOT(+1) - (1-p_pdot1)*PDOT(-1) + err
 3   0.000 :  RS = p_rs1*PDOT + Y + ers + exo
 4   0.000 :  Y = p_y1*Y(-1) - p_y2*RR - p_y3*RR(-1) + ey

The model object holds everything the file defined.

Python note. zip(names, values) pairs the two lists element by element, and dict(...) turns the pairs into a dictionary.

print("Variables: ", jlmp.symbols["variables"])
print("Shocks:    ", jlmp.symbols["shocks"])
print("Exogenous: ", jlmp.symbols["exogenous"])
print("Parameters:", dict(zip(jlmp.symbols["parameters"], jlmp.calibration["parameters"])))
print("Options:   ", jlmp.options)
Variables:  ['PDOT', 'RR', 'RS', 'Y']
Shocks:     ['ey', 'err', 'ers', 'epdot']
Exogenous:  ['exo']
Parameters: {'g': np.float64(0.049), 'p_pdot1': np.float64(0.414), 'p_pdot2': np.float64(0.196), 'p_pdot3': np.float64(0.276), 'p_rs1': np.float64(3.0), 'p_y1': np.float64(0.304), 'p_y2': np.float64(0.098), 'p_y3': np.float64(0.315)}
Options:    {'T': 14, 'periods': [1], 'shock_values': [0.02]}

Finally, Snowdrop can count the roots of the linearized model, as we did by hand in Section G.4. The model has one forward-looking variable, inflation PDOT(+1), so it needs exactly one root larger than 1 in absolute value.

roots, text = quietly(driver.findEigenValues, model=jlmp)
roots = np.sort(np.abs(roots))
print("Absolute values of the roots:", np.round(roots, 3))
print("Roots larger than 1:", int(np.sum(roots > 1)), "| forward-looking variables: 1")
Absolute values of the roots: [0.    0.015 0.015 0.995 1.42 ]
Roots larger than 1: 1 | forward-looking variables: 1

The model has one unstable root and one jump variable: the Blanchard–Kahn condition holds, and the model has a unique stable solution.

G.6 Your first model file: the AS/AD model of Chapter 13

The best first model is one you already know. Chapter 13 combines an AD curve (the IS curve plus the central bank’s rule \(R_t-\bar{r}=\bar{m}(\pi_t-\bar{\pi})\)) with an AS curve (the Phillips curve with adaptive expectations):

\[\tilde{Y}_t=\bar{a}_t-\bar{b}\bar{m}\,(\pi_t-\bar{\pi}), \qquad (G.5)\]

\[\pi_t=\pi_{t-1}+\bar{\nu}\,\tilde{Y}_t+\bar{o}_t. \qquad (G.6)\]

\(\tilde{Y}_t\) is the output gap and \(\pi_t\) inflation, both in percent. The demand shock \(\bar{a}_t\) and the inflation shock \(\bar{o}_t\) move the economy away from its steady state, where output is at potential and inflation equals the target \(\bar{\pi}\). We use Chapter 13’s baseline: \(\bar{\pi}=2\), \(\bar{m}=0.5\), \(\bar{b}=2\) and \(\bar{\nu}=1\). The model has no expected future values, only the past (\(\pi_{t-1}\)), so it is not a DSGE model, but it is written, solved and simulated with exactly the same tools.

Writing the model file

The notebook command %%writefile saves the rest of a cell as a file. One name needs care: \(\pi\) is a built-in constant (3.14159…) in the algebra library that Snowdrop uses, so a variable called pi would clash with it. We call inflation infl.

%%writefile asad.yaml
name: The AS/AD model of Chapter 13

symbols:
   variables: [Ytil, infl]           # output gap and inflation, in percent
   shocks: [a, o]                    # demand shock and inflation shock
   parameters: [b, m, nu, infl_bar]  # IS slope, policy response, Phillips slope, inflation target

equations:
   - Ytil = a - b*m*(infl - infl_bar)        # the AD curve (G.5)
   - infl = infl(-1) + nu*Ytil + o           # the AS curve (G.6)

calibration:
   b: 2.0
   m: 0.5
   nu: 1.0
   infl_bar: 2.0
   Ytil: 0.0                         # starting values: the steady state
   infl: 2.0

labels:
   Ytil: "Output gap, %"
   infl: "Inflation, %"

options:
   T: 20
   periods: [1]
   shock_values: [[0.0, 2.0]]        # Event 1: an inflation shock o = 2 in period 1
Writing asad.yaml

Event 1: an inflation shock

load_model reads the file, and simulate solves the model and returns a table with one row per period. Period 0 holds the starting values.

asad = load_model("asad.yaml", verbose=True)
event1 = simulate(asad)
event1.head(6).round(3)
=============================
The AS/AD model of Chapter 13
=============================


Model:
------
name: "The AS/AD model of Chapter 13"
file: "/Users/carlosmendez/Documents/GitHub/macro102/.work/appG/run/dsge/asad.yaml

Linear Model

Transition Equations:
---------------------

 1   0.000 :  Ytil = a - b*m*(infl - infl_bar)
 2   0.000 :  infl = infl(-1) + nu*Ytil + o
Ytil infl
0 0.000 2.000
1 -1.000 3.000
2 -0.500 2.500
3 -0.250 2.250
4 -0.125 2.125
5 -0.062 2.062

These are the numbers of Chapter 13: inflation jumps to 3 percent, output falls 1 percent below potential, and the gap to the target halves every period. Snowdrop’s plot draws every variable of a simulation in its own panel.

Python note. plot(...) is Snowdrop’s chart function. show=False, save=False tells it to return the charts instead of showing and saving them, so that show(...) can draw them in the book’s colors. figs[0] is the first (here the only) chart.

figs = plot(path_to_dir=WORK, data=event1.to_numpy(), variable_names=list(event1.columns),
            var_labels=asad.symbols["variables_labels"], header="Event 1: an inflation shock",
            sizes=(1, 2), figsize=(10, 4), show=False, save=False)
show(figs[0], "Snowdrop's chart of the inflation shock: inflation jumps to 3 percent and output falls 1 percent", snowdrop=True)
Snowdrop's chart of the inflation shock: inflation jumps to 3 percent and output falls 1 percent

Snowdrop and Chapter 13 agree

Chapter 13 solved the model period by period with a formula: given last period’s inflation, equations (G.5) and (G.6) are two linear equations in this period’s \(\tilde{Y}_t\) and \(\pi_t\), with the solution \(\tilde{Y}_t=[\bar{a}_t-\bar{b}\bar{m}(\pi_{t-1}+\bar{o}_t-\bar{\pi})]/(1+\bar{b}\bar{m}\bar{\nu})\). Here is that solution again, to check Snowdrop against it.

def ch13_path(a_list, o_list, infl_start=2.0, infl_bar=2.0, b=2.0, m=0.5, nu=1.0):
    """Chapter 13's solution of (G.5)-(G.6), one period at a time; period 0 is the starting point."""
    rows = [(0.0, infl_start)]
    for t in range(len(a_list)):
        infl_prev = rows[-1][1]
        Y = (a_list[t] - b * m * (infl_prev + o_list[t] - infl_bar)) / (1 + b * m * nu)
        rows.append((Y, infl_prev + nu * Y + o_list[t]))
    return pd.DataFrame(rows, columns=["Ytil", "infl"])

no_shock = [0.0] * 20
check1 = ch13_path(no_shock, [2.0] + [0.0] * 19)
gap = event1.to_numpy() - check1.iloc[:len(event1)].to_numpy()   # same periods
print(f"Largest difference between Snowdrop and Chapter 13: {np.abs(gap).max():.1e}")
Largest difference between Snowdrop and Chapter 13: 0.0e+00

Python note. [0.0] * 20 repeats the list: twenty zeros. [2.0] + [0.0] * 19 joins two lists: a shock of 2 in period 1 and zeros afterwards.

Event 2: disinflation

The central bank lowers its inflation target from 4 to 2 percent. We start the economy at the old steady state, with inflation at 4 percent, and use the new target of 2 percent from period 1 on. No shock hits.

asad = load_model("asad.yaml")
set_values(asad, "variables", {"infl": 4.0})          # inflation starts at the old target
asad.options["shock_values"] = [[0.0, 0.0]]           # no shock
event2 = simulate(asad)
figs = plot(path_to_dir=WORK, data=event2.to_numpy(), variable_names=list(event2.columns),
            var_labels=asad.symbols["variables_labels"], header="Event 2: disinflation from 4 to 2 percent",
            sizes=(1, 2), figsize=(10, 4), show=False, save=False)
show(figs[0], "Disinflation: a recession of 1 percent brings inflation from 4 down to 2 percent", snowdrop=True)

check2 = ch13_path(no_shock, no_shock, infl_start=4.0)
print(f"Largest difference to Chapter 13: {np.abs(event2.to_numpy() - check2.iloc[:len(event2)].to_numpy()).max():.1e}")
Disinflation: a recession of 1 percent brings inflation from 4 down to 2 percent
Largest difference to Chapter 13: 0.0e+00

Event 3: a positive demand shock

Spending rises by \(\bar{a}=2\) percent of potential output for nine periods, then returns to normal. A shock that lasts several periods is a list of periods with one row of shock values for each.

asad = load_model("asad.yaml")
asad.options["periods"] = list(range(1, 10))          # periods 1, 2, ..., 9
asad.options["shock_values"] = [[2.0, 0.0]] * 9      # a = 2 and o = 0 in each of them
event3 = simulate(asad)
figs = plot(path_to_dir=WORK, data=event3.to_numpy(), variable_names=list(event3.columns),
            var_labels=asad.symbols["variables_labels"], header="Event 3: a demand shock in periods 1-9",
            sizes=(1, 2), figsize=(10, 4), show=False, save=False)
show(figs[0], "A demand shock: output booms, inflation climbs toward 4 percent, then a recession follows", snowdrop=True)

check3 = ch13_path([2.0] * 9 + [0.0] * 11, no_shock)
print(f"Largest difference to Chapter 13: {np.abs(event3.to_numpy() - check3.iloc[:len(event3)].to_numpy()).max():.1e}")
A demand shock: output booms, inflation climbs toward 4 percent, then a recession follows
Largest difference to Chapter 13: 0.0e+00

What to notice. All three events reproduce Chapter 13 exactly. The demand shock first raises output and inflation; as inflation rises, the central bank’s rule raises the real interest rate and pulls output back to potential, with inflation stuck near 4 percent. When the shock ends, the economy needs a recession to bring inflation back to 2 percent.

Your turn. Make monetary policy more aggressive, \(\bar{m}=1\), and rerun Event 1. By how much does output fall in period 1, and how fast does the inflation gap close? (Chapter 13: each period the gap shrinks by the factor \(\lambda=1/(1+\bar{b}\bar{m}\bar{\nu})\).)

Show the answer

With \(\bar{m}=1\), \(\lambda=1/3\): the inflation gap falls to a third each period instead of a half, and output falls by \(\bar{b}\bar{m}\lambda\bar{o}=2\times1\times\tfrac{1}{3}\times2\approx1.33\) percent in period 1, more than the 1 percent of the baseline. A tougher central bank buys faster disinflation with a deeper first recession.

asad = load_model("asad.yaml")
set_values(asad, "parameters", {"m": 1.0})
simulate(asad).head(5).round(3)
# Your turn: try it here

G.7 The paper’s example: a monetary policy model with expectations

The model, read as economics

The paper’s model has four equations. In the file, PDOT is inflation \(\pi_t\), Y the output gap \(y_t\), RS the central bank’s interest rate \(i_t\) and RR the real interest rate \(r_t\). All four are deviations from the steady state, in decimals (0.01 is one percentage point). With the paper’s names for the parameters:

\[\pi_t = p_1\,\pi_{t+1} + (1-p_1)\,\pi_{t-1} + p_2\Big(\frac{g^2}{g-y_t}-g\Big) + p_3\Big(\frac{g^2}{g-y_{t-1}}-g\Big) + \varepsilon^{\pi}_t, \qquad (G.7)\]

\[r_t = i_t - p_1\,\pi_{t+1} - (1-p_1)\,\pi_{t-1} + \varepsilon^{r}_t, \qquad (G.8)\]

\[i_t = p_4\,\pi_t + y_t + \varepsilon^{i}_t + \text{exo}_t, \qquad (G.9)\]

\[y_t = p_5\,y_{t-1} - p_6\,r_t - p_7\,r_{t-1} + \varepsilon^{y}_t. \qquad (G.10)\]

  • (G.7) is a Phillips curve that mixes expected inflation (weight \(p_1=0.414\)) and past inflation. The output gap enters through \(g^2/(g-y)-g\), which is close to \(y\) when the gap is small but rises ever faster as \(y\) approaches \(g=0.049\): an economy near full capacity sees inflation accelerate. Booms raise inflation by more than slumps of the same size lower it. Such a convex Phillips curve was a feature of the IMF’s models of the 1990s.
  • (G.8) defines the real interest rate: the policy rate minus the inflation people expect (Chapters 8 and 12).
  • (G.9) is the policy rule: the rate rises by \(p_4=3\) points for each point of inflation and one for one with the output gap. \(\text{exo}_t\) is a deliberate change of policy, set from outside.
  • (G.10) is an IS curve with lags: a higher real interest rate, now or last period, lowers the output gap (Chapters 11 and 12).

Because inflation and the real rate depend on expected inflation, the model is forward-looking; because of the convex term, it is nonlinear.

g = 0.049
y_gap = np.linspace(-0.04, 0.03, 141)
fig, ax = book_figure()
ax.plot(100 * y_gap, 100 * y_gap, color=GRAY, linestyle="--", label="a linear Phillips curve: $y$")
ax.plot(100 * y_gap, 100 * (g**2 / (g - y_gap) - g), color=BLUE, label="the paper's term: $g^2/(g-y)-g$")
ax.set_title("The output gap enters the Phillips curve in a convex way")
ax.set_xlabel("output gap $y$, percent")
ax.set_ylabel("effect on inflation, before $p_2$")
ax.legend(loc="upper left")
show(fig, "The convex term equals the gap near zero but rises much faster for large positive gaps")
The convex term equals the gap near zero but rises much faster for large positive gaps

The paper’s listing and the package’s file

The file you printed in Section G.5 is not quite the listing in the paper. The differences are harmless, but you need to know them to reproduce the paper:

The paper’s listing Snowdrop’s JLMP98.yaml
Parameter names p1, …, p7 p_pdot1, p_pdot2, p_pdot3, p_rs1, p_y1, p_y2, p_y3
Shocks one, ey (to output) four: ey, err, ers, epdot (one per equation)
Layout equations and calibration indented under symbols (a slip: Snowdrop would reject it) separate blocks
The policy revision exo: [0,0,0,0.03,0] in calibration not set; we set it below
Shock periods: [1], shock_values: [std] with std: 0.02 the same

Solving with Newton’s method

Snowdrop solves nonlinear models along the whole path, as in Section G.4: it stacks the four equations for every period and applies Newton’s method until the residuals vanish. First the output shock alone, with both of Snowdrop’s methods. quietly keeps Snowdrop’s report, and we print its last lines.

paths = {}
for method in ["LBJ", "ABLR"]:
    jlmp = load_model("JLMP98.yaml", Solver=method)
    jlmp.options["periods"] = [1]
    jlmp.options["shock_values"] = [0.02]             # ey = 0.02: a 2 percent output shock in period 1
    (y, dates), text = quietly(driver.run, model=jlmp, Plot=False)
    paths[method] = np.asarray(y)
    print(method, "|", " | ".join(text.strip().splitlines()[-2:]))

print(f"Largest difference between the two methods: {np.abs(paths['LBJ'] - paths['ABLR']).max():.1e}")
LBJ | Elapsed time: 0.01 (seconds) | Number of iterations: 5; error: 1.9e-11
ABLR | Elapsed time: 0.10 (seconds) | Number of iterations: 5; error: 1.9e-11
Largest difference between the two methods: 1.3e-17

Newton’s method needs a handful of iterations because the model is nonlinear, and the two methods find the same path.

Replicating the paper’s Fig. 1

The paper adds a revision of monetary policy: in period 4 the policy rate is raised by 3 percentage points on top of what the rule says, for one period. That is a path for the exogenous variable exo: 0.03 in period 4 and 0 from period 5 on. getExogenousSeries turns the path into the form Snowdrop uses.

Python note. pd.Series([0.03, 0.0], index=[4, 5]) is a column of two numbers labelled by the periods 4 and 5. Snowdrop keeps the last value for all later periods.

from snowdrop.src.utils.util import getExogenousSeries

jlmp = load_model("JLMP98.yaml", Solver="LBJ")
jlmp.options["periods"] = [1]
jlmp.options["shock_values"] = [0.02]                 # the 2 percent output shock in period 1
jlmp.symbolic.exog_data = {"exo": pd.Series([0.03, 0.0], index=[4, 5])}
jlmp.calibration["exogenous"] = getExogenousSeries(jlmp)
fig1 = simulate(jlmp)
(100 * fig1.iloc[:9]).round(2)                       # in percent, periods 0 to 8
PDOT RR RS Y
0 0.00 0.00 0.00 0.00
1 0.94 3.97 4.44 1.61
2 1.14 1.85 2.48 -0.94
3 0.19 -0.76 -0.22 -0.79
4 -0.30 1.97 1.89 -0.19
5 -0.46 -1.59 -1.91 -0.52
6 -0.33 -0.34 -0.63 0.38
7 -0.03 0.28 0.10 0.19
8 0.03 0.07 0.05 -0.04

Compare with the paper’s Fig. 1: inflation rises to about 0.9 percent in period 1 and 1.1 percent in period 2, and falls to about −0.45 percent in period 5; the real interest rate jumps to 4 percent; the output gap is 1.6 percent in period 1 and −0.9 percent in period 2. The table has the same numbers.

Before we trust a nonlinear solution, we check it: put the path back into the four equations and look at what is left over.

from snowdrop.src.numeric.solver.util import checkSolution

errors = checkSolution(jlmp, periods=jlmp.options["periods"], y=fig1.to_numpy())
print(f"LBJ: largest residual of the four equations: {np.abs(errors).max():.1e}")

jlmp_ablr = load_model("JLMP98.yaml", Solver="ABLR")
jlmp_ablr.options["periods"] = [1]
jlmp_ablr.options["shock_values"] = [0.02]
jlmp_ablr.symbolic.exog_data = {"exo": pd.Series([0.03, 0.0], index=[4, 5])}
jlmp_ablr.calibration["exogenous"] = getExogenousSeries(jlmp_ablr)
path_ablr = simulate(jlmp_ablr)
errors = checkSolution(jlmp_ablr, periods=jlmp_ablr.options["periods"], y=path_ablr.to_numpy())
print(f"ABLR: largest residual of the four equations: {np.abs(errors).max():.1e}")
LBJ: largest residual of the four equations: 3.5e-18
ABLR: largest residual of the four equations: 3.0e-02

What to notice. The LBJ path satisfies the equations to machine precision. The ABLR path leaves a residual of exactly 0.03 in the policy rule: in this version of Snowdrop, the ABLR method does not apply the exogenous path, although it solved the output shock alone correctly. Nothing in Snowdrop’s report warns about it; only the residual check reveals it. This is why the paper’s model runs with LBJ, and why you should check residuals.

Now the chart. plotDecomposition draws, for each variable, the contribution of each term on the right-hand side of its equation, as stacked bars, with the total as a line.

figs = plotDecomposition(path_to_dir=WORK, model=jlmp, y=fig1.to_numpy(), variables_names=list(fig1.columns),
                         decomp_variables=["PDOT", "RR", "RS", "Y"], periods=jlmp.options["periods"],
                         header="Shock to Output and Revision of Nominal Interest Rate", bPercent=True,
                         show=False, save=False)
show(figs[0], "Replication of Fig. 1 of the Snowdrop paper: contributions to inflation, the real and policy "
     "interest rates and the output gap", snowdrop=True)
Replication of Fig. 1 of the Snowdrop paper: contributions to inflation, the real and policy interest rates and the output gap

Reading a contribution chart

Each panel splits one equation. For inflation, equation (G.7) says that inflation is the sum of five terms: the lead of inflation, the lag of inflation, the output gap term, the lagged output gap term and the inflation shock. In each period the bars show the size of each term, positive above zero and negative below, and they add up to the black line. Snowdrop’s decompose function returns the numbers behind the bars.

from snowdrop.src.numeric.solver.util import decompose

T_fig = len(fig1)
parts, names = decompose(jlmp, fig1.to_numpy(), list(fig1.columns), "PDOT", T_fig, jlmp.options["periods"], False)
parts = 100 * pd.DataFrame(parts, index=fig1.index)  # in percent
parts["sum of the terms"] = parts.sum(axis=1)
parts["inflation"] = 100 * fig1["PDOT"]
parts.iloc[1:7].round(3)
Lead of Inflation Lag of Inflation Output Gap Lag of Output Gap Inflation Shock sum of the terms inflation
1 0.471 0.000 0.471 0.000 0.0 0.942 0.942
2 0.079 0.552 -0.155 0.663 0.0 1.139 1.139
3 -0.126 0.667 -0.134 -0.218 0.0 0.190 0.190
4 -0.191 0.111 -0.037 -0.188 0.0 -0.304 -0.304
5 -0.138 -0.178 -0.093 -0.051 0.0 -0.461 -0.461
6 -0.013 -0.270 0.080 -0.131 0.0 -0.334 -0.334

What to notice. The terms add up to inflation. In period 1 the output shock opens a positive output gap, and the output gap term pushes inflation up; so does the lead of inflation, because people expect the boom to raise inflation next period too. The central bank’s rule answers with a large rise of the policy rate, so the real interest rate jumps to 4 percent and the output gap turns negative from period 2. Inflation peaks in period 2, carried by its own lag and the lagged boom, and is below zero by period 4. The policy revision in period 4 raises the real interest rate once more and deepens the slump in period 5, when inflation reaches its low of about −0.46 percent. The paper’s chart tells this whole story at a glance.

Your turn. The convex Phillips curve makes the model asymmetric. Simulate an output shock of +2 percent and one of −2 percent, without the policy revision, and compare the largest movement of inflation in each case.

Show the answer

The boom raises inflation by about 1.2 percent at its peak, while the slump of the same size lowers it by only about 0.55 percent, because the output gap term rises faster for positive gaps than it falls for negative ones (the chart of the convex term above).

for shock in [0.02, -0.02]:
    jlmp = load_model("JLMP98.yaml")
    jlmp.options["periods"] = [1]
    jlmp.options["shock_values"] = [shock]
    path = simulate(jlmp)
    print(f"shock {shock:+.2f}: largest move of inflation {100 * path['PDOT'].abs().max():.3f} percent")
# Your turn: try it here

G.8 A real business cycle model

The model

Chapter 15 described real business cycle (RBC) models: an economy without frictions, hit by productivity shocks. Snowdrop’s RBC.yaml is the simplest one with a household that chooses how much to save. Labor is fixed at one.

\[\frac{1}{C_t}=\beta\,\frac{1+r_t}{C_{t+1}} \qquad (G.11)\]

\[Y_t = C_t + K_t-(1-\delta)K_{t-1} \qquad (G.12)\]

\[Y_t = K_{t-1}^{\gamma}\,A_t^{1-\gamma} \qquad (G.13)\]

\[\gamma\,\frac{Y_{t+1}}{K_t}=r_t+\delta \qquad (G.14)\]

\[\log A_t=\rho\log A_{t-1}+(1-\rho)\log a+\varepsilon_t \qquad (G.15)\]

  • (G.11) is the Euler equation of Chapter 16 with log utility: the household gives up a unit of consumption today if the return \(1+r_t\), discounted by \(\beta\), makes up for it.
  • (G.12) is the resource constraint: output is consumed or invested, and investment \(K_t-(1-\delta)K_{t-1}\) builds the capital stock, which depreciates at rate \(\delta\) (Chapter 17).
  • (G.13) is the production function of Chapter 4, with labor-augmenting technology \(A_t\).
  • (G.14) says that capital is rented until its marginal product equals its user cost \(r_t+\delta\) (Chapter 17). Capital chosen in period \(t\) produces in \(t+1\).
  • (G.15) is the technology shock, an AR(1) in logs around the level \(a\).

The calibration is \(\beta=0.99\), \(\gamma=0.5\), \(\delta=0.03\), \(\rho=0.8\) and \(a=0.1\), with one period a quarter.

print(open("RBC.yaml").read())
name:  Simple Real Business Cycle Model

symbols:
   #log_variables: [Y,C]
   variables: [K,r,A,Y,C]
   shocks: [ea]
   parameters: [beta,delta,gamma,rho,a]

equations:
    - 1/C = 1/C(1) * beta * (1 + r)           
    #- K = Y - C + (1-delta) * K(-1)           
    - Y = C + K - (1-delta) * K(-1)
    - Y = K(-1)^gamma * A^(1-gamma)
    - gamma*Y(1)/K = r + delta
    - log(A) = rho*log(A(-1)) + (1-rho)*log(a) + ea

calibration:
      # parameters
      beta : 0.99
      gamma : 0.50
      delta : 0.03
      rho : 0.80
      a : 0.1
      # initial values
      C : 0.78046
      K : 15.5546
      Y : 1.25
      r : 0.0101
      A : a  
      ea : 0      
      std : 0.1
    
options:
    T : 201    
    periods: [1]
    shock_values: [[std]]

The steady state by hand

In the steady state nothing changes, so (G.11) gives \(1=\beta(1+r)\), (G.14) gives the capital–output ratio, and (G.13) and (G.12) give output and consumption:

\[r^*=\frac{1}{\beta}-1,\qquad \frac{K^*}{Y^*}=\frac{\gamma}{r^*+\delta},\qquad Y^*=a\Big(\frac{K^*}{Y^*}\Big)^{\gamma/(1-\gamma)},\qquad C^*=Y^*-\delta K^*. \qquad (G.16)\]

The third formula comes from writing (G.13) as \(Y=(K/Y)^{\gamma/(1-\gamma)}A\) with \(A=a\).

beta, gamma, delta, a_level = 0.99, 0.5, 0.03, 0.1
r_star = 1 / beta - 1
KY = gamma / (r_star + delta)
Y_star = a_level * KY ** (gamma / (1 - gamma))
K_star = KY * Y_star
C_star = Y_star - delta * K_star
steady = {"K": K_star, "r": r_star, "A": a_level, "Y": Y_star, "C": C_star}
pd.Series(steady).round(5)
K    15.54638
r     0.01010
A     0.10000
Y     1.24685
C     0.78046
dtype: float64

Snowdrop has a steady-state solver. It starts from the starting values in the file and searches with Newton’s method.

rbc = load_model("RBC.yaml")
(ss, growth), text = quietly(driver.findSteadyStateSolution, model=rbc)
comparison = pd.DataFrame({"by hand": pd.Series(steady), "Snowdrop": pd.Series(ss, index=rbc.symbols["variables"])})
comparison["difference, %"] = 100 * (comparison["Snowdrop"] / comparison["by hand"] - 1)
comparison.round(5)
by hand Snowdrop difference, %
K 15.54638 15.58878 0.27270
r 0.01010 0.01008 -0.20593
A 0.10000 0.10000 0.00118
Y 1.24685 1.24856 0.13730
C 0.78046 0.78090 0.05630

Snowdrop’s answer is close, but its capital stock is about 0.3 percent too high. Its search stops with residuals of about 0.00003, which it treats as small enough. For dynamic simulations that is not quite good enough: a model that starts slightly off its steady state drifts even when no shock hits. When the steady state has a formula, use the formula. We put the exact values in as starting values, and check: the steady-state solver now returns them unchanged, and a simulation with no shock stays put.

rbc = load_model("RBC.yaml")
set_values(rbc, "variables", steady)
(ss, growth), text = quietly(driver.findSteadyStateSolution, model=rbc)
print("Snowdrop's steady state, starting from the formula:", np.round(ss, 5))

rbc.options["shock_values"] = [[0.0]]                 # no shock
calm = simulate(rbc)
print(f"With no shock, the largest move away from the steady state: {np.abs(calm - calm.iloc[0]).to_numpy().max():.1e}")
Snowdrop's steady state, starting from the formula: [1.554638e+01 1.010000e-02 1.000000e-01 1.246850e+00 7.804600e-01]
With no shock, the largest move away from the steady state: 2.2e-16

A technology shock under perfect foresight

The file’s experiment is a technology shock \(\varepsilon_1=0.1\) in period 1: technology jumps 10.5 percent and then returns to its steady state at the rate \(\rho=0.8\). After the shock, households and firms know the future path of technology: the solution is a perfect-foresight path, found with Newton’s method as before.

rbc = load_model("RBC.yaml")
set_values(rbc, "variables", steady)                  # start from the exact steady state
tfp = simulate(rbc)                                   # the file's shock: 0.1 in period 1
rbc_labels = {"K": "Capital", "r": "Interest rate (quarterly)", "A": "Technology", "Y": "Output", "C": "Consumption"}
figs = plot(path_to_dir=WORK, data=tfp.iloc[:61].to_numpy(), variable_names=list(tfp.columns), var_labels=rbc_labels,
            header="A technology shock in the RBC model (60 quarters)", sizes=(2, 3), figsize=(12, 6.5),
            show=False, save=False)
show(figs[0], "Snowdrop's chart of the RBC model after a technology shock: capital, the interest rate, "
     "technology, output and consumption", snowdrop=True)
Snowdrop's chart of the RBC model after a technology shock: capital, the interest rate, technology, output and consumption

The levels hide the sizes. Impulse responses show each variable as a percent deviation from its steady state (the interest rate in percentage points, at an annual rate).

irf = 100 * (tfp / pd.Series(steady) - 1)            # percent deviations from the steady state
irf["r"] = 400 * (tfp["r"] - r_star)                 # percentage points, annual rate
irf = irf[["A", "Y", "C", "K", "r"]]
irf.iloc[[1, 2, 4, 8, 16, 40]].round(2)
A Y C K r
1 10.52 5.13 0.61 0.38 0.62
2 8.33 4.28 0.76 0.67 0.47
4 5.25 3.05 0.96 1.07 0.25
8 2.12 1.73 1.11 1.39 0.02
16 0.35 0.86 1.02 1.35 -0.09
40 0.00 0.38 0.55 0.74 -0.06
fig, ax = book_figure()
labels = {"Y": "output", "C": "consumption", "K": "capital", "A": "technology"}
colors = {"Y": BLUE, "C": TEAL, "K": GREEN, "A": GRAY}
for name in ["A", "Y", "C", "K"]:
    style = "--" if name == "A" else "-"
    ax.plot(irf.index[:41], irf[name].iloc[:41], color=colors[name], linestyle=style, label=labels[name])
ax.axhline(0, color=AXIS, linewidth=1, gid="rule")
ax.set_title("Impulse responses to a technology shock of 10 percent")
ax.set_xlabel("quarters after the shock")
ax.set_ylabel("percent deviation from the steady state")
ax.legend()
show(fig, "Output jumps with technology; consumption rises little but stays up; capital builds up slowly")
Output jumps with technology; consumption rises little but stays up; capital builds up slowly

What to notice. Output jumps with technology, by about half as much (the exponent \(1-\gamma=0.5\) in (G.13)). Consumption rises only a little: the household knows the shock is temporary and smooths consumption (Chapter 16). The rest of the extra output is invested, so capital builds up for several years, and it keeps output and consumption above their steady state after technology has returned to normal. The interest rate rises with the marginal product of capital and then falls below its steady state while the extra capital is run down.

How nonlinear is the model?

The RBC model is nonlinear: (G.13) has a power, (G.11) a ratio. Linear solution methods, like Klein’s and Dynare’s first-order perturbation, replace the model by a straight-line approximation around the steady state. A linear model responds in proportion to the shock: twice the shock, twice the response. We can test how far the RBC model is from that. We simulate technology shocks \(\varepsilon_1\) of 0.01, 0.1, 0.3 and −0.3 (in logs, so roughly 1, 10, 30 and −30 percent) and scale each response of output to a shock of 1 percent.

fig, ax = book_figure()
sizes = [0.01, 0.1, 0.3, -0.3]
colors = [GRAY, BLUE, TEAL, RUST]
for k in range(len(sizes)):
    rbc = load_model("RBC.yaml")
    set_values(rbc, "variables", steady)
    rbc.options["shock_values"] = [[sizes[k]]]
    path = simulate(rbc)
    per_unit = 100 * (path["Y"] / Y_star - 1) / (100 * sizes[k])   # % response per 1% shock
    ax.plot(per_unit.index[:41], per_unit.iloc[:41], color=colors[k], label=f"shock of {100 * sizes[k]:+.0f}%")
ax.set_title("Output response per 1 percent of shock, for four shock sizes")
ax.set_xlabel("quarters after the shock")
ax.set_ylabel("percent per percent of shock")
ax.legend()
show(fig, "The responses to small shocks coincide; large positive and negative shocks give different responses per unit")
The responses to small shocks coincide; large positive and negative shocks give different responses per unit

What to notice. For small shocks the scaled responses lie on top of each other, so a linear solution would be accurate. For shocks of ±30 percent they come apart: per unit of shock, a large positive shock raises output by more than a large negative one lowers it. Technology enters in logs, so \(\varepsilon=0.3\) raises \(A\) by 35 percent (\(e^{0.3}-1\)), while \(\varepsilon=-0.3\) lowers it by only 26 percent. Normal business cycles are small, so linear methods serve well for estimation (Sections G.11 and G.12). Big events (a pandemic, a financial crisis) are where nonlinear methods like Snowdrop’s earn their keep.

Random shocks: one model, many histories

So far one shock hit, once. In RBC1.yaml, two shocks hit every period: the technology shock and a shock to output in (G.13). They are drawn from a normal distribution (!MvNormal) for ten different histories (Npaths). The file gives the shocks means of −0.05 and 0.05; we set both to zero, so that the shocks only add noise around the steady state.

text = open("RBC1.yaml").read().replace("mean: [-0.05,0.05]", "mean: [0.0, 0.0]")
open("RBC1_zero.yaml", "w").write(text)
print(text[text.find("options"):])
options:
    T : 51    
    Npaths : 10
    distribution: !MvNormal
        mean: [0.0, 0.0]
        cov: [[std^2, cov],[cov, std^2]]

Python note. np.random.seed(2026) fixes the random numbers, so that the same histories come out every time the notebook runs. A stochastic run returns an array with three dimensions: path, period and variable.

One more setting matters. By default, Snowdrop solves each history as one perfect-foresight path: it imposes all the random shocks at once, as if households knew in period 1 every shock still to come. In a stochastic simulation the shocks must be surprises. anticipate=False makes Snowdrop solve the model period by period and reveal each shock only when it hits. This takes a few seconds longer.

rbc1 = load_model("RBC1_zero.yaml", anticipate=False)
set_values(rbc1, "variables", steady)
np.random.seed(2026)
(y, dates), text = quietly(driver.run, model=rbc1, Plot=False, anticipate=False)
print("Shape of the result (paths, periods, variables):", np.shape(y))
figs = plot(path_to_dir=WORK, data=np.asarray(y), variable_names=rbc1.symbols["variables"], Npaths=10,
            var_labels=rbc_labels, header="Ten histories of the RBC model with random shocks", sizes=(2, 3), figsize=(12, 6.5),
            show=False, save=False)
show(figs[0], "Ten simulated histories of output, consumption, capital, the interest rate and technology", snowdrop=True)
Shape of the result (paths, periods, variables): (10, 53, 5)
Ten simulated histories of output, consumption, capital, the interest rate and technology

What to notice. The same model, the same parameters and the same distribution of shocks produce ten different histories. This is how DSGE models see the business cycle: a stable economy constantly hit by small random shocks. Consumption is much smoother than output in every history, and capital moves slowly around its steady state. (Run the cell without anticipate=False and you will see what goes wrong when households know the future: consumption jumps once in period 1 and then drifts, and capital wanders far from its steady state.) Estimation (Sections G.11 and G.12) asks the reverse question: given one observed history, which parameters make it most likely?

Your turn. Make technology shocks more persistent, \(\rho=0.95\), and draw the impulse responses again. How does the response of consumption change, and why?

Show the answer

A more persistent shock raises income for longer, so it is closer to a permanent rise in income: consumption jumps by more on impact (the permanent income idea of Chapter 16), and the household invests less of each extra unit of output.

rbc = load_model("RBC.yaml")
set_values(rbc, "parameters", {"rho": 0.95})
set_values(rbc, "variables", steady)          # the steady state does not depend on rho
path = simulate(rbc)
(100 * (path / pd.Series(steady) - 1))[["A", "Y", "C", "K"]].iloc[[1, 4, 8, 20]].round(2)
# Your turn: try it here

G.9 From model to data: state space and the Kalman filter

The solved model is a state-space model

Once a linear model is solved, its decision rules say how the variables today depend on the variables yesterday and on today’s shocks. Stack the variables into a vector \(s_t\), the state:

\[s_t = T\,s_{t-1} + R\,\varepsilon_t \qquad \text{(transition equation)}\]

\[y_t = Z\,s_t + u_t \qquad \text{(measurement equation)}\]

The first line is the model. The second says which combinations of the state we observe in the data, \(y_t\), perhaps with measurement errors \(u_t\). In Ireland’s model of Section G.11 the state has seven variables and the data three. The output gap, the preference shock and the cost-push shock are never observed. The Kalman filter does two jobs at once: it infers the unobserved states from the data, period by period, and it computes the likelihood of the data, the number that estimation maximizes. We build it for the smallest case first.

A Kalman filter for one variable

The state is an AR(1), and we observe it with noise:

\[s_t=\rho\,s_{t-1}+e_t,\quad e_t\sim N(0,\sigma_e^2), \qquad (G.17)\]

\[y_t=s_t+u_t,\quad u_t\sim N(0,\sigma_u^2). \qquad (G.18)\]

Think of \(s_t\) as the true output gap and \(y_t\) as a noisy first estimate of it. We simulate 200 periods with \(\rho=0.9\) and \(\sigma_e=\sigma_u=1\), so we know the truth and can see how well the filter recovers it.

Python note. np.random.default_rng(2026) creates a random number generator with a fixed seed, so the numbers are the same every time; rng.normal() draws one number from the standard normal distribution.

rho_true, sig_e, sig_u = 0.9, 1.0, 1.0
T_data = 200
rng = np.random.default_rng(2026)
s_true = np.zeros(T_data)
y_obs = np.zeros(T_data)
s_prev = 0.0
for t in range(T_data):
    s_true[t] = rho_true * s_prev + sig_e * rng.normal()    # equation (G.17)
    y_obs[t] = s_true[t] + sig_u * rng.normal()             # equation (G.18)
    s_prev = s_true[t]
print(f"Standard deviation of the state: {s_true.std():.2f}, of the data: {y_obs.std():.2f}")
Standard deviation of the state: 2.00, of the data: 2.25

Each period the filter does three things. Write \(\hat{s}_{t|t-1}\) for the best guess of the state before seeing \(y_t\), \(\hat{s}_{t|t}\) for the guess after, and \(P\) for the variance (the uncertainty) of each guess.

  1. Predict the state with the model: \(\hat{s}_{t|t-1}=\rho\,\hat{s}_{t-1|t-1}\) and \(P_{t|t-1}=\rho^2P_{t-1|t-1}+\sigma_e^2\). (G.19)
  2. Compare with the data: the forecast error is \(v_t=y_t-\hat{s}_{t|t-1}\), with variance \(F_t=P_{t|t-1}+\sigma_u^2\). (G.20)
  3. Update: move the guess toward the data by the Kalman gain \(K_t=P_{t|t-1}/F_t\): \(\hat{s}_{t|t}=\hat{s}_{t|t-1}+K_tv_t\) and \(P_{t|t}=(1-K_t)P_{t|t-1}\). (G.21)

The gain weighs the two sources of information: when the model’s prediction is uncertain (\(P\) large) the filter trusts the data; when the data are noisy (\(\sigma_u\) large) it trusts the model. Before the first observation we use the long-run variance of the state, \(\sigma_e^2/(1-\rho^2)\); Snowdrop calls this choice Prior="Equilibrium".

The likelihood comes for free. If the model is right, each forecast error \(v_t\) is normal with mean 0 and variance \(F_t\). The probability of the whole sample is the product of these normal densities, so its logarithm is a sum:

\[\log L=-\frac{1}{2}\sum_{t=1}^{T}\Big(\log 2\pi+\log F_t+\frac{v_t^2}{F_t}\Big). \qquad (G.22)\]

def kalman_filter(y, rho, sig_e, sig_u):
    """Equations (G.19)-(G.21) for the model (G.17)-(G.18); returns the filtered states and log L of (G.22)."""
    s_hat = 0.0                                    # the state's mean before any data
    P = sig_e**2 / (1 - rho**2)                    # and its long-run variance
    filtered = np.zeros(len(y))
    loglik = 0.0
    for t in range(len(y)):
        s_pred = rho * s_hat                       # 1. predict
        P_pred = rho**2 * P + sig_e**2
        v = y[t] - s_pred                          # 2. compare: forecast error and its variance
        F = P_pred + sig_u**2
        K = P_pred / F                             # 3. update with the Kalman gain
        s_hat = s_pred + K * v
        P = (1 - K) * P_pred
        filtered[t] = s_hat
        loglik = loglik - 0.5 * (np.log(2 * np.pi) + np.log(F) + v**2 / F)
    return filtered, loglik

filtered, loglik = kalman_filter(y_obs, rho_true, sig_e, sig_u)
print(f"Log-likelihood at the true parameters: {loglik:.2f}")
print(f"Typical error: data {np.std(y_obs - s_true):.2f}, filtered state {np.std(filtered - s_true):.2f}")
Log-likelihood at the true parameters: -381.78
Typical error: data 1.07, filtered state 0.76
fig, ax = book_figure()
periods = np.arange(1, 81)
ax.plot(periods, y_obs[:80], color=GRAY, linestyle="none", marker="o", markersize=3.5, label="data $y_t$")
ax.plot(periods, s_true[:80], color=TEAL, linewidth=1.6, label="true state $s_t$")
ax.plot(periods, filtered[:80], color=BLUE, linewidth=2.4, label="filtered state $\\hat{s}_{t|t}$")
ax.set_title("The Kalman filter recovers the state from noisy data (first 80 periods)")
ax.set_xlabel("period")
ax.legend(loc="upper left")
show(fig, "The filtered state follows the true state much more closely than the noisy data do")
The filtered state follows the true state much more closely than the noisy data do

What to notice. The data jump around the true state; the filtered state follows the truth much more closely, because it combines each new observation with what the model predicted. The filter’s error is smaller than the error of the raw data.

The same filter with matrices. For a model with many variables, the scalars become matrices: \(P_{t|t-1}=TP_{t-1|t-1}T'+RQR'\), \(F_t=ZP_{t|t-1}Z'+H\) and \(K_t=P_{t|t-1}Z'F_t^{-1}\), where \(Q\) and \(H\) hold the variances of the shocks and of the measurement errors. The log-likelihood has the same form, with \(\log\det F_t\) and \(v_t'F_t^{-1}v_t\). Snowdrop’s Durbin_Koopman filter does this, in a version that is fast and numerically careful (Durbin and Koopman, 2012).

Your turn. Make the data noisier, \(\sigma_u=3\): simulate the data again and filter them. How does the filtered state change? Print the Kalman gain of the last period.

Show the answer

With noisy data the filter trusts the model more: the Kalman gain falls from about 0.6 to about 0.23, so each new observation moves the estimate less. The filtered state becomes smoother and reacts to the data more slowly.

sig_u = 3.0
y_noisy = s_true + sig_u * np.random.default_rng(7).normal(size=T_data)
filtered_noisy, ll = kalman_filter(y_noisy, rho_true, sig_e, sig_u)
P = sig_e**2 / (1 - rho_true**2)
for t in range(T_data):                       # the gain does not depend on the data, only on the variances
    P_pred = rho_true**2 * P + sig_e**2
    K = P_pred / (P_pred + sig_u**2)
    P = (1 - K) * P_pred
print(f"Kalman gain with sig_u = 3: {K:.2f}")
sig_u = 1.0                                   # back to the baseline
# Your turn: try it here

G.10 Maximum likelihood from small pieces

The likelihood of one parameter

Pretend we do not know \(\rho\). Every value of \(\rho\) gives a value of the log-likelihood (G.22): how probable the observed data would be if \(\rho\) were the truth. The maximum likelihood estimate is the value that makes the data most probable. With one parameter we can simply try a grid of values.

rho_grid = np.linspace(0.5, 0.99, 99)
loglik_grid = np.zeros(len(rho_grid))
for k in range(len(rho_grid)):
    filtered_k, loglik_grid[k] = kalman_filter(y_obs, rho_grid[k], sig_e, sig_u)
rho_best = rho_grid[np.argmax(loglik_grid)]

fig, ax = book_figure()
ax.plot(rho_grid, loglik_grid, color=BLUE)
ax.axvline(rho_true, color=GRAY, linestyle="--", label=f"true value {rho_true}")
ax.axvline(rho_best, color=RUST, label=f"maximum at {rho_best:.3f}")
ax.set_ylim(loglik_grid.max() - 40, loglik_grid.max() + 4)
ax.set_title("The log-likelihood of the persistence parameter")
ax.set_xlabel("$\\rho$")
ax.set_ylabel("log-likelihood")
ax.legend(loc="lower center")
show(fig, "The log-likelihood is highest near the true persistence of 0.9")
The log-likelihood is highest near the true persistence of 0.9

Curvature and the standard error

How sure can we be? If the log-likelihood falls steeply on both sides of its peak, values far from the peak are much less likely, and the estimate is precise. If it is flat, many values fit the data almost as well. The curvature at the peak, the second derivative, measures this, and the standard error of the estimate is \(1/\sqrt{-\text{curvature}}\). We compute the second derivative numerically, from three nearby points. Snowdrop does exactly this for all its parameters at once.

def negative_loglik_rho(rho):
    """Minus the log-likelihood (G.22) as a function of rho alone (the two sigmas stay at their true values)."""
    filtered_k, ll = kalman_filter(y_obs, rho, sig_e, sig_u)
    return -ll

result = optimize.minimize_scalar(negative_loglik_rho, bounds=(0.01, 0.999), method="bounded")
rho_hat = result.x
h = 1e-4
curvature = -(negative_loglik_rho(rho_hat + h) - 2 * negative_loglik_rho(rho_hat)
              + negative_loglik_rho(rho_hat - h)) / h**2
se = 1 / np.sqrt(-curvature)
print(f"Estimate {rho_hat:.4f}, standard error {se:.4f}")
print(f"95 percent interval: {rho_hat - 1.96 * se:.3f} to {rho_hat + 1.96 * se:.3f} (true value {rho_true})")
Estimate 0.8512, standard error 0.0376
95 percent interval: 0.778 to 0.925 (true value 0.9)

All parameters at once, with a numerical optimizer

In practice we estimate all parameters together. A numerical optimizer searches for the maximum, here SciPy’s L-BFGS-B, the method Snowdrop uses. It accepts bounds: \(\rho\) must lie between 0 and 1, and standard deviations must be positive. The matrix of second derivatives (the Hessian) then gives the standard errors: they are the square roots of the diagonal of the inverse of minus the Hessian.

Python note. optimize.minimize finds the minimum of a function, so we give it minus the log-likelihood. x0 is the starting point, bounds one (lower, upper) pair per parameter, and result.x the solution.

def negative_loglik(theta):
    """Minus the log-likelihood (G.22) of theta = (rho, sig_e, sig_u)."""
    filtered_k, ll = kalman_filter(y_obs, theta[0], theta[1], theta[2])
    return -ll

result = optimize.minimize(negative_loglik, x0=[0.5, 0.5, 0.5], method="L-BFGS-B",
                           bounds=[(0.01, 0.999), (0.01, 10.0), (0.01, 10.0)])

def hessian(f, x, h=1e-4):
    """The matrix of second derivatives of f at x, by central differences."""
    n = len(x)
    H = np.zeros((n, n))
    for i in range(n):
        for j in range(n):
            e_i, e_j = np.eye(n)[i] * h, np.eye(n)[j] * h
            H[i, j] = (f(x + e_i + e_j) - f(x + e_i - e_j) - f(x - e_i + e_j) + f(x - e_i - e_j)) / (4 * h * h)
    return H

std_errors = np.sqrt(np.diag(np.linalg.inv(hessian(negative_loglik, result.x))))
pd.DataFrame({"true": [rho_true, sig_e, sig_u], "estimate": result.x, "std. error": std_errors},
             index=["rho", "sigma_e", "sigma_u"]).round(3)
true estimate std. error
rho 0.9 0.747 0.080
sigma_e 1.0 1.455 0.243
sigma_u 1.0 0.546 0.417

What to notice. The optimizer started far from the truth (0.5 for every parameter) and found the peak of the likelihood. (Since negative_loglik is minus the log-likelihood, its Hessian is already “minus the curvature”.) The estimates are within about two standard errors of the true values, but they are not very close, and the standard error of \(\sigma_u\) is almost as large as the estimate. With 200 observations the data cannot tell well how much of the movement in \(y_t\) comes from shocks to the state and how much from noise in the measurement. This is a first taste of weak identification, which we will meet again in Ireland’s model. That is the whole of maximum likelihood estimation: write the model in state-space form, compute the likelihood with the Kalman filter, and let an optimizer find its peak. Snowdrop does the same for a model with seven variables and twelve parameters.

Your turn. Estimate \(\rho\) from the first 50 observations only (y_obs[:50]). How do the log-likelihood curve and the standard error change?

Show the answer

With a quarter of the data the log-likelihood is flatter, so the standard error is about twice as large (it shrinks with the square root of the sample size), and the estimate may land further from 0.9.

def negative_loglik_short(rho):
    """Minus the log-likelihood of the first 50 observations."""
    filtered_k, ll = kalman_filter(y_obs[:50], rho, sig_e, sig_u)
    return -ll
rho_short = optimize.minimize_scalar(negative_loglik_short, bounds=(0.01, 0.999), method="bounded").x
h = 1e-4
curv = -(negative_loglik_short(rho_short + h) - 2 * negative_loglik_short(rho_short) + negative_loglik_short(rho_short - h)) / h**2
print(f"Estimate {rho_short:.3f}, standard error {1 / np.sqrt(-curv):.3f}")
# Your turn: try it here

G.11 Estimating Ireland (2004) by maximum likelihood

The model

Ireland (2004) asked how much technology shocks, the heart of real business cycle theory, matter once a New Keynesian model gives other shocks a chance. His model has four shocks and seven equations. All variables are deviations from the steady state, quarterly, in decimals:

\[a_t=\rho_a\,a_{t-1}+\varepsilon_{at} \qquad (G.23)\]

\[e_t=\rho_e\,e_{t-1}+\varepsilon_{et} \qquad (G.24)\]

\[x_t=\alpha_x\,x_{t-1}+(1-\alpha_x)\,\mathbb{E}_tx_{t+1}-(r_t-\mathbb{E}_t\pi_{t+1})+(1-\omega)(1-\rho_a)\,a_t \qquad (G.25)\]

\[\pi_t=\beta\,[\alpha_\pi\,\pi_{t-1}+(1-\alpha_\pi)\,\mathbb{E}_t\pi_{t+1}]+\psi\,x_t-e_t \qquad (G.26)\]

\[x_t=y_t-\omega\,a_t \qquad (G.27)\]

\[g_t=y_t-y_{t-1}+\varepsilon_{zt} \qquad (G.28)\]

\[r_t-r_{t-1}=\rho_\pi\,\pi_t+\rho_g\,g_t+\rho_x\,x_t+\varepsilon_{rt} \qquad (G.29)\]

  • (G.23) and (G.24) are the preference shock \(a_t\) and the cost-push shock \(e_t\), both AR(1).
  • (G.25) is the IS curve: the output gap \(x_t\) depends on the expected gap and the real interest rate, as in Chapters 11 and 12, with a preference shock that raises demand. \(\alpha_x\) adds a backward-looking element.
  • (G.26) is the New Keynesian Phillips curve of Section G.4, with a backward-looking weight \(\alpha_\pi\).
  • (G.27) defines the output gap as output minus its efficient level, which moves with the preference shock.
  • (G.28) is output growth \(g_t\); \(\varepsilon_{zt}\) is the technology shock. It changes the level of output permanently, so it shows up in growth.
  • (G.29) is the monetary policy rule, written in changes of the interest rate: the Fed raises the rate when inflation, output growth or the output gap are high (Chapter 13).

We observe three variables: output growth, inflation and the interest rate. Following Ireland, there are no measurement errors, so \(g^{obs}_t=g_t\), \(\pi^{obs}_t=\pi_t\) and \(r^{obs}_t=r_t\). The discount factor \(\beta=0.99\) and the slope \(\psi=0.1\) are fixed; the other twelve parameters (eight coefficients and four shock standard deviations) are estimated.

The data

Snowdrop’s file holds Ireland’s U.S. data from 1948Q1 to 2002Q4: per-capita real GDP growth, inflation of the GDP deflator, and the three-month Treasury bill rate, all as quarterly rates. Ireland’s own sample ends one quarter later, in 2003Q1. The columns obs_g, obs_pie and obs_r are deviations from the sample means, which is what the model needs; obsg, obspie and obsr are the raw rates.

data = pd.read_csv("gpr_1948.csv", index_col=0, parse_dates=True)
print(data.index[0].date(), "to", data.index[-1].date(), "-", len(data), "quarters")
print("Averages at annual rates (percent):", (400 * data[["obsg", "obspie", "obsr"]].mean()).round(2).to_dict())
data.head()
1948-01-01 to 2002-10-01 - 220 quarters
Averages at annual rates (percent): {'obsg': 1.94, 'obspie': 3.43, 'obsr': 5.0}
obs_g obs_pie obs_r obsg obspie obsr
Date
1948-01-01 0.008526 0.002566 -0.009989 0.013364 0.011147 0.002503
1948-04-01 -0.003986 0.011634 -0.009863 0.000852 0.020214 0.002628
1948-07-01 -0.004559 -0.005726 -0.009638 0.000279 0.002855 0.002854
1948-10-01 -0.020547 -0.013725 -0.009562 -0.015709 -0.005144 0.002929
1949-01-01 -0.010063 -0.020108 -0.009562 -0.005225 -0.011528 0.002929
fig, axes = book_figure(1, 3, width=12, height=3.6)
series = [("obsg", "Output growth"), ("obspie", "Inflation"), ("obsr", "Interest rate")]
for k in range(3):
    column, title = series[k]
    axes[k].plot(data.index, 400 * data[column], color=SERIES[k * 2], linewidth=1.4)
    axes[k].set_title(title + ", % per year")
fig.suptitle("Ireland's data: the United States, 1948-2002", y=1.04)
show(fig, "U.S. output growth, inflation and the Treasury bill rate from 1948 to 2002")
U.S. output growth, inflation and the Treasury bill rate from 1948 to 2002

The model file

Snowdrop’s file has the four estimation blocks we skipped in Section G.5:

  • measurement_variables and measurement_equations link the data columns to the model (obs_g = g + res_obs_g);
  • measurement_shocks are the measurement errors, here with standard deviations of zero;
  • estimated_parameters lists the parameters to estimate, one per line: name, starting value, lower bound, upper bound, prior distribution, prior mean, prior standard deviation. Maximum likelihood uses only the first four entries; the prior comes in Section G.12. The shock standard deviations are estimated too, as std_epsa and so on.

The calibration block holds Ireland’s own estimates, and options sets the sample (range, and filter_range for the filter).

text = open("Ireland2004.yaml").read()
print(text[text.find("measurement_equations"):text.find("labels")])
measurement_equations: 
    - obs_g   = g   + res_obs_g
    - obs_pie = pie + res_obs_pie
    - obs_r   = r   + res_obs_r

calibration:
   # parameters:
    beta :     0.99
    psi :      0.1
    omega :    0.0617
    alphax :   0.0836
    alphapie : 0.0001
    rhopie :   0.3597
    rhog :     0.2536
    rhox :     0.0347
    rhoa :     0.9470
    rhoe :     0.9625

    # starting values for endogenous variables:
    y:   0.0 
    pie: 0.0
    r: 0.0
    g: 0.0
    x: 0.0
    a: 0.0
    e: 0.0
    
    #Standard deviation of shocks:
    std_epsa: 0.0405
    std_epse: 0.0012
    std_epsz: 0.0109
    std_epsr: 0.0031
      
    #Standard deviations of observation errors:
    std_res_obs_g:   0
    std_res_obs_pie: 0
    std_res_obs_r:   0
    

estimated_parameters:
    # Please choose one of the following distributions: 
    # normal_pdf,lognormal_pdf,beta_pdf,gamma_pdf,t_pdf,weibull_pdf,inv_gamma_pdf,inv_weibull_pdf,wishart_pdf,inv_wishart_pdf    
    # PARAM NAME, INITVAL, LB, UB, PRIOR_SHAPE, PRIOR_P1, PRIOR_P2, PRIOR_P3, PRIOR_P4, PRIOR_P5
    # The first parameter is the parameter name, the second is the initial value, the third and 
    # the fourth are the lower and the upper bounds,the fifth is the prior shape, 
    # the sixth to tenth are prior parameters (mean, standard deviation, shape, etc.).
    # Parameters
    - omega,    0.2, 1.e-7, 1,  normal_pdf, 0.20, 0.02
    - alphax,   0.08,  1.e-7, 1,  normal_pdf, 0.10, 0.05
    - alphapie, 1.e-4, 1.e-7, 1,  normal_pdf, 5.e-6, 1.e-6
    - rhoa,     0.9,  1.e-7, 1,  normal_pdf, 0.85, 0.10
    - rhoe,     0.9,  1.e-7, 1,  normal_pdf, 0.85, 0.10
    - rhopie,   0.3,  1.e-7, 1,  normal_pdf, 0.30, 0.1
    - rhog,     0.2,  1.e-7, 1,  normal_pdf, 0.30, 0.1
    - rhox,     0.03,  1.e-7, 1,  normal_pdf, 0.25, 0.0625
    
    # Endogenous variables shocks
    # should we use inverse wishart distribution for sigma^-2: inverse wishart_pdf ?
    - std_epsa, 0.0405, 1.e-7, 1,  normal_pdf, 0.03,      1.80
    - std_epse, 0.0012, 1.e-7, 1,  normal_pdf, 0.0000727, 0.0000582
    - std_epsz, 0.0109, 1.e-7, 1,  normal_pdf, 0.005,     0.275
    - std_epsr, 0.0031, 1.e-7, 1,  normal_pdf, 0.005,     0.004417
    
    # # Measurement variables shocks
    # - std_res_obs_g,   0.01,  0, 10, normal_pdf, 0.03, 2
    # - std_res_obs_pie, 0.01,  0, 10, normal_pdf, 0.03, 2
    # - std_res_obs_r,   0.01,  0, 10, normal_pdf, 0.03, 2
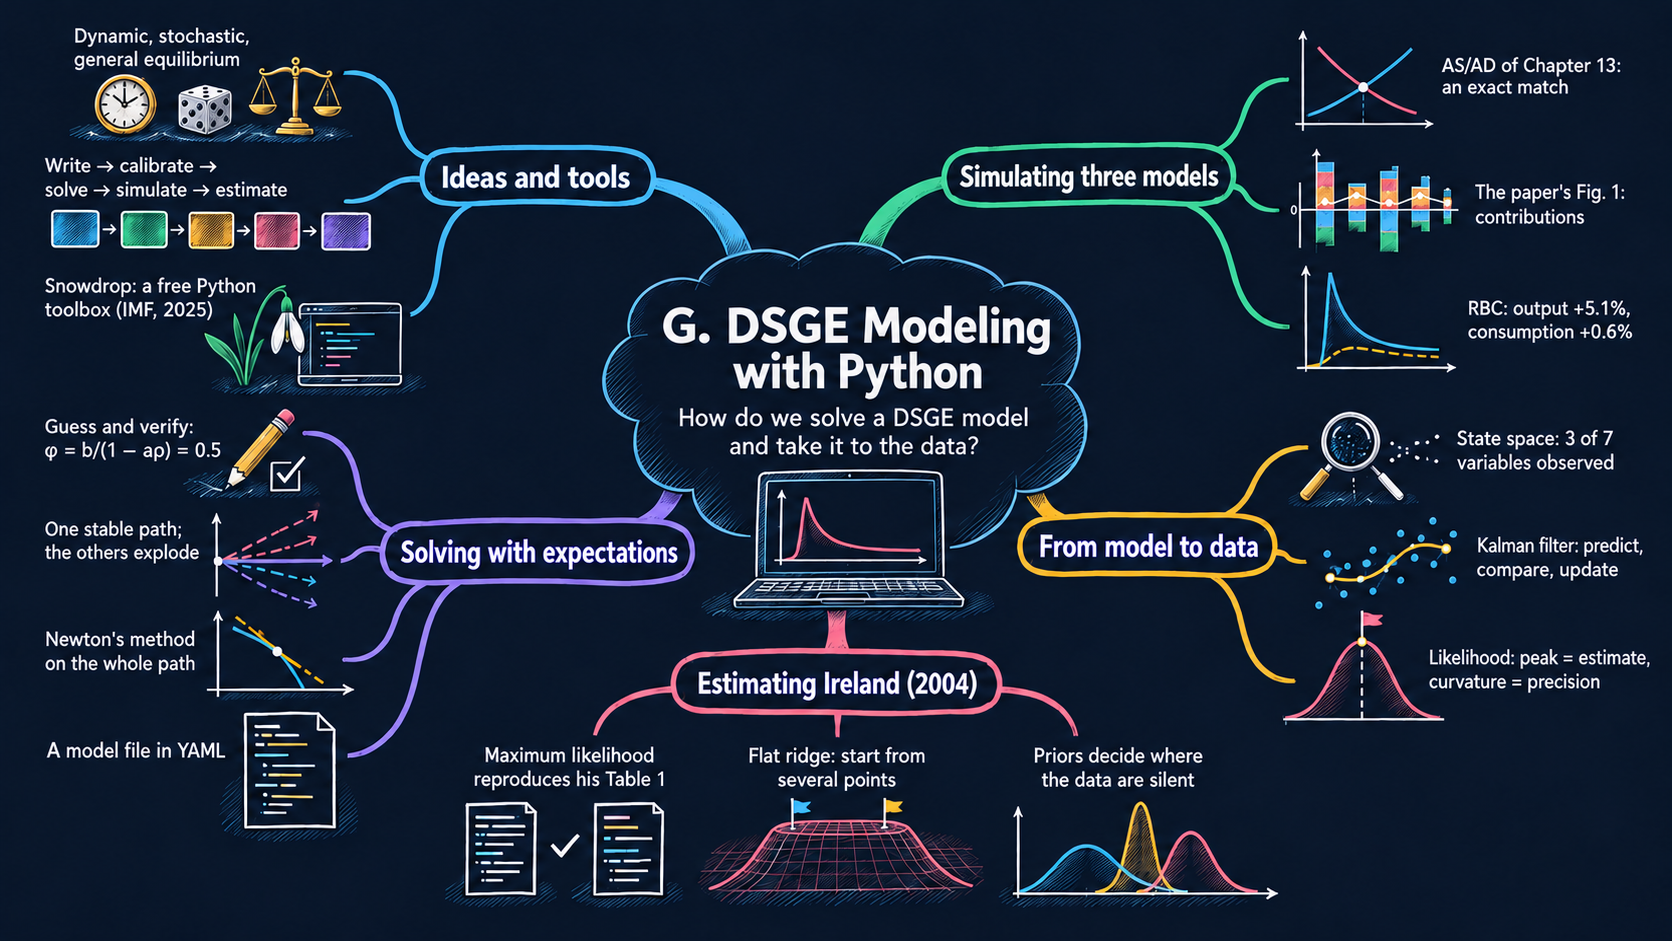
One thing in the file is wrong: some labels do not match Ireland’s model. The file calls a “Total Factor Productivity” and e “Aggregate Technology”, but in the equations a is the preference shock and e the cost-push shock; epsz, the technology shock, is labelled “Shock to Output Gap”. Labels only name charts, but wrong names mislead, so we fix them in our copy, ireland.yaml.

Python note. re.sub(pattern, replacement, text, count=1) replaces the first match of a pattern. Here the pattern finds a line such as a: "…", and re.escape protects characters like ( in a(-1).

fixes = {"a": "Preference shock", "a(-1)": "Lag of the preference shock", "e": "Cost-push shock",
         "e(-1)": "Lag of the cost-push shock", "epsa": "Innovation to preferences",
         "epse": "Innovation to the cost-push shock", "epsz": "Technology shock", "epsr": "Monetary policy shock"}
for key in fixes:
    pattern = r'(\n\s*' + re.escape(key) + r':\s*)"[^"]*"'
    text = re.sub(pattern, r'\g<1>"' + fixes[key] + '"', text, count=1)
open("ireland.yaml", "w").write(text)
print(text[text.find("labels"):text.find("options")])
labels:
   y:       "Output"
   y(-1):   "Lag of Output"
   x:       "Output Gap"
   x(-1):   "Lag of Output Gap"
   x(+1):   "Lead of Output Gap"
   r:       "Interest Rate"
   r(-1):   "Lag of Interest Rate"
   pie:     "Inflation"
   g:       "Output Growth"
   pie(+1): "Lead of Inflation"
   pie(-1): "Lag of Inflation"
   a:       "Preference shock"
   a(-1):   "Lag of the preference shock"
   e:       "Cost-push shock"
   e(-1):   "Lag of the cost-push shock"
   epsa:    "Innovation to preferences"
   epse:    "Innovation to the cost-push shock"
   epsz:    "Technology shock"
   epsr:    "Monetary policy shock"


A first run

We read the model with four settings. Solver="Klein" solves the linear model with the generalized Schur method (the method of IRIS). Filter="Durbin_Koopman" is the filter; Snowdrop’s estimation works only with this filter or "Non_Diffuse_Filter". Smoother="Durbin_Koopman" lets Snowdrop also compute the smoothed variables that we plot below. Prior="Equilibrium" starts the filter from the long-run variance of the state, as in Section G.9. (In this option, “prior” means the filter’s starting point, not the priors of Section G.12.) Then estimate(..., estimate_ML=True) maximizes the likelihood, starting from the second column of estimated_parameters. This takes about one minute here, and about two minutes in Colab.

DATA = os.path.join(WORK, "gpr_1948.csv")
ireland = load_model("ireland.yaml", Solver="Klein", Filter="Durbin_Koopman", Smoother="Durbin_Koopman",
                     Prior="Equilibrium", measurement_file_path=DATA)
first_try, out = estimate(ireland, estimate_ML=True)
print(f"\nLog-likelihood at the estimates: {first_try.attrs['log value']:.2f}")
Number of iterations performed by the optimizer: 57, function value: 2646.66

Maximum Likelihood Estimation
+----------+----------------+----------+---------+
|   Name   | Starting Value | Estimate |   Std.  |
+----------+----------------+----------+---------+
|  omega   |    0.20000     | 0.19257  | 0.05132 |
|  alphax  |    0.08000     | 0.07896  | 0.13175 |
| alphapie |    0.00010     | 0.00000  | 0.00000 |
|  rhopie  |    0.30000     | 0.30138  | 0.02429 |
|   rhog   |    0.20000     | 0.21055  | 0.03047 |
|   rhox   |    0.03000     | 0.05012  | 0.01347 |
|   rhoa   |    0.90000     | 0.94518  | 0.01116 |
|   rhoe   |    0.90000     | 0.91956  | 0.02103 |
| std_epsa |    0.04050     | 0.03433  | 0.00578 |
| std_epse |    0.00120     | 0.00126  | 0.00017 |
| std_epsz |    0.01090     | 0.00895  | 0.00173 |
| std_epsr |    0.00310     | 0.00284  | 0.00026 |
+----------+----------------+----------+---------+

Log-likelihood at the estimates: 2646.66

The table shows each parameter’s starting value, its estimate and its standard error. Before we read it, one warning. The optimizer of this first run starts from rough values (0.2, 0.08, 0.3, …) and stops when it no longer finds improvements. On a flat likelihood it can stop in different places on different computers: the numbers in your table may differ from ours, and so may the log-likelihood. A careful researcher never trusts a single run.

Starting from Ireland’s estimates

A good check is to start the search somewhere else and see whether it ends at the same peak. We start from Ireland’s published estimates, which are in the calibration block of the file. We write them into the second column of estimated_parameters.

ireland_published = {"omega": 0.0617, "alphax": 0.0836, "alphapie": 0.0001, "rhopie": 0.3597,
                     "rhog": 0.2536, "rhox": 0.0347, "rhoa": 0.9470, "rhoe": 0.9625,
                     "std_epsa": 0.0405, "std_epse": 0.0012, "std_epsz": 0.0109, "std_epsr": 0.0031}
text = open("ireland.yaml").read()
for name in ireland_published:
    pattern = r"(\n\s*-\s*" + name + r",\s*)[0-9.e+-]+"
    text = re.sub(pattern, r"\g<1>" + str(ireland_published[name]), text, count=1)
open("ireland_start.yaml", "w").write(text)
print(text[text.find("estimated_parameters"):text.find("labels")])
estimated_parameters:
    # Please choose one of the following distributions: 
    # normal_pdf,lognormal_pdf,beta_pdf,gamma_pdf,t_pdf,weibull_pdf,inv_gamma_pdf,inv_weibull_pdf,wishart_pdf,inv_wishart_pdf    
    # PARAM NAME, INITVAL, LB, UB, PRIOR_SHAPE, PRIOR_P1, PRIOR_P2, PRIOR_P3, PRIOR_P4, PRIOR_P5
    # The first parameter is the parameter name, the second is the initial value, the third and 
    # the fourth are the lower and the upper bounds,the fifth is the prior shape, 
    # the sixth to tenth are prior parameters (mean, standard deviation, shape, etc.).
    # Parameters
    - omega,    0.0617, 1.e-7, 1,  normal_pdf, 0.20, 0.02
    - alphax,   0.0836,  1.e-7, 1,  normal_pdf, 0.10, 0.05
    - alphapie, 0.0001, 1.e-7, 1,  normal_pdf, 5.e-6, 1.e-6
    - rhoa,     0.947,  1.e-7, 1,  normal_pdf, 0.85, 0.10
    - rhoe,     0.9625,  1.e-7, 1,  normal_pdf, 0.85, 0.10
    - rhopie,   0.3597,  1.e-7, 1,  normal_pdf, 0.30, 0.1
    - rhog,     0.2536,  1.e-7, 1,  normal_pdf, 0.30, 0.1
    - rhox,     0.0347,  1.e-7, 1,  normal_pdf, 0.25, 0.0625
    
    # Endogenous variables shocks
    # should we use inverse wishart distribution for sigma^-2: inverse wishart_pdf ?
    - std_epsa, 0.0405, 1.e-7, 1,  normal_pdf, 0.03,      1.80
    - std_epse, 0.0012, 1.e-7, 1,  normal_pdf, 0.0000727, 0.0000582
    - std_epsz, 0.0109, 1.e-7, 1,  normal_pdf, 0.005,     0.275
    - std_epsr, 0.0031, 1.e-7, 1,  normal_pdf, 0.005,     0.004417
    
    # # Measurement variables shocks
    # - std_res_obs_g,   0.01,  0, 10, normal_pdf, 0.03, 2
    # - std_res_obs_pie, 0.01,  0, 10, normal_pdf, 0.03, 2
    # - std_res_obs_r,   0.01,  0, 10, normal_pdf, 0.03, 2

ireland = load_model("ireland_start.yaml", Solver="Klein", Filter="Durbin_Koopman", Smoother="Durbin_Koopman",
                     Prior="Equilibrium", measurement_file_path=DATA)
ml, out_ml = estimate(ireland, estimate_ML=True)
print(f"\nLog-likelihood at the estimates: {ml.attrs['log value']:.2f}")
print(f"Log-likelihood of the first run:  {first_try.attrs['log value']:.2f}")
Number of iterations performed by the optimizer: 14, function value: 2648.47

Maximum Likelihood Estimation
+----------+----------------+----------+---------+
|   Name   | Starting Value | Estimate |   Std.  |
+----------+----------------+----------+---------+
|  omega   |    0.06170     | 0.06193  | 0.06274 |
|  alphax  |    0.08360     | 0.08365  | 0.12247 |
| alphapie |    0.00010     | 0.00000  | 0.00000 |
|  rhopie  |    0.35970     | 0.35968  | 0.05140 |
|   rhog   |    0.25360     | 0.25364  | 0.03956 |
|   rhox   |    0.03470     | 0.03464  | 0.01567 |
|   rhoa   |    0.94700     | 0.94703  | 0.01487 |
|   rhoe   |    0.96250     | 0.96257  | 0.02753 |
| std_epsa |    0.04050     | 0.04019  | 0.00930 |
| std_epse |    0.00120     | 0.00124  | 0.00025 |
| std_epsz |    0.01090     | 0.01091  | 0.00284 |
| std_epsr |    0.00310     | 0.00311  | 0.00035 |
+----------+----------------+----------+---------+

Log-likelihood at the estimates: 2648.47
Log-likelihood of the first run:  2646.66

Our estimates next to Ireland’s

Ireland’s Table 1 reports his maximum likelihood estimates and standard errors. We put them next to ours.

ireland_se = {"omega": 0.0634, "alphax": 0.1139, "alphapie": 0.0737, "rhopie": 0.0469, "rhog": 0.0391,
              "rhox": 0.0152, "rhoa": 0.0250, "rhoe": 0.0248, "std_epsa": 0.0157, "std_epse": 0.0003,
              "std_epsz": 0.0028, "std_epsr": 0.0003}
compare = pd.DataFrame({"Ireland (2004)": pd.Series(ireland_published), "his s.e.": pd.Series(ireland_se),
                        "ours": ml["estimate"], "our s.e.": ml["std. error"], "first run": first_try["estimate"]})
compare.round(4)
Ireland (2004) his s.e. ours our s.e. first run
omega 0.0617 0.0634 0.0619 0.0627 0.1926
alphax 0.0836 0.1139 0.0836 0.1225 0.0790
alphapie 0.0001 0.0737 0.0000 0.0000 0.0000
rhopie 0.3597 0.0469 0.3597 0.0514 0.3014
rhog 0.2536 0.0391 0.2536 0.0396 0.2106
rhox 0.0347 0.0152 0.0346 0.0157 0.0501
rhoa 0.9470 0.0250 0.9470 0.0149 0.9452
rhoe 0.9625 0.0248 0.9626 0.0275 0.9196
std_epsa 0.0405 0.0157 0.0402 0.0093 0.0343
std_epse 0.0012 0.0003 0.0012 0.0002 0.0013
std_epsz 0.0109 0.0028 0.0109 0.0028 0.0090
std_epsr 0.0031 0.0003 0.0031 0.0004 0.0028
names = list(ireland_published)
greek = {"omega": "$\\omega$", "alphax": "$\\alpha_x$", "alphapie": "$\\alpha_\\pi$", "rhopie": "$\\rho_\\pi$",
         "rhog": "$\\rho_g$", "rhox": "$\\rho_x$", "rhoa": "$\\rho_a$", "rhoe": "$\\rho_e$",
         "std_epsa": "$\\sigma_a$", "std_epse": "$\\sigma_e$", "std_epsz": "$\\sigma_z$", "std_epsr": "$\\sigma_r$"}
fig, axes = book_figure(1, 2, width=12, height=4.6)
groups = [names[:8], names[8:]]
scales = [1, 100]                                   # shock standard deviations in percent
for k in range(2):
    pos = np.arange(len(groups[k]))
    est = scales[k] * compare.loc[groups[k], "ours"]
    err = scales[k] * 1.96 * compare.loc[groups[k], "our s.e."]
    axes[k].errorbar(pos - 0.12, est, yerr=err, fmt="o", color=BLUE, capsize=3, label="ours, ±1.96 s.e.")
    axes[k].plot(pos + 0.12, scales[k] * compare.loc[groups[k], "Ireland (2004)"], "D", color=RUST, label="Ireland (2004)")
    axes[k].set_xticks(pos)
    axes[k].set_xticklabels([greek[n] for n in groups[k]])
axes[0].set_title("Coefficients")
axes[1].set_title("Shock standard deviations, %")
axes[0].legend(loc="upper left")
show(fig, "Our maximum likelihood estimates with 95 percent intervals, next to Ireland's estimates")
Our maximum likelihood estimates with 95 percent intervals, next to Ireland's estimates

What to notice. Started from Ireland’s values, the search stays there: our estimates reproduce his Table 1 almost to the last digit, and most standard errors are close to his. Two exceptions are worth understanding:

  • \(\alpha_\pi\) sits at its lower bound of zero, and its standard error is reported as 0. That number is meaningless. Standard errors come from the curvature of the likelihood, which is computed by stepping a little to each side of the estimate; at a bound one side is off limits, so the calculation breaks down. Ireland reports a standard error of 0.07 for his estimate of zero, computed in a different way.
  • Some standard errors, such as those of \(\sigma_a\) and \(\rho_a\), differ from Ireland’s by a third or more. Numerical second derivatives are sensitive to the step size, and Ireland’s sample has one more quarter.

Why the two runs differ: a flat likelihood

Compare the two log-likelihoods printed above. When the first run ends lower, its optimizer simply stopped too early. But it can also happen that the first run reaches the same log-likelihood with very different values of \(\omega\) and \(\alpha_x\) (our test run in Colab did: \(\omega\approx0.16\) instead of 0.06, with the same log-likelihood to two decimals). Then the likelihood has a flat ridge: many combinations of these parameters fit the data equally well, and the data cannot tell them apart. Ireland’s large standard errors for \(\omega\) (0.063 for an estimate of 0.062) and \(\alpha_x\) say the same thing. Economists call such parameters weakly identified.

Three habits follow:

  1. Start the search from several places, including published estimates, and keep the run with the highest log-likelihood.
  2. Read the standard errors: a parameter whose standard error is as large as its estimate is barely identified; do not build conclusions on it.
  3. Know your software. Snowdrop computes the filter’s starting variance (Prior="Equilibrium") once, from the starting values, before the search begins. So the likelihood itself depends a little on where you start, one more reason to start near the answer.

Bayesian estimation, next, is the other standard remedy: a prior adds curvature exactly where the likelihood is flat.

What the estimated model says

estimate also returns the smoothed values of all seven variables: the filter’s best estimate of each one in each quarter, using the whole sample. Snowdrop’s plot shows them, with the data as dots. With no measurement errors, the three observed series are matched exactly; the interesting panels are the variables we never observe.

smoothed = np.asarray(out_ml[0])[1]                 # [0] holds the filtered values, [1] the smoothed ones
dates = list(out_ml[1])
measured = data[["obs_g", "obs_pie", "obs_r"]]
labels = {"y": "Output", "x": "Output gap", "r": "Interest rate", "g": "Output growth", "pie": "Inflation",
          "a": "Preference shock", "e": "Cost-push shock"}
figs = plot(path_to_dir=WORK, data=smoothed[1:], variable_names=ireland.symbols["variables"], meas_values=measured,
            meas_variables=list(measured.columns), output_variables=["g", "pie", "r", "x", "a", "e"],
            var_labels=labels, rng=dates, rng_meas=list(measured.index), sizes=(3, 2), figsize=(12, 9),
            header="Ireland (2004) estimated: data (dots) and smoothed variables", show=False, save=False)
show(figs[0], "The smoothed output gap, preference shock and cost-push shock over 1948-2002, with the observed "
     "series", snowdrop=True)
The smoothed output gap, preference shock and cost-push shock over 1948-2002, with the observed series

What to notice. The model reads the 1970s and the Volcker disinflation of 1979–1982 through the shocks. The cost-push shock falls sharply in 1974 and again in 1979–1980; it enters the Phillips curve (G.26) with a minus sign, so these dips are inflationary cost shocks, the two oil shocks. The output gap is deeply negative in the early 1980s, when the Fed raised interest rates to bring inflation down, while a large positive preference shock (strong demand) pushed the other way. In Ireland’s own decomposition of the forecast errors (his Table 2), technology shocks explain about a quarter of the variance of output growth, monetary policy shocks more than a third, and preference and cost-push shocks the rest: real business cycle theory is part of the story, not all of it.

The estimates themselves describe the U.S. economy:

  • The policy rule responds strongly to inflation (\(\rho_\pi\approx0.36\)) and output growth (\(\rho_g\approx0.25\)) and little to the output gap (\(\rho_x\approx0.03\)). Because the rule is written in changes, these responses accumulate over time.
  • The preference and cost-push shocks are very persistent (\(\rho_a\) and \(\rho_e\) near 0.95).
  • The backward-looking weights \(\alpha_x\) and \(\alpha_\pi\) are small: the data prefer the purely forward-looking IS and Phillips curves.

G.12 Bayesian estimation: priors and the posterior mode

Bayes’ rule with one parameter

Bayesian estimation treats parameters as uncertain and describes what we know about them with probability distributions. Before seeing the data, the prior \(p(\theta)\) sums up outside evidence. The data enter through the likelihood \(p(y\mid\theta)\). Bayes’ rule combines the two into the posterior:

\[p(\theta\mid y)\;\propto\;p(y\mid\theta)\,p(\theta),\qquad\text{so}\qquad \log p(\theta\mid y)=\log L(\theta)+\log p(\theta)+\text{constant}. \qquad (G.30)\]

The posterior mode is the value of \(\theta\) that maximizes the posterior: the maximum likelihood problem with one extra term, the log of the prior. Back to the AR(1) of Section G.9. Suppose we have only 40 observations, and an economist who believes shocks fade fast: her prior for \(\rho\) is a beta distribution with mean 0.5 and standard deviation 0.15.

Python note. A beta distribution lives between 0 and 1, which suits a persistence parameter. Its two shape parameters follow from the mean \(m\) and standard deviation \(s\): with \(k=m(1-m)/s^2-1\), they are \(mk\) and \((1-m)k\). stats.beta.logpdf(x, a, b) is the log of its density.

y_short = y_obs[:40]
m_prior, s_prior = 0.5, 0.15
k = m_prior * (1 - m_prior) / s_prior**2 - 1
a_prior, b_prior = m_prior * k, (1 - m_prior) * k

rho_grid = np.linspace(0.01, 0.99, 197)
log_prior = stats.beta.logpdf(rho_grid, a_prior, b_prior)
log_lik = np.zeros(len(rho_grid))
for j in range(len(rho_grid)):
    filtered_j, log_lik[j] = kalman_filter(y_short, rho_grid[j], sig_e, sig_u)
log_post = log_lik + log_prior                       # equation (G.30)

def density(log_values):
    """Turn log values on the grid into a density that integrates to one."""
    values = np.exp(log_values - log_values.max())
    return values / (values.sum() * (rho_grid[1] - rho_grid[0]))

print(f"Prior mean {m_prior}, maximum likelihood {rho_grid[log_lik.argmax()]:.3f}, "
      f"posterior mode {rho_grid[log_post.argmax()]:.3f}")
Prior mean 0.5, maximum likelihood 0.815, posterior mode 0.740
fig, ax = book_figure()
ax.plot(rho_grid, density(log_prior), color=GRAY, linestyle="--", label="prior")
ax.plot(rho_grid, density(log_lik), color=TEAL, label="likelihood (scaled)")
ax.plot(rho_grid, density(log_post), color=BLUE, linewidth=3, label="posterior")
ax.axvline(rho_true, color=AXIS, linewidth=1, gid="rule")
ax.set_title("Prior, likelihood and posterior of the persistence parameter (40 observations)")
ax.set_xlabel("$\\rho$ (the thin line is the true value, 0.9)")
ax.set_ylabel("density")
ax.legend(loc="upper left")
show(fig, "The posterior lies between the prior and the likelihood, closer to the more precise of the two")
The posterior lies between the prior and the likelihood, closer to the more precise of the two

What to notice. The posterior is a compromise between the prior and the likelihood, and it leans toward whichever is more precise. With 40 observations the likelihood is narrower than the prior, so the data win most of the argument, but the prior still pulls the posterior mode down from the maximum likelihood estimate. With more data the likelihood narrows further and the prior matters less. Where the likelihood is flat, as for \(\omega\) in Ireland’s model, the prior decides.

The posterior mode of Ireland’s model, with the file’s priors

The last three entries of each line of estimated_parameters are the prior: its distribution, mean and standard deviation. Snowdrop’s file uses normal priors throughout. estimate_Posterior=True maximizes the log-likelihood plus the log of the priors. We start from the same values as the maximum likelihood run.

ireland = load_model("ireland_start.yaml", Solver="Klein", Filter="Durbin_Koopman", Smoother="Durbin_Koopman",
                     Prior="Equilibrium", measurement_file_path=DATA)
file_priors = ireland.priors                        # name -> distribution and its parameters
post_file, out_post = estimate(ireland, estimate_Posterior=True)
print(f"\nLog-likelihood plus log-prior at the mode: {post_file.attrs['log value']:.2f}")
Posterior Maximum Likelihood Estimation
+----------+----------------+----------+---------+
|   Name   | Starting Value | Estimate |   Std.  |
+----------+----------------+----------+---------+
|  omega   |    0.06170     | 0.15462  | 0.01946 |
|  alphax  |    0.08360     | 0.10996  | 0.13699 |
| alphapie |    0.00010     | 0.00000  | 0.00000 |
|  rhopie  |    0.35970     | 0.34827  | 0.10025 |
|   rhog   |    0.25360     | 0.27560  | 0.07147 |
|   rhox   |    0.03470     | 0.06979  | 0.08411 |
|   rhoa   |    0.94700     | 0.92451  | 0.02355 |
|   rhoe   |    0.96250     | 0.96259  | 0.03793 |
| std_epsa |    0.04050     | 0.02547  | 0.00418 |
| std_epse |    0.00120     | 0.00092  | 0.00062 |
| std_epsz |    0.01090     | 0.01182  | 0.00433 |
| std_epsr |    0.00310     | 0.00341  | 0.00075 |
+----------+----------------+----------+---------+

Log-likelihood plus log-prior at the mode: 2640.56

A chart for each parameter shows its prior (the curve), the maximum likelihood estimate (dashed) and the posterior mode (solid). Snowdrop’s pdf function gives the prior densities exactly as estimate computes them.

Show the helper code
# @title Helper code: prior densities and the prior-versus-estimates charts
from snowdrop.src.utils.distributions import pdf, getHyperParameters

def prior_density(prior, x):
    """Snowdrop's prior density of one parameter at the points x, as estimate() evaluates it."""
    distribution = prior["distribution"]
    pars = np.array(prior["parameters"], dtype=float)
    if not distribution.endswith("_hp"):
        pars[3], pars[4] = getHyperParameters(distr=distribution, mean=pars[3], std=pars[4])
    values = np.zeros(len(x))
    for i in range(len(x)):
        values[i] = pdf(distribution, x[i], pars)[0]
    return values

def prior_panels(priors, estimates, title):
    """One panel per parameter: the prior density and vertical lines for the estimates {label: Series}."""
    fig, axes = book_figure(3, 4, width=13, height=8.4)
    styles = [("--", RUST), ("-", BLUE), ("-", TEAL)]
    for k in range(len(names)):
        name, ax = names[k], axes[k]
        lower, upper, mean, sd = [float(v) for v in priors[name]["parameters"][1:5]]
        values = [float(est[name]) for est in estimates.values()]
        lo = max(lower, min(mean - 3 * sd, min(values) * 0.7))
        hi = min(upper, max(mean + 3 * sd, max(values) * 1.3), 5 * max(max(values), mean))
        x = np.linspace(lo, hi, 300)
        ax.fill_between(x, prior_density(priors[name], x), color=GRAY, alpha=0.35, linewidth=0)
        j = 0
        for label, est in estimates.items():
            ax.axvline(float(est[name]), linestyle=styles[j][0], color=styles[j][1], label=label)
            j += 1
        ax.set_title(greek[name] + "  (" + priors[name]["distribution"].replace("_pdf", "") + ")", fontsize=11)
        ax.set_yticks([])
        ax.tick_params(axis="x", labelsize=8)
    axes[0].legend(fontsize=8, loc="upper left")
    fig.tight_layout(h_pad=2.6)
    fig.suptitle(title, y=1.02)
    return fig
fig = prior_panels(file_priors, {"maximum likelihood": ml["estimate"], "posterior mode": post_file["estimate"]},
                   "The file's normal priors (shaded), the ML estimates and the posterior modes")
show(fig, "Twelve panels: each parameter's prior density with its maximum likelihood estimate and posterior mode")
Twelve panels: each parameter's prior density with its maximum likelihood estimate and posterior mode
compare = pd.DataFrame({"prior mean": [float(file_priors[n]["parameters"][3]) for n in names],
                        "prior s.d.": [float(file_priors[n]["parameters"][4]) for n in names],
                        "max. likelihood": ml["estimate"], "posterior mode": post_file["estimate"],
                        "posterior s.e.": post_file["std. error"]}, index=names)
compare.round(4)
prior mean prior s.d. max. likelihood posterior mode posterior s.e.
omega 0.2000 0.0200 0.0619 0.1546 0.0195
alphax 0.1000 0.0500 0.0836 0.1100 0.1370
alphapie 0.0000 0.0000 0.0000 0.0000 0.0000
rhopie 0.3000 0.1000 0.3597 0.3483 0.1003
rhog 0.3000 0.1000 0.2536 0.2756 0.0715
rhox 0.2500 0.0625 0.0346 0.0698 0.0841
rhoa 0.8500 0.1000 0.9470 0.9245 0.0236
rhoe 0.8500 0.1000 0.9626 0.9626 0.0379
std_epsa 0.0300 1.8000 0.0402 0.0255 0.0042
std_epse 0.0001 0.0001 0.0012 0.0009 0.0006
std_epsz 0.0050 0.2750 0.0109 0.0118 0.0043
std_epsr 0.0050 0.0044 0.0031 0.0034 0.0008

A conventional set of priors

Normal priors are an odd choice for most of these parameters. A normal distribution puts probability on negative values and, for the persistence parameters, on values above one, which the model rules out (the bounds then cut the distribution off). Some of the file’s priors are also very tight or very loose. The prior for \(\alpha_\pi\) has mean 0.000005 and standard deviation 0.000001: it nails \(\alpha_\pi\) at zero before any data are seen. The prior for \(\sigma_a\) has mean 0.03 and standard deviation 1.8, which is flat over every plausible value.

DSGE studies usually choose the prior’s shape to fit each parameter’s range (Smets and Wouters, 2007):

Parameter Range Usual prior Our choice (mean, s.d.)
\(\omega\), \(\alpha_x\), \(\alpha_\pi\), \(\rho_a\), \(\rho_e\) between 0 and 1 beta \(\omega\) (0.2, 0.1); \(\alpha_x\), \(\alpha_\pi\) (0.1, 0.05); \(\rho_a\), \(\rho_e\) (0.85, 0.1)
\(\rho_\pi\), \(\rho_g\), \(\rho_x\) positive gamma \(\rho_\pi\), \(\rho_g\) (0.3, 0.1); \(\rho_x\) (0.1, 0.05)
\(\sigma_a\), \(\sigma_e\), \(\sigma_z\), \(\sigma_r\) positive, possibly large inverse gamma mean = s.d. = 0.03, 0.002, 0.01, 0.003

Snowdrop takes the mean and standard deviation and computes each distribution’s own parameters. For the beta distribution this is the formula above; a gamma with mean \(m\) and standard deviation \(s\) has shape \(m^2/s^2\) and scale \(s^2/m\). For the inverse gamma we use inv_gamma1_pdf, the version Dynare uses. In this version of Snowdrop, the other two inverse-gamma variants (inv_gamma_pdf and inv_gamma2_pdf) do not turn the mean and standard deviation into the right parameters, so check any prior you use by plotting it, as we do below. These priors build on the set in Snowdrop’s own file distributions.py.

conventional = """estimated_parameters:
    - omega,    0.0617, 1.e-7, 1,      beta_pdf,       0.20,  0.10
    - alphax,   0.0836, 1.e-7, 1,      beta_pdf,       0.10,  0.05
    - alphapie, 0.05,   1.e-7, 1,      beta_pdf,       0.10,  0.05
    - rhopie,   0.3597, 1.e-7, 1,      gamma_pdf,      0.30,  0.10
    - rhog,     0.2536, 1.e-7, 1,      gamma_pdf,      0.30,  0.10
    - rhox,     0.0347, 1.e-7, 1,      gamma_pdf,      0.10,  0.05
    - rhoa,     0.9470, 1.e-7, 0.9999, beta_pdf,       0.85,  0.10
    - rhoe,     0.9625, 1.e-7, 0.9999, beta_pdf,       0.85,  0.10
    - std_epsa, 0.0405, 1.e-7, 0.2,    inv_gamma1_pdf, 0.03,  0.03
    - std_epse, 0.0012, 1.e-7, 0.02,   inv_gamma1_pdf, 0.002, 0.002
    - std_epsz, 0.0109, 1.e-7, 0.1,    inv_gamma1_pdf, 0.01,  0.01
    - std_epsr, 0.0031, 1.e-7, 0.05,   inv_gamma1_pdf, 0.003, 0.003

"""
text = open("ireland.yaml").read()
text = text[:text.find("estimated_parameters:")] + conventional + text[text.find("labels:"):]
open("ireland_conventional.yaml", "w").write(text)
3343

The starting values are Ireland’s estimates again, except \(\alpha_\pi\): a beta prior has almost no density at zero, so we start it at 0.05.

ireland = load_model("ireland_conventional.yaml", Solver="Klein", Filter="Durbin_Koopman",
                     Smoother="Durbin_Koopman", Prior="Equilibrium", measurement_file_path=DATA)
conv_priors = ireland.priors
post_conv, out_conv = estimate(ireland, estimate_Posterior=True)
print(f"\nLog-likelihood plus log-prior at the mode: {post_conv.attrs['log value']:.2f}")
Posterior Maximum Likelihood Estimation
+----------+----------------+----------+---------+
|   Name   | Starting Value | Estimate |   Std.  |
+----------+----------------+----------+---------+
|  omega   |    0.06170     | 0.09420  | 0.04976 |
|  alphax  |    0.08360     | 0.07824  | 0.04414 |
| alphapie |    0.05000     | 0.03117  | 0.01884 |
|  rhopie  |    0.35970     | 0.35262  | 0.04001 |
|   rhog   |    0.25360     | 0.26213  | 0.03731 |
|   rhox   |    0.03470     | 0.03873  | 0.01218 |
|   rhoa   |    0.94700     | 0.93010  | 0.01748 |
|   rhoe   |    0.96250     | 0.95477  | 0.02408 |
| std_epsa |    0.04050     | 0.03113  | 0.00574 |
| std_epse |    0.00120     | 0.00123  | 0.00020 |
| std_epsz |    0.01090     | 0.01069  | 0.00214 |
| std_epsr |    0.00310     | 0.00315  | 0.00033 |
+----------+----------------+----------+---------+

Log-likelihood plus log-prior at the mode: 2676.89
fig = prior_panels(conv_priors, {"maximum likelihood": ml["estimate"], "posterior mode": post_conv["estimate"]},
                   "Conventional priors (shaded), the ML estimates and the posterior modes")
show(fig, "Twelve panels: the beta, gamma and inverse gamma priors with the ML estimates and posterior modes")
Twelve panels: the beta, gamma and inverse gamma priors with the ML estimates and posterior modes

How the posterior mode moves

The last table puts the three sets of estimates side by side. The final column compares the uncertainty after seeing the data (the posterior standard error) with the uncertainty before (the prior standard deviation). A small ratio means the data were informative; a ratio near one means the data said little, and the prior decided.

summary = pd.DataFrame({"max. likelihood": ml["estimate"], "posterior, file's priors": post_file["estimate"],
                        "posterior, conventional": post_conv["estimate"],
                        "prior s.d.": [float(conv_priors[n]["parameters"][4]) for n in names],
                        "posterior s.e.": post_conv["std. error"]}, index=names)
summary["s.e. / prior s.d."] = summary["posterior s.e."] / summary["prior s.d."]
summary.round(4)
max. likelihood posterior, file's priors posterior, conventional prior s.d. posterior s.e. s.e. / prior s.d.
omega 0.0619 0.1546 0.0942 0.100 0.0498 0.4976
alphax 0.0836 0.1100 0.0782 0.050 0.0441 0.8828
alphapie 0.0000 0.0000 0.0312 0.050 0.0188 0.3768
rhopie 0.3597 0.3483 0.3526 0.100 0.0400 0.4001
rhog 0.2536 0.2756 0.2621 0.100 0.0373 0.3731
rhox 0.0346 0.0698 0.0387 0.050 0.0122 0.2436
rhoa 0.9470 0.9245 0.9301 0.100 0.0175 0.1748
rhoe 0.9626 0.9626 0.9548 0.100 0.0241 0.2408
std_epsa 0.0402 0.0255 0.0311 0.030 0.0057 0.1913
std_epse 0.0012 0.0009 0.0012 0.002 0.0002 0.1000
std_epsz 0.0109 0.0118 0.0107 0.010 0.0021 0.2140
std_epsr 0.0031 0.0034 0.0032 0.003 0.0003 0.1100

What to notice.

  • Where the data are informative, the three columns agree and the posterior is much narrower than the prior. The policy responses \(\rho_\pi\) and \(\rho_g\) barely move. For the shock standard deviations and the persistence parameters, the posterior standard error is a fifth of the prior standard deviation or less.
  • Where the likelihood is flat, the prior decides. For \(\alpha_x\) the posterior is hardly narrower than the prior (the ratio is close to one): the data say almost nothing about it. The file’s tight normal prior around 0.2 pulls \(\omega\) from 0.06 up to about 0.15. The conventional beta prior has the same mean but is five times wider, and \(\omega\) lands at about 0.09, between the prior and the maximum likelihood estimate. For \(\alpha_\pi\) the conventional prior pulls the estimate off its bound of zero, where the file’s prior had nailed it.
  • A prior on one parameter moves others. When the file’s prior pushes \(\omega\) up, the standard deviation of the preference shocks \(\sigma_a\) falls from about 0.040 to 0.026 at the same time. Both shape how preference shocks enter the model, so the data pin down a combination of them rather than each one alone.

This is what Bayesian estimation offers: where the data are silent, the answer is the prior, and you can see it. It is also its danger: a prior chosen without care can decide a result that looks like a finding from the data. Always report the priors, and compare the posterior with them.

Your turn. Suppose you believe the Fed responds more strongly to inflation. Give \(\rho_\pi\) a tight gamma prior with mean 0.5 and standard deviation 0.05 and estimate the posterior mode again. Does \(\rho_\pi\) move? What happens to the posterior standard error, and to the other parameters?

Show the answer

The tight prior pulls \(\rho_\pi\) up from about 0.35 to about 0.41: halfway to the prior mean of 0.5, because the likelihood pushes back. Its posterior standard error, about 0.03, is smaller than both the prior’s 0.05 and the 0.04 of the conventional run: prior and data now both carry information about \(\rho_\pi\). Other parameters adjust a little; for example, the response to output growth \(\rho_g\) rises. The estimation takes about two minutes in Colab.

text = open("ireland_conventional.yaml").read()
text = text.replace("rhopie,   0.3597, 1.e-7, 1,      gamma_pdf,      0.30,  0.10",
                    "rhopie,   0.3597, 1.e-7, 1,      gamma_pdf,      0.50,  0.05")
open("ireland_tight.yaml", "w").write(text)
ireland = load_model("ireland_tight.yaml", Solver="Klein", Filter="Durbin_Koopman", Smoother="Durbin_Koopman",
                     Prior="Equilibrium", measurement_file_path=DATA)
post_tight, out_tight = estimate(ireland, estimate_Posterior=True)
# Your turn: try it here

G.13 Going further

Sampling the whole posterior

The posterior mode is one number per parameter. Bayesian studies usually report the whole posterior distribution, drawn by Markov chain Monte Carlo (MCMC). Snowdrop offers the affine-invariant ensemble sampler of Goodman and Weare (2010), through the emcee library, and adaptive Metropolis–Hastings samplers from pymcmcstat. Choose one when you read the model, importModel(..., SamplingMethod="emcee"), then call driver.estimate(model=..., sample=True, Ndraws=..., Niter=..., burn=...). With Plot=True, Snowdrop draws the prior and posterior densities and a corner plot of the draws. Serious runs take hours, not minutes, and you must check that the chains have converged. Herbst and Schorfheide (2016) explain how.

The Kalman smoother and historical decompositions

Section G.11 plotted the smoothed variables. The same output holds the smoothed shocks: the fourth element of what estimate returns has one column per structural shock and one row per quarter. With them you can rebuild history shock by shock and ask, for example, how much of the 1980–82 recession monetary policy shocks explain. Snowdrop’s kalman_filter function runs the filter and smoother without estimating, and plotDecomposition (with isKF=True) is the place to start for the contribution charts.

The paper’s epidemic model, and the Smets–Wouters model

The folder supplements/models/COVID19 of the package (in SUPP) holds the paper’s third example, ert_model.yaml (Eichenbaum, Rebelo and Trabandt), with its data in supplements/data/COVID19 and the code that runs it in snowdrop/src/epidemic/ert.py. The same folder has sw_model.yaml, a replication of the Smets and Wouters (2007) model whose estimated responses appear in Chapter 15, and gsw_model.yaml, the Galí–Smets–Wouters model applied to the COVID-19 lockdowns. These are large models; read their files first, then simulate them with the tools of Sections G.6 to G.8.

Your own data

Ireland’s sample ends in 2002. To re-estimate the model on today’s data, download the four series with the tools of Appendix B: real GDP, population, the GDP deflator and the three-month Treasury bill rate (FRED: GDPC1, CNP16OV, GDPDEF, TB3MS). Average the monthly series by quarter. Compute quarterly per-capita output growth and inflation (log differences) and the quarterly interest rate (the annual rate divided by 400), subtract each series’ mean, and save a CSV file with a Date column and the columns obs_g, obs_pie and obs_r. Change range and filter_range in the model file and pass the new file as measurement_file_path. Two warnings: from 2009 to 2015 the interest rate was stuck at zero, which a linear policy rule cannot describe, and the pandemic quarters of 2020 are huge outliers.

Other model files and other tools

importModel also reads Dynare (.mod) and IRIS model files: supplements/models/MPAF holds the IMF’s basic Quarterly Projection Model both as model.mod and as model.yaml. The package’s User Guide (supplements/docs/UserGuide.pdf) lists every option of the model files and functions, and supplements/docs/NumericalAlgorithms.pdf describes the solvers and filters. Other open-source Python projects for DSGE models exist too, for example dolo and pydsge.

Common errors and how to fix them

What you see Why What to do
ModuleNotFoundError: No module named 'snowdrop' Colab forgets installed packages when the runtime restarts run the install cell again
pip tries to build NumPy 1.26 and fails the install cell lost its --no-deps install exactly as in Section G.3
FileNotFoundError for a file you just wrote importing Snowdrop, or its estimation module, moved Python into Snowdrop’s folder os.chdir(WORK)
a variable named pi gives odd results it clashes with the constant \(\pi\) of the algebra library rename it (infl, pie)
run(..., irf=True) fails for a nonlinear model a limitation of this version simulate with and without the shock and subtract
a simulation drifts although no shock hits the starting values are not the steady state compute the steady state by formula; check that importModel’s residuals are 0.000
random histories look too smooth Snowdrop anticipates all future shocks by default anticipate=False
a plausible-looking path it may still be wrong; ABLR leaves out exogenous paths in this version check with checkSolution; use LBJ
estimation returns nonsense, or “Model calibration failed” the filter does not support estimation, or a starting value lies outside its bounds Filter="Durbin_Koopman"; check the bounds
TypeError: 'NoneType' object is not subscriptable at the end of estimate no smoother was chosen Smoother="Durbin_Koopman"
a second estimation lists the std_ parameters twice Snowdrop keeps a list between runs use our estimate helper, which clears it, and read the model again
estimates change from run to run the likelihood is flat in some directions start from several points; keep the highest log-likelihood
an inverse-gamma prior with the wrong mean inv_gamma_pdf and inv_gamma2_pdf mis-handle their inputs use inv_gamma1_pdf, and plot every prior
algorithm="..." changes nothing Snowdrop always uses L-BFGS-B when it computes standard errors nothing to do

Where to learn more

  • Goumilevski, A., and Otterson, J. (2025). Snowdrop: Python Package for DSGE Modeling. Journal of Open Source Software 10(112), 8197. The code, User Guide and examples: github.com/gumilevskij/Framework.
  • Ireland, P. N. (2004). Technology Shocks in the New Keynesian Model. Review of Economics and Statistics 86(4), 923–936.
  • Galí, J. (2015). Monetary Policy, Inflation, and the Business Cycle, 2nd ed. Princeton University Press. The standard textbook of the New Keynesian model.
  • Blanchard, O. J., and Kahn, C. M. (1980). The Solution of Linear Difference Models under Rational Expectations. Econometrica 48(5), 1305–1311; Klein, P. (2000). Using the Generalized Schur Form to Solve a Multivariate Linear Rational Expectations Model. Journal of Economic Dynamics and Control 24(10), 1405–1423.
  • Juillard, M., Laxton, D., McAdam, P., and Pioro, H. (1998). An Algorithm Competition: First-Order Iterations versus Newton-Based Techniques. Journal of Economic Dynamics and Control 22(8–9), 1291–1318.
  • Hamilton, J. D. (1994). Time Series Analysis, Chapter 13; Durbin, J., and Koopman, S. J. (2012). Time Series Analysis by State Space Methods, 2nd ed. Oxford University Press. The Kalman filter in depth.
  • Herbst, E. P., and Schorfheide, F. (2016). Bayesian Estimation of DSGE Models. Princeton University Press.
  • Smets, F., and Wouters, R. (2007). Shocks and Frictions in US Business Cycles: A Bayesian DSGE Approach. American Economic Review 97(3), 586–606.
  • Fernández-Villaverde, J., and Guerrón-Quintana, P. A. (2021). Estimating DSGE Models: Recent Advances and Future Challenges. Annual Review of Economics 13, 229–252.
  • Eichenbaum, M., Rebelo, S., and Trabandt, M. (2021). The Macroeconomics of Epidemics. Review of Financial Studies 34(11), 5149–5187.

Concluding remarks

  • A DSGE model is a set of equations from optimizing households and firms, market clearing, policy rules and random shocks. Solving it means finding decision rules (or, for a nonlinear model, a whole path) that satisfy every equation in every period; the Blanchard–Kahn condition tells whether a unique stable solution exists.
  • Snowdrop, a free Python package from the IMF, writes models as plain YAML files and solves them with Newton’s method (nonlinear models) or generalized Schur methods (linear models). With it we reproduced Chapter 13’s AS/AD model exactly, replicated Fig. 1 of the Snowdrop paper, and simulated a real business cycle model with one shock and with many random ones.
  • To take a model to data, write its solution in state-space form; the Kalman filter infers the unobserved states and gives the likelihood. Maximum likelihood finds the parameters that make the data most probable; the curvature of the likelihood gives their standard errors.
  • Estimating Ireland’s (2004) model reproduced his published estimates, but only after we restarted the search from a second point: DSGE likelihoods are often flat in some directions, and an optimizer can stop early. Bayesian estimation adds priors, which decide exactly where the data are silent; always report them and compare the posterior with them.
  • The habit that runs through the appendix is to check every result: against a case you can solve by hand, against the residuals of the equations, against a second starting point, against the published numbers. Research software is powerful, and like any tool it is only as reliable as the checks you run on it.
