One line of Python shows that 2 percent growth doubles income in 35 years
1.9998895526624565An economy growing 2% a year, after 35 years: twice as large. That is the rule of 70, computed rather than memorized. By the end of today you will write lines like this, load real data and draw live charts, all in a web browser.
Today: five steps from zero to a small data project
- Colab. Where do the book’s notebooks run, and how do you use one?
- Python building blocks. Numbers, variables, lists, loops,
if, functions, errors. - AI-powered coding. Gemini in Colab: ask, generate, fix, the agent, Learn Mode, and checking its work.
- The data science libraries. NumPy and pandas for numbers and tables; Plotly and ipywidgets for charts and sliders.
- A mini project. Which economies grew fastest after 1990? By hand, then with AI.
Five kinds of cards guide you through the code
Code in a dark box, its output with a green rule, a Predict card before an output is revealed, a Try it in Colab exercise, and a Common mistake card.
Colab: notebooks in the browser
Act I
A notebook mixes text, code and results on one page
Text
Explanations, headings and equations such as \(y = \bar{A}k^{1/3}\).
Code
Short Python cells that compute, load data and draw.
Results
Numbers, tables and charts, right below the code that made them.
Change the code, run it again, and the result below it updates.
Colab runs your notebook on Google’s computers, not on your laptop
Your web browser code →
← results Colab runtime ← CSV files The book’s GitHub data
The computer that runs the code is called the runtime. It lives in a Google data centre.
Five reasons the book uses Colab
- Nothing to install: Python, NumPy, pandas, Plotly and ipywidgets are already there.
- The same setup for everyone: Windows, macOS, Linux or a Chromebook.
- Live models: the model figures get sliders; move one and the model is solved again.
- Easy to save and share: a copy in Google Drive, shared with a link.
- Data straight from the source: files are read from the book’s GitHub repository.
Four limits to keep in mind
- The runtime is temporary. Close the notebook or leave it idle, and every variable is forgotten. Runtime → Run all rebuilds everything in seconds.
- Edits are not saved automatically in a notebook opened from GitHub: save your own copy first.
- Free resources are shared: only a few runtimes at a time. Close yours properly.
- You need to be online: the runtime and the data live on the internet.
Closing the tab is not the same as closing the runtime
I closed the browser tab, so my work is saved and the runtime has stopped.
Neither is true. A notebook opened from GitHub is read-only: edits are lost unless you saved a copy in Drive. And the runtime keeps running for a while after the tab closes, using one of your few free slots.
A whole session takes seven steps
| Step | What you do | Where |
|---|---|---|
| 1 | Open the notebook | the Open in Colab badge |
| 2 | Find your way around | menus, toolbar, contents, cells |
| 3 | Run the whole notebook | Runtime → Run all (Ctrl+F9) |
| 4 | Accept the warning | Run anyway |
| 5 | Read the cells, move the sliders | the model figures |
| 6 | Save your own copy | File → Save a copy in Drive |
| 7 | Close the runtime | Runtime → Disconnect and delete runtime |
Step 1: every chapter page has an Open in Colab badge under its mind map
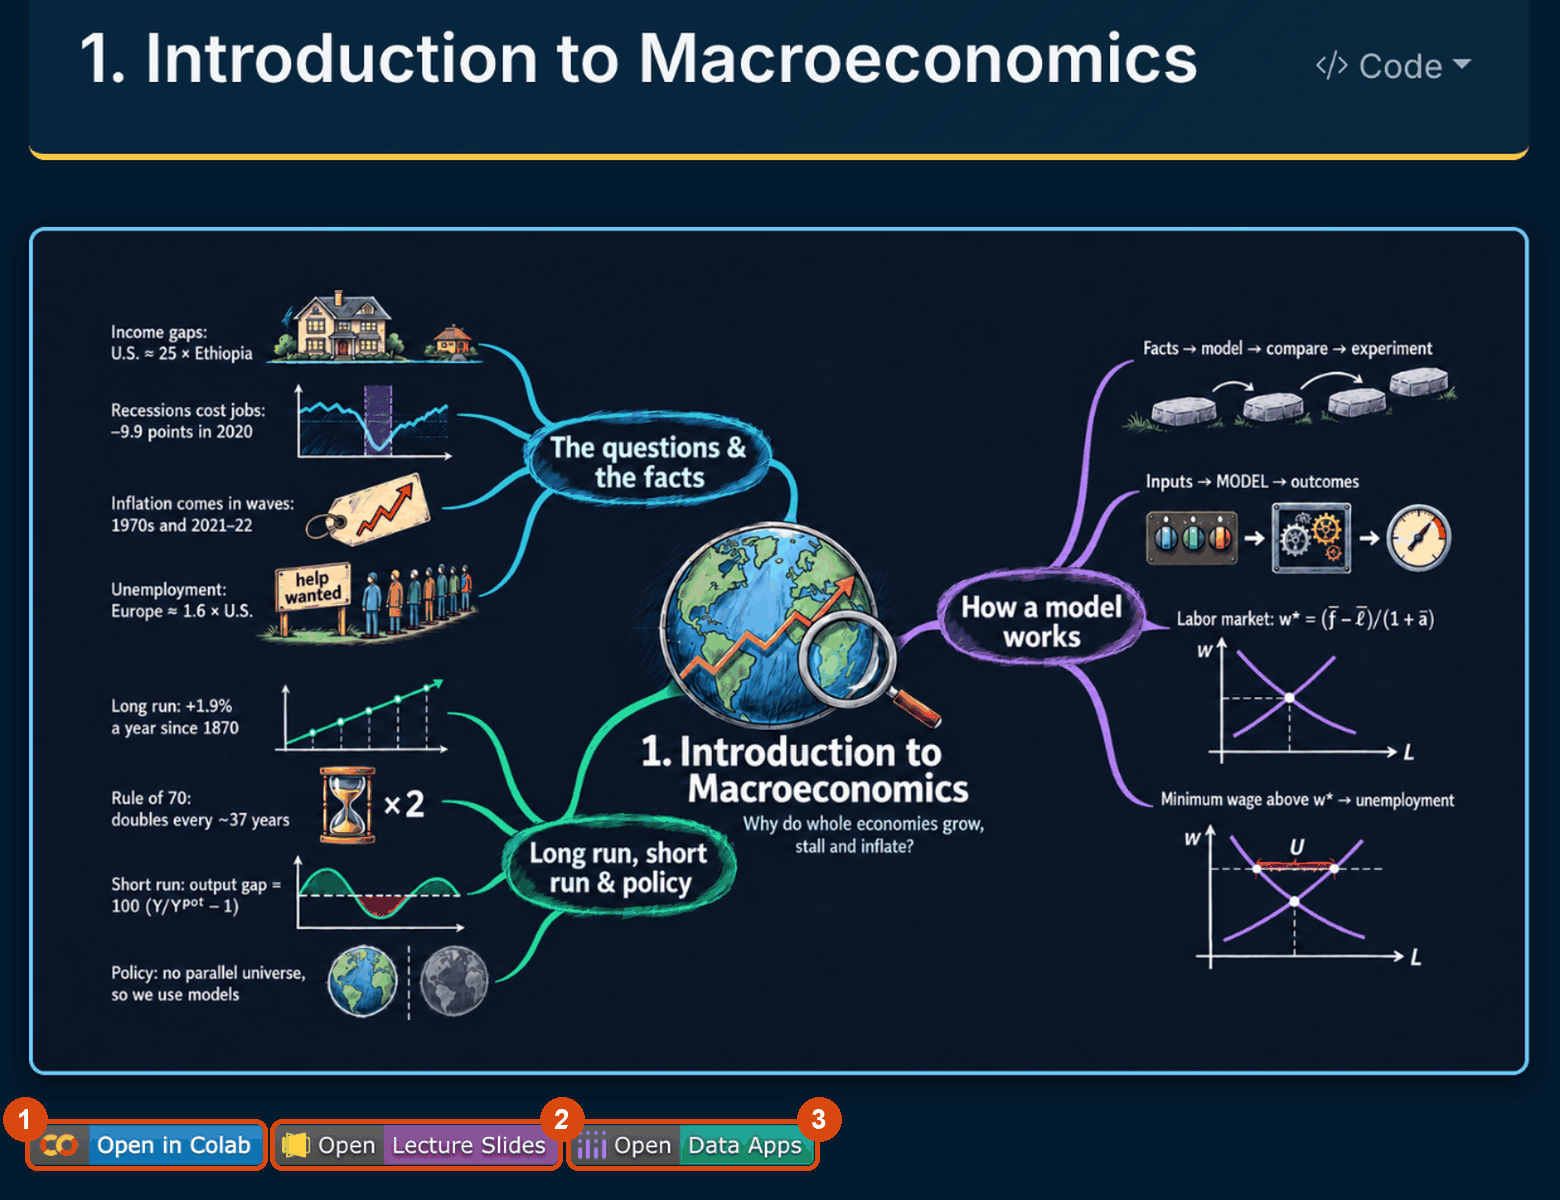
1 Open in Colab · 2 Open Lecture Slides · 3 Open Data Apps (some chapters). Sign in with a Google account to run the notebook.
Step 2: the Colab window has six parts to know
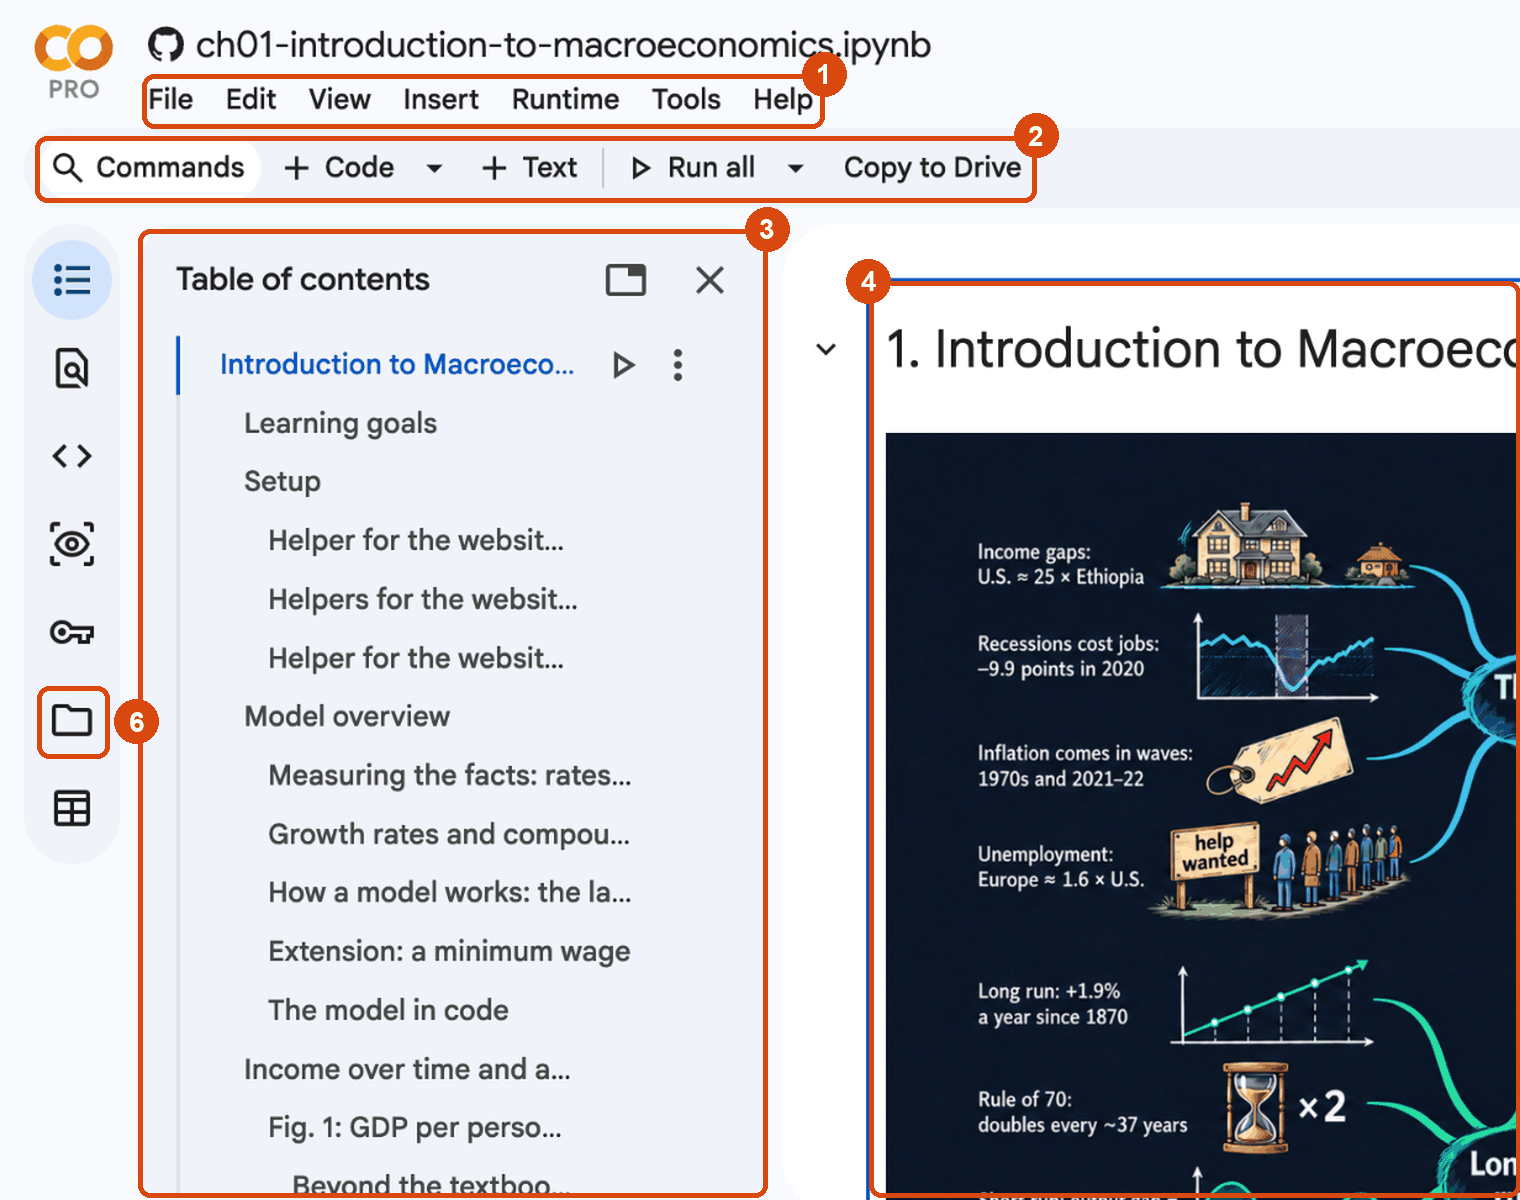
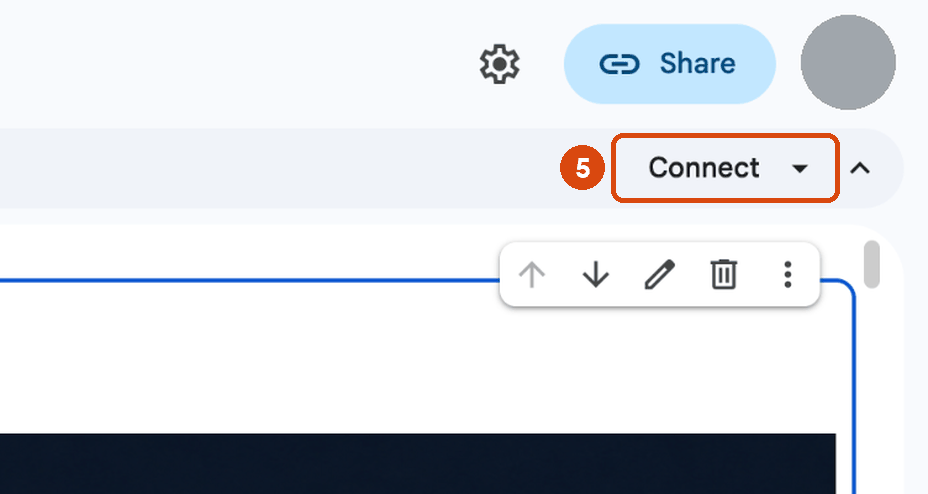
1 menus · 2 toolbar (+ Code, + Text, Run all) · 3 table of contents · 4 a text cell (title and mind map) · 5 Connect · 6 files
Step 3: Runtime → Run all runs every cell from top to bottom
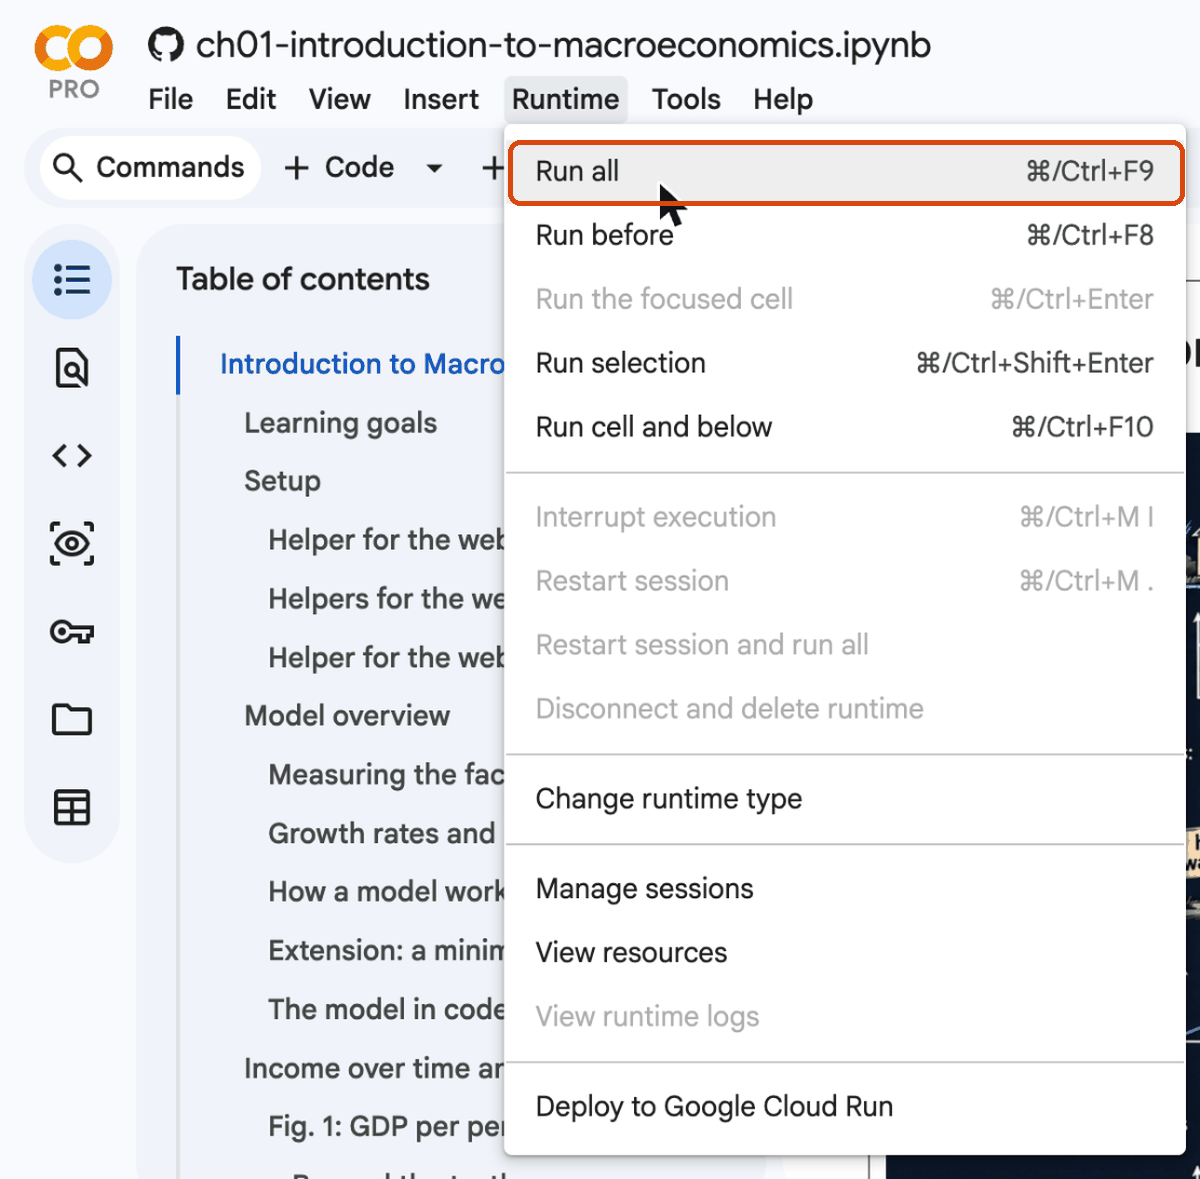
Shortcut: Ctrl+F9 (⌘+F9 on a Mac). Colab connects to a runtime first.
Step 4: a warning reminds you to run only code you trust
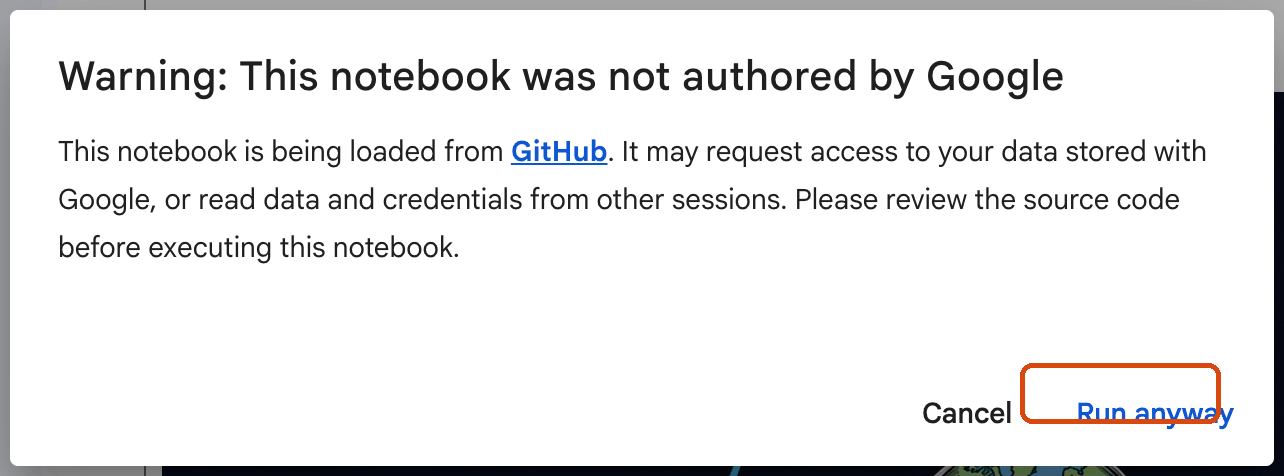
The book’s notebooks only read public data files and draw charts: click Run anyway.
Step 5: the number in brackets counts the runs
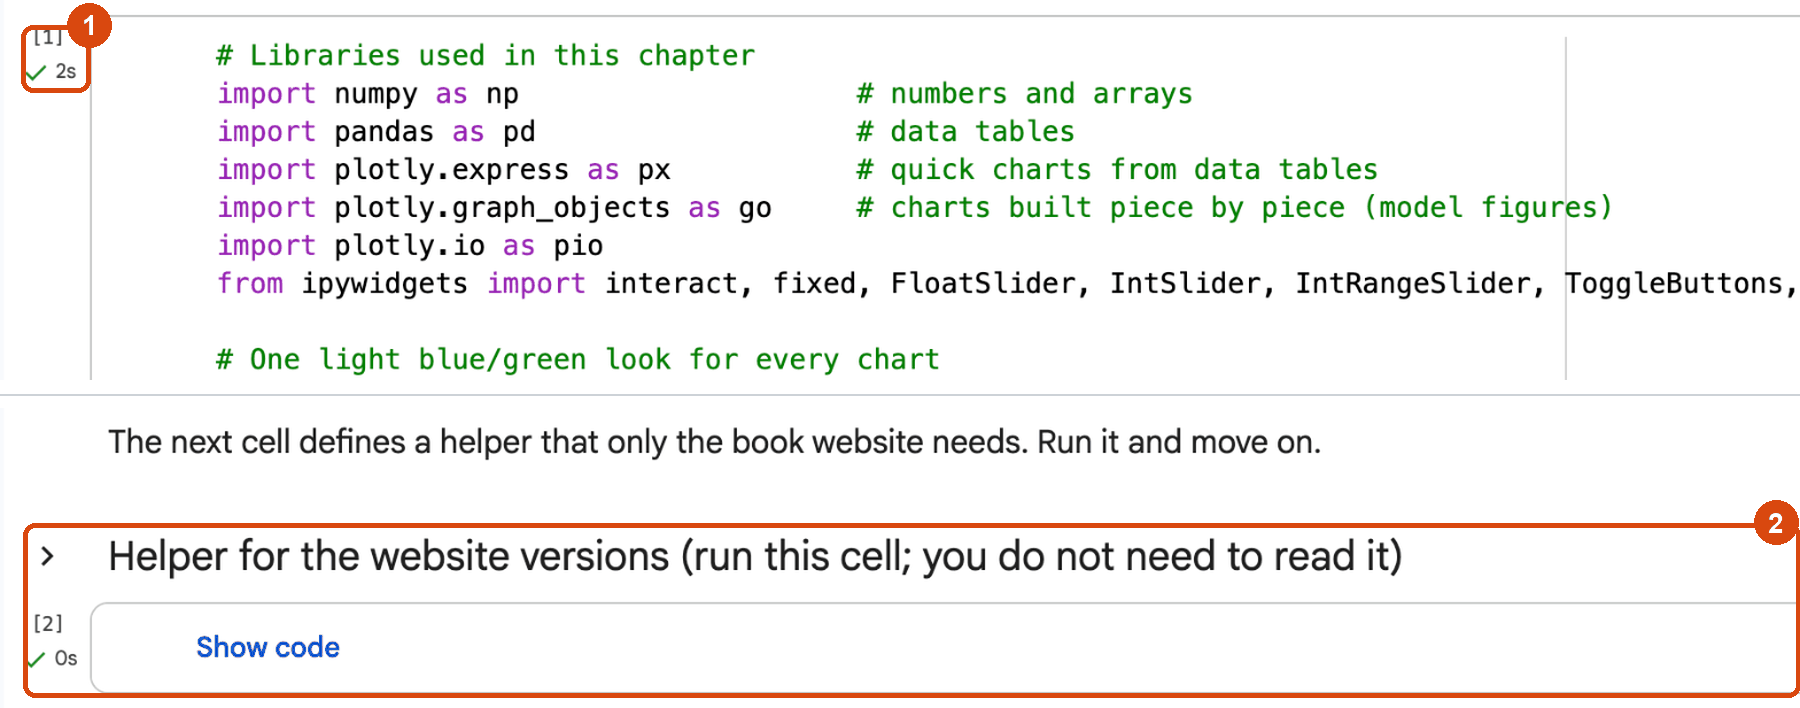
1: the run number, a tick and the time. 2: a folded helper cell. Run it; you need not read it.
In Colab, moving a slider solves the model again
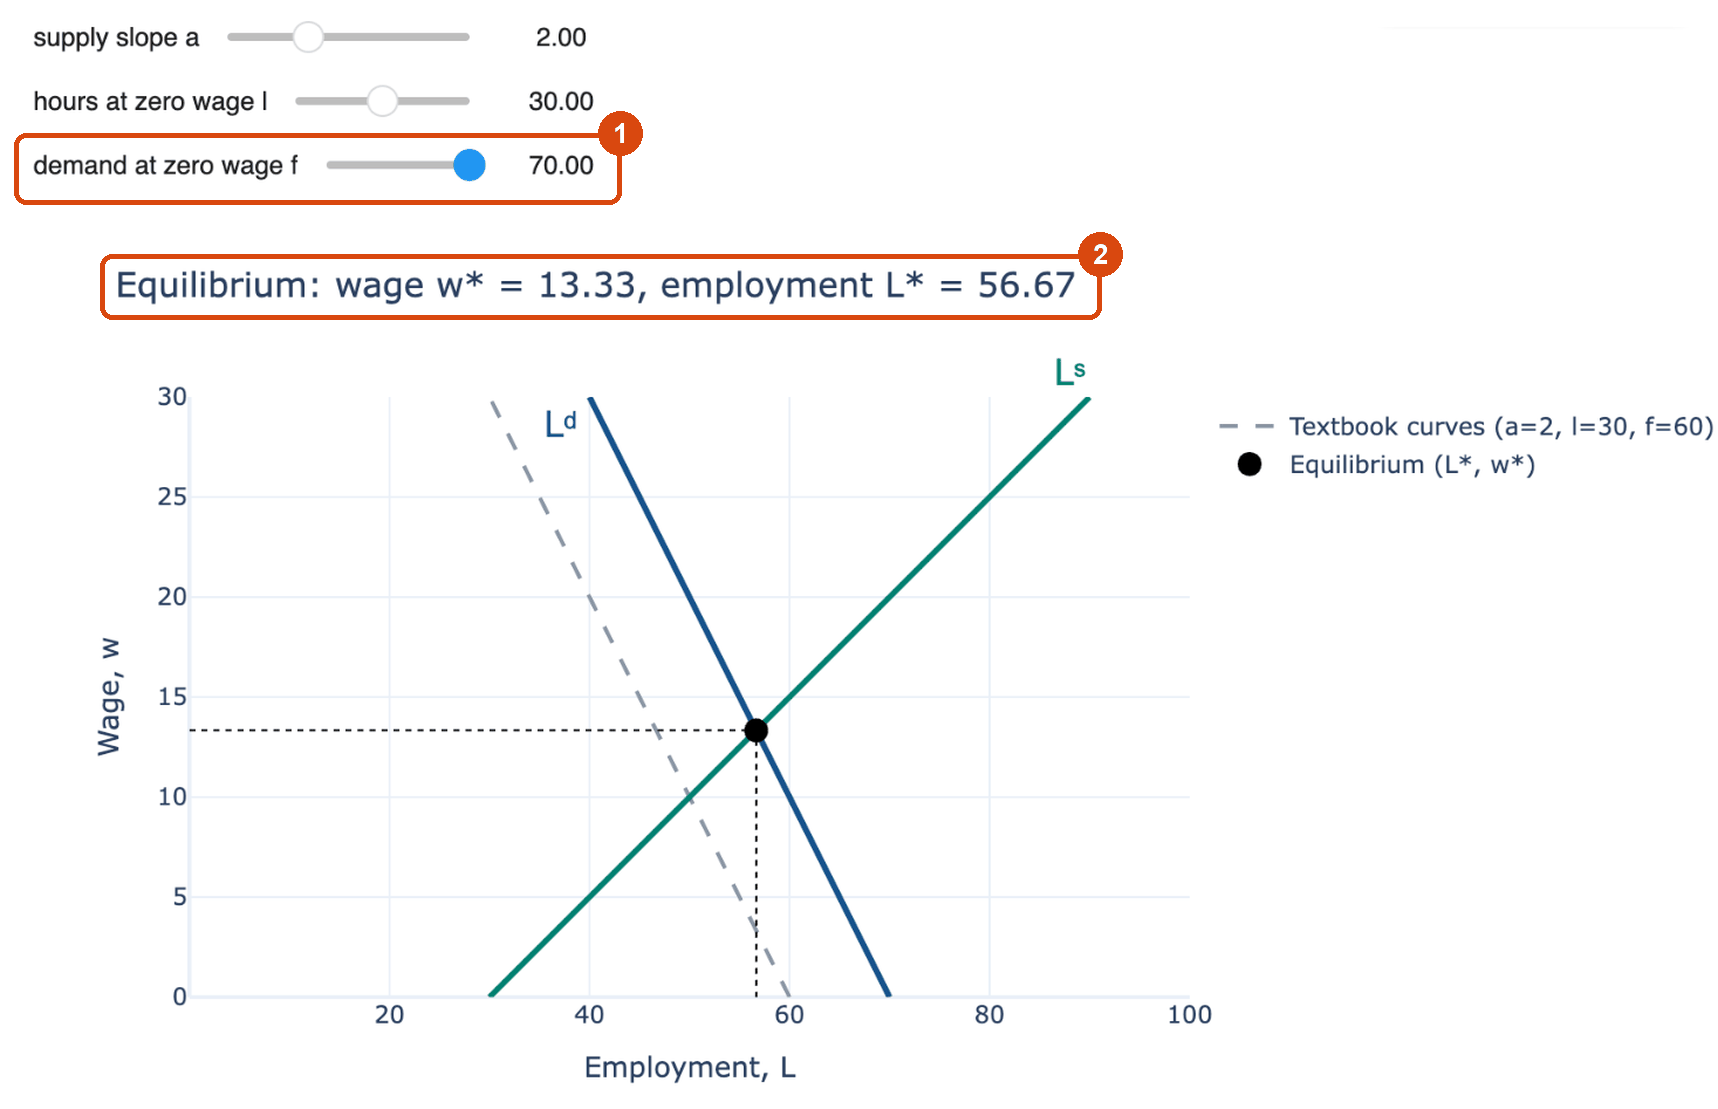
Chapter 1, Fig. 8: labor demand at a zero wage \(\bar{f}\) from 60 to 70 (1). The equilibrium moves to \(w^* = 13.33\), \(L^* = 56.67\) (2).
The book website shows a precomputed version of each live figure
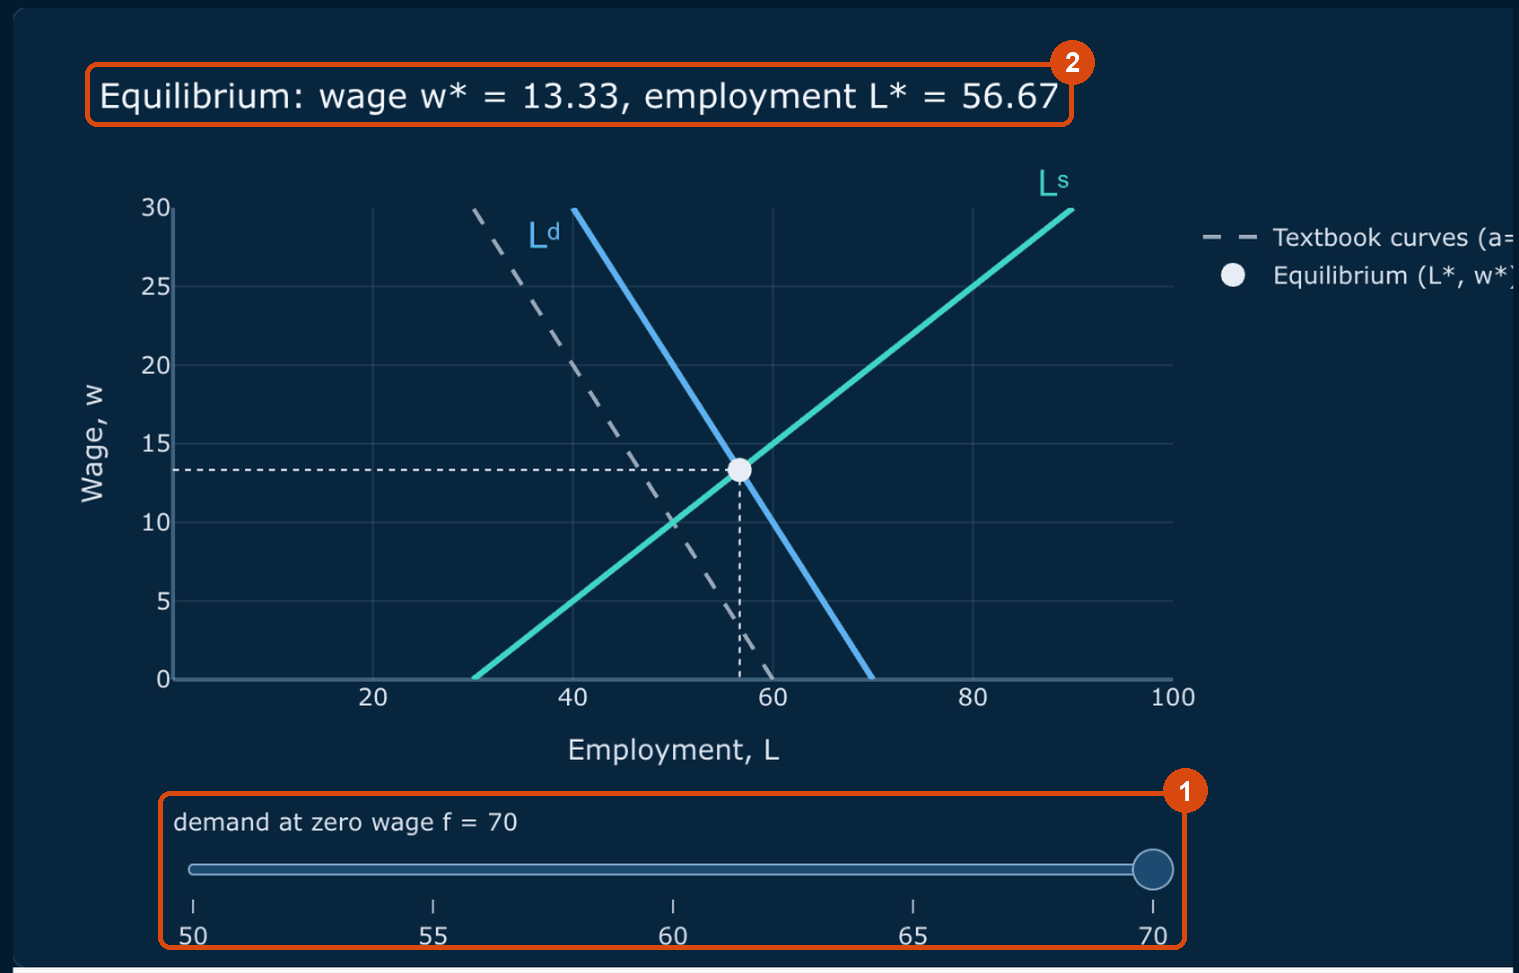
The website cannot run Python: the same chart is computed in advance for a few values and joined by one slider.
The website is for reading; Colab is for doing
| Book website | Colab | |
|---|---|---|
| Read the text and the charts | ✓ | ✓ |
| Hover, zoom, click legends | ✓ | ✓ |
| Move one precomputed slider | ✓ | ✓ |
| Move every slider freely | ✓ | |
| Change and rerun the code | ✓ |
Step 6: save your own copy before you edit
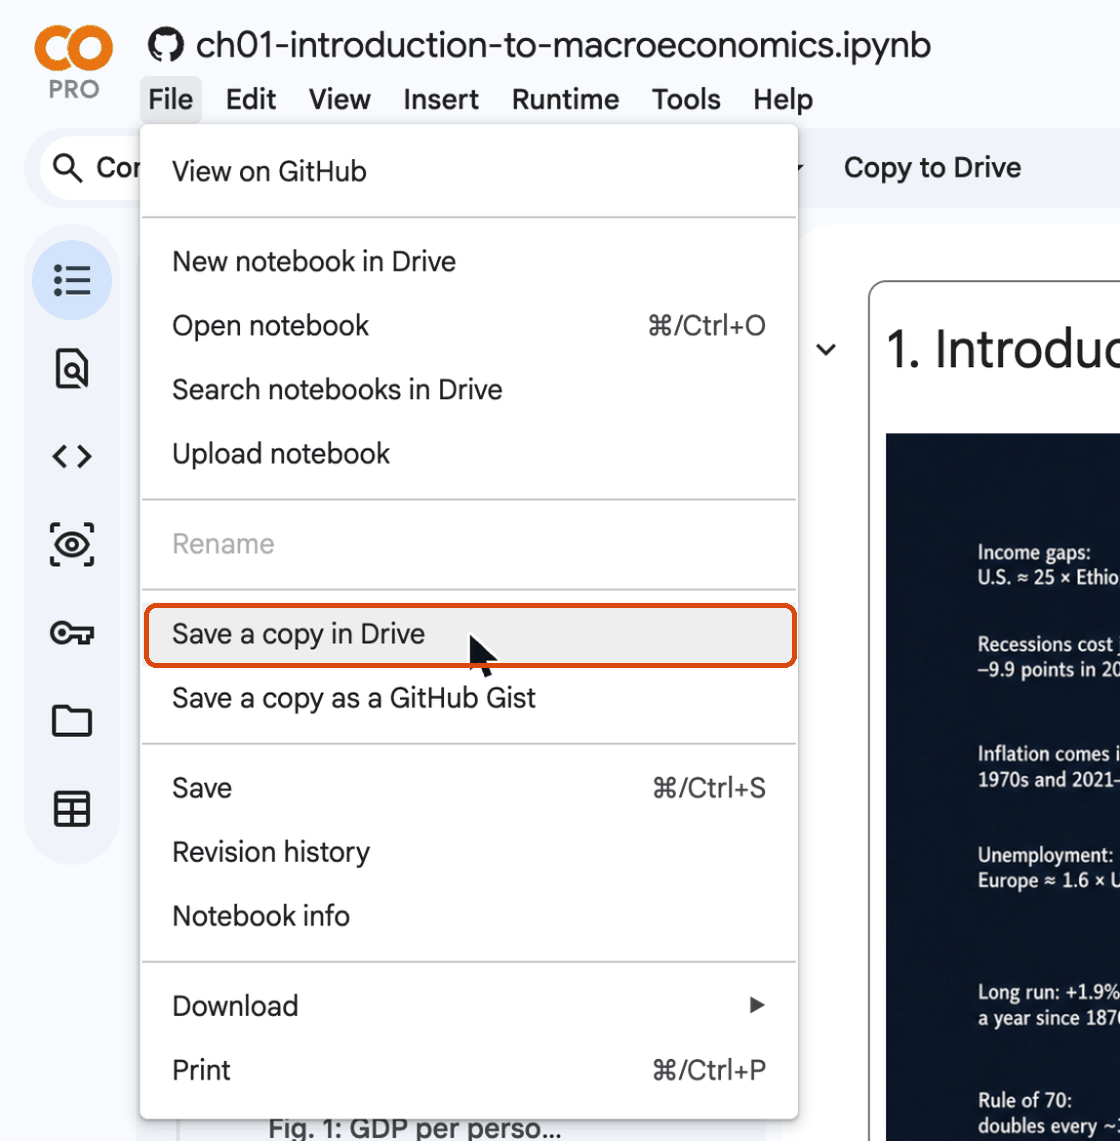
File → Save a copy in Drive. The copy goes to a “Colab Notebooks” folder and saves as you work.
Step 7: delete the runtime when you are done
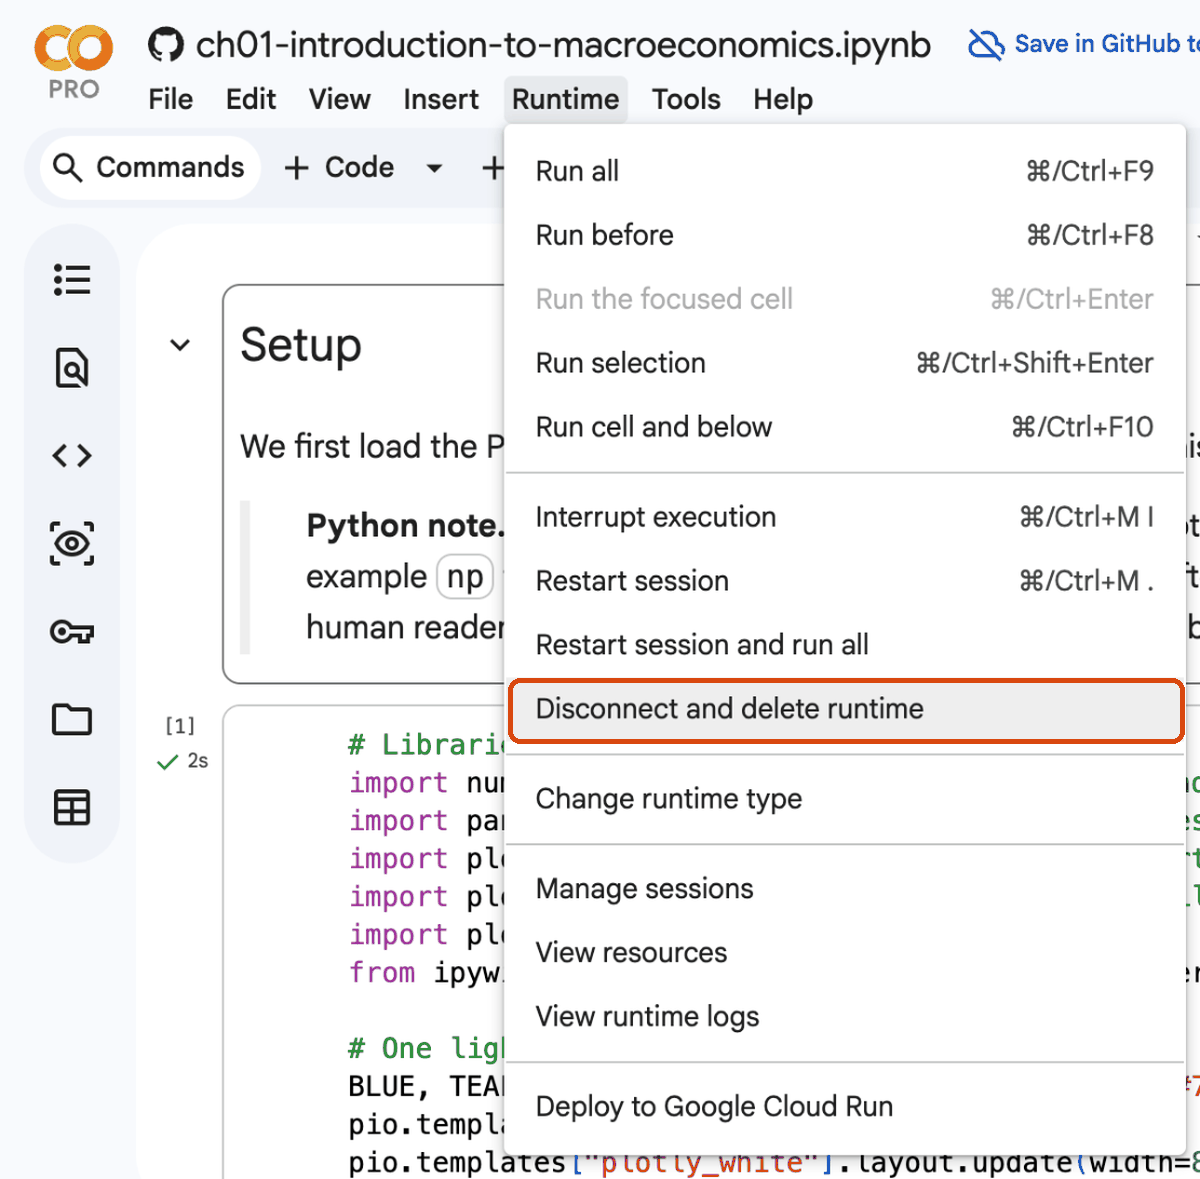
Runtime → Disconnect and delete runtime, then close the tab. “Too many sessions”? Runtime → Manage sessions.
Your first session in Colab
Open the Chapter 1 notebook with its badge, run it, and move the demand at zero wage f slider of Fig. 8. Then save a copy in your Drive and delete the runtime.
Code cells run with Shift+Enter; text cells are written in Markdown
Text cells
Markdown: **bold**, *italic*, # Heading, and equations like \(y = \bar{A}k^{1/3}\).
Code cells
Python. Click inside and press Shift+Enter, or click the round ▶ button.
5Only the last line of a cell is shown automatically
What appears below this cell: one line, or two? Which ones?
Hello, Colab!
20Cells run in the order you run them, not the order on the page
“Run the cell I need” is how most notebook errors start
I opened the notebook and ran the cell with the chart. It says NameError, so the notebook is broken.
The notebook is fine: a cell above it has not run yet, so a variable or a library does not exist. Runtime → Run all fixes it almost every time.
Six keyboard shortcuts cover most of your work
| Action | Windows / Linux | Mac |
|---|---|---|
| Run the cell and move to the next one | Shift+Enter | Shift+Enter |
| Run the cell and stay on it | Ctrl+Enter | ⌘+Enter |
| Run all cells | Ctrl+F9 | ⌘+F9 |
| Run all cells above | Ctrl+F8 | ⌘+F8 |
| Interrupt a running cell | Ctrl+M I | ⌘+M I |
| Show all shortcuts | Ctrl+M H | ⌘+M H |
Runtime → Restart session clears every variable. Then run the cells again from the top.
help(...) prints the documentation of any function
Help on built-in function round in module builtins:

round(number, ndigits=None)
    Round a number to a given precision in decimal digits.

    The return value is an integer if ndigits is omitted or None.  Otherwise
    the return value has the same type as the number.  ndigits may be negative.
In a code cell, type a function name and ( and wait: Colab shows the arguments it takes.
Your first code cell
Add a new code cell (+ Code), compute how many hours there are in a year, and run it with Shift+Enter. Then change it to compute the hours in a leap year and run it again.
Act I cheat sheet: Colab
| You want to … | Do this |
|---|---|
| open a chapter | click its Open in Colab badge |
| run everything | Runtime → Run all (Ctrl+F9) |
| run one cell | Shift+Enter |
fix a NameError after a jump |
Runtime → Run before, or Run all |
| start clean | Runtime → Restart session, then Run all |
| keep your edits | File → Save a copy in Drive |
| finish | Runtime → Disconnect and delete runtime |
| read a function’s manual | help(name) |
Python building blocks
Act II
Python works like a calculator
What do 7 // 3 and 7 % 3 give? And 2 ** 10?
10 4 21 2.3333333333333335
2 1
1024** is all you need for compound growth
\[\text{after } t \text{ years at growth rate } g:\qquad y_t = y_0\,(1+g)^t\]
1.9998895526624565At 2% a year a variable doubles in about 70/2 = 35 years: the rule of 70 of Chapter 3.
In Python, ^ is not a power
To compute 2 to the 10th, I write 2 ^ 10, like in Excel.
In Python the power is **: 2 ** 10 gives 1024. The caret ^ is a different operation on the bits of whole numbers, and 2 ^ 10 quietly gives 8, with no error message.
A variable is a name for a value
1.5815186636765661=means “store the value on the right under the name on the left”.- Names: letters, digits and underscores; no spaces;
GDPandgdpare different. - The book follows the textbook’s notation:
s,d,A,k_star,y_star.
From the growth factor to the average annual growth rate
\[y_{2022} = y_{1990}\,(1+g)^{32} \quad\Longrightarrow\quad g = \left(\frac{y_{2022}}{y_{1990}}\right)^{1/32} - 1\]
0.014427636896671148U.S. GDP per person grew about 1.44% a year on average from 1990 to 2022.
= stores a value; == asks a question
if g = 0.02: checks whether the growth rate is 2 percent.
One = assigns, and inside an if it is a SyntaxError. Two == compare and give True or False: g == 0.02.
Every value has a type
<class 'str'> <class 'int'> <class 'float'> <class 'bool'>int |
float |
str |
bool |
|---|---|---|---|
whole numbers: 32 |
decimals: 0.0144 |
text in quotes: "Japan" |
True or False |
An f-string puts values into text, formatted
What will {g:.2%} show for \(g = 0.014427\ldots\)? And {y_1990:,.0f} for 47713?
United States: GDP per person grew from 47,713 to 75,459 dollars,
or 1.44% a year on average over 32 years.A list holds values in order, counted from 0
Which country is countries[0]? Which is countries[-1]?
United States | China | 3 countries
['United States', 'Japan', 'China', 'India']A for loop repeats the indented lines, once per value
year 1: 102.00
year 2: 104.04
year 3: 106.12
year 4: 108.24
year 5: 110.41
range(1, 6) gives 1, 2, 3, 4, 5. The colon and the four spaces mark the lines inside the loop.
Loops simulate models over time: the Solow model in one line
\[k_{t+1} = k_t + s\,k_t^{1/3} - d\,k_t\]
- Each year, capital per person \(k\) grows by investment \(s\,k_t^{1/3}\) …
- … and shrinks by depreciation \(d\,k_t\).
- With \(s = 0.2\) and \(d = 0.1\), the steady state is \(k^* = (s/d)^{3/2}\).
The loop runs the model for 50 years
s, d = 0.2, 0.1        # investment rate and depreciation rate
k = 1.0                # capital per person in year 0
path = [k]             # a list that will hold the whole path
for t in range(50):
    k = k + s * k ** (1 / 3) - d * k
    path.append(k)
k_star = (s / d) ** 1.5                 # the steady state of this model, (s/d)^(3/2)
print(f"k after 10 years: {path[10]:.3f}, after 50 years: {path[50]:.3f}")
print(f"steady state k* = {k_star:.3f}")
Capital starts at 1, below the steady state of about 2.83. After 50 years, will it be above, below or at \(k^*\)?
Capital rises fast at first, then slows as it nears the steady state
k after 10 years: 1.828, after 50 years: 2.761
steady state k* = 2.828- In the first 10 years \(k\) rises from 1 to 1.828; in the next 40, only to 2.761.
- After 50 years it is still just below \(k^* = 2.828\): it approaches, never overshoots.
- The principle of transition dynamics of Chapter 5, from a five-line loop.
A loop turns a model’s equation into its whole time path.
if, elif and else choose which lines run
Which label does 1.4 get? What about 3.0, and −0.5?
Growth of 1.4% a year is moderate.A dictionary stores values under names
The first line prints 0.2. What does the loop print for s?
0.2
s = 0.3
d = 0.1
A = 1.0A function packs an equation under a name
defstarts the definition;kandAare its arguments.A=1.0is a default: leaveAout and it is 1.- The text in triple quotes, the docstring, says what the function does.
returnsends back the result.
In the chapters, each model equation becomes one short function like this one.
Calling the function: change the arguments, get a new answer
The cube root of 8 is 2. What do the two lines print?
2.0
4.0
Twice the productivity, twice the output, with the same capital.
The rule of 70 as a function, tried in a loop
growth of 1% a year: doubles in about 70 years
growth of 2% a year: doubles in about 35 years
growth of 3.5% a year: doubles in about 20 years
growth of 7% a year: doubles in about 10 yearsimport loads a library: the rule of 70 against the exact answer
At 2% a year: exactly 35.0 years; rule of 70: 35.0 years
At 7% a year: exactly 10.2 years; rule of 70: 10.0 years
The exact doubling time is \(\ln 2 / \ln(1+g)\). The rule is very close at low growth and a little off at high growth.
Read an error message from the bottom up
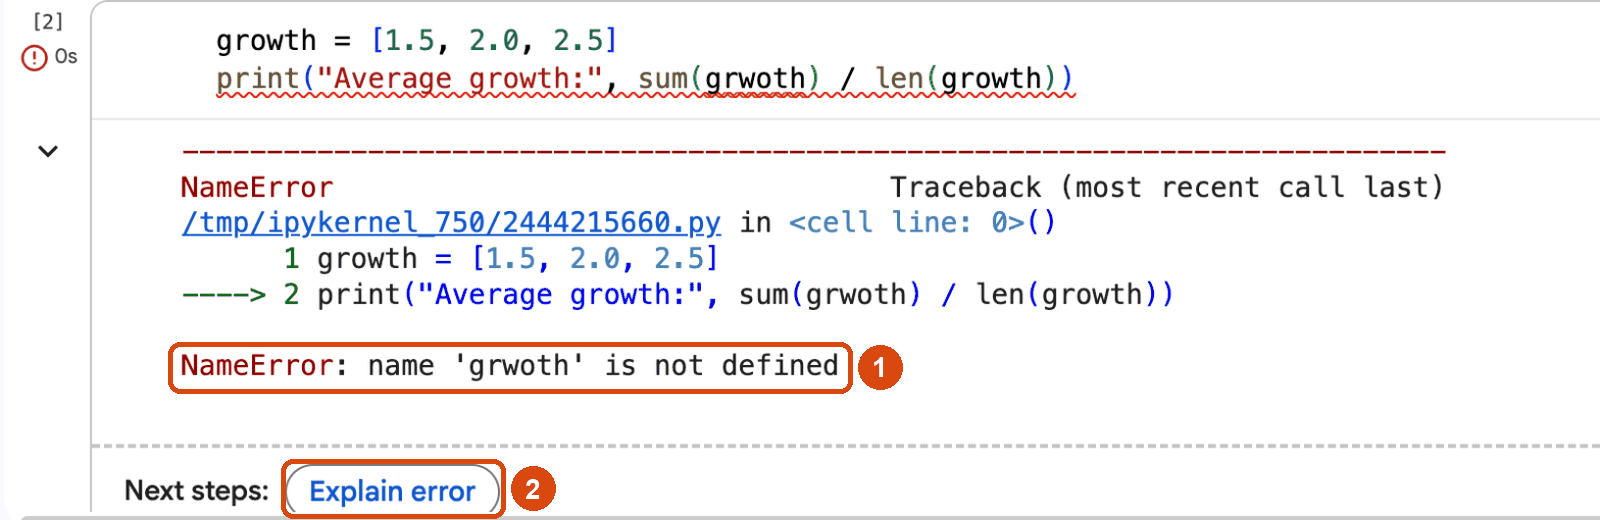
- The last line names the error and what went wrong:
name 'grwoth' is not defined. - The arrow
---->points to the line that failed. - Explain error asks Gemini for help (Act III). Read the message yourself first.
try … except catches an error instead of stopping
TypeError: can only concatenate str (not "int") to str
GDP in 2025
The setup cell of every chapter uses try … except to run one line that only works in Colab.
Indentation is part of the code, not decoration
Spaces at the start of a line are just for looks; Python ignores them.
Python uses the indentation to know which lines belong to a for, an if or a def. Forget it, or mix 3 and 4 spaces, and you get an IndentationError, or worse, a line that silently runs outside the loop.
A function for the average growth rate
Write a function growth_rate(y_start, y_end, years) that returns the average annual growth rate in percent. Check it with the U.S. numbers: 47713 in 1990, 75459 in 2022. You should get about 1.4.
Act II cheat sheet: Python building blocks
| Building block | Example from this act |
|---|---|
| arithmetic and powers | 7 // 3, 7 % 3, 1.02 ** 35 |
| variables | g = growth_factor ** (1 / 32) - 1 |
| f-strings | f"{g:.2%}", f"{y:,.0f}" |
| lists | countries[0], countries[-1], .append(...) |
| loops | for t in range(50): (colon + 4 spaces) |
| conditions | if … elif … else, ==, !=, >= |
| dictionaries | params["s"] |
| functions | def output(k, A=1.0): return A * k ** (1 / 3) |
| libraries and errors | import math, try … except TypeError |
AI-powered coding with Gemini
Act III
Gemini is built into Colab, and it can see your notebook
- You ask in plain language, in English or in your own language.
- Gemini reads the notebook: its text, its code and the results of the cells you ran.
- So you can ask about “this cell” or “the table above”, and it can write and run new cells.
Gemini needs a Google account of someone aged 18 or older in a supported country. Everything else in the book works without it.
Five ways to use Gemini in Colab
| Tool | What you do |
|---|---|
| Ask Gemini | ask about Python, economics or a cell of the notebook |
| Generate code | describe the code you want; accept or reject the cell it writes |
| Explain error | click the button under an error; get an explanation and a fix |
| The agent | describe a whole analysis; Gemini plans, writes, runs and reports |
| Learn Mode | Gemini becomes a tutor that guides you step by step |
Then three skills that matter more than any button: good prompts, checking the output, responsible use.
Code that runs is not the same as code that is right
If the AI’s code runs without an error, the answer is right.
A wrong formula, a wrong column or a wrong year range gives no error message: you get a number that looks fine. You only notice if you can read the code and know what the number should be.
What is the average growth rate of an income that rises 50% and then falls 50%?
incomes = [100, 150, 75]     # income rises 50 percent, then falls 50 percent
yearly = []
for t in range(1, len(incomes)):
    yearly.append((incomes[t] / incomes[t - 1] - 1) * 100)
print("yearly growth rates (percent):", yearly)
print("average of the yearly rates:", sum(yearly) / len(yearly))

g_true = ((incomes[-1] / incomes[0]) ** (1 / 2) - 1) * 100     # the formula of Section A.4.2
print(f"true average annual growth rate: {g_true:.1f} percent")
Predict both numbers before you look.
yearly growth rates (percent): [50.0, -50.0]
average of the yearly rates: 0.0
true average annual growth rate: -13.4 percentThe average of yearly rates says 0; income actually fell 25 percent
Use the compound rate \(g = (y_{end}/y_{start})^{1/n} - 1\), the formula of Act II, not the average of yearly rates.
With real data the gap can flip the sign: the mini project finds a country that got poorer but “grows” 4.6 percent a year on the wrong formula.
The blue star opens the Gemini panel
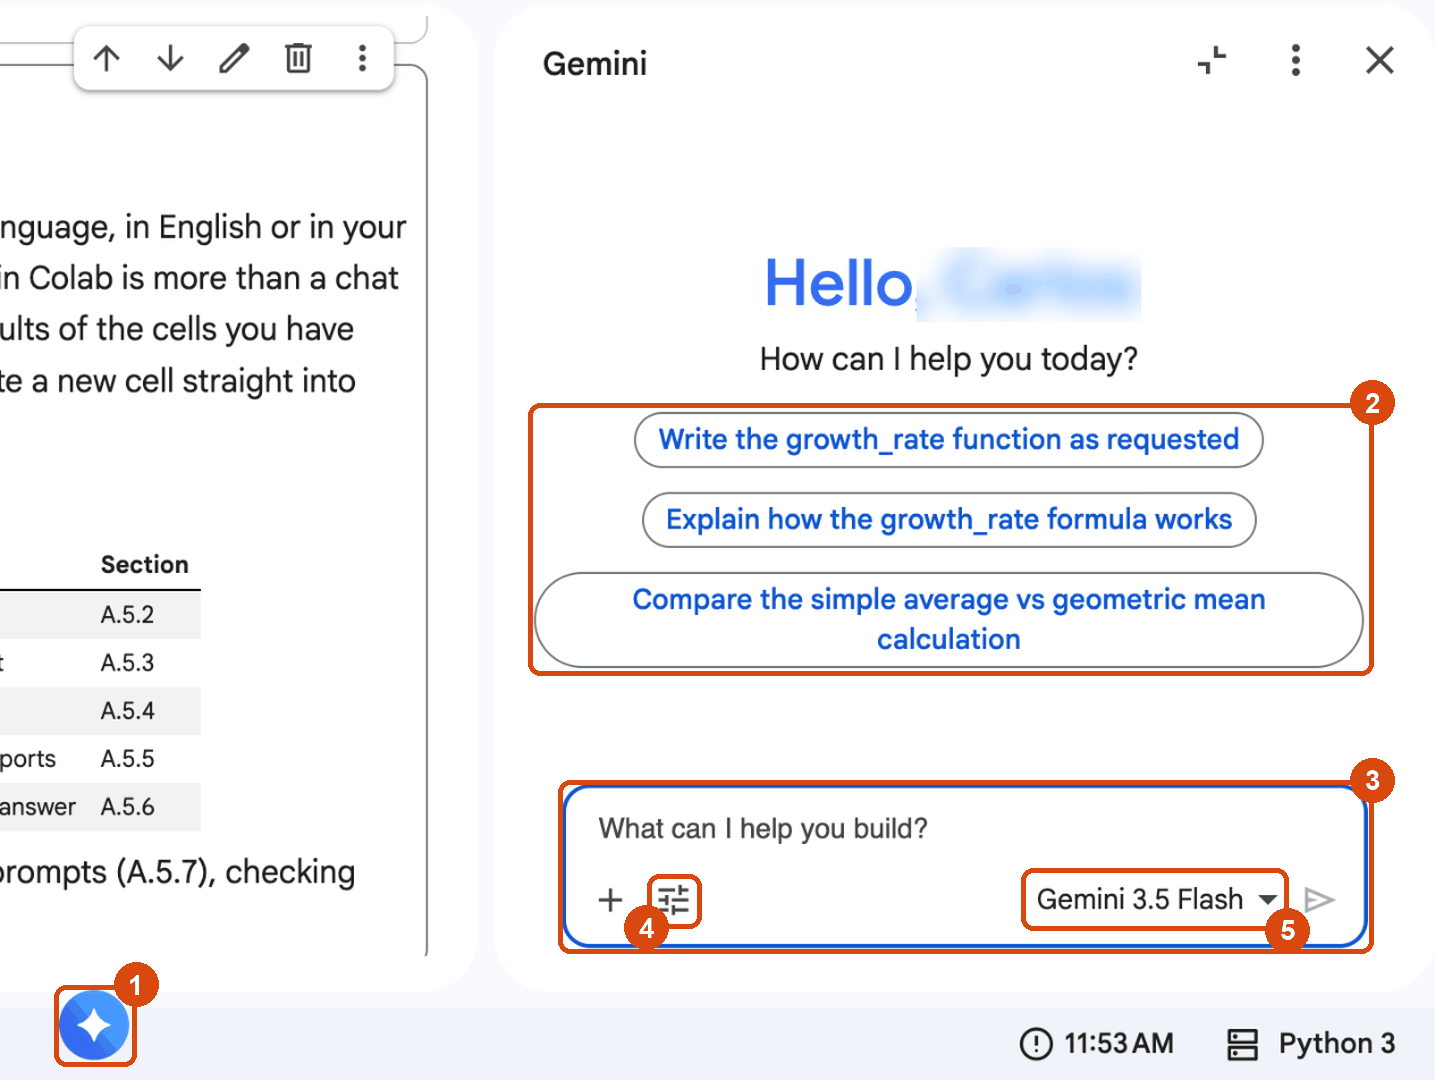
1 the Gemini button · 2 suggested prompts · 3 the prompt box · 4 the mode menu · 5 the model menu
Ask Gemini to explain a cell, line by line
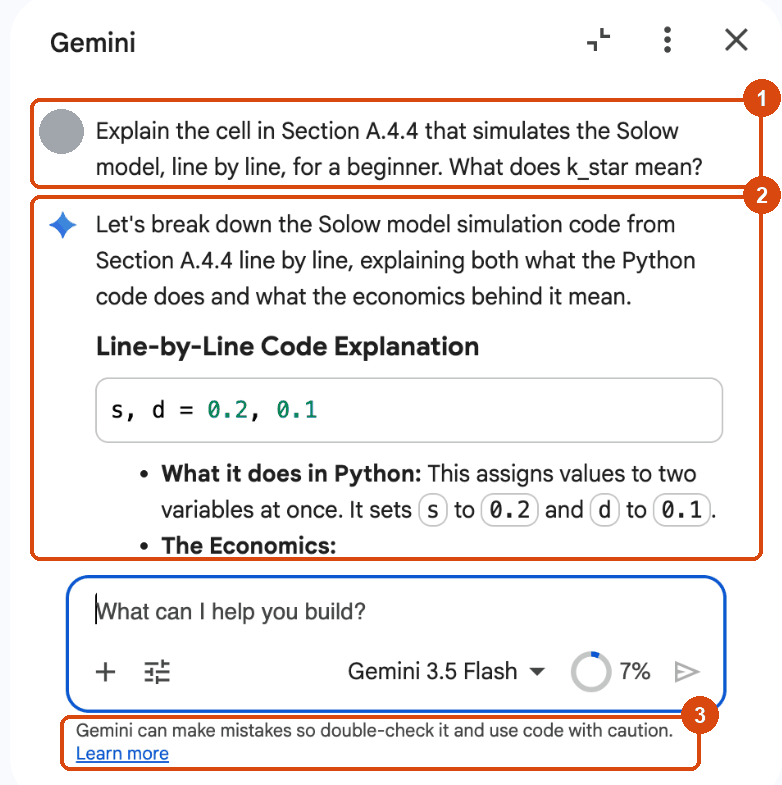
1 the Solow loop of A.4.4 · 2 our prompt · 3 the line-by-line answer · 4 “Gemini can make mistakes”
Generate code: Gemini writes the cell, you decide
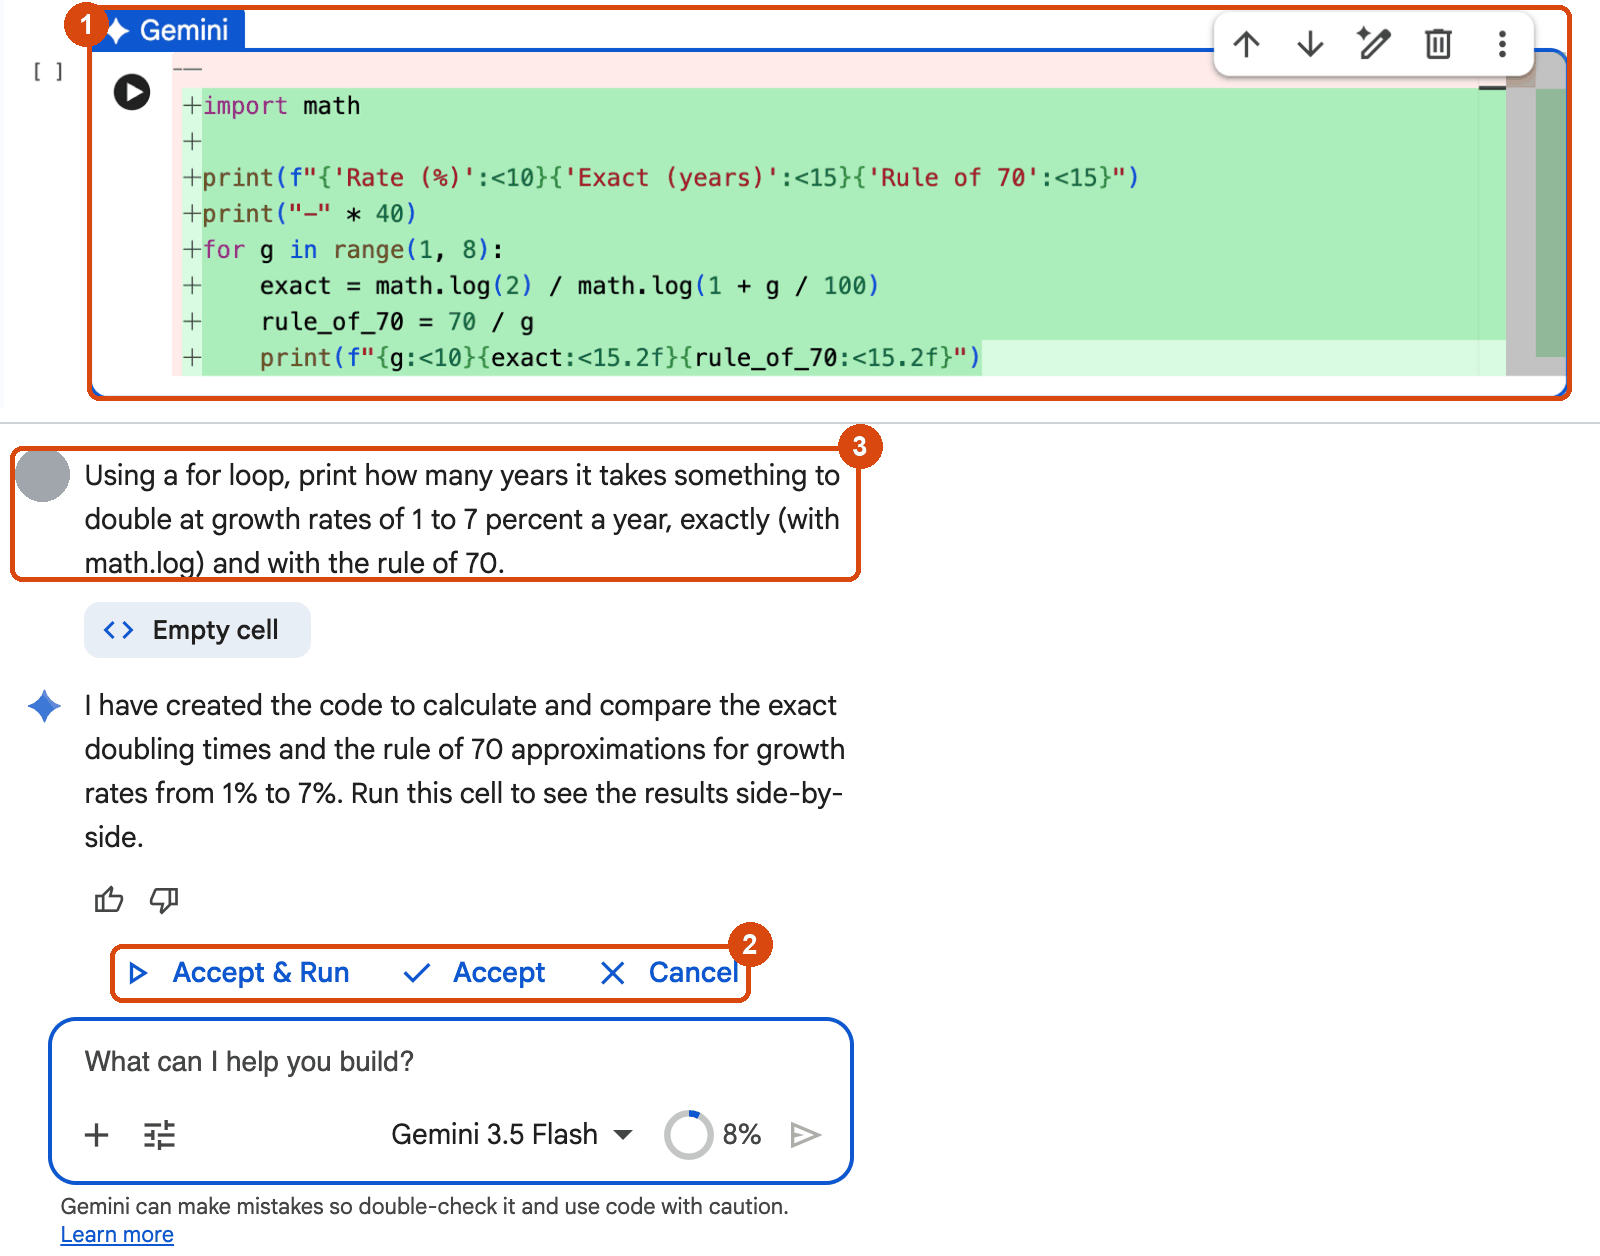
1 the new cell, shown as a diff (green lines start with +) · 2 Accept & Run, Accept or Cancel · 3 our request
Read the cell before you accept it
- The formula:
math.log(2) / math.log(1 + g / 100)is the exact doubling time. Right. - The range:
range(1, 8)gives 1 to 7, becauserangestops before its end value. Right. - Your code: it rewrote
70 / ginstead of callingyears_to_double(A.4.7). Fine here; in a long notebook, duplicated code drifts apart. - Inline completions: grey suggestions as you type; Tab accepts. Switch them off in Tools → Settings → AI Assistance while you learn.
Explain error: an explanation and a fix to check
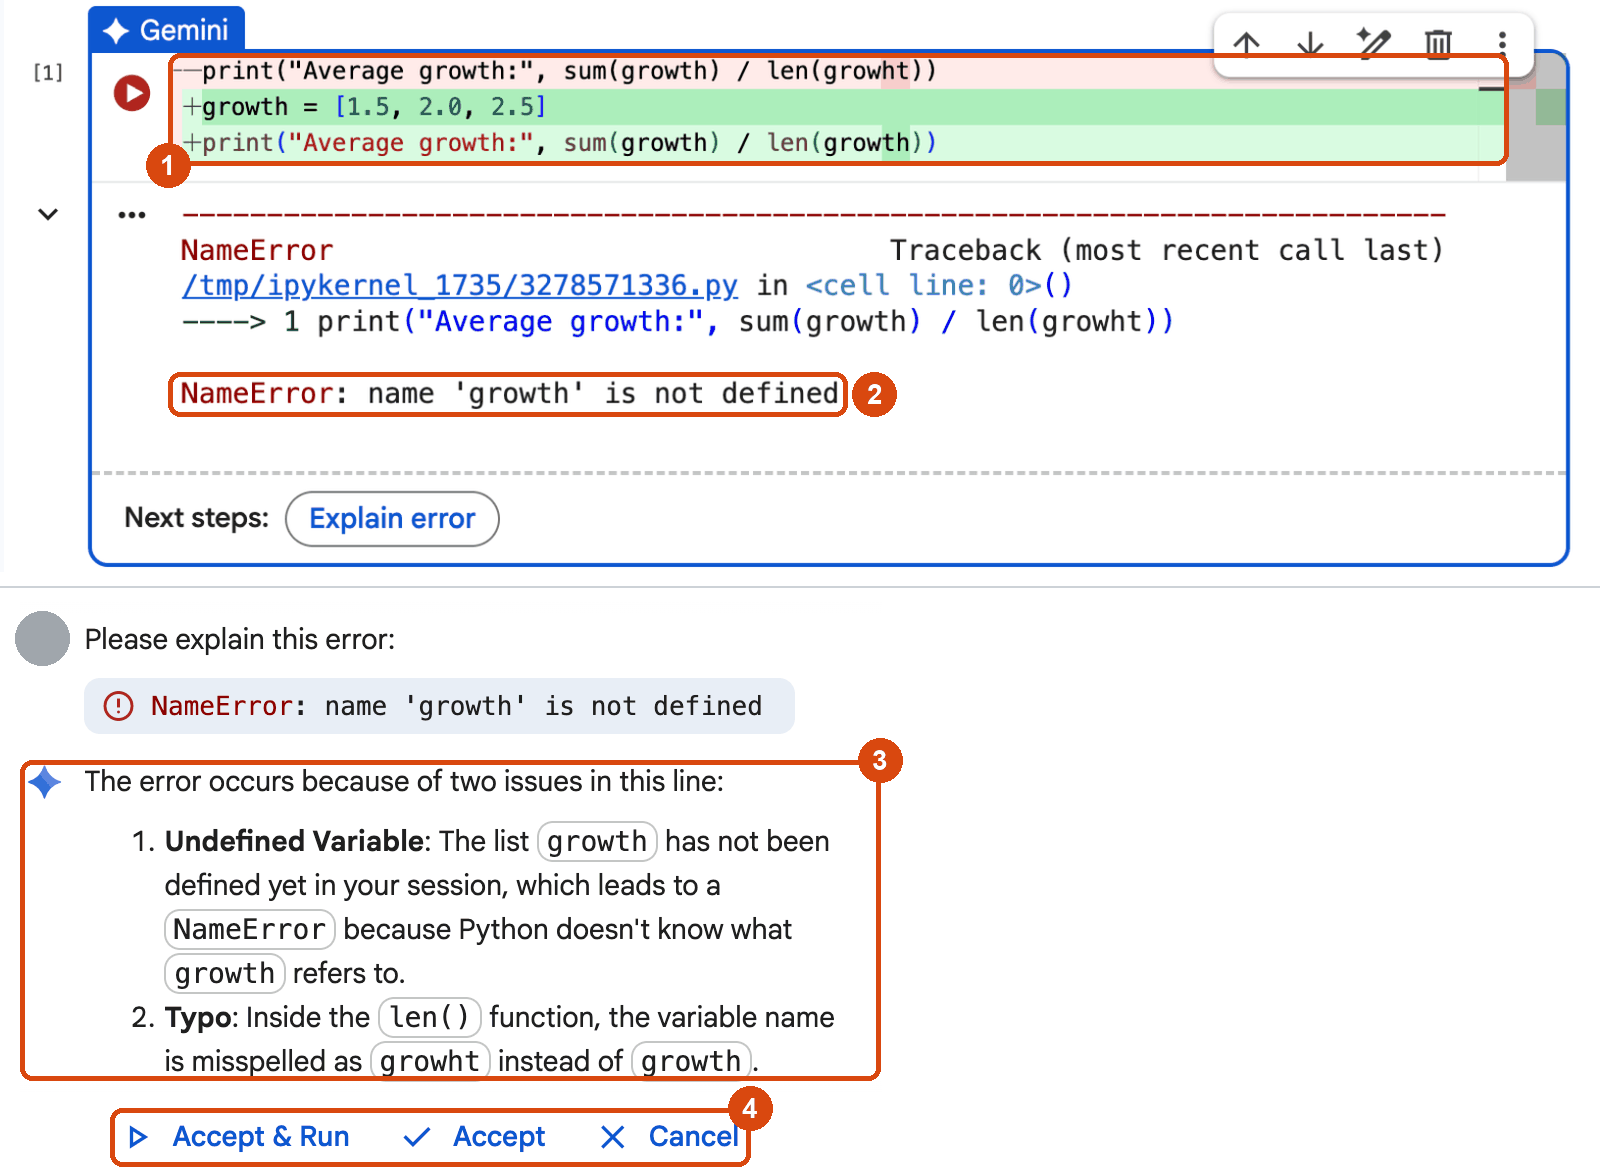
1 the proposed fix, as a diff · 2 the error · 3 Gemini’s explanation · 4 accept or cancel the fix
Accepting the fix makes the typo go away, not the problem
Gemini fixed it, so I can click Accept & Run and move on.
The fix adds growth = [1.5, 2.0, 2.5]: the cell now runs, on invented numbers, not your data. The real cure: run the cell that creates your data (Runtime → Run before).
The agent: one request, a whole analysis
Load …/data/appA/maddison_panel.csv with pandas. Plot GDP per person of every country since 1950 on a ratio scale, and tell me which country grew fastest since 1950.
A plan → Cells, run after you accept → A report on the results
Google first launched this as the Data Science Agent; it now lives in the same Gemini panel.
The agent at work
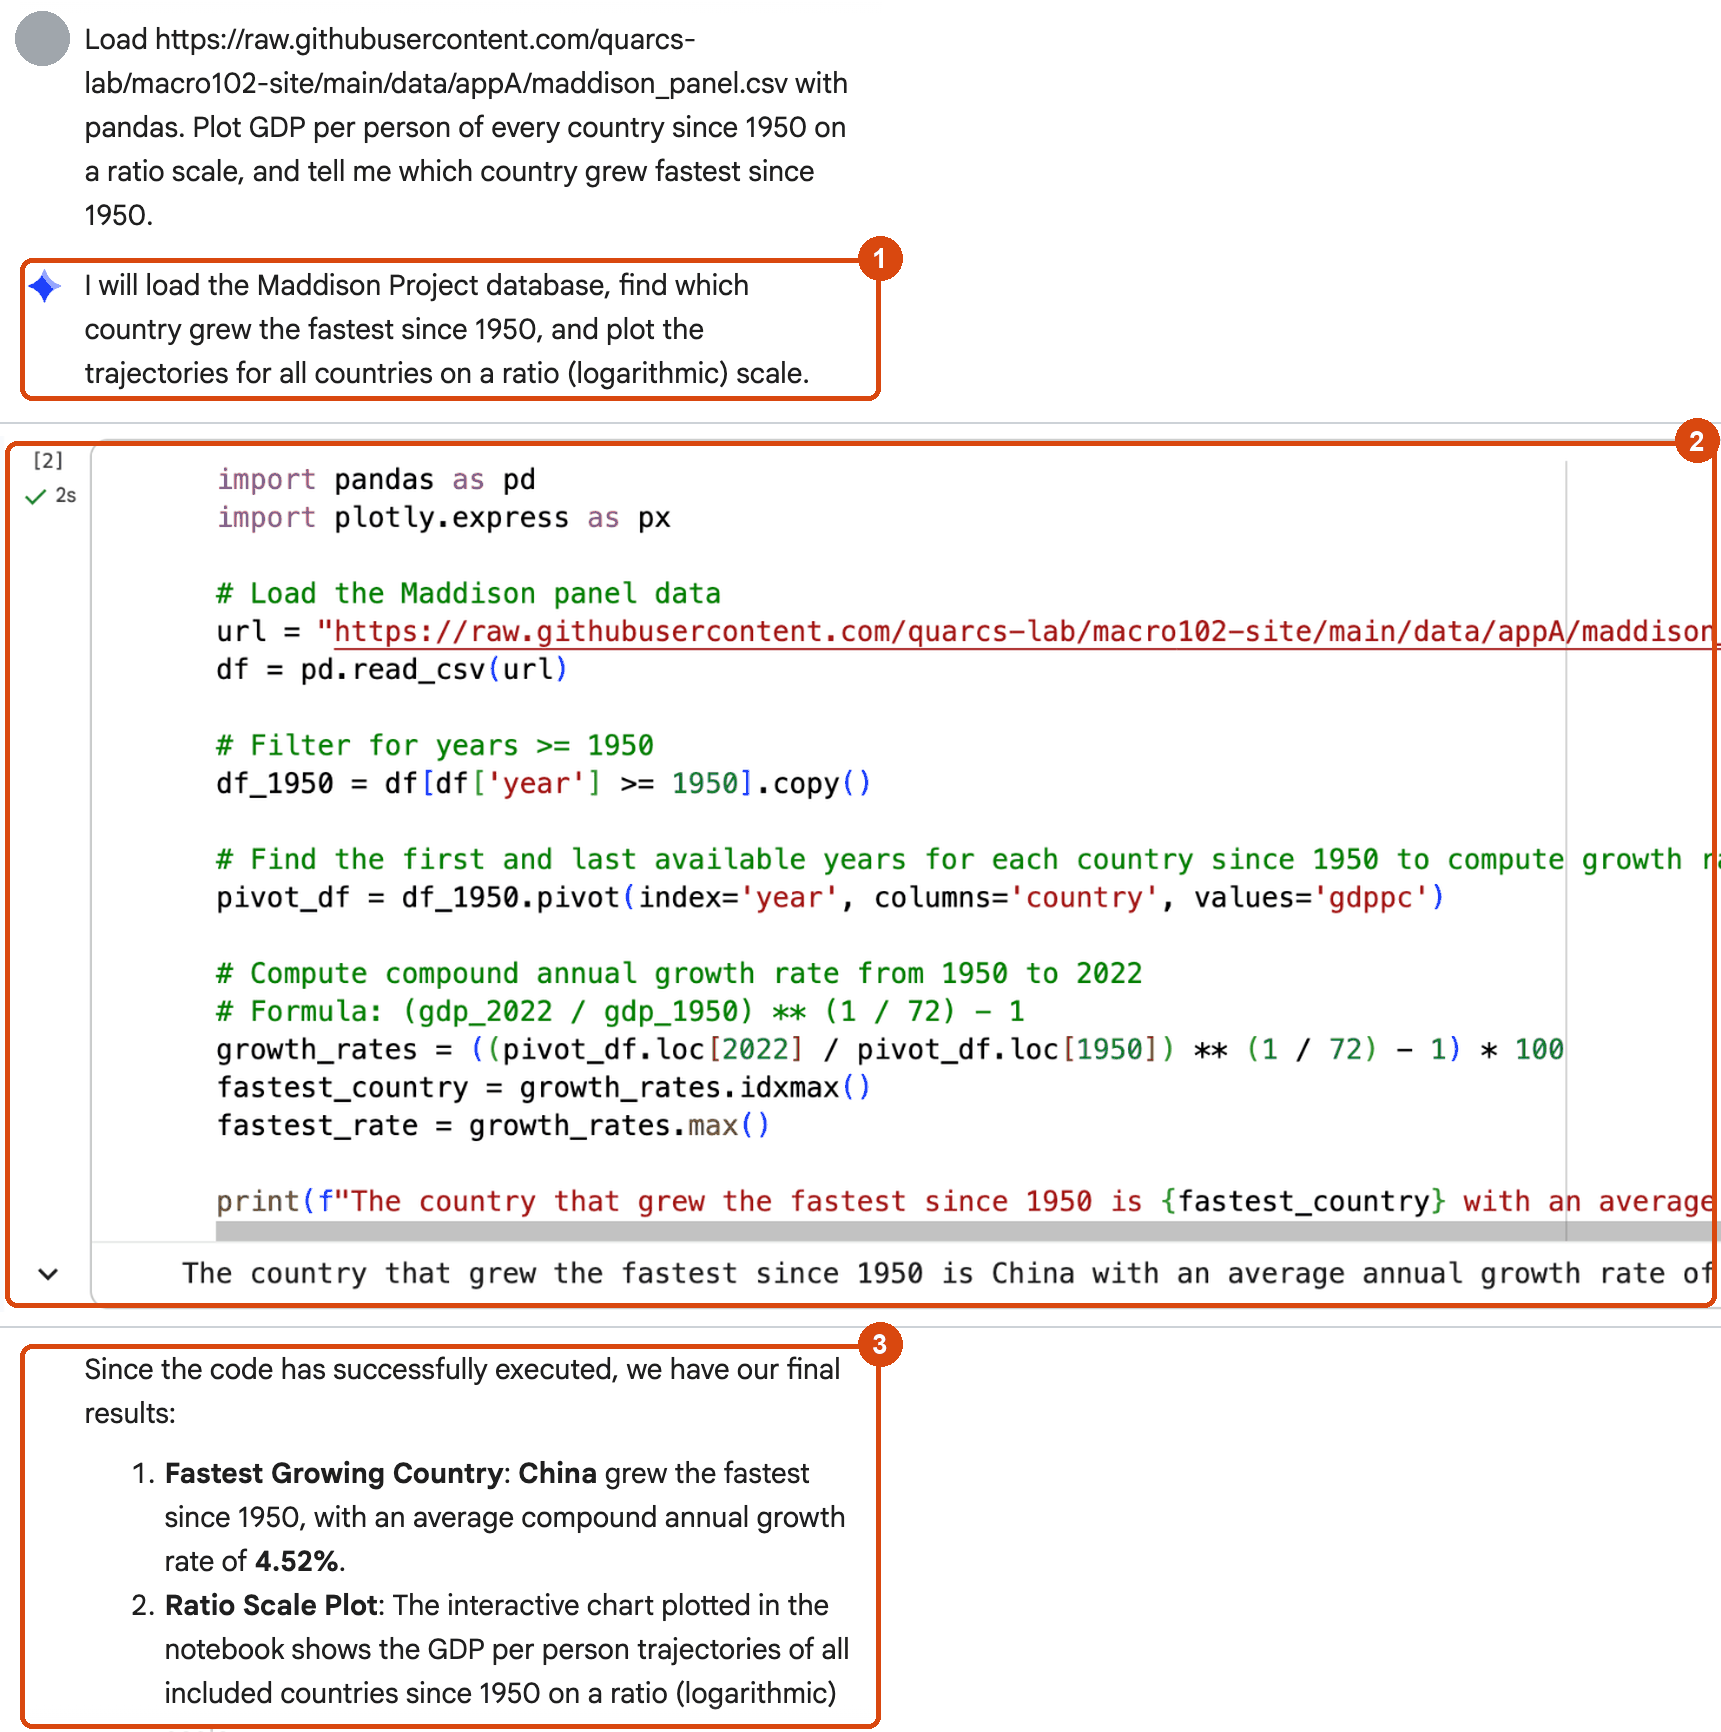
1 the plan · 2 the first of two cells it wrote and ran · 3 its report: China, 4.52 percent a year since 1950
Learn Mode: a tutor instead of an answer
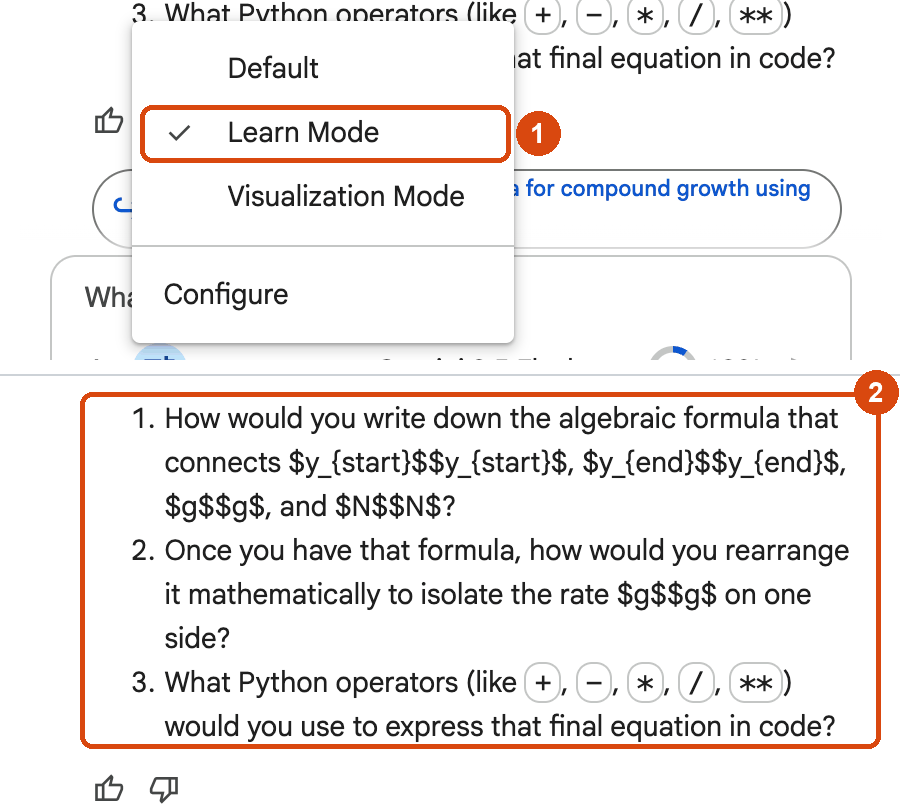
1 Learn Mode in the mode menu · 2 instead of code, Gemini asks you three questions
Four habits make a good prompt
- Name the data: the file or DataFrame and the exact columns (
gdp_pc,year). - Define the calculation: the formula, not only its name.
- Fix the scope: which years, which countries, what units.
- Describe the result: a sorted table? a line chart on a ratio scale, with labeled axes?
Not what you wanted? Reply in the same chat (“use 1990 as the start year”). Gemini remembers the conversation.
Vague prompts get vague code
| Vague | Better |
|---|---|
| Plot GDP. | Plot gdppc from panel for China and the United States since 1950, Plotly Express, ratio scale, labeled axes. |
| Which countries grew fastest? | Using pwt, compute the compound average annual growth rate of gdp_pc from 1990 to 2023 for each country; show the ten fastest in a table. |
| Fix this. | This cell gives a KeyError for ‘gdp’. The names are in df.columns. Fix the column name only. |
| Explain the Solow model. | Explain the cell above line by line for a beginner, and relate it to k(t+1) = k(t) + s k(t)^(1/3) − d k(t). |
Check AI output before you use it
- Read every line. Ask Gemini to explain any line you do not understand.
- Check the formula. Compound rate, not the average of yearly rates.
- Check one number by hand in a new cell.
- Check the data: file, columns, years, units, missing values.
- Look at a chart for jumps, impossible values, surprising countries.
- Check the report: every number must match an output.
- Rerun from a clean start: Runtime → Restart session and run all.
Use AI responsibly
- Follow your course’s rules. Policies differ; disclose AI help when asked (
# written with Gemini, checked by me). - Protect private information. Google stores prompts, code and answers, and people may read them. No personal data, passwords or API keys.
- You are responsible for the result, whoever typed the code.
- Use it to learn, not to skip learning: more explain this, less write this for me.
Try each AI tool once
1. Ask: select the cell of A.4.8 that compares the exact doubling time with the rule of 70; ask Gemini why the rule works. 2. Fix: run print(growth_factor ** (1 / yeras)) and click Explain error. Does the fix keep your variables? 3. Generate and check: ask for growth_rate(y_start, y_end, years); compare with yours; test it on the U.S. numbers (about 1.4).
Act III cheat sheet: AI-powered coding
| Tool or habit | Where | Remember |
|---|---|---|
| Ask Gemini | the blue star | name the cell; read the reminder |
| Generate | generate in an empty cell | read the diff; then Accept & Run |
| Explain error | under a failed cell | the fix may hide the problem |
| The agent | the Gemini panel | check the plan, the code and the report |
| Learn Mode | the mode menu | a tutor: you write the code |
| Prompts | data, formula, scope, result | |
| Checking | read, recompute one number, rerun all |
The data science libraries
Act IV
Four libraries do almost all the work in this book
| Library | Nickname | What it does | Where you see it most |
|---|---|---|---|
| NumPy | np |
fast math on whole arrays of numbers | model curves (np.linspace), logs, trend lines |
| pandas | pd |
data tables: read, filter, reshape, combine | every data figure |
| Plotly | px, go |
interactive charts | px for data figures, go for model figures |
| ipywidgets | sliders, buttons and menus | the live model figures |
Every chapter uses all four.
Every chapter starts with a setup cell: first, the libraries
# Libraries used in this appendix
import numpy as np                              # numbers and arrays
import pandas as pd                             # data tables
import plotly.express as px                     # quick charts from data tables
import plotly.graph_objects as go               # charts built piece by piece (model figures)
import plotly.io as pio
from plotly.subplots import make_subplots       # several panels in one figure
from ipywidgets import interact, FloatSlider, Dropdown, SelectMultiple
import numpy as np: load NumPy under the nicknamenp, so we writenp.log.from ipywidgets import interact: load one function, so we write justinteract.
The rest of the setup cell: one look, Colab support and the data address
# One light blue/green look for every chart
BLUE, TEAL, GREEN, GRAY = "#16528c", "#008070", "#7fb23a", "#8a96a3"
pio.templates.default = "plotly_white"
WIDE = {"description_width": "initial"}         # show the full widget labels

# Colab only: let Plotly charts appear inside the interactive widgets
try:
    import google.colab
    google.colab.output.enable_custom_widget_manager()
except ImportError:
    pass                                        # not running in Colab: nothing to do

# The data files of this appendix live in the book's GitHub repository
DATA_URL = "https://raw.githubusercontent.com/quarcs-lab/macro102-site/main/data/appA/"Folded helper cells build the website versions: run them, then move on
- Most chapters have one or two folded helper cells right after the setup cell.
- They precompute the website version of each interactive figure: one chart per slider value, joined by a Plotly slider.
- You must run them; you do not need to read them.
Run all runs them for you.
A NumPy array does math on every element at once
What six numbers does np.linspace(0, 10, 6) make?
[ 0.  2.  4.  6.  8. 10.]
[0.         1.25992105 1.58740105 1.81712059 2.         2.15443469]
[0. 1.25992105 1.58740105 1.81712059 2. 2.15443469]NumPy has the usual math functions and summaries
2.25 3.0
4.605170185988092 100.00000000000004
Also np.sqrt, .min(), and many more. np.log is the natural log.
Computers round decimals in the last digits
np.exp(np.log(100)) printed 100.00000000000004, so NumPy is broken.
Computers store decimals in binary with about 16 significant digits, so tiny rounding errors appear in the last digits, as in 7 / 3 = 2.3333333333333335. They never matter for economics; round when you print.
pandas reads a data table with one line
| iso3 | country | year | gdppc | |
|---|---|---|---|---|
| 0 | ARG | Argentina | 1870 | 3019 |
| 1 | ARG | Argentina | 1875 | 3362 |
| 2 | ARG | Argentina | 1876 | 3369 |
| 3 | ARG | Argentina | 1877 | 3638 |
| 4 | ARG | Argentina | 1878 | 3379 |
A DataFrame: named columns, one row per observation. GDP per person for seven countries since 1870, Maddison Project Database.
Long format: one row per country and year
| iso3 | country | year | gdppc |
|---|---|---|---|
| ARG | Argentina | 1870 | 3019 |
| ARG | Argentina | 1875 | 3362 |
| … | … | … | … |
| ZAF | South Africa | 2022 | 14728 |
iso3: a three-letter country code.gdppc: GDP per person in 2022 U.S. dollars.- Long (or tidy) tables are what Plotly Express wants.
- Later,
pivotturns it wide: one column per country.
Three quick ways to look at a new table
(965, 4)
['iso3', 'country', 'year', 'gdppc']| year | gdppc | |
|---|---|---|
| count | 965 | 965 |
| mean | 1951.1 | 13,743.5 |
| min | 1870 | 1,031 |
| max | 2022 | 75,459 |
A condition inside the brackets keeps only the rows where it is True
| iso3 | country | year | gdppc | |
|---|---|---|---|---|
| 668 | JPN | Japan | 2020 | 47513 |
| 669 | JPN | Japan | 2021 | 48611 |
| 670 | JPN | Japan | 2022 | 49373 |
panel["country"] picks one column; panel[condition] picks rows.
Combine conditions with & (and) or | (or), each in parentheses
How many rows will asia have?
| iso3 | country | year | gdppc | |
|---|---|---|---|---|
| 233 | CHN | China | 2018 | 20613 |
| … | … | … | … | … |
| 237 | CHN | China | 2022 | 24821 |
| 526 | IND | India | 2018 | 9091 |
| … | … | … | … | … |
| 530 | IND | India | 2022 | 10019 |
pandas wants &, not and, and parentheses around each condition
panel[panel["year"] >= 2018 and panel["country"] == "China"] should work: and means and.
Python’s and works on one True or False, not on a whole column, so pandas stops with a ValueError (“the truth value of a Series is ambiguous”). Use & or |, and put each condition in its own parentheses.
New columns, sorting, and the latest year
| iso3 | country | year | gdppc | gdppc_thousands | |
|---|---|---|---|---|---|
| 823 | USA | United States | 2022 | 75459 | 75.459 |
| 390 | GBR | United Kingdom | 2022 | 49551 | 49.551 |
| 670 | JPN | Japan | 2022 | 49373 | 49.373 |
| 237 | CHN | China | 2022 | 24821 | 24.821 |
| 148 | ARG | Argentina | 2022 | 23600 | 23.600 |
| 964 | ZAF | South Africa | 2022 | 14728 | 14.728 |
| 530 | IND | India | 2022 | 10019 | 10.019 |
groupby summarizes each group: one row per country
| country | min | max | count |
|---|---|---|---|
| Argentina | 3019 | 25807 | 149 |
| China | 1031 | 24821 | 89 |
| India | 1088 | 10019 | 140 |
| Japan | 2038 | 49547 | 140 |
| South Africa | 1559 | 15544 | 141 |
| United Kingdom | 7443 | 50462 | 153 |
| United States | 6197 | 75459 | 153 |
Split by country, take the gdppc column, apply three summaries to each group.
The count column is a story about the data
- The United States and the United Kingdom have all 153 years from 1870 to 2022.
- China has only 89: the historical estimates cover only some years before 1950.
- Japan’s maximum (49,547) is not its 2022 value (49,373): income can fall.
Count before you compare: a missing year is not a zero.
pivot turns the long table wide: one column per country
country
Argentina          4
China             64
India             13
Japan             13
South Africa      12
United Kingdom     0
United States      0
dtype: int64
Years with no estimate become NaN, pandas’ marker for a missing value.
.loc[...] picks rows by their label
| year | Argentina | China | India | Japan | South Africa | U.K. | U.S. |
|---|---|---|---|---|---|---|---|
| 1870 | 3019 | 1219 | 1097 | 2038 | 1659 | 7520 | 6197 |
| 1950 | 10256 | 1031 | 1273 | 3950 | 5214 | 14271 | 19662 |
| 2022 | 23600 | 24821 | 10019 | 49373 | 14728 | 49551 | 75459 |
Three snapshots of 150 years. China was poorer in 1950 than in 1870, then passed Argentina by 2022.
One line computes every country’s growth rate since 1950
Which of the seven grew fastest from 1950 to 2022, and which most slowly?
country
Argentina         1.16
South Africa      1.45
United Kingdom    1.74
United States     1.89
India             2.91
Japan             3.57
China             4.52
dtype: float64merge joins two tables on a column they share
fig3-7.csv: 111 countries, GDP per person relative to the U.S. and growth 1960–2023 (Penn World Table).countries.csv: each country’s World Bank region and income group.on="iso3": match rows by country code.how="left": keep every row ofgrowth60.
The merged table has a region and an income group for every country
| iso3 | country | gdppc_rel_us_2023 | growth_1960_2023_pct | region | income | |
|---|---|---|---|---|---|---|
| 0 | ARG | Argentina | 0.3677 | 3.270 | Latin America & Caribbean | Upper middle |
| 1 | AUS | Australia | 0.8424 | 2.064 | East Asia & Pacific | High |
| 2 | AUT | Austria | 0.8436 | 2.772 | Europe & Central Asia | High |
| 3 | BDI | Burundi | 0.0124 | 0.245 | Sub-Saharan Africa | Low |
| 4 | BEL | Belgium | 0.8274 | 2.567 | Europe & Central Asia | High |
The output of growth60.head(), without the two 2019 columns of the file.
Average growth since 1960 by region
region
Sub-Saharan Africa            1.30
Latin America & Caribbean     1.72
North America                 1.98
South Asia                    2.61
Middle East & North Africa    2.63
Europe & Central Asia         2.89
East Asia & Pacific           3.89
Name: growth_1960_2023_pct, dtype: float64
merge gave us the region; groupby averages within it. East Asia grew three times as fast as Sub-Saharan Africa.
Fastest and slowest since 1960
Which country in growth60 grew fastest from 1960 to 2023, and which most slowly? Use sort_values, or the methods nlargest and nsmallest.
Act IV cheat sheet: NumPy and pandas
| You want to … | Write |
|---|---|
| evenly spaced x-values | np.linspace(0, 10, 200) |
| math on a whole array or column | k ** (1 / 3), np.log(x), x.mean() |
| read a CSV file | pd.read_csv(DATA_URL + "file.csv") |
| look at a table | .head(), .shape, .columns, .describe() |
| keep rows | df[df["year"] >= 2018], (…) & (…), .isin([...]) |
| add a column | df["new"] = df["old"] / 1000 |
| sort | .sort_values("col", ascending=False), .nlargest(5, "col") |
| summarize groups | df.groupby("country")["gdppc"].agg(["min", "max"]) |
| reshape and join | df.pivot(index=, columns=, values=), a.merge(b, on="iso3") |
Plotly Express draws a whole chart from a table in one call
fig = px.line(panel, x="year", y="gdppc", color="country", log_y=True,
              labels={"year": "Year", "gdppc": "GDP per person (2022 dollars, ratio scale)",
                      "country": ""},
              title="GDP per person in seven economies, 1870-2022")
fig.update_yaxes(tickvals=[1000, 2000, 5000, 10000, 20000, 50000, 100000])
fig.show()- Name the table, the column for each axis and the column for the colors.
log_y=True: a ratio scale.tickvals: which numbers label the axis.
Seven economies over 150 years
On a ratio scale, a straight line means a constant growth rate. Which economies grew at a steady rate, and which sped up?
On a ratio scale the U.S. line is nearly straight; Japan and China bend upward
Data: Maddison Project Database 2023 (Bolt and van Zanden 2024), GDP per person in 2022 dollars; file data/appA/maddison_panel.csv. Chart inspired by the discussion of long-run growth in Chapter 3 of Jones (2024), Macroeconomics, 6th ed.
A ratio scale turns constant growth into a straight line
- The U.S. line is close to straight: its percentage growth has been fairly steady for 150 years.
- Japan’s line is steepest after 1950: fast catch-up growth, then a slowdown.
- China’s line bends sharply upward after 1980.
px.line, one call: hover, zoom and legend come for free.
px.scatter shows how two variables relate
plot_data = growth60[growth60["iso3"] != "VEN"]
labels = {"gdppc_rel_us_2023": "GDP per person in 2023 (U.S. = 1, ratio scale)",
          "growth_1960_2023_pct": "Average growth, 1960-2023 (percent a year)",
          "region": "Region"}
fig = px.scatter(plot_data, x="gdppc_rel_us_2023", y="growth_1960_2023_pct", color="region",
                 hover_name="country", log_x=True, labels=labels,
                 title="Countries that grew faster since 1960 are richer today")
fig.update_xaxes(tickvals=[0.01, 0.03, 0.1, 0.3, 1])
fig.show()
hover_name puts the country’s name in the hover box; color="region" gives each region a color. Venezuela is dropped first.
Growth since 1960 and income today
Did the countries that grew faster since 1960 end up richer in 2023? How strong is the link?
Draw the cloud you expect: income relative to the U.S. on the horizontal axis, growth on the vertical axis.
Countries that grew faster since 1960 are richer today
Data: Penn World Table 11.0 (Feenstra, Inklaar and Timmer 2015), real GDP per person (rgdpe/pop); regions from the World Bank country classification; files data/appA/fig3-7.csv, countries.csv. Chart inspired by Fig. 3.7 in Jones (2024), Macroeconomics, 6th ed.
Faster growth since 1960 goes with higher income today
- The cloud slopes up: growth over six decades shows up in today’s income levels.
- East Asia & Pacific sits high (region average 3.89%); Sub-Saharan Africa low (1.30%).
- Dropping Venezuela first is a data check, not cosmetics.
Three arguments of px.scatter (hover_name, color, log_x) make a chart you can explore.
animation_frame adds a play button and a slider
decades = panel[panel["year"].isin([1950, 1960, 1970, 1980, 1990, 2000, 2010, 2020])]
fig = px.bar(decades, x="country", y="gdppc", animation_frame="year", range_y=[0, 80000],
             labels={"country": "", "gdppc": "GDP per person (2022 dollars)", "year": "Year"},
             title="GDP per person by decade: press the play button")
fig.show()- Each frame shows the rows for one value of the
yearcolumn. range_yfixes the y-axis, so the bars can visibly grow from frame to frame.
GDP per person by decade
Press play in your head: which country’s bar changes most between 1950 and 2020?
Will China’s bar pass Argentina’s and South Africa’s by 2020? When does it start to rise?
China’s bar barely moves until 1980, then rises faster than any other
Data: Maddison Project Database 2023 (Bolt and van Zanden 2024); file data/appA/maddison_panel.csv. Chart inspired by the discussion of long-run growth in Chapter 3 of Jones (2024), Macroeconomics, 6th ed.
An animation shows the race; a ratio scale shows the growth rates
- By 2020 China has passed Argentina and South Africa.
- On a linear axis the U.S. bar adds the most dollars each decade, even at steady growth.
- Animation is good for who passes whom; the ratio-scale line chart is better for how fast.
Pick the chart for the question.
Graph objects build a chart piece by piece: the model figures
k = np.linspace(0, 10, 200)
fig = go.Figure()
fig.add_trace(go.Scatter(x=k, y=output(k), mode="lines", name="A = 1",
                         line=dict(color=BLUE, width=3)))
fig.add_trace(go.Scatter(x=k, y=output(k, A=1.5), mode="lines", name="A = 1.5",
                         line=dict(color=TEAL, width=3, dash="dash")))
fig.update_layout(title="Higher productivity A shifts the production function up",
                  xaxis=dict(title="Capital per person, k", range=[0, 10]),
                  yaxis=dict(title="Output per person, y", range=[0, 3.5]))
fig.show()
go.Figure() starts an empty chart; each add_trace adds one curve; update_layout sets the title and axes.
Two production functions
What does raising productivity from \(\bar{A} = 1\) to \(\bar{A} = 1.5\) do to the curve \(y = \bar{A}k^{1/3}\)? A parallel shift, or something else?
Higher productivity scales the production function up at every \(k\)
Model figure: \(y = \bar{A}k^{1/3}\) for \(\bar{A} = 1\) and \(\bar{A} = 1.5\). Adapted from the production model of Chapter 4 in Jones (2024), Macroeconomics, 6th ed.
A higher \(\bar{A}\) multiplies output; it does not add a constant
- The answer: not parallel. Output is multiplied by 1.5 at every \(k\), so the gap widens as \(k\) grows.
- Both curves bend: diminishing returns to capital, the exponent \(1/3\).
- A model figure is a few
add_tracecalls on one function.
One function, two calls, two curves: that is how every model figure of the book is drawn.
make_subplots puts panels side by side
fig = make_subplots(rows=1, cols=2, subplot_titles=("Linear scale", "Ratio scale"))
for name, color in [("United States", BLUE), ("China", TEAL)]:
    one = panel[panel["country"] == name]
    fig.add_trace(go.Scatter(x=one["year"], y=one["gdppc"], mode="lines", name=name,
                             line=dict(color=color)), row=1, col=1)
    fig.add_trace(go.Scatter(x=one["year"], y=one["gdppc"], mode="lines", name=name,
                             line=dict(color=color), showlegend=False), row=1, col=2)
fig.update_yaxes(title_text="GDP per person (2022 dollars)", row=1, col=1)
fig.update_yaxes(type="log", tickvals=[1000, 3000, 10000, 30000, 100000], row=1, col=2)
fig.update_layout(title="The same two series on two scales")
The loop runs once per (name, color) pair; row= and col= pick the panel; showlegend=False lists each country once.
Same data, two scales
On the linear scale, does U.S. growth seem to speed up over time? And on the ratio scale?
Predict the shape of the U.S. line in each panel.
On a linear scale U.S. growth seems to speed up; on a ratio scale it is steady
Data: Maddison Project Database 2023 (Bolt and van Zanden 2024); file data/appA/maddison_panel.csv. Chart inspired by the discussion of ratio scales in Chapter 3 of Jones (2024), Macroeconomics, 6th ed.
A line that curves up on a linear scale can be constant growth
On the linear chart the U.S. curve gets steeper, so U.S. growth has been accelerating.
A constant percentage growth adds more dollars each year as the base grows, so the linear curve bends up. On the ratio scale the U.S. line is close to straight: steady growth. China’s line, by contrast, bends up on both scales after 1980.
ipywidgets turns a function’s arguments into controls
Move a slider: \(\bar{A} = 1.5\) → interact calls production_figure(A=1.5) → A new chart
interact(f, ...) draws one control per argument and calls f again every time you move one.
Step 1: a function that returns a figure
def production_figure(A=1.0, alpha=1 / 3):
    """Production function y = A k^alpha (Chapter 4), with fixed axes so changes are visible."""
    k = np.linspace(0, 10, 200)
    fig = go.Figure()
    fig.add_trace(go.Scatter(x=k, y=k ** (1 / 3), mode="lines", name="Baseline: A = 1, α = 1/3",
                             line=dict(color=GRAY, dash="dash")))
    fig.add_trace(go.Scatter(x=k, y=A * k ** alpha, mode="lines", name="Your production function",
                             line=dict(color=TEAL, width=3)))
    fig.update_layout(title=f"Output per person at k = 8: y = {A * 8 ** alpha:.2f} (baseline 2.00)",
                      xaxis=dict(title="Capital per person, k", range=[0, 10]),
                      yaxis=dict(title="Output per person, y", range=[0, 7]))
    return fig
A dashed baseline that never moves, the user’s curve, and an f-string title that reports \(y\) at \(k = 8\).
Step 2: hand the function to interact with two controls
FloatSlider: decimal numbers frommintomaxin steps ofstep, starting atvalue.Dropdown: a menu; each option is a pair("label shown", value).style=WIDEshows the whole label; the final;hides an extra line of text.
Doubling productivity
At \(k = 8\) and \(\bar{A} = 1\), output is \(y = 2.00\). Move \(\bar{A}\) to 2: what is \(y\) now? And does the curve keep its shape?
Doubling \(\bar{A}\) doubles output at every level of capital
Model figure: \(y = \bar{A}k^{\alpha}\), website version with a precomputed slider for \(\bar{A}\) (0.5 to 2). Adapted from the production model of Chapter 4 in Jones (2024), Macroeconomics, 6th ed.
The website version precomputes; Colab solves on the spot
- Doubling \(\bar{A}\) doubles \(y\): from 2.00 to 4.00 at \(k = 8\).
- In Colab, a larger exponent \(\alpha\) makes the curve bend less: diminishing returns set in more slowly.
- Website: 4 precomputed values of one parameter. Colab: any value of both.
interact + a function that returns a figure = a live model.
Five kinds of controls appear in the chapters
| Control | What it does | Example in the book |
|---|---|---|
FloatSlider, IntSlider |
choose a number | the investment rate in the Solow model (Chapter 5) |
Dropdown |
choose one option from a menu | a country or a base year |
ToggleButtons |
switch between a few options | linear or ratio scale |
SelectMultiple |
choose several items from a list | the country pickers of the data figures |
interact_manual |
run only when you press a button | the “Earthquake!” button of Chapter 5 |
A third production function
Copy the production-function cell (the two add_trace curves) into an empty cell and add a third curve with \(\bar{A} = 0.5\), in the color GREEN and with dash="dot".
Act IV cheat sheet: Plotly and ipywidgets
| You want to … | Write |
|---|---|
| a line chart from a table | px.line(df, x=, y=, color=, log_y=True) |
| a scatter with hover names | px.scatter(df, x=, y=, color=, hover_name="country") |
| an animation | px.bar(..., animation_frame="year", range_y=[...]) |
| a model curve | go.Figure(), fig.add_trace(go.Scatter(x=k, y=f(k))) |
| titles and axes | fig.update_layout(title=, xaxis=dict(...)) |
| two panels | make_subplots(rows=1, cols=2), row=, col= |
| a ratio scale | log_y=True, or update_yaxes(type="log") |
| a live model | interact(f, A=FloatSlider(...)) |
A mini project
Act V
Which economies grew fastest after 1990, and which fell behind?
Which economies raised their GDP per person fastest between 1990 and 2023, and which fell behind?
- Step 1. Load and look.
- Step 2. One row per economy, with its 1990 and 2023 values.
- Step 3. Look at your data; list the fastest and slowest.
- Step 4. An interactive chart.
Step 1: load and look
(11201, 7) | 185 economies
years: 1950 to 2023| iso3 | country | year | gdp_pc | y_rel_us_2019 | pop_millions | in_sample | |
|---|---|---|---|---|---|---|---|
| 0 | ABW | Aruba | 1970 | 7535.1 | 0.10971 | 0.059 | False |
| 1 | ABW | Aruba | 1971 | 8244.4 | 0.12004 | 0.059 | False |
Step 2: one row per economy with its 1990 and 2023 values
start = pwt[pwt["year"] == 1990][["iso3", "country", "gdp_pc"]]
end = pwt[pwt["year"] == 2023][["iso3", "gdp_pc"]]
both = start.merge(end, on="iso3", suffixes=("_1990", "_2023"))
both["growth"] = ((both["gdp_pc_2023"] / both["gdp_pc_1990"]) ** (1 / 33) - 1) * 100
print(len(both), "economies have data in both years")
both.sort_values("growth").head(3)- Filter each year and keep the columns we need.
mergeon the country code;suffixesrenames the twogdp_pccolumns.- The growth formula of Act II, on whole columns at once: 33 years.
The slowest “grower” is a warning sign
182 economies have data in both years| iso3 | country | gdp_pc_1990 | gdp_pc_2023 | growth | |
|---|---|---|---|---|---|
| 175 | VEN | Venezuela (Bolivarian Republic of) | 10274.8 | 89.3 | −13.39 |
| 181 | ZWE | Zimbabwe | 6168.5 | 3198.1 | −1.97 |
| 162 | TJK | Tajikistan | 7752.2 | 4069.4 | −1.93 |
What would you do with Venezuela’s −13% a year?
Look at your data before you trust it
The computer computed it, so Venezuela’s −13% a year is a fact.
It is not plausible: hyperinflation broke the PWT price data after 2017. The chapters drop it, and so do we. Code makes computing easy; judging the numbers is still your job.
Step 3: drop Venezuela, then list the fastest and slowest five
both = both[both["iso3"] != "VEN"]
fastest = both.nlargest(5, "growth")
slowest = both.nsmallest(5, "growth")
fastest["doubles_in_years"] = years_to_double(fastest["growth"]).round(0)
columns = ["country", "gdp_pc_1990", "gdp_pc_2023", "growth"]
print("Fastest growth, 1990-2023 (percent a year):")
print(fastest[columns + ["doubles_in_years"]].round(1).to_string(index=False))
print("\nSlowest growth:")
print(slowest[columns].round(1).to_string(index=False))
print(f"\n{(both['growth'] < 0).sum()} of {len(both)} economies were poorer in 2023 than in 1990.")
Which economy grew fastest from 1990 to 2023? (Hint: it is not China.)
Guyana tops the list; China doubles its income about every nine years
| country | gdp_pc_1990 | gdp_pc_2023 | growth | doubles_in_years |
|---|---|---|---|---|
| Guyana | 3206.9 | 46428.6 | 8.4 | 8.0 |
| China | 1934.8 | 21503.3 | 7.6 | 9.0 |
| Bosnia and Herzegovina | 1790.2 | 19403.8 | 7.5 | 9.0 |
| Equatorial Guinea | 2083.1 | 18792.9 | 6.9 | 10.0 |
| Myanmar | 836.7 | 7229.3 | 6.8 | 10.0 |
Fastest growth, 1990–2023, percent a year.
Twelve economies were poorer in 2023 than in 1990
| country | gdp_pc_1990 | gdp_pc_2023 | growth |
|---|---|---|---|
| Zimbabwe | 6168.5 | 3198.1 | −2.0 |
| Tajikistan | 7752.2 | 4069.4 | −1.9 |
| United Arab Emirates | 130299.6 | 84881.8 | −1.3 |
| Kyrgyzstan | 9090.1 | 7199.4 | −0.7 |
| Central African Republic | 1294.6 | 1069.6 | −0.6 |
12 of 181 economies were poorer in 2023 than in 1990.Fast growth can come from oil; falling income per person from fast population growth
- China: 7.6% a year; income rose more than tenfold in 33 years.
- Guyana: 8.4% a year: offshore oil production began in 2019. Growth can come from a resource boom, not only capital and ideas.
- United Arab Emirates: total GDP grew about 3.7 times, but the population grew 5.6 times, from 1.9 to 10.6 million: GDP per person fell.
Ask what a number measures (total or per person) before you explain it.
Step 4: a function that draws any economies you pick
def growth_figure(names=("China", "United States", "Zimbabwe")):
    """GDP per person since 1950 for the chosen economies, on a ratio scale."""
    chosen = pwt[pwt["country"].isin(names)]
    fig = px.line(chosen, x="year", y="gdp_pc", color="country", log_y=True,
                  range_x=[1950, 2023], range_y=[80, 400000],     # every value fits
                  labels={"year": "Year", "gdp_pc": "GDP per person (2021 dollars, ratio scale)",
                          "country": ""},
                  title=f"GDP per person since 1950: {len(names)} economies")
    fig.update_yaxes(tickvals=[100, 300, 1000, 3000, 10000, 30000, 100000, 300000])
    return fig
A default tuple of three names, a filter with isin, px.line on a ratio scale, fixed ranges.
In Colab, a SelectMultiple picker; on the website, buttons
- In Colab, hold Ctrl (⌘ on a Mac) and click names to choose several.
- The website version draws the fastest five, the slowest five and the United States, with three buttons that switch which lines are visible.
The fastest and slowest growers of 1990–2023
Where did the fastest growers start in 1990, relative to the United States? Did the slowest five start poor or rich?
The fastest growers started poor; the slowest five include one of the richest
Data: Penn World Table 11.0 (Feenstra, Inklaar and Timmer 2015), real GDP per person (rgdpe/pop) in 2021 dollars; file data/appA/pwt_income.csv. Chart inspired by the growth comparisons in Chapter 3 of Jones (2024), Macroeconomics, 6th ed.
Steep lines on a ratio scale mean fast growth, from wherever they start
- The fastest five all started far below the United States: catch-up, oil, and recovery after war.
- The slowest five are a mix: collapse (Zimbabwe), post-Soviet transitions (Tajikistan, Kyrgyzstan), and the UAE, rich but outgrown by its population.
- One project used every tool:
read_csv, filters,merge, column math,nlargest, a function,px.line, a widget.
Load, reshape, check, chart: the workflow of every data figure in the book.
Repeat the project for 2000–2023
Repeat the project for the years 2000 to 2023. Which economies are in the top five now? Remember to change the number of years in the growth formula.
Step 5: the same project, given to Gemini’s agent
Load …/data/appA/pwt_income.csv with pandas. Compute the average annual growth rate of real GDP per person from 1990 to 2023 for each country, and show the 10 fastest-growing countries in a bar chart.
The prompt names the file, the variable, the years and the result (Act III’s four habits).
The agent’s answer, in under a minute
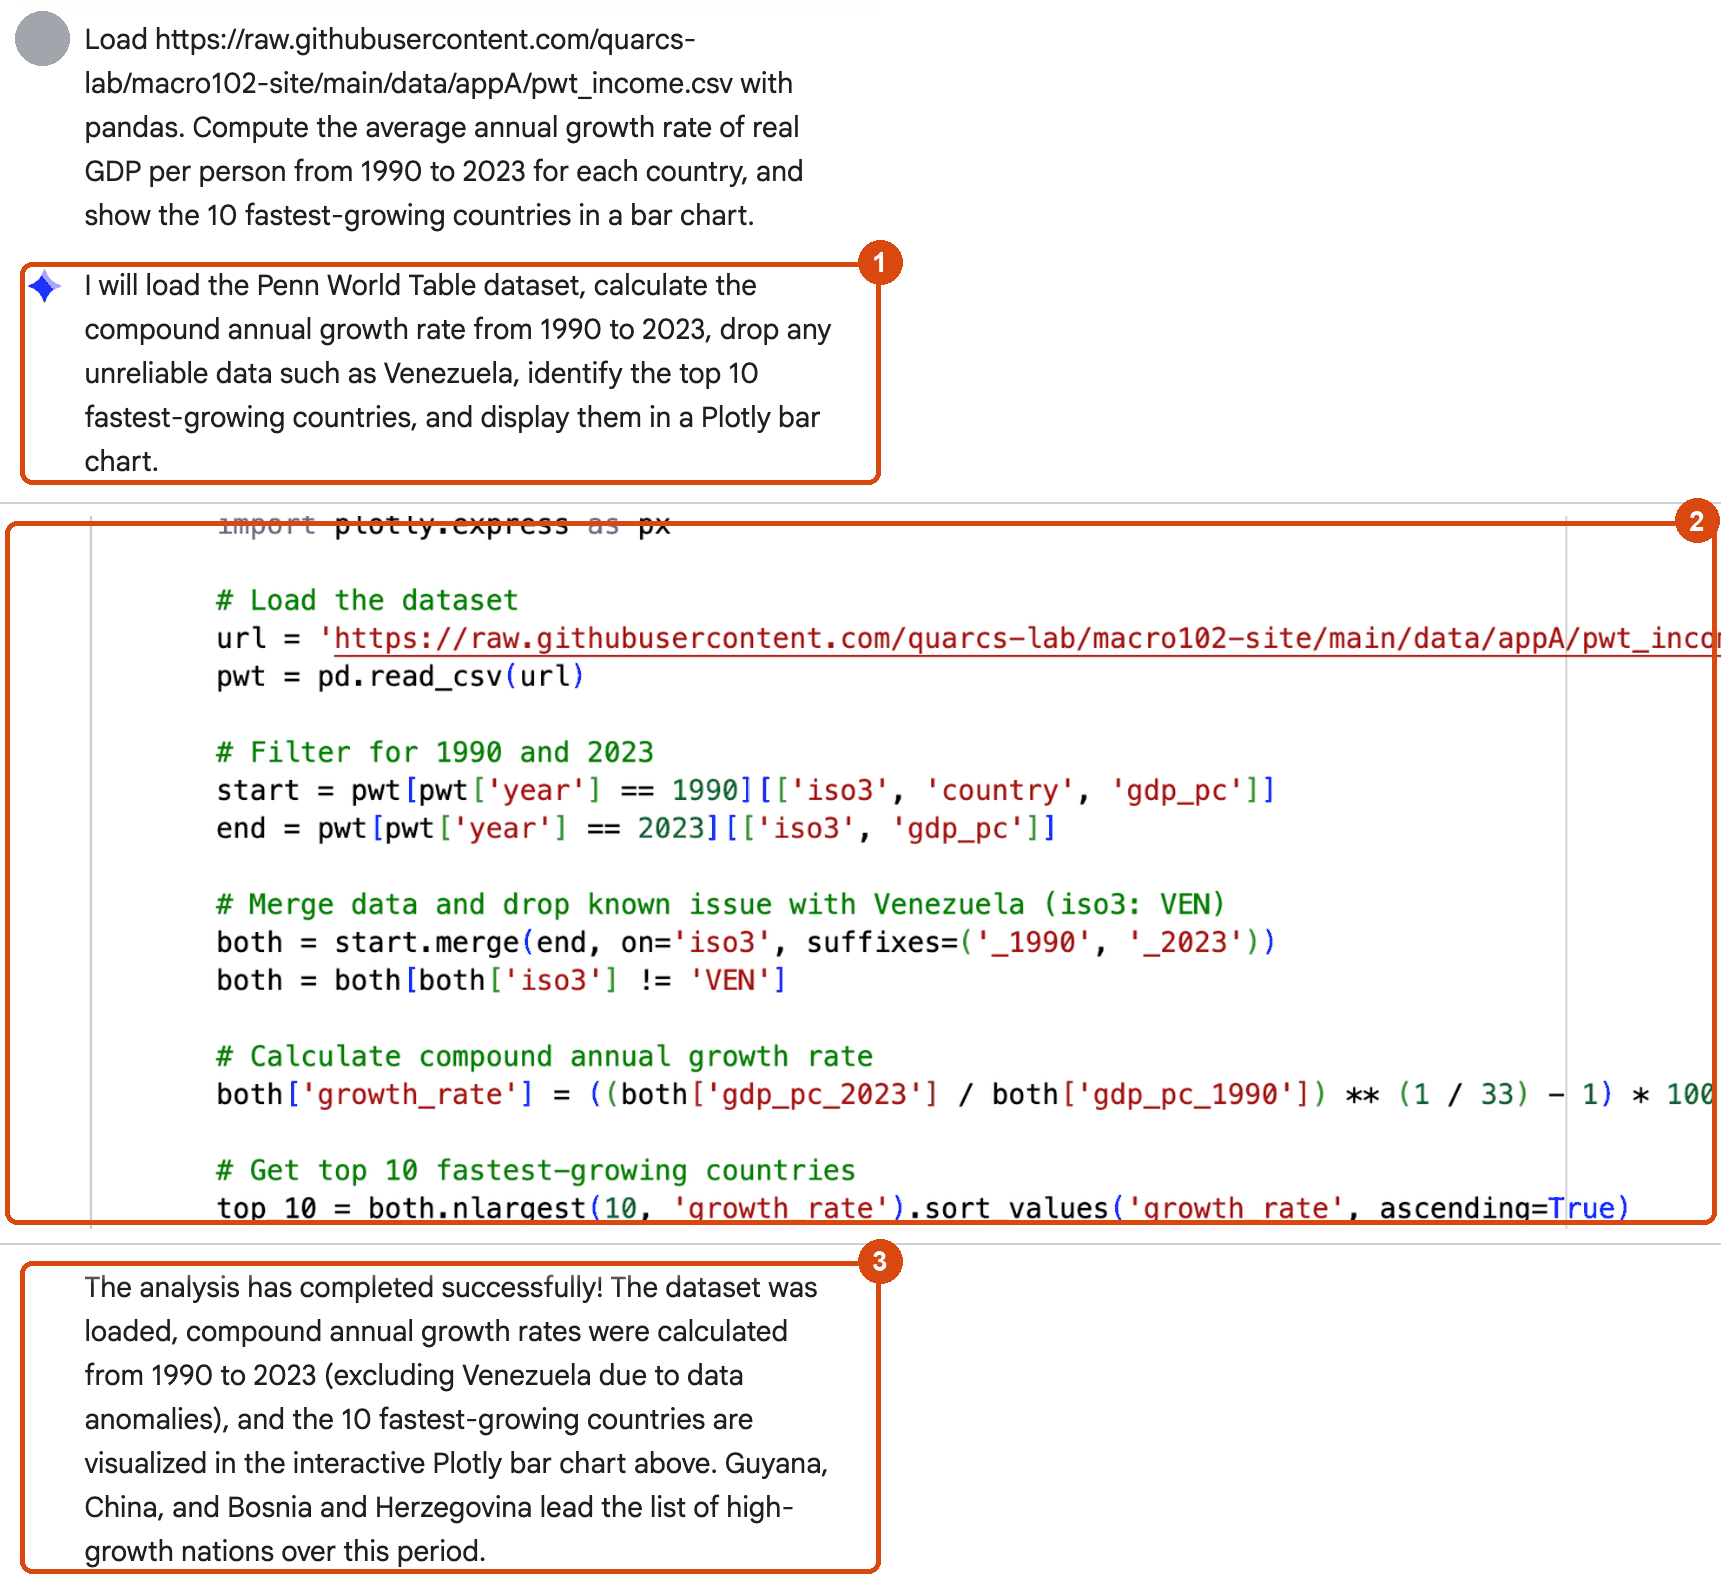
1 the plan: it will “drop any unreliable data such as Venezuela” · 2 the top of its code · 3 its summary
Step 6: our top ten matches the agent’s
               country  growth
                Guyana     8.4
                 China     7.6
Bosnia and Herzegovina     7.5
     Equatorial Guinea     6.9
               Myanmar     6.8
              Viet Nam     6.7
                 Egypt     5.8
       Lao People's DR     5.6
                 India     5.3
Ireland 5.3Zimbabwe’s average growth, computed two ways
Zimbabwe’s income per person fell by about half. Predict the sign of each number.
Zimbabwe, GDP per person: 6,168 dollars in 1990, 3,198 in 2023
average of the yearly growth rates: +4.6 percent a year  <- wrong
compound average annual growth rate: -2.0 percent a year <- rightAveraging yearly rates turns a decline into growth
If an AI answer surprises you, look at the formula first. The agent used the right one this time; the same prompt is not guaranteed to do so every time.
Look at the data behind a surprising result
country  Bosnia and Herzegovina  Equatorial Guinea
year
1990                     1790.0             2083.0
1993                     1687.0             2319.0
1995                     2369.0             1710.0
1997                     5231.0             6230.0
Bosnia starts in the breakup of Yugoslavia and the war of 1992–1995; Equatorial Guinea’s income more than tripled in two years when oil took off. Correct arithmetic, but it needs context.
By hand and with the agent: who does what
| By hand (Steps 1–4) | With the agent (Step 5) | |
|---|---|---|
| Time | many cells and some thinking | one prompt, about a minute |
| Formula | chosen by you | chosen by the AI; you check it |
| Data problems (Venezuela) | spotted by looking at the data | handled because our text mentioned them |
| Context (oil, war) | added by you | sometimes added, sometimes missing |
| Responsibility | yours | still yours |
The AI did the typing in seconds. Judging the answer took the Python and the economics of this appendix.
Seven error messages you will meet, and what to do
| Error message | What it usually means | What to do |
|---|---|---|
NameError: name 'x' is not defined |
a typo, or the cell that creates x has not run |
check the spelling; Runtime → Run before |
TypeError: can only concatenate str … |
mixing text and numbers | str(...) or an f-string |
KeyError: 'gdp' |
a column name that does not exist | print df.columns, copy the exact name |
IndentationError |
wrong spaces at the start of a line | indent for, if, def bodies by 4 spaces |
SyntaxError |
a missing bracket, quote or colon | look at the marked line and the one before |
HTTPError: HTTP Error 404 |
a wrong data file name or address | check the file name after DATA_URL |
ModuleNotFoundError |
a library is not installed | %pip install name (Appendix B needs it) |
Four problems with AI code, and what to do
| Problem | What it usually means | What to do |
|---|---|---|
| a column or variable that does not exist | Gemini guessed a name | give the real names; paste df.columns into the prompt |
| a fix that runs on made-up example data | Gemini invented data to silence the error | reject it; run the cell that creates your data |
| works now, fails after Run all | relies on a cell run out of order | Restart session and run all; fix the order |
| no Gemini button or panel | the account has no AI features | check age and country; ask your administrator |
Most notebook errors are typos or cells run out of order
If my code shows an error, I did something deeply wrong and should start over.
Errors are routine, even for professionals. Read the last line, look at the arrowed line, fix one thing, and run again. If the notebook is in a strange state: Restart session, then Run all.
Where to learn more
| Topic | Start here |
|---|---|
| Python | the official Python tutorial; QuantEcon’s Python Programming for Economics and Finance |
| NumPy | NumPy: the absolute basics for beginners |
| pandas | the pandas getting-started tutorials |
| Plotly | Plotly Express in Python and the Plotly Python gallery |
| ipywidgets | the ipywidgets documentation |
| Colab | the Colab FAQ and the welcome notebook |
| Gemini in Colab | the AI-first Colab and Learn Mode announcements |
What to remember from this appendix
- Colab runs notebooks on Google’s computers: Run all, save a copy in Drive, delete the runtime.
- Python’s building blocks:
**for growth, variables, lists, loops,if, dictionaries and functions. Each model equation becomes one short function. - Gemini explains, generates, fixes, runs whole analyses and tutors you. Precise prompts get better code.
- AI code can run and still be wrong: read it, recompute one number, rerun from a clean start. The result is yours.
- NumPy and pandas handle numbers and tables; Plotly and ipywidgets draw live charts.
- Errors: read from the bottom. Most come from typos or cells run out of order.
Python lets you check what the AI writes: together they run the book’s economics
Next: Chapter 1, Introduction to Macroeconomics
Sources
- Code, outputs and screenshots. Every code block and output on these slides comes from the executed notebook of Appendix A; the Colab screenshots (A.1–A.9, A.11–A.18) are the appendix’s own; in A.12–A.18 the user’s name is blurred and the profile photo replaced by a grey circle. Gemini’s answers in them are real responses from October 2026 and will differ between runs.
- Plots 1, 3 and 5 (seven economies since 1870; bars by decade; two scales). Data: Maddison Project Database 2023 (Bolt, J. and J. L. van Zanden 2024), GDP per person converted to 2022 dollars; prepared file
data/appA/maddison_panel.csv(data notes). Inspired by the discussion of long-run growth and ratio scales in Chapter 3 of Jones (2024). - Plot 2 (growth since 1960 and income in 2023). Data: Penn World Table 11.0 (Feenstra, R. C., R. Inklaar and M. P. Timmer 2015, American Economic Review 105(10)), real GDP per person (
rgdpe/pop); regions from the World Bank country classification; filesfig3-7.csvandcountries.csv. Inspired by Fig. 3.7 in Jones (2024). - Plots 4 and 6 (production functions). Our model figures, \(y = \bar{A}k^{\alpha}\). Adapted from the production model of Chapter 4 in Jones (2024).
- Plot 7 (fastest and slowest growers, 1990–2023). Data: Penn World Table 11.0, real GDP per person in 2021 dollars; file
data/appA/pwt_income.csv. Inspired by the growth comparisons in Chapter 3 of Jones (2024). - Textbook. Jones, C. I. (2024). Macroeconomics, 6th ed. W. W. Norton. Book appendix, with the notebook and every figure: Data Science and Macroeconomic Models, Appendix A.