# Libraries used in this appendix
import math                                     # math on single numbers
import numpy as np                              # numbers and arrays
import pandas as pd                             # data tables
import plotly.express as px                     # quick charts from data tables
import plotly.graph_objects as go               # charts built piece by piece
import plotly.io as pio
import sympy as sp                              # symbolic math: algebra and calculus with letters
from scipy import optimize, integrate           # numerical solvers, optimizers and differential equations
from ipywidgets import interact, FloatSlider

# One light blue/green look for every chart
BLUE, TEAL, GREEN, GRAY, ORANGE = "#16528c", "#008070", "#7fb23a", "#8a96a3", "#c4651a"
pio.templates.default = "plotly_white"
pio.templates["plotly_white"].layout.update(width=860, height=480)   # same size in Colab and on the website
px.defaults.color_discrete_sequence = [BLUE, TEAL, GREEN, ORANGE, "#8e5ea2", "#5aa0d8", "#0b4f47"]
WIDE = {"description_width": "initial"}         # show the full widget labels

# Colab only: let Plotly charts appear inside the interactive widgets
try:
    import google.colab
    google.colab.output.enable_custom_widget_manager()
except ImportError:
    pass                                        # not running in Colab: nothing to do

# The data files of this appendix live in the book's GitHub repository
DATA_URL = "https://raw.githubusercontent.com/quarcs-lab/macro102-site/main/data/appC/"C. Math Review for Macroeconomics
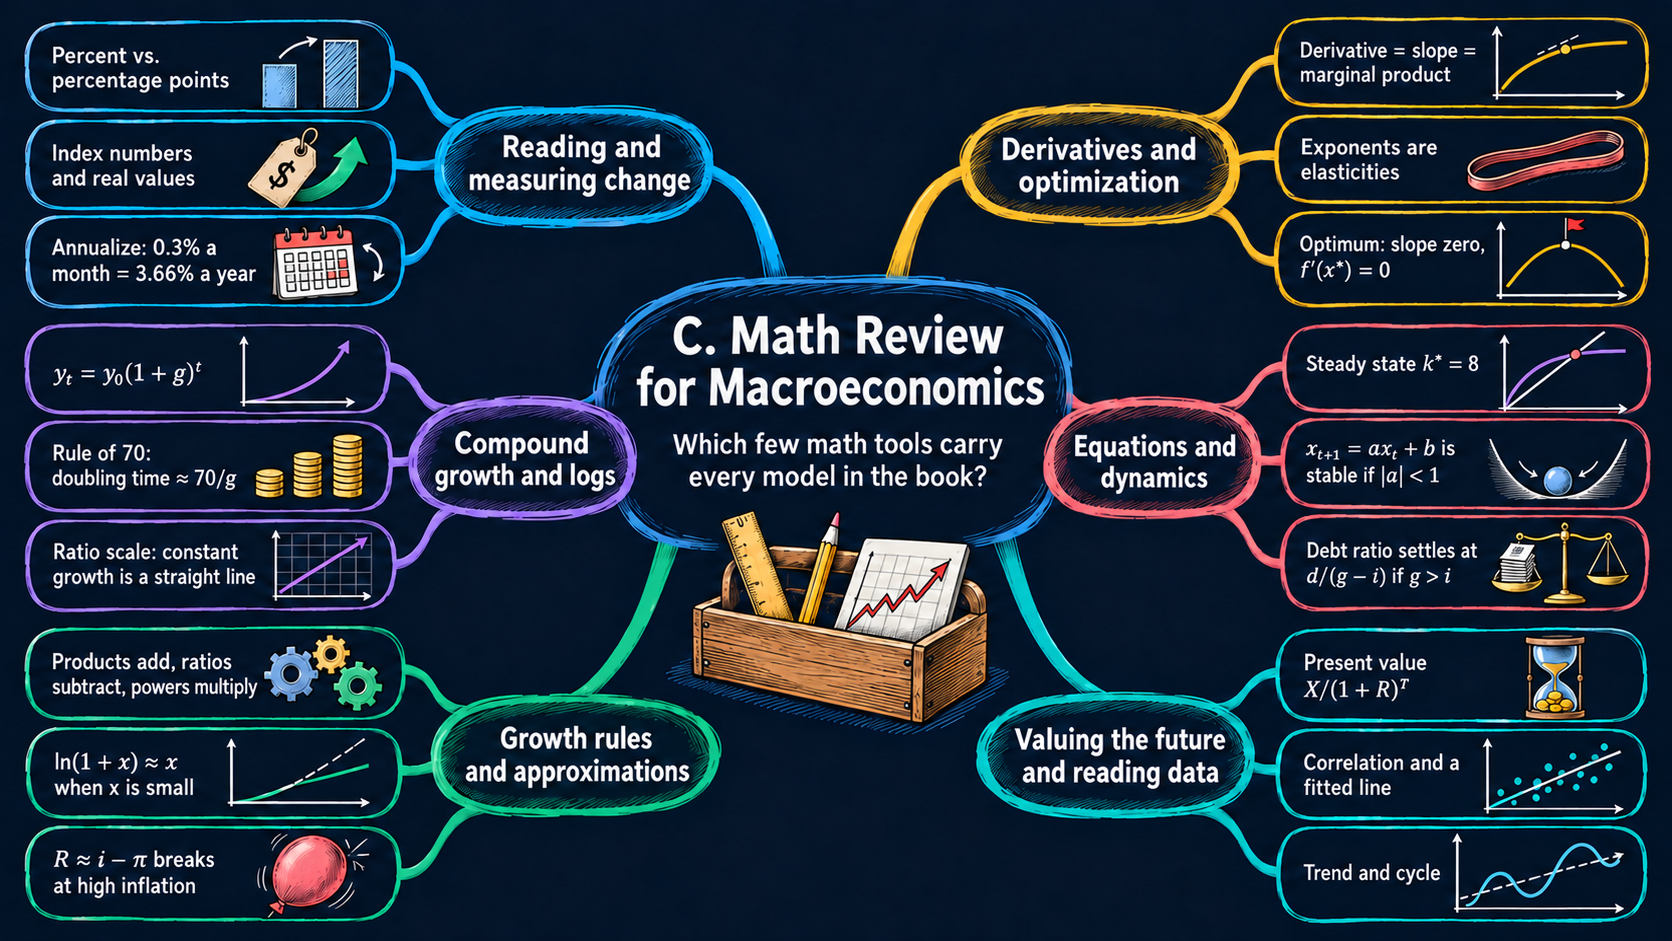


Learning goals
You do not need much math to understand macroeconomics, but you do need to be comfortable with a few tools. By the end of this appendix you will be able to:
- work with percentages, ratios and index numbers, and tell a percent change from a change in percentage points;
- use exponents and logarithms to describe compound growth, read a ratio scale and apply the Rule of 70;
- compute growth rates three ways, apply the growth rules for products, ratios and powers, and know when an approximation such as \(i \approx R + \pi\) is good enough;
- use derivatives for marginal products, elasticities and optimization, and solve equations and systems of equations;
- simulate difference equations (how capital, unemployment, inflation and public debt move over time), value future payments with present value, and separate the trend of a series from its cycle;
- do all of this in Python, with NumPy for numbers, SymPy for algebra and calculus with letters, and SciPy for numerical solvers.
A map of the tools
| Tool | The question it answers | Where the book uses it | Section |
|---|---|---|---|
| Notation and functions | How do I read an equation such as \(\tilde{Y}_t=\bar{a}-\bar{b}(R_t-\bar{r})\)? | every chapter | C.1 |
| Percentages, ratios, index numbers | How much did prices rise? What is real GDP? | Chapters 2, 8, 18 | C.2 |
| Exponents and exponential growth | How much richer is a country after 50 years of 2 percent growth? | Chapters 3, 5, 6 | C.3 |
| Logarithms and the ratio scale | Why do economists plot GDP on a log scale? | Chapters 3, 5, 6, 8 | C.4 |
| Growth rates and growth rules | How fast does \(Y=AK^{1/3}L^{2/3}\) grow? | Chapters 3, 4, 6, 8 | C.5 |
| Approximations | When is \(R \approx i - \pi\) good enough? | Chapters 3, 8, 9, 12 | C.6 |
| Derivatives | What is the marginal product of capital? | Chapters 4, 5, 16, 17 | C.7 |
| Optimization | How many workers does a firm hire? How much does a household consume? | Chapters 4, 16 | C.8 |
| Equations and systems | Where is the steady state? Where do the IS, MP and AS curves meet? | Chapters 5, 7, 11–13 | C.9 |
| Difference equations | How do capital, unemployment, inflation and debt move over time? | Chapters 5, 6, 7, 12, 13, 18 | C.10 |
| Continuous time | What does \(\dot{k}\) mean in more advanced books? | Chapter 15 and beyond | C.11 |
| Present value | What is a stream of future payments worth today? | Chapters 7, 14, 16, 17, 18 | C.12 |
| Describing data | How volatile is growth? What is the trend, and what is the cycle? | Chapters 2, 9, 12, 13 | C.13 |
Setup
The setup cell loads the libraries and sets the look of the charts. Two libraries are new compared with the chapters. SymPy does math with letters, as you would on paper: it simplifies, solves and differentiates formulas. SciPy holds numerical methods: it finds the number that solves an equation, the point where a function is highest, or the path of a differential equation. Both come with Colab, so there is nothing to install.
Show the helper code
# @title Helper for the website versions (run this cell; you do not need to read it)
def slider_figure(make_figure, name, values, start, label=None):
    """Precompute make_figure(name=value) for every value and join the results with one slider.

    The website cannot run Python, so each interactive figure also gets this precomputed version.
    """
    figures = [make_figure(**{name: v}) for v in values]
    first = values.index(start)
    fig = go.Figure(layout=figures[first].layout)
    owner = []                                  # which precomputed figure each trace comes from
    for i, f in enumerate(figures):
        for trace in f.data:
            trace.visible = (i == first)
            fig.add_trace(trace)
            owner.append(i)
    steps = []
    for i, f in enumerate(figures):
        layout = {"title": f.layout.title.to_plotly_json(),
                  "annotations": [a.to_plotly_json() for a in f.layout.annotations],
                  "shapes": [s.to_plotly_json() for s in f.layout.shapes]}
        visible = [o == i for o in owner]
        steps.append(dict(method="update", label=str(values[i]), args=[{"visible": visible}, layout]))
    fig.update_layout(sliders=[dict(active=first, steps=steps, pad=dict(t=60),
                                    currentvalue=dict(prefix=(label or name) + " = "))])
    return fig
Three ways to do math in Python
Here is a question from Chapter 3: if income grows by 2 percent a year, after how many years has it doubled? In symbols, we want the \(t\) that solves \((1+0.02)^t = 2\). Python can answer it in three ways, and each way is the right one in some situations.
1. NumPy: compute many numbers and look. We compute income for every year from 0 to 50 and find the first year in which it reaches 2.
Python note.
np.arange(0, 51)makes the whole numbers 0, 1, …, 50.1.02 ** yearsraises 1.02 to each of them at once.years[income >= 2]keeps only the years in which the condition is true (this is called boolean indexing), and[0]takes the first of them.
years = np.arange(0, 51)               # 0, 1, 2, ..., 50
income = 1.02 ** years                 # income in each year, starting from 1
first_year = years[income >= 2][0]     # the first year in which income is at least twice its start
print("Income is at least twice its start value in year", first_year)
Income is at least twice its start value in year 362. SymPy: solve with letters, then put in the number. SymPy treats \(g\) and \(t\) as letters and solves \((1+g)^t=2\) for \(t\), exactly as you would with pen and paper.
Python note.
sp.symbols("g t")creates two symbols, letters that SymPy can do algebra with.sp.Eq(left, right)writes an equation, andsp.solve(equation, t)returns a list of solutions;[0]takes the first one. When the last line of a cell is a SymPy formula, the notebook shows it as typeset math.
g, t = sp.symbols("g t")                         # two symbols
doubling_time = sp.solve(sp.Eq((1 + g) ** t, 2), t)[0]
doubling_time
\(\displaystyle \frac{\log{\left(2 \right)}}{\log{\left(g + 1 \right)}}\)
The answer is a formula: it holds for every growth rate. .subs(g, 0.02) puts in the number.
print(f"Exact doubling time at 2 percent: {float(doubling_time.subs(g, 0.02)):.2f} years")Exact doubling time at 2 percent: 35.00 years3. SciPy: let a numerical solver find the answer. Many equations in economics have no formula for their solution. A root finder searches for the number at which a function equals zero. optimize.brentq(f, low, high) needs a function f whose sign is different at low and high, and it narrows down the zero in between.
def doubling_gap(t):
    """How far income after t years of 2 percent growth is from twice its start."""
    return 1.02 ** t - 2

t_double = optimize.brentq(doubling_gap, 1, 100)    # search between 1 and 100 years
print(f"brentq finds {t_double:.2f} years")
brentq finds 35.00 years| Way | Library | Gives you | Use it when |
|---|---|---|---|
| Compute and look | NumPy | numbers for many cases at once | you want a table or a chart, or a quick check |
| Symbolic math | SymPy | exact formulas, derivatives, solutions with letters | you want to see why a result holds, or check the algebra of a chapter |
| Numerical solvers | SciPy | the number that solves, maximizes or simulates | there is no formula, or the formula is too messy |
All three agree: about 35 years. NumPy says “year 36” because it only looks at whole years.
C.1 Notation, functions and equations
Goal. Read the equations of the book with confidence, and let SymPy turn them into numbers and charts.
Economic models are written with a few conventions. Once you know them, an equation reads like a sentence.
| Symbol | Meaning | Example in the book |
|---|---|---|
| a bar, as in \(\bar{s}\) | a parameter: a value the model takes as given | the investment rate \(\bar{s}\) (Chapter 5) |
| a subscript \(t\), as in \(K_t\) | the value in period \(t\) (usually a year) | capital \(K_t\) |
| \(\Delta x_{t+1} \equiv x_{t+1}-x_t\) | the change from one period to the next | \(\Delta K_{t+1}\), equation (5.3) |
| \(g_x\) | the growth rate of \(x\) | \(g_Y\), equation (6.14) |
| a star, as in \(k^*\) | a steady state or equilibrium value | \(k^*\), equation (5.8) |
| a tilde, as in \(\tilde{Y}_t\) | short-run output: the percent gap between GDP and potential GDP | equation (9.2) |
| \(\equiv\) | “is defined as” | \(\tilde{Y}_t \equiv (Y_t-\bar{Y}_t)/\bar{Y}_t\) |
| \(\pi\) | the inflation rate (not 3.14159…) | Chapter 8 |
| \(\sum_{t=0}^{T}\) | the sum over periods 0 to \(T\) | present values, Chapter 7 |
A function links an input to an output. The IS curve of Chapter 11 is a function: it says how short-run output \(\tilde{Y}_t\) (in percent) depends on the real interest rate \(R_t\) (also in percent):
\[\tilde{Y}_t=\bar{a}-\bar{b}\,(R_t-\bar{r}). \qquad (11.14)\]
Here \(\bar{a}\) is an aggregate demand shock, \(\bar{b}\) says how strongly spending reacts to the interest rate, and \(\bar{r}\) is the long-run real interest rate. Let us write it in SymPy and ask: which interest rate brings output back to potential (\(\tilde{Y}_t=0\))?
Python note. SymPy shows a symbol named
"abar"as \(\bar{a}\) and"Ytilde"as \(\tilde{Y}\)..subs(...)substitutes: it replaces a symbol with a number or another formula. A dictionary such as{abar: 1}replaces several symbols at once.
Y_tilde, R, abar, bbar, rbar = sp.symbols("Ytilde R abar bbar rbar")
IS = sp.Eq(Y_tilde, abar - bbar * (R - rbar))     # equation (11.14)
IS
\(\displaystyle \tilde{Y} = \bar{a} - \bar{b} \left(R - \bar{r}\right)\)
R_closes_gap = sp.solve(IS.subs(Y_tilde, 0), R)[0]   # set output to potential and solve for R
R_closes_gap
\(\displaystyle \frac{\bar{a}}{\bar{b}} + \bar{r}\)
The formula says: raise the interest rate above \(\bar{r}\) by \(\bar{a}/\bar{b}\). With a positive demand shock of \(\bar{a}=1\) percent, \(\bar{b}=0.5\) and \(\bar{r}=2\) percent (our own illustrative numbers):
IS_values = {abar: 1, bbar: 0.5, rbar: 2}
print(f"Real interest rate that closes the gap: {float(R_closes_gap.subs(IS_values)):.1f} percent")
Real interest rate that closes the gap: 4.0 percentsp.lambdify turns a SymPy formula into an ordinary Python function that works on NumPy arrays. That is how we go from algebra to a chart.
IS_formula = sp.solve(IS, Y_tilde)[0].subs(IS_values)    # output as a formula of R
IS_function = sp.lambdify(R, IS_formula)                 # now a Python function of R
R_grid = np.linspace(0, 8, 81)
is_fig = go.Figure()
is_fig.add_trace(go.Scatter(x=IS_function(R_grid), y=R_grid, mode="lines", name="IS curve",
                            line=dict(color=BLUE, width=3)))
is_fig.add_trace(go.Scatter(x=[0], y=[float(R_closes_gap.subs(IS_values))], mode="markers", name="output at potential",
                            marker=dict(color=TEAL, size=12)))
is_fig.add_trace(go.Scatter(x=[1], y=[2], mode="markers", name="R at its long-run value",
                            marker=dict(color=GRAY, size=12)))
is_fig.update_layout(title="With a demand shock of 1 percent, a real rate of 4 percent closes the gap",
                     xaxis=dict(title="short-run output, Ỹ (percent)", range=[-3, 3], tickvals=[-2, -1, 0, 1, 2, 3]),
                     yaxis=dict(title="real interest rate, R (percent)", range=[0, 8]),
                     legend=dict(x=0.99, xanchor="right", y=0.98))
is_fig
Source. Illustration of the IS curve, equation (11.14) in Jones (2024), Macroeconomics, 6th ed.
What to notice.
- The book draws the IS curve with output on the horizontal axis and the interest rate on the vertical axis, so we plot
x=IS_function(R_grid), y=R_grid. - SymPy gave the general answer \(\bar{r}+\bar{a}/\bar{b}\); the numbers came last. Working with letters first shows which parameters matter.
Your turn. Suppose spending reacts twice as strongly to the interest rate (\(\bar{b}=1\)). Which real interest rate now closes the gap? Answer with R_closes_gap.subs(...).
Hint
Copy IS_values, change bbar to 1, and substitute the new dictionary. A larger \(\bar{b}\) means a smaller rise in \(R\) is enough.
# Your turn: try it hereC.2 Percentages, ratios and index numbers
Goal. Compute percent changes, rebase an index, turn nominal values into real ones, and annualize monthly or quarterly changes.
The percent change of a variable from \(x_0\) to \(x_1\) is \(100 \times (x_1-x_0)/x_0\). Be careful with rates that are already in percent, such as the unemployment rate. When it rises from 4 to 5 percent, it rises by 1 percentage point, but by 25 percent.
u_before, u_after = 4.0, 5.0           # unemployment rate, percent
print("Change:", u_after - u_before, "percentage point")
print("Change:", 100 * (u_after - u_before) / u_before, "percent")
Change: 1.0 percentage point
Change: 25.0 percentA ratio divides one variable by another, often to remove the size of the economy. Public debt of 30 trillion dollars means little on its own; debt of 100 percent of GDP is easy to compare over time and across countries (Chapter 18).
Index numbers and inflation
A price index measures the price level relative to a base period. The U.S. consumer price index (CPI) has the base 1982–84 = 100. To rebase it to another year, divide by the value in that year and multiply by 100.
cpi = pd.read_csv(DATA_URL + "us_cpi.csv")
cpi_2025 = cpi.loc[cpi["year"] == 2025, "cpi"].iloc[0]
cpi["cpi_2025"] = 100 * cpi["cpi"] / cpi_2025           # now 2025 = 100
cpi["inflation"] = 100 * cpi["cpi"].pct_change()        # percent change from the year before
cpi.tail()| year | cpi | cpi_2025 | inflation | |
|---|---|---|---|---|
| 247 | 2021 | 270.97 | 84.167857 | 4.698427 |
| 248 | 2022 | 292.66 | 90.905138 | 8.004576 |
| 249 | 2023 | 304.70 | 94.644965 | 4.113989 |
| 250 | 2024 | 313.69 | 97.437411 | 2.950443 |
| 251 | 2025 | 321.94 | 100.000000 | 2.629985 |
Python note.
.loc[condition, "column"]selects the rows where the condition is true, and.iloc[0]takes the first value..pct_change()computes \((x_t - x_{t-1})/x_{t-1}\) for every row; the first row has no year before it, so it getsNaN(“not a number”).
The rebased index answers questions such as “what would 100 dollars of 1913 buy today?”
cpi_1913 = cpi.loc[cpi["year"] == 1913, "cpi"].iloc[0]
print(f"100 dollars of 1913 buy as much as {100 * cpi_2025 / cpi_1913:,.0f} dollars of 2025")
print(f"The 1913 price level, with 2025 = 100: {cpi.loc[cpi['year'] == 1913, 'cpi_2025'].iloc[0]:.1f}")
100 dollars of 1913 buy as much as 3,354 dollars of 2025
The 1913 price level, with 2025 = 100: 3.0modern = cpi[cpi["year"] >= 1914]
peak = modern.loc[modern["inflation"].idxmax()]
low = modern.loc[modern["inflation"].idxmin()]
inflation_fig = px.line(modern, x="year", y="inflation",
labels={"year": "", "inflation": "CPI inflation (percent)"},
title=f"U.S. inflation since 1914: a high of {peak['inflation']:.1f}% in {peak['year']:.0f} "
f"and a low of {low['inflation']:.1f}% in {low['year']:.0f}")
inflation_fig.add_hline(y=0, line_color=GRAY, line_width=1)
inflation_figSources. Data: MeasuringWorth, Officer and Williamson, The Annual Consumer Price Index for the United States, 1774–Present. Prepared file: data/appC/us_cpi.csv (see the data notes). Chart: inspired by Fig. 8.1 in Jones (2024), Macroeconomics, 6th ed.
Nominal and real values
Nominal GDP is measured at current prices; real GDP at the prices of a base year. Their ratio is the GDP deflator, a price index for everything the economy produces (Chapter 2):
\[\text{deflator}_t = 100 \times \frac{\text{nominal GDP}_t}{\text{real GDP}_t}.\]
nipa = pd.read_csv(DATA_URL + "nipa_annual.csv", usecols=["year", "gdp", "real_gdp", "population"])
nipa["deflator"] = 100 * nipa["gdp"] / nipa["real_gdp"]    # 2017 = 100, because real GDP is in 2017 dollars
nipa[nipa["year"].isin([1929, 1970, 2017, 2025])].round(1)| year | gdp | real_gdp | population | deflator | |
|---|---|---|---|---|---|
| 0 | 1929 | 104.6 | 1191.1 | 121878 | 8.8 |
| 41 | 1970 | 1073.3 | 5316.4 | 205089 | 20.2 |
| 88 | 2017 | 19612.1 | 19612.1 | 326860 | 100.0 |
| 96 | 2025 | 30861.3 | 23943.3 | 341944 | 128.9 |
Annualizing
Monthly and quarterly changes are usually reported at an annual rate: the change that would result if the same monthly (or quarterly) change went on for a whole year. Because changes compound, a monthly change \(m\) becomes \((1+m)^{12}-1\) a year, which is a bit more than \(12 \times m\).
monthly = 0.3                                          # prices rise 0.3 percent in one month
annual = 100 * ((1 + monthly / 100) ** 12 - 1)
print(f"{monthly}% a month is {annual:.2f}% at an annual rate (12 x {monthly} = {12 * monthly:.1f})")
quarterly = 0.5                                        # real GDP grows 0.5 percent in one quarter
print(f"{quarterly}% a quarter is {100 * ((1 + quarterly / 100) ** 4 - 1):.2f}% at an annual rate")
0.3% a month is 3.66% at an annual rate (12 x 0.3 = 3.6)
0.5% a quarter is 2.02% at an annual rateWhat to notice.
- The chart shows the deflation of 1921 and of the early 1930s, and the bursts of inflation around 1917–1920, in 1947, around 1980 and in 2022.
- Rebasing changes the levels of an index but not its percent changes: inflation is the same whatever the base year.
- The deflator in 2017 equals 100 because the real GDP series is measured in 2017 dollars.
Your turn. How much would 100 dollars of 1980 buy in 2025? And by how many percent did the GDP deflator rise from 2019 to 2025?
Hint
Use cpi.loc[cpi["year"] == 1980, "cpi"].iloc[0] like the 1913 example. For the deflator, select the two years from nipa the same way and apply the percent-change formula.
# Your turn: try it hereC.3 Exponents and exponential growth
Goal. See how compound growth works, and why small differences in growth rates become large differences in income.
An exponent says how many times a number is multiplied by itself: \(x^3 = x \cdot x \cdot x\). The rules you need are few:
| Rule | Example |
|---|---|
| \(x^a \cdot x^b = x^{a+b}\) | \(K^{1/3}K^{2/3}=K\) |
| \((x^a)^b = x^{ab}\) | \((k^{1/3})^{3/2}=k^{1/2}\) |
| \(x^{-a}=1/x^a\) | \(K^{-2/3}=1/K^{2/3}\) |
| \(x^{1/n}=\sqrt[n]{x}\) | \(k^{1/3}\) is the cube root of \(k\) |
| \((xy)^a=x^a y^a\) | \((AK)^{1/3}=A^{1/3}K^{1/3}\) |
If income per person grows at a constant rate \(\bar{g}\) each year, then after one year it is \(y_0(1+\bar{g})\), after two years \(y_0(1+\bar{g})^2\), and after \(t\) years
\[y_t=y_0\,(1+\bar{g})^t. \qquad (3.7)\]
This is exponential growth: income grows by the same percent each year, so it grows by more and more dollars.
def income_path(g, years):
    """Equation (3.7): income y_t = (1 + g)^t for t = 0, ..., years, with g in percent and y_0 = 1."""
    t = np.arange(0, years + 1)
    return (1 + g / 100) ** t

for rate in [1, 2, 3]:
    print(f"{rate}% a year for 100 years multiplies income by {income_path(rate, 100)[-1]:.1f}")
1% a year for 100 years multiplies income by 2.7
2% a year for 100 years multiplies income by 7.2
3% a year for 100 years multiplies income by 19.2In more advanced work, growth is often written in continuous time: \(y_t=y_0e^{gt}\), where \(e \approx 2.718\) is Euler’s number. For small growth rates the two versions are close (Section C.6 explains why).
print(f"(1.02)^100 = {1.02 ** 100:.2f} versus e^(0.02 x 100) = {math.exp(0.02 * 100):.2f}")(1.02)^100 = 7.24 versus e^(0.02 x 100) = 7.39The Rule of 70
Income doubles when \((1+\bar{g})^t=2\). Section “Three ways” solved this for \(t\): \(t=\ln 2/\ln(1+\bar{g})\). The Rule of 70 of Chapter 3 says \(t \approx 70/g\), with \(g\) in percent. How good is it?
rule_rates = np.array([0.5, 1, 2, 3, 5, 7, 10, 20])
rule_table = pd.DataFrame({"growth rate (%)": rule_rates,
                           "exact doubling time (years)": np.log(2) / np.log(1 + rule_rates / 100),
                           "Rule of 70": 70 / rule_rates})
rule_table.round(1)| growth rate (%) | exact doubling time (years) | Rule of 70 | |
|---|---|---|---|
| 0 | 0.5 | 139.0 | 140.0 |
| 1 | 1.0 | 69.7 | 70.0 |
| 2 | 2.0 | 35.0 | 35.0 |
| 3 | 3.0 | 23.4 | 23.3 |
| 4 | 5.0 | 14.2 | 14.0 |
| 5 | 7.0 | 10.2 | 10.0 |
| 6 | 10.0 | 7.3 | 7.0 |
| 7 | 20.0 | 3.8 | 3.5 |
The rule is excellent for the growth rates of GDP per person (1 to 5 percent) and still fair at 10 percent. At 20 percent it is off by a few months. Section C.6 shows where the 70 comes from.
Interactive: two economies, two growth rates
Two economies start with the same income. Move the sliders to change their growth rates and see the gap after 100 years.
def compounding_chart(g_a=1.0, g_b=3.0):
    """Two economies that start equal and grow at constant rates, equation (3.7)."""
    t = np.arange(0, 101)
    path_a, path_b = income_path(g_a, 100), income_path(g_b, 100)
    fig = go.Figure()
    fig.add_trace(go.Scatter(x=t, y=path_a, mode="lines", name=f"{g_a:.2f}% a year", line=dict(color=BLUE, width=3)))
    fig.add_trace(go.Scatter(x=t, y=path_b, mode="lines", name=f"{g_b:.2f}% a year", line=dict(color=TEAL, width=3)))
    fig.update_layout(title=f"After 100 years: {path_a[-1]:.1f} times versus {path_b[-1]:.1f} times the starting income",
                      xaxis=dict(title="years", range=[0, 100]),
                      yaxis=dict(title="income (start = 1)", range=[0, 60], tickvals=[10, 20, 30, 40, 50, 60]),
                      legend=dict(x=0.02, y=0.98))
    return fig
interact(compounding_chart,
g_a=FloatSlider(value=1.0, min=0.0, max=4.0, step=0.25, description="growth rate A (%)", style=WIDE),
g_b=FloatSlider(value=3.0, min=0.0, max=4.0, step=0.25, description="growth rate B (%)", style=WIDE));Show the code of the website version
# @title Website version: the compounding chart with a precomputed slider for economy B's growth rate
slider_figure(compounding_chart, "g_b", [1.0, 1.5, 2.0, 2.5, 3.0, 3.5, 4.0], start=3.0,
              label="growth rate B (%)")
Source. Illustration of the constant-growth rule, equation (3.7) in Jones (2024), Macroeconomics, 6th ed.
What to notice.
- With 1 percent growth, income less than triples in a century. With 3 percent, it rises about 19 times.
- The faster economy pulls away more and more each year: the gap is itself growing exponentially.
Your turn. At 2 percent growth, how many years does it take for income to rise tenfold? Use optimize.brentq as in the “Three ways” section, then check your answer with logs: \(t=\ln 10/\ln 1.02\).
Hint
Write a function that returns 1.02 ** t - 10 and search between 1 and 300 years. The answer is a bit more than 100 years.
# Your turn: try it hereC.4 Logarithms
Goal. Use logarithms to undo exponents, to turn multiplication into addition, and to read charts on a ratio scale.
The natural logarithm \(\ln x\) is the power to which \(e\) must be raised to get \(x\): if \(x=e^{z}\), then \(\ln x=z\). So the logarithm undoes the exponential: \(\ln e^{z}=z\) and \(e^{\ln x}=x\). (The base-10 logarithm, \(\log_{10}\), works the same way with 10 instead of \(e\): \(\log_{10}1000=3\).) Logs are defined only for positive numbers. Their rules are the reason economists love them:
| Rule | In words | Used for |
|---|---|---|
| \(\ln(xy)=\ln x+\ln y\) | the log of a product is the sum of the logs | growth of GDP = growth of GDP per person + growth of population |
| \(\ln(x/y)=\ln x-\ln y\) | the log of a ratio is the difference of the logs | growth of a ratio such as \(Y/L\) |
| \(\ln(x^a)=a\ln x\) | an exponent comes down as a factor | growth of \(K^{1/3}\) |
| \(\ln 1=0\) |
SymPy knows these rules. sp.expand_log applies them; the symbols must be declared positive, because logs of negative numbers are not defined.
x, y, a = sp.symbols("x y a", positive=True)
print(sp.expand_log(sp.log(x * y)))
print(sp.expand_log(sp.log(x / y)))
print(sp.expand_log(sp.log(x ** a)))
print(sp.expand_log(sp.log(sp.symbols("Abar", positive=True) * sp.symbols("K", positive=True) ** sp.Rational(1, 3))))
log(x) + log(y)
log(x) - log(y)
a*log(x)
log(Abar) + log(K)/3NumPy computes logs of numbers: np.log is the natural log and np.log10 the base-10 log. A quick numerical check of the rules:
print(np.log(3 * 5), np.log(3) + np.log(5))       # the same number
print(np.log(2 ** 10), 10 * np.log(2))            # the same number
print(np.log10(1000), np.exp(np.log(42)))         # 3, and 42 back again
2.70805020110221 2.70805020110221
6.931471805599453 6.931471805599453
3.0 42.00000000000001Log differences are (almost) percent changes. When income rises from 100 to 103, it rises by 3 percent, and \(100 \times (\ln 103-\ln 100)=2.96\). Economists call \(100 \times \Delta\ln x\) a change in log points. For changes of a few percent, log points and percent are nearly the same number (Section C.6).
The ratio scale
On a ratio scale (or log scale), equal distances on the vertical axis mean equal ratios: from 5,000 to 10,000 dollars is as far as from 40,000 to 80,000. Taking logs of (3.7) gives \(\ln y_t=\ln y_0+t\ln(1+\bar{g})\), a straight line in \(t\) with slope \(\ln(1+\bar{g})\). So a series that grows at a constant rate is a straight line on a ratio scale, and the slope of the line shows the growth rate (Chapter 3).
gdp_pc = pd.read_csv(DATA_URL + "fig3-2.csv")
start, end = gdp_pc.iloc[0], gdp_pc.iloc[-1]
avg_growth = 100 * ((end["gdppc"] / start["gdppc"]) ** (1 / (end["year"] - start["year"])) - 1)
ratio_fig = px.line(gdp_pc, x="year", y="gdppc", log_y=True,
                    labels={"year": "", "gdppc": "GDP per person (2022 dollars)"},
                    title=f"U.S. GDP per person, 1870–2025: {avg_growth:.1f}% a year, close to a straight line "
                          "on a ratio scale")
ratio_ticks = [3000, 5000, 10000, 20000, 50000, 100000]
ratio_fig.update_yaxes(tickvals=ratio_ticks, range=[np.log10(3000), np.log10(100000)])
ratio_fig.update_layout(updatemenus=[dict(type="buttons", direction="right", x=0.99, xanchor="right", y=0.04,
    yanchor="bottom", buttons=[
        dict(label="Ratio scale", method="relayout",
             args=[{"yaxis.type": "log", "yaxis.range": [np.log10(3000), np.log10(100000)], "yaxis.tickvals": ratio_ticks}]),
        dict(label="Linear scale", method="relayout",
             args=[{"yaxis.type": "linear", "yaxis.range": [0, 90000], "yaxis.tickvals": [0, 20000, 40000, 60000, 80000]}])])])
ratio_fig
Sources. Data: U.S. Bureau of Economic Analysis, Real Gross Domestic Product (GDPCA), via FRED; population (B230RC0A052NBEA), via FRED; GDP deflator (A191RD3A086NBEA), via FRED; before 1929, the Maddison Project Database 2023 (Bolt and van Zanden 2024). Prepared file: data/appC/fig3-2.csv (see the data notes). Chart: inspired by Figs. 3.2 and 3.5 in Jones (2024), Macroeconomics, 6th ed.
What to notice.
- Click Linear scale: the early decades look flat and the recent ones steep, as if growth had sped up. On the ratio scale the line is nearly straight: growth has been roughly constant for 150 years.
- On the ratio scale, the dip of the Great Depression (1929–1933) stands out clearly, while on the linear scale it looks smaller than the 2008–2009 recession, which was much milder in percent.
Your turn. Compute the average annual growth rate of GDP per person from 1950 to 2025 with the same formula. Is it faster or slower than over 1870–2025?
Hint
Select the rows with gdp_pc[gdp_pc["year"] == 1950] and ... == 2025, and use \((y_T/y_0)^{1/T}-1\) with \(T=75\).
# Your turn: try it hereC.5 Growth rates and the growth rules
Goal. Compute growth rates in three ways, and use the three growth rules of Chapter 3 to find the growth of products, ratios and powers.
There are three common ways to measure growth:
| Measure | Formula | In pandas |
|---|---|---|
| growth from one year to the next | \(g_t=(y_t-y_{t-1})/y_{t-1}\) | 100 * y.pct_change() |
| log difference | \(\ln y_t-\ln y_{t-1}\) | 100 * np.log(y).diff() |
| average annual growth over \(T\) years | \(\bar{g}=(y_T/y_0)^{1/T}-1\), equation (3.9) | as in Section C.4 |
gdp_pc["growth"] = 100 * gdp_pc["gdppc"].pct_change()           # percent
gdp_pc["log_growth"] = 100 * np.log(gdp_pc["gdppc"]).diff()      # log points
print(f"Average annual growth, equation (3.9):     {avg_growth:.2f}%")
print(f"Simple mean of the yearly growth rates:    {gdp_pc['growth'].mean():.2f}%")
print(f"Mean of the yearly log differences:        {gdp_pc['log_growth'].mean():.2f} log points")
Average annual growth, equation (3.9): 1.88%
Simple mean of the yearly growth rates: 1.99%
Mean of the yearly log differences: 1.86 log pointsWhy is the simple mean of the yearly rates higher than the average annual growth rate? Because ups and downs do not cancel out in percent: a fall of 50 percent followed by a rise of 50 percent leaves you at \(0.5 \times 1.5 = 0.75\), not where you started, even though the mean of \(-50\) and \(+50\) is zero. When you want the growth rate that takes \(y_0\) to \(y_T\), use (3.9). The mean log difference is the continuous-time version of (3.9).
The growth rules
If \(x\) grows at rate \(g_x\) and \(y\) at rate \(g_y\), Chapter 3 gives three rules:
- Product: \(z=x \times y \;\Rightarrow\; g_z \approx g_x+g_y\).
- Ratio: \(z=x/y \;\Rightarrow\; g_z \approx g_x-g_y\).
- Power: \(z=x^a \;\Rightarrow\; g_z \approx a \times g_x\).
Why “approximately”? Over one year, \(1+g_z=(1+g_x)(1+g_y)=1+g_x+g_y+g_x g_y\). The last term is the product of two small numbers (0.02 × 0.03 = 0.0006), so we drop it. SymPy shows the exact result:
g_x, g_y = sp.symbols("g_x g_y")
print("Product, exact:", sp.expand((1 + g_x) * (1 + g_y) - 1))
print("With 2% and 3%:", sp.expand((1 + g_x) * (1 + g_y) - 1).subs({g_x: 0.02, g_y: 0.03}))
Product, exact: g_x*g_y + g_x + g_y
With 2% and 3%: 0.0506000000000000In continuous time the rules are exact (Section C.11 proves them with derivatives).
The famous example. Apply the rules to the production function \(Y_t=A_tK_t^{1/3}L_t^{2/3}\): the product rule adds the pieces, and the power rule multiplies each growth rate by its exponent,
\[g_Y=g_A+\tfrac{1}{3}g_K+\tfrac{2}{3}g_L. \qquad (6.14)\]
def output_growth(g_A, g_K, g_L):
    """Growth rules applied to Y = A K^(1/3) L^(2/3), equation (6.14); rates in percent."""
    return g_A + g_K / 3 + 2 * g_L / 3

print("Output growth with g_A = 1, g_K = 3, g_L = 1:", round(output_growth(1, 3, 1), 2), "percent")
print("GDP per worker grows at", round(output_growth(1, 3, 1) - 1, 2), "percent (ratio rule: g_Y - g_L)")
Output growth with g_A = 1, g_K = 3, g_L = 1: 2.67 percent
GDP per worker grows at 1.67 percent (ratio rule: g_Y - g_L)The same rules give the quantity theory of money in growth rates (Chapter 8): from \(MV=PY\) (8.1), \(g_M+g_V=g_P+g_Y\) (8.3). With a constant velocity, inflation is money growth minus output growth (8.4): 7 percent money growth and 3 percent output growth give about 4 percent inflation.
The rules in the data
Nominal GDP is real GDP times the deflator (divided by 100), so by the product rule, nominal GDP growth ≈ real GDP growth + inflation. Let us check it with the U.S. national accounts.
nipa["g_nominal"] = 100 * nipa["gdp"].pct_change()
nipa["g_real"] = 100 * nipa["real_gdp"].pct_change()
nipa["inflation"] = 100 * nipa["deflator"].pct_change()
nipa["sum_of_rates"] = nipa["g_real"] + nipa["inflation"]      # the product rule
nipa["gap"] = nipa["g_nominal"] - nipa["sum_of_rates"]
biggest = nipa.loc[nipa["gap"].abs().idxmax()]
print(f"Largest gap: {biggest['gap']:.2f} points in {biggest['year']:.0f}")
nipa[["year", "g_nominal", "g_real", "inflation", "sum_of_rates"]].tail().round(2)
Largest gap: 1.51 points in 1932| year | g_nominal | g_real | inflation | sum_of_rates | |
|---|---|---|---|---|---|
| 92 | 2021 | 11.09 | 6.27 | 4.54 | 10.81 |
| 93 | 2022 | 9.74 | 2.43 | 7.14 | 9.57 |
| 94 | 2023 | 6.78 | 2.92 | 3.75 | 6.67 |
| 95 | 2024 | 5.59 | 2.95 | 2.56 | 5.51 |
| 96 | 2025 | 5.04 | 2.34 | 2.63 | 4.98 |
rules_long = nipa.melt(id_vars="year", value_vars=["g_nominal", "sum_of_rates"], var_name="series", value_name="rate")
rules_long["series"] = rules_long["series"].map({"g_nominal": "Nominal GDP growth",
                                                 "sum_of_rates": "Real GDP growth + inflation"})
rules_fig = px.line(rules_long, x="year", y="rate", color="series",
                    labels={"year": "", "rate": "percent"},
                    title=f"The product rule in U.S. data: the two lines differ by at most {abs(biggest['gap']):.1f} points")
rules_fig.update_layout(legend_title_text="", legend=dict(x=0.99, xanchor="right", y=0.98))
rules_fig
Sources. Data: U.S. Bureau of Economic Analysis, Gross Domestic Product (GDPA), via FRED and Real Gross Domestic Product (GDPCA), via FRED. Prepared file: data/appC/nipa_annual.csv (see the data notes). Chart: inspired by the growth rules and Fig. 3.9 in Jones (2024), Macroeconomics, 6th ed.
What to notice.
- The two lines are almost on top of each other. They separate only when both rates are large, as in the 1930s and 1940s, because the dropped term \(g_{\text{real}} \times \pi\) is then no longer small.
- In 2025 the gap is a few hundredths of a point: for normal growth and inflation rates, the rule is all you need.
Your turn. Use the ratio rule on GDP per person: compute the growth of real GDP, of the population, and of real GDP per person in nipa, and check that per-person growth ≈ GDP growth − population growth.
Hint
Create nipa["g_pop"] = 100 * nipa["population"].pct_change() and a column for real GDP divided by population, then its pct_change(). Compare the columns in the last few years with .tail().
# Your turn: try it hereC.6 Approximations
Goal. Know the few approximations the book uses, where they come from, and when they break down.
Economists often replace an exact formula with a simpler one that is almost right for small numbers. Four approximations do most of the work:
| Approximation | Good when | Used for |
|---|---|---|
| \(\ln(1+x) \approx x\) | \(x\) is small | log differences ≈ percent changes; the output gap |
| \((1+a)(1+b) \approx 1+a+b\) | \(a\) and \(b\) are small | the growth rules (C.5) |
| \((1+a)/(1+b) \approx 1+a-b\) | \(a\) and \(b\) are small | the Fisher equation \(R \approx i-\pi\) (Chapter 8) |
| \(f(x) \approx f(x_0)+f'(x_0)(x-x_0)\) | \(x\) is close to \(x_0\) | linearizing a model around its steady state (C.10) |
The last line is the general idea, the first-order Taylor approximation: near a point \(x_0\), any smooth function looks like a straight line through \(f(x_0)\) with slope \(f'(x_0)\) (the derivative, Section C.7). The others are special cases. SymPy’s series gives the approximation to any order:
x = sp.symbols("x")
sp.series(sp.log(1 + x), x, 0, 4)    # ln(1 + x) near x = 0, up to x^3
\(\displaystyle x - \frac{x^{2}}{2} + \frac{x^{3}}{3} + O\left(x^{4}\right)\)
So \(\ln(1+x)=x-x^2/2+x^3/3-\dots\). For \(x=0.02\) the second term is only \(0.0002\).
Where the Rule of 70 comes from. The exact doubling time is \(\ln 2/\ln(1+g)\). Its series in \(g\):
g = sp.symbols("g", positive=True)
sp.series(sp.log(2) / sp.log(1 + g), g, 0, 2)
\(\displaystyle \frac{\log{\left(2 \right)}}{g} + \frac{\log{\left(2 \right)}}{2} - \frac{g \log{\left(2 \right)}}{12} + O\left(g^{2}\right)\)
With \(g\) in percent (\(g=G/100\)), the first two terms are \(69.3/G+0.35\). At \(G=2\) this is \(34.66+0.35=35.0\), exactly \(70/2\). So “70” is \(100\ln 2 \approx 69.3\), rounded up to absorb the second term at the growth rates that matter for income.
How large is the error?
x_values = np.array([0.01, 0.02, 0.05, 0.10, 0.25, 0.50, 1.00])
errors = pd.DataFrame({"x": x_values, "ln(1 + x)": np.log(1 + x_values)})
errors["error: x - ln(1 + x)"] = errors["x"] - errors["ln(1 + x)"]
errors["error as % of x"] = 100 * errors["error: x - ln(1 + x)"] / errors["x"]
errors.round(4)| x | ln(1 + x) | error: x - ln(1 + x) | error as % of x | |
|---|---|---|---|---|
| 0 | 0.01 | 0.0100 | 0.0000 | 0.4967 |
| 1 | 0.02 | 0.0198 | 0.0002 | 0.9869 |
| 2 | 0.05 | 0.0488 | 0.0012 | 2.4197 |
| 3 | 0.10 | 0.0953 | 0.0047 | 4.6898 |
| 4 | 0.25 | 0.2231 | 0.0269 | 10.7426 |
| 5 | 0.50 | 0.4055 | 0.0945 | 18.9070 |
| 6 | 1.00 | 0.6931 | 0.3069 | 30.6853 |
def approximation_chart(x0=0.05):
    """The curve ln(1 + x), the straight line x, and the error at x0."""
    x0 = round(x0, 2) + 0.0                             # a slider step can give -2e-17 instead of 0
    x_grid = np.linspace(-0.5, 1.05, 311)
    exact, error = math.log(1 + x0), x0 - math.log(1 + x0)
    fig = go.Figure()
    fig.add_trace(go.Scatter(x=x_grid, y=np.log(1 + x_grid), mode="lines", name="exact: ln(1 + x)", line=dict(color=BLUE, width=3)))
    fig.add_trace(go.Scatter(x=x_grid, y=x_grid, mode="lines", name="approximation: x", line=dict(color=TEAL, width=3, dash="dash")))
    fig.add_trace(go.Scatter(x=[x0, x0], y=[exact, x0], mode="lines+markers", name="error",
                             line=dict(color=ORANGE, width=3), marker=dict(size=9)))
    fig.update_layout(title=f"x = {x0:.2f}: ln(1 + x) = {exact:.4f}; the error is {error:.4f}",
                      xaxis=dict(title="x", range=[-0.5, 1.05]), yaxis=dict(title="value", range=[-0.8, 1.1]),
                      legend=dict(x=0.02, y=0.98))
    return fig
interact(approximation_chart,
x0=FloatSlider(value=0.05, min=-0.4, max=1.0, step=0.05, description="x", style=WIDE));Show the code of the website version
# @title Website version: the approximation chart with a precomputed slider for x
slider_figure(approximation_chart, "x0", [-0.3, -0.1, 0.02, 0.05, 0.1, 0.2, 0.3, 0.5, 0.75, 1.0], start=0.05,
              label="x")
Source. Illustration of the approximation \(\ln(1+x) \approx x\) used throughout Jones (2024), Macroeconomics, 6th ed.
The Fisher equation when inflation is high
The exact link between the nominal rate \(i\), the real rate \(R\) and inflation \(\pi\) is \(1+i=(1+R)(1+\pi)\), so the exact real rate is \(R=(1+i)/(1+\pi)-1\). The book uses the approximation \(R=i-\pi\) (8.6). Compare the two in the United States and in Argentina:
interest = pd.read_csv(DATA_URL + "interest_rates_panel.csv")
fisher = interest[interest["iso3"].isin(["USA", "ARG"]) & interest["year"].between(2021, 2024)].copy()
fisher["real_exact"] = 100 * ((1 + fisher["short_rate"] / 100) / (1 + fisher["inflation"] / 100) - 1)
fisher = fisher.rename(columns={"short_rate": "nominal rate i", "inflation": "inflation π",
                                "real_rate": "approximation i - π", "real_exact": "exact real rate"})
fisher[["country", "year", "nominal rate i", "inflation π", "approximation i - π", "exact real rate"]].round(1)| country | year | nominal rate i | inflation π | approximation i - π | exact real rate | |
|---|---|---|---|---|---|---|
| 22 | Argentina | 2021 | 34.1 | 48.4 | -14.3 | -9.6 |
| 23 | Argentina | 2022 | 53.2 | 72.4 | -19.2 | -11.2 |
| 24 | Argentina | 2023 | 95.8 | 133.5 | -37.7 | -16.1 |
| 25 | Argentina | 2024 | 55.7 | 219.9 | -164.2 | -51.3 |
| 2049 | United States | 2021 | 0.0 | 4.7 | -4.6 | -4.4 |
| 2050 | United States | 2022 | 2.0 | 8.0 | -6.0 | -5.5 |
| 2051 | United States | 2023 | 5.1 | 4.1 | 0.9 | 0.9 |
| 2052 | United States | 2024 | 5.0 | 3.0 | 2.0 | 2.0 |
The output gap as a log difference
Short-run output is \(\tilde{Y}_t=(Y_t-\bar{Y}_t)/\bar{Y}_t\) (9.2). Since \(\ln(1+x) \approx x\), it is close to \(\ln Y_t-\ln \bar{Y}_t\), which is how many researchers compute it.
potential = pd.read_csv(DATA_URL + "fig9-2.csv")
potential["gap_percent"] = 100 * (potential["gdp_actual"] - potential["gdp_potential"]) / potential["gdp_potential"]
potential["gap_log"] = 100 * np.log(potential["gdp_actual"] / potential["gdp_potential"])
potential[potential["year"].isin([1933, 1982, 2009, 2020, 2025])].round(2)| year | gdp_actual | gdp_potential | gap_percent | gap_log | |
|---|---|---|---|---|---|
| 4 | 1933 | 1.04 | 1.35 | -23.25 | -26.47 |
| 53 | 1982 | 8.62 | 9.20 | -6.23 | -6.43 |
| 80 | 2009 | 19.30 | 20.24 | -4.66 | -4.77 |
| 91 | 2020 | 23.94 | 24.75 | -3.28 | -3.33 |
| 96 | 2025 | 28.26 | 27.87 | 1.40 | 1.39 |
What to notice.
- Up to \(x=0.10\) the error of \(\ln(1+x)\approx x\) is less than 5 percent of \(x\); at \(x=1\) it is about 30 percent.
- In the United States, with inflation of a few percent, \(i-\pi\) and the exact real rate differ by tenths of a point. In Argentina in 2024, with inflation above 200 percent, the approximation gives a real rate of about \(-164\) percent, while the exact rate is about \(-51\) percent. A real rate below \(-100\) percent is impossible: it would mean lenders lose more than everything.
- The two output gaps are almost equal in normal recessions and differ by about 3 points in 1933, when output was 23 percent below potential.
Your turn. The exact version of the quantity theory in growth rates is \((1+g_M)(1+g_V)=(1+g_P)(1+g_Y)\). With money growth of 100 percent a year, constant velocity and output growth of 2 percent, compute inflation with the exact formula and with the approximation \(\pi=g_M-g_Y\) (8.4).
Hint
Exactly, \(1+\pi=(1+g_M)/(1+g_Y)=2/1.02\). The approximation gives \(100-2=98\) percent.
# Your turn: try it hereC.7 Derivatives and marginal thinking
Goal. Compute derivatives by hand, with SymPy and numerically, and use them for marginal products, elasticities and returns to scale.
The derivative \(f'(x)\), also written \(df/dx\), is the slope of a function at a point: how much \(f\) changes per unit change in \(x\), for a very small change. Economists say “marginal”: the marginal product of capital (MPK) is the extra output from one more unit of capital. The rules you need:
| Function | Derivative | Example |
|---|---|---|
| \(x^n\) | \(n\,x^{n-1}\) | \(\frac{d}{dk}k^{1/3}=\tfrac{1}{3}k^{-2/3}\) |
| \(\ln x\) | \(1/x\) | \(\frac{d}{dc}\ln c=1/c\) (marginal utility, Chapter 16) |
| \(e^{ax}\) | \(a\,e^{ax}\) | |
| \(c \cdot f(x)\) | \(c \cdot f'(x)\) | constants stay |
| \(f(g(x))\) | \(f'(g(x))\,g'(x)\) | the chain rule |
A function of several inputs, such as \(Y=F(K,L)\), has a partial derivative for each input: change one, hold the others fixed. It is written \(\partial Y/\partial K\).
Abar, K, L = sp.symbols("Abar K L", positive=True)
Y = Abar * K ** sp.Rational(1, 3) * L ** sp.Rational(2, 3)      # equation (4.1)
MPK = sp.diff(Y, K)                                             # partial derivative with respect to K
MPL = sp.diff(Y, L)
MPK
\(\displaystyle \frac{\bar{A} L^{\frac{2}{3}}}{3 K^{\frac{2}{3}}}\)
Python note.
sp.Rational(1, 3)is the exact fraction 1/3. Writing1/3would give the decimal 0.3333…, and SymPy could no longer simplify exactly.sp.diff(Y, K)differentiatesYwith respect toK, treating every other symbol as a constant.
Chapter 4 writes these as shares of the average product: \(MPK=\tfrac{1}{3}\,Y/K\) (4.3) and \(MPL=\tfrac{2}{3}\,Y/L\) (4.4). SymPy confirms both: the differences simplify to zero.
print("MPK - (1/3) Y/K =", sp.simplify(MPK - Y / (3 * K)))
print("MPL - (2/3) Y/L =", sp.simplify(MPL - 2 * Y / (3 * L)))
print("Second derivative in K:", sp.simplify(sp.diff(Y, K, 2)), "(negative: diminishing returns)")
MPK - (1/3) Y/K = 0
MPL - (2/3) Y/L = 0
Second derivative in K: -2*Abar*L**(2/3)/(9*K**(5/3)) (negative: diminishing returns)Elasticities and returns to scale
An elasticity is a ratio of percent changes: the elasticity of \(Y\) with respect to \(K\) is \((\partial Y/\partial K)\cdot(K/Y)\), the percent change in output for a 1 percent change in capital. In a Cobb-Douglas function, each exponent is an elasticity. Constant returns to scale means that doubling all inputs doubles output: \(F(\lambda K,\lambda L)=\lambda F(K,L)\).
lam = sp.symbols("lambda", positive=True)
print("Elasticity of Y with respect to K:", sp.simplify(MPK * K / Y))
print("Elasticity of Y with respect to L:", sp.simplify(MPL * L / Y))
print("F(λK, λL) / F(K, L) =", sp.simplify(Y.subs({K: lam * K, L: lam * L}, simultaneous=True) / Y))
print("K·MPK + L·MPL - Y =", sp.simplify(K * MPK + L * MPL - Y))
Elasticity of Y with respect to K: 1/3
Elasticity of Y with respect to L: 2/3
F(λK, λL) / F(K, L) = lambda
K·MPK + L·MPL - Y = 0The last line is the reason factor shares add up to one in Chapter 4: when firms pay \(r=MPK\) and \(w=MPL\), capital gets \(rK/Y=1/3\) of output and labor gets \(wL/Y=2/3\), and together they exhaust output (4.5)–(4.6).
Numerical derivatives
When a function has no formula, or the formula is messy, we can approximate the slope with a small step \(h\): \(f'(x) \approx [f(x+h)-f(x)]/h\). NumPy’s np.gradient does this for a whole grid at once.
def y_per_person(k):
    """Output per person y = k^(1/3), equation (5.6) with A = 1."""
    return k ** (1 / 3)

k0 = 8.0
for h in [1, 0.1, 0.01, 0.001]:
    print(f"h = {h:<6}: slope = {(y_per_person(k0 + h) - y_per_person(k0)) / h:.5f}")
print(f"exact      : slope = {(1 / 3) * k0 ** (-2 / 3):.5f}")
k_grid = np.linspace(1, 20, 191)                    # steps of 0.1
slopes = np.gradient(y_per_person(k_grid), k_grid)
print(f"np.gradient at k = 8: {slopes[70]:.5f}")
h = 1 : slope = 0.08008
h = 0.1 : slope = 0.08299
h = 0.01 : slope = 0.08330
h = 0.001 : slope = 0.08333
exact : slope = 0.08333
np.gradient at k = 8: 0.08334tangent_fig = go.Figure()
k_axis = np.linspace(0, 20, 401)
tangent_fig.add_trace(go.Scatter(x=k_axis, y=y_per_person(k_axis), mode="lines", name="y = k^(1/3)",
line=dict(color=BLUE, width=3)))
for k_point, color in [(1.0, TEAL), (8.0, GREEN)]:
slope = (1 / 3) * k_point ** (-2 / 3)
k_near = np.linspace(max(k_point - 4, 0), k_point + 4, 50)
tangent_fig.add_trace(go.Scatter(x=k_near, y=y_per_person(k_point) + slope * (k_near - k_point), mode="lines",
name=f"slope at k = {k_point:.0f}: {slope:.3f}", line=dict(color=color, width=2, dash="dash")))
tangent_fig.add_trace(go.Scatter(x=[k_point], y=[y_per_person(k_point)], mode="markers", showlegend=False,
marker=dict(color=color, size=11)))
tangent_fig.update_layout(title="Diminishing returns: the marginal product falls from 0.333 at k = 1 to 0.083 at k = 8",
xaxis=dict(title="capital per person, k", range=[0, 20], tickvals=[5, 10, 15, 20]),
yaxis=dict(title="output per person, y", range=[0, 3.2]),
legend=dict(x=0.99, xanchor="right", y=0.02, yanchor="bottom"))
tangent_figSource. Illustration of the production function (5.6) and its marginal product, as in Chapters 4 and 5 of Jones (2024), Macroeconomics, 6th ed.
What to notice.
- The dashed lines touch the curve at one point each: they are the tangents, and their slopes are the derivatives. The curve gets flatter as \(k\) rises: each extra unit of capital adds less output.
- The numerical slope approaches the exact one as \(h\) shrinks. With \(h=0.001\) they agree to five decimals.
Your turn. Use SymPy to find the marginal utility \(u'(c)\) of the utility function \(u(c)=\ln c\) and of \(u(c)=c^{1/2}\). Do both fall as \(c\) rises? (Chapter 16 uses this to explain why households smooth consumption.)
Hint
Create c = sp.symbols("c", positive=True) and use sp.diff(sp.log(c), c) and sp.diff(sp.sqrt(c), c). The second derivative, sp.diff(..., c, 2), tells you whether the slope falls.
# Your turn: try it hereC.8 Optimization
Goal. Find the best choice of a firm and of a household: set the derivative to zero, and check the answer with a numerical optimizer.
At the top of a hill the ground is flat. So when a function has a maximum at \(x^*\), its slope there is zero: \(f'(x^*)=0\). This is the first-order condition. (To be sure it is a maximum and not a minimum, the slope must fall as you pass through \(x^*\): the second derivative is negative.)
A firm chooses how many workers to hire
A firm with a fixed capital stock \(\bar{K}=8\) and productivity \(\bar{A}=1\) pays the wage \(w\) per worker. It chooses labor \(L\) to maximize profit (compare (4.2)): \(\Pi(L)=\bar{A}\bar{K}^{1/3}L^{2/3}-wL\). The first-order condition says: hire until the marginal product of labor equals the wage, \(MPL=w\).
L, w = sp.symbols("L w", positive=True)
profit = 1 * 8 ** sp.Rational(1, 3) * L ** sp.Rational(2, 3) - w * L     # A = 1, K = 8
first_order_condition = sp.Eq(sp.diff(profit, L), 0)                      # MPL - w = 0
L_star = sp.solve(first_order_condition, L)[0]
L_star
\(\displaystyle \frac{64}{27 w^{3}}\)
print("Workers hired when w = 2/3:", L_star.subs(w, sp.Rational(2, 3)))
print("Second derivative at that point:", sp.diff(profit, L, 2).subs({w: sp.Rational(2, 3), L: 8}))
Workers hired when w = 2/3: 8
Second derivative at that point: -1/36SciPy finds the same answer numerically. Its optimizers minimize, so we give it minus the profit.
def minus_profit(L):
    """Minus the firm's profit with A = 1, K = 8 and w = 2/3 (SciPy minimizes)."""
    return -(8 ** (1 / 3) * L ** (2 / 3) - (2 / 3) * L)

best_L = optimize.minimize_scalar(minus_profit, bounds=(0.1, 50), method="bounded")
print(f"minimize_scalar: L* = {best_L.x:.4f}, profit = {-best_L.fun:.4f}")
minimize_scalar: L* = 8.0000, profit = 2.6667A household chooses consumption today and tomorrow
In Chapter 16 a household lives two periods, values consumption with \(U=\ln c_{\text{today}}+\beta\ln c_{\text{future}}\), and faces the budget constraint \(c_{\text{today}}+c_{\text{future}}/(1+R)=\bar{X}\), where \(\bar{X}\) is its lifetime wealth (16.5). There are two ways to solve such a problem.
Substitution. Use the constraint to write \(c_{\text{future}}=(1+R)(\bar{X}-c_{\text{today}})\), put it into \(U\), and set the derivative with respect to \(c_{\text{today}}\) to zero.
c_today, c_future, R, beta, X = sp.symbols("c_today c_future R beta X", positive=True)
U = sp.log(c_today) + beta * sp.log((1 + R) * (X - c_today))
c_today_star = sp.solve(sp.diff(U, c_today), c_today)[0]
c_today_star
\(\displaystyle \frac{X}{\beta + 1}\)
With \(\beta=1\) this is \(\bar{X}/2\), equation (16.9): the household consumes half of its lifetime wealth today.
The Lagrangian. Add the constraint, multiplied by a new variable \(\mu\) (the Lagrange multiplier), to the objective, and set the derivative with respect to every variable to zero. This method works even when you cannot substitute easily.
mu = sp.symbols("mu")                           # the Lagrange multiplier
lagrangian = sp.log(c_today) + beta * sp.log(c_future) + mu * (X - c_today - c_future / (1 + R))
conditions = [sp.diff(lagrangian, c_today), sp.diff(lagrangian, c_future), sp.diff(lagrangian, mu)]
solution = sp.solve(conditions, [c_today, c_future, mu], dict=True)[0]
print("c_today  =", solution[c_today])
print("c_future =", solution[c_future])
print("c_future / c_today =", sp.simplify(solution[c_future] / solution[c_today]), " (the Euler equation, 16.8)")
c_today = X/(beta + 1)
c_future = X*beta*(R + 1)/(beta + 1)
c_future / c_today = beta*(R + 1) (the Euler equation, 16.8)The ratio \(c_{\text{future}}/c_{\text{today}}=\beta(1+R)\) is the Euler equation with log utility: patience (\(\beta\)) and a high interest rate (\(R\)) tilt consumption toward the future.
X_value, beta_value, R_value = 100, 0.96, 0.05            # our own illustrative numbers
c_grid = np.linspace(5, 95, 181)
utility = np.log(c_grid) + beta_value * np.log((1 + R_value) * (X_value - c_grid))
c_best = X_value / (1 + beta_value)
utility_fig = go.Figure()
utility_fig.add_trace(go.Scatter(x=c_grid, y=utility, mode="lines", name="lifetime utility", line=dict(color=BLUE, width=3)))
u_best = np.log(c_best) + beta_value * np.log((1 + R_value) * (X_value - c_best))
utility_fig.add_trace(go.Scatter(x=[c_best - 15, c_best + 15], y=[u_best, u_best], mode="lines", name="slope zero",
                                 line=dict(color=TEAL, dash="dash")))
utility_fig.add_trace(go.Scatter(x=[c_best], y=[u_best], mode="markers", name="the best choice", marker=dict(color=TEAL, size=12)))
utility_fig.update_layout(title=f"With X = 100, β = 0.96 and R = 5%, utility is highest at c_today = {c_best:.1f}",
                          xaxis=dict(title="consumption today", range=[0, 100], tickvals=[20, 40, 60, 80, 100]),
                          yaxis=dict(title="lifetime utility", range=[5.6, 8.1]), legend=dict(x=0.02, y=0.02, yanchor="bottom"))
utility_fig
Source. Illustration of the household’s problem, equation (16.5) in Jones (2024), Macroeconomics, 6th ed.
What to notice.
- The curve is flat at its peak, where the tangent is horizontal. That is the first-order condition at work.
- The household consumes a little more than half today (\(100/1.96=51.0\)): with \(\beta=0.96\) it is slightly impatient, and the 5 percent interest rate is not quite enough to make up for it.
Your turn. Check the household’s answer with SciPy: use optimize.minimize_scalar on minus the utility along the budget line, with \(\bar{X}=100\), \(\beta=0.96\) and \(R=0.05\), searching between 1 and 99.
Hint
Write a function of c that returns -(np.log(c) + 0.96 * np.log(1.05 * (100 - c))), then call optimize.minimize_scalar(your_function, bounds=(1, 99), method="bounded") and print .x.
# Your turn: try it hereC.9 Solving equations and systems
Goal. Solve a system of linear equations with NumPy and SymPy, and a nonlinear equation with SymPy and SciPy.
A linear system: the short-run model
The short-run model of Chapters 11–13 has three equations and three unknowns: output \(\tilde{Y}_t\), the real interest rate \(R_t\) and inflation \(\pi_t\).
\[\begin{aligned} \text{IS:}\quad & \tilde{Y}_t=\bar{a}-\bar{b}(R_t-\bar{r}) & (11.14)\\ \text{MP rule:}\quad & R_t-\bar{r}=\bar{m}(\pi_t-\bar{\pi}) & (13.1)\\ \text{AS:}\quad & \pi_t=\pi_{t-1}+\bar{\nu}\tilde{Y}_t+\bar{o} & (13.2) \end{aligned}\]
Move all unknowns to the left and all numbers to the right, and the system has the matrix form \(Mz=c\):
\[\begin{pmatrix}1 & \bar{b} & 0\\ 0 & 1 & -\bar{m}\\ -\bar{\nu} & 0 & 1\end{pmatrix} \begin{pmatrix}\tilde{Y}_t\\ R_t\\ \pi_t\end{pmatrix}= \begin{pmatrix}\bar{a}+\bar{b}\bar{r}\\ \bar{r}-\bar{m}\bar{\pi}\\ \pi_{t-1}+\bar{o}\end{pmatrix}.\]
We take our own illustrative numbers: a negative demand shock \(\bar{a}=-2\), \(\bar{b}=\bar{m}=\bar{\nu}=0.5\), \(\bar{r}=\bar{\pi}=2\), last year’s inflation \(\pi_{t-1}=2\) and no price shock, \(\bar{o}=0\).
Python note.
np.array([[...], [...]])builds a matrix row by row.np.linalg.solve(M, c)solves \(Mz=c\) for the vector \(z\).
a_, b_, m_, nu_, r_, pibar_, pi_last, o_ = -2, 0.5, 0.5, 0.5, 2, 2, 2, 0
M = np.array([[1, b_, 0],
              [0, 1, -m_],
              [-nu_, 0, 1]])
c = np.array([a_ + b_ * r_, r_ - m_ * pibar_, pi_last + o_])
Y_short, R_short, pi_short = np.linalg.solve(M, c)
print(f"Output gap {Y_short:.3f}%, real rate {R_short:.3f}%, inflation {pi_short:.3f}%")
Output gap -1.778%, real rate 1.556%, inflation 1.111%SymPy solves the same system with letters, which shows how the answer depends on each parameter:
Yt, Rt, pit = sp.symbols("Ytilde R_t pi_t")
abar, bbar, mbar, nubar, rbar, pibar, obar = sp.symbols("abar bbar mbar nubar rbar pibar obar")
pi_prev = sp.Symbol(r"\pi_{t-1}")          # a symbol may carry its own LaTeX name
short_run = [sp.Eq(Yt, abar - bbar * (Rt - rbar)),
             sp.Eq(Rt - rbar, mbar * (pit - pibar)),
             sp.Eq(pit, pi_prev + nubar * Yt + obar)]
short_run_solution = sp.solve(short_run, [Yt, Rt, pit], dict=True)[0]
sp.simplify(short_run_solution[Yt])
\(\displaystyle \frac{- \pi_{t-1} \bar{b} \bar{m} + \bar{a} - \bar{b} \bar{m} \bar{o} + \bar{b} \bar{m} \bar{\pi}}{\bar{b} \bar{m} \bar{\nu} + 1}\)
The formula says: output falls with a negative demand shock \(\bar{a}\) and with inflation inherited from last year above target, and the factor \(1/(1+\bar{b}\bar{m}\bar{\nu})\) shows how the monetary policy rule softens the shock.
A nonlinear equation: the Solow steady state
In the Solow model (Chapter 5), capital per person stops changing when investment equals depreciation: \(\bar{s}\bar{A}k^{1/3}=\bar{d}k\). With \(\bar{s}=0.4\), \(\bar{d}=0.1\) and \(\bar{A}=1\):
k = sp.symbols("k", positive=True)
steady_state_equation = sp.Eq(sp.Rational(2, 5) * k ** sp.Rational(1, 3), sp.Rational(1, 10) * k)
print("SymPy:", sp.solve(steady_state_equation, k))
print("Formula (5.8):", (0.4 * 1 / 0.1) ** (3 / 2))
SymPy: [8]
Formula (5.8): 8.0def net_investment(k):
"""Investment minus depreciation per person, s A k^(1/3) - d k, with s = 0.4, A = 1, d = 0.1."""
return 0.4 * k ** (1 / 3) - 0.1 * k
print("brentq:", optimize.brentq(net_investment, 1, 100)) # one sign change between 1 and 100
print("fsolve:", optimize.fsolve(net_investment, 5)[0]) # starts at k = 5 and walks to the rootbrentq: 8.0
fsolve: 7.999999999999998Python note.
brentqneeds an interval where the function changes sign, and it always finds a root inside it.fsolveneeds only a starting guess, and it also solves systems of equations, but it can end at a different root (here \(k=0\) is a root too) if the guess is poor.
k_line = np.linspace(0, 20, 401)
solow_fig = go.Figure()
solow_fig.add_trace(go.Scatter(x=k_line, y=0.4 * k_line ** (1 / 3), mode="lines", name="investment, s·y",
                               line=dict(color=BLUE, width=3)))
solow_fig.add_trace(go.Scatter(x=k_line, y=0.1 * k_line, mode="lines", name="depreciation, d·k",
                               line=dict(color=TEAL, width=3)))
solow_fig.add_trace(go.Scatter(x=[8], y=[0.8], mode="markers", name="steady state k* = 8", marker=dict(color=GREEN, size=12)))
solow_fig.update_layout(title="The steady state solves s·A·k^(1/3) = d·k: k* = 8 when s = 0.4, d = 0.1, A = 1",
                        xaxis=dict(title="capital per person, k", range=[0, 20], tickvals=[5, 10, 15, 20]),
                        yaxis=dict(title="investment and depreciation", range=[0, 1.25]),
                        legend=dict(x=0.02, y=0.98))
solow_fig
Source. Adapted from Fig. 5.1 in Jones (2024), Macroeconomics, 6th ed.
What to notice.
- NumPy and SymPy agree: the demand shock opens a negative output gap of about 1.8 percent, inflation falls below target and the central bank cuts the real rate below \(\bar{r}\).
- The Solow equation has two roots, \(k=0\) and \(k^*=8\). SymPy, told that \(k\) is positive, reports only \(k^*=8\);
brentqfinds it because we started the interval at 1, away from zero.
Your turn. Solve the short-run system again with a price shock \(\bar{o}=1\) and no demand shock (\(\bar{a}=0\)). What happens to output and inflation? Then check your numbers with short_run_solution and .subs(...).
Hint
Change a_ and o_, rebuild c and call np.linalg.solve again. For SymPy, substitute a dictionary such as {abar: 0, bbar: 0.5, mbar: 0.5, nubar: 0.5, rbar: 2, pibar: 2, pi_prev: 2, obar: 1}.
# Your turn: try it hereC.10 Difference equations: how macro variables move over time
Goal. Find the steady state of a difference equation, decide whether it is stable, and simulate the path of capital, unemployment, inflation and public debt.
A difference equation says how a variable today depends on its own value in the period before. Many key equations of the book are difference equations: capital accumulation \(\Delta k_{t+1}=\bar{s}y_t-\bar{d}k_t\) (5.7), the “bathtub” model of unemployment (Chapter 7), the Phillips curve \(\pi_t=\pi_{t-1}+\bar{\nu}\tilde{Y}_t\) (12.5), and the government budget constraint \(B_{t+1}=(1+i)B_t+G_t-T_t\) (18.2). The simplest form is first-order and linear:
\[x_{t+1}=a\,x_t+b.\]
- Its steady state is the value that repeats itself: \(x^*=a\,x^*+b\), so \(x^*=b/(1-a)\) when \(a \neq 1\).
- Its solution is \(x_t=x^*+a^t(x_0-x^*)\): the gap to the steady state is multiplied by \(a\) each period.
- So the steady state is stable when \(|a|<1\): the gap shrinks to zero. With \(0<a<1\) the path approaches \(x^*\) smoothly; with \(-1<a<0\) it jumps from one side to the other. When \(|a|>1\) the gap explodes.
- The half-life, the number of periods it takes to close half of the gap, is \(\ln 0.5/\ln|a|\).
SymPy finds the steady state and the whole solution (rsolve solves recurrences, another name for difference equations):
x = sp.Function("x")
t, a, b, x0 = sp.symbols("t a b x_0")
x_star = sp.symbols("x_star")
print("Steady state:", sp.solve(sp.Eq(x_star, a * x_star + b), x_star))
sp.rsolve(x(t + 1) - a * x(t) - b, x(t), {x(0): x0})
Steady state: [-b/(a - 1)]\(\displaystyle \frac{a^{t} \left(a x_{0} + b - x_{0}\right)}{a - 1} - \frac{b}{a - 1}\)
With a loop, Python simulates any difference equation, linear or not:
def simulate_linear(a, b, x0, periods):
    """Iterate x_{t+1} = a x_t + b for the given number of periods, starting from x0."""
    path = [x0]
    for period in range(periods):
        path.append(a * path[-1] + b)
    return np.array(path)

path = simulate_linear(0.8, 1.0, 0.0, 10)
formula = 5 + 0.8 ** np.arange(0, 11) * (0.0 - 5)      # x* + a^t (x_0 - x*), with x* = 1 / (1 - 0.8) = 5
print(path.round(3))
print("Largest difference from the formula:", np.abs(path - formula).max())
[0. 1. 1.8 2.44 2.952 3.362 3.689 3.951 4.161 4.329 4.463]
Largest difference from the formula: 1.7763568394002505e-15Interactive: stability and speed
Move \(a\) and \(b\) and watch the path from \(x_0=0\). In Colab both sliders are live. On the website the slider moves \(a\) with \(b=1-a\), so the steady state stays at \(x^*=1\) and you see only the speed of the approach and the zigzag of a negative \(a\).
def difference_chart(a=0.8, b=1.0):
    """The path of x_{t+1} = a x_t + b from x_0 = 0, with its steady state x* = b / (1 - a)."""
    a = round(a, 2) + 0.0                               # a slider step can give 2e-16 instead of 0
    path = simulate_linear(a, b, 0.0, 30)
    x_star = b / (1 - a)
    top = 45.0
    for candidate in [2.5, 5.0, 12.0, 25.0, 45.0]:       # widen the axis in steps, only when needed
        if max(path.max(), x_star) * 1.05 <= candidate:
            top = candidate
            break
    fig = go.Figure()
    fig.add_trace(go.Scatter(x=[-5, 40], y=[x_star, x_star], mode="lines", name=f"steady state x* = {x_star:.2f}",
                             line=dict(color=GRAY, dash="dash")))
    fig.add_trace(go.Scatter(x=np.arange(0, 31), y=path, mode="lines+markers", name="path of x",
                             line=dict(color=BLUE, width=3), marker=dict(size=6)))
    if a == 0:
        speed = "x reaches x* after one period"
    else:
        speed = f"half of the gap closes every {math.log(0.5) / math.log(abs(a)):.1f} periods"
    fig.update_layout(title=f"a = {a:.2f}: x* = {x_star:.2f}; {speed}",
                      xaxis=dict(title="period, t", range=[0, 30], tickvals=[5, 10, 15, 20, 25, 30]), yaxis=dict(title="x", range=[-0.04 * top, top]),
                      legend=dict(orientation="h", x=0, y=1.02, yanchor="bottom"))
    return fig
interact(difference_chart,
a=FloatSlider(value=0.8, min=-0.9, max=0.95, step=0.05, description="a (persistence)", style=WIDE),
b=FloatSlider(value=1.0, min=0.0, max=2.0, step=0.25, description="b (constant)", style=WIDE));Show the code of the website version
# @title Website version: the difference equation with a precomputed slider for a (b = 1 - a, so x* stays at 1)
def difference_chart_web(a=0.8):
    """The website steps share one axis, so b = 1 - a keeps the steady state at x* = 1 for every a."""
    return difference_chart(a=a, b=round(1 - a, 2))

slider_figure(difference_chart_web, "a", [-0.8, -0.5, 0.0, 0.3, 0.5, 0.7, 0.8, 0.9], start=0.8, label="a (persistence)")
Source. Illustration of a first-order linear difference equation, the form of equations (5.7), (12.5) and (18.2) in Jones (2024), Macroeconomics, 6th ed.
Example 1: the bathtub model of unemployment
Each month a fraction \(\bar{s}\) of the employed lose their job and a fraction \(\bar{f}\) of the unemployed find one (Chapter 7). With the labor force normalized to 1, the unemployment rate follows \(u_{t+1}=u_t+\bar{s}(1-u_t)-\bar{f}u_t=(1-\bar{s}-\bar{f})\,u_t+\bar{s}\). That is our linear form with \(a=1-\bar{s}-\bar{f}\) and \(b=\bar{s}\), so the steady state is \(u^*=\bar{s}/(\bar{s}+\bar{f})\) (7.4). With the book’s monthly values \(\bar{s}=0.01\) and \(\bar{f}=0.20\):
s_job, f_job = 0.01, 0.20
u_path = simulate_linear(1 - s_job - f_job, s_job, 0.10, 12)          # start at 10 percent unemployment
print(f"Natural rate u* = {100 * s_job / (s_job + f_job):.2f}%")
print("Unemployment, months 0-12 (%):", (100 * u_path).round(2))
print(f"Half-life: {math.log(0.5) / math.log(1 - s_job - f_job):.1f} months")
Natural rate u* = 4.76%
Unemployment, months 0-12 (%): [10. 8.9 8.03 7.34 6.8 6.37 6.04 5.77 5.56 5.39 5.26 5.15
5.07]
Half-life: 2.9 monthsExample 2: the Solow model, a nonlinear difference equation
Capital per person follows \(k_{t+1}=k_t+\bar{s}\bar{A}k_t^{1/3}-\bar{d}k_t\) (5.7). This is not linear, but near the steady state it behaves like a linear equation whose \(a\) is the slope of the right-hand side at \(k^*\) (the Taylor approximation of Section C.6). SymPy computes that slope:
k, s_, d_ = sp.symbols("k s d", positive=True)
next_k = k + s_ * k ** sp.Rational(1, 3) - d_ * k                      # A = 1
k_star_formula = (s_ / d_) ** sp.Rational(3, 2)                        # equation (5.8)
slope_at_steady_state = sp.simplify(sp.diff(next_k, k).subs(k, k_star_formula))
slope_at_steady_state
\(\displaystyle 1 - \frac{2 d}{3}\)
The slope is \(1-\tfrac{2}{3}\bar{d}\). With \(\bar{d}=0.1\) it is about 0.933, so the gap to the steady state halves roughly every 10 years. A simulation from \(k_0=4\) confirms it:
k_values = [4.0]
for year in range(40):
    k_values.append(k_values[-1] + 0.4 * k_values[-1] ** (1 / 3) - 0.1 * k_values[-1])
k_values = np.array(k_values)
half_closed = np.argmax(8 - k_values <= 0.5 * (8 - 4.0))               # first year with half the gap closed
print(f"Linear approximation: half-life {math.log(0.5) / math.log(1 - 2 * 0.1 / 3):.1f} years")
print(f"Simulation: half of the gap is closed after {half_closed} years (k = {k_values[half_closed]:.2f})")
Linear approximation: half-life 10.0 years
Simulation: half of the gap is closed after 11 years (k = 6.00)Example 3: disinflation with the Phillips curve
Combine the Phillips curve \(\pi_t=\pi_{t-1}+\bar{\nu}\tilde{Y}_t\) (12.5) with the aggregate demand curve \(\tilde{Y}_t=-\bar{b}\bar{m}(\pi_t-\bar{\pi})\) (13.3, with \(\bar{a}=0\)). Solving the two for \(\pi_t\) gives a linear difference equation in inflation:
pi_t, nubar, bbar, mbar, pibar = sp.symbols("pi_t nubar bbar mbar pibar")
pi_prev = sp.Symbol(r"\pi_{t-1}")
inflation_next = sp.solve(sp.Eq(pi_t, pi_prev - nubar * bbar * mbar * (pi_t - pibar)), pi_t)[0]
sp.collect(sp.expand(inflation_next), pi_prev)
\(\displaystyle \frac{\pi_{t-1}}{\bar{b} \bar{m} \bar{\nu} + 1} + \frac{\bar{b} \bar{m} \bar{\nu} \bar{\pi}}{\bar{b} \bar{m} \bar{\nu} + 1}\)
The coefficient on \(\pi_{t-1}\) is \(a=1/(1+\bar{\nu}\bar{b}\bar{m})\), between 0 and 1, so inflation falls smoothly to the target \(\bar{\pi}\). With \(\bar{\nu}=\bar{b}=\bar{m}=0.5\), \(\bar{\pi}=2\) and inflation starting at 6 percent:
a_pi = 1 / (1 + 0.5 * 0.5 * 0.5)
inflation_path = simulate_linear(a_pi, (1 - a_pi) * 2, 6.0, 10)      # b = (1 - a) x pi_bar keeps x* = pi_bar
print(f"a = {a_pi:.3f}; inflation over 10 years (%):", inflation_path.round(2))
a = 0.889; inflation over 10 years (%): [6. 5.56 5.16 4.81 4.5 4.22 3.97 3.75 3.56 3.39 3.23]Example 4: the public debt ratio
The government budget constraint (18.2) says \(B_{t+1}=(1+i)B_t+D_t\), where \(B\) is the debt, \(i\) the nominal interest rate and \(D_t=G_t-T_t\) the primary deficit (spending other than interest, minus taxes). Divide both sides by next year’s GDP, \(Y_{t+1}=(1+g)Y_t\), where \(g\) is the growth rate of nominal GDP. With \(b_t=B_t/Y_t\) and \(d=D_t/Y_t\):
\[b_{t+1}=\frac{1+i}{1+g}\,b_t+\frac{d}{1+g}.\]
This is our linear form with \(a=(1+i)/(1+g)\). When the economy grows faster than the interest rate (\(g>i\)), \(a<1\) and the ratio settles at \(b^*=d/(g-i)\). When \(i>g\), \(a>1\) and the ratio keeps rising unless the government runs primary surpluses. The chart starts from the actual U.S. debt ratio of 2025.
debt = pd.read_csv(DATA_URL + "fig18-2.csv")
debt = debt.dropna(subset=["debt_public_gdp_pct"])           # the debt series starts in FY1940
debt_2025 = debt.loc[debt["year"] == 2025, "debt_public_gdp_pct"].iloc[0]
print(f"Federal debt held by the public, FY2025: {debt_2025:.1f}% of GDP")
debt.tail(3)
Federal debt held by the public, FY2025: 99.5% of GDP| year | surplus_gdp_pct | debt_public_gdp_pct | |
|---|---|---|---|
| 89 | 2023 | -6.2 | 95.8 |
| 90 | 2024 | -6.3 | 97.4 |
| 91 | 2025 | -5.9 | 99.5 |
def debt_chart(i=3.5, g=4.0, d=2.5):
    """The debt ratio b_{t+1} = (1 + i)/(1 + g) b_t + d/(1 + g) from 2025 to 2055 (from equation 18.2)."""
    path = simulate_linear((1 + i / 100) / (1 + g / 100), d / (1 + g / 100), debt_2025, 30)
    top = 2000.0
    for candidate in [200.0, 400.0, 1000.0, 2000.0]:          # widen the axis in steps, only when needed
        if path.max() * 1.05 <= candidate:
            top = candidate
            break
    fig = go.Figure()
    fig.add_trace(go.Scatter(x=debt["year"], y=debt["debt_public_gdp_pct"], mode="lines", name="actual, 1940–2025",
                             line=dict(color=GRAY, width=3)))
    fig.add_trace(go.Scatter(x=np.arange(2025, 2056), y=path, mode="lines", name="simulation, 2025–2055",
                             line=dict(color=TEAL, width=3)))
    if g > i:
        ending = f"steady state {round(100 * d / (g - i)) + 0}%"    # b* = d / (g - i), with rates in percent
    else:
        ending = "no stable steady state (i ≥ g)"
    fig.update_layout(title=f"i = {i:.1f}%, g = {g:.1f}%, d = {d:.1f}%: {round(path[-1]) + 0}% of GDP in 2055; {ending}",
                      xaxis=dict(title="", range=[1940, 2055], tickvals=[1950, 1970, 1990, 2010, 2030, 2050]),
                      yaxis=dict(title="debt held by the public (% of GDP)", range=[-50 if path.min() < 0 else 0, top]),
                      legend=dict(x=0.02, y=0.98))
    return fig
interact(debt_chart,
i=FloatSlider(value=3.5, min=0.0, max=8.0, step=0.5, description="interest rate i (%)", style=WIDE),
g=FloatSlider(value=4.0, min=0.0, max=8.0, step=0.5, description="nominal GDP growth g (%)", style=WIDE),
d=FloatSlider(value=2.5, min=-2.0, max=6.0, step=0.5, description="primary deficit d (% of GDP)", style=WIDE));Show the code of the website version
# @title Website version: the debt ratio with a precomputed slider for the primary deficit
slider_figure(debt_chart, "d", [-2.0, -1.0, 0.0, 1.0, 2.0, 2.5, 3.0, 3.5], start=2.5,
              label="primary deficit d (% of GDP)")
Sources. Data: U.S. Office of Management and Budget, Historical Tables, Table 7.1 (federal debt at the end of the year). Prepared file: data/appC/fig18-2.csv (see the data notes). Simulation: illustration of the government budget constraint, equation (18.2) in Jones (2024), with our own illustrative values for \(i\), \(g\) and \(d\); the historical line is inspired by Fig. 18.2 in Jones (2024), Macroeconomics, 6th ed.
What to notice.
- In the difference-equation chart, a value of \(a\) close to 1 means a slow approach and a large steady state; a negative \(a\) makes the path zigzag around \(x^*\).
- The bathtub model converges in a few months, the Solow model in decades: the half-life tells you which equations describe the short run and which the long run.
- In the debt chart, the gap between \(g\) and \(i\) matters as much as the deficit. With \(g\) only half a point above \(i\), a primary deficit of 2.5 percent of GDP has a steady state of 500 percent: the ratio keeps rising for decades. Set \(i\) above \(g\) and even a balanced primary budget (\(d=0\)) makes the ratio grow.
Your turn. With \(i=3.5\) and \(g=4\), which primary balance keeps the debt ratio at its 2025 level? Use the steady-state formula \(b^*=d/(g-i)\), then check with debt_chart.
Hint
Set \(b^*\) equal to the 2025 ratio and solve for \(d\): \(d=b^*(g-i)/100\) when \(b^*\) is in percent. It is a small primary deficit, about half a percent of GDP.
# Your turn: try it hereC.11 Continuous time and differential equations
Goal. Read the continuous-time notation of more advanced books, prove the growth rules, and solve a differential equation with SymPy and SciPy.
The book counts time in periods \(t=0,1,2,\dots\), but many advanced books let time flow continuously. Then the change \(\Delta x_{t+1}\) becomes the time derivative \(\dot{x}\equiv dx/dt\), and the growth rate becomes \(\dot{x}/x\). A neat fact: the growth rate is the time derivative of the log, \(\dot{x}/x=d\ln x/dt\) (by the chain rule, since \(d\ln x/dx=1/x\)). With it, the growth rules of Section C.5 become exact:
t = sp.symbols("t")
x_t = sp.Function("x", positive=True)(t)
y_t = sp.Function("y", positive=True)(t)
a = sp.symbols("a")

def growth_rate(z):
    """The continuous-time growth rate of z(t): the time derivative of its log."""
    return sp.simplify(sp.diff(sp.expand_log(sp.log(z), force=True), t))

print("product:", growth_rate(x_t * y_t))
print("ratio:  ", growth_rate(x_t / y_t))
print("power:  ", growth_rate(x_t ** a))
product: Derivative(y(t), t)/y(t) + Derivative(x(t), t)/x(t)
ratio: -Derivative(y(t), t)/y(t) + Derivative(x(t), t)/x(t)
power: a*Derivative(x(t), t)/x(t)Derivative(x(t), t)/x(t) is \(\dot{x}/x=g_x\): the growth of a product is the sum of the growth rates, with no term dropped.
A differential equation links a variable to its own time derivative. The simplest one is constant growth, \(\dot{y}=g\,y\). sp.dsolve solves it:
y = sp.Function("y")
g, y0 = sp.symbols("g y_0", positive=True)
sp.dsolve(sp.Eq(y(t).diff(t), g * y(t)), y(t), ics={y(0): y0})
\(\displaystyle y{\left(t \right)} = y_{0} e^{g t}\)
That is the continuous version of (3.7): \(y_t=y_0e^{gt}\).
The Solow model in continuous time
In continuous time, capital accumulation reads \(\dot{k}=\bar{s}\bar{A}k^{1/3}-\bar{d}k\). Most differential equations of this kind are solved numerically. integrate.solve_ivp (“solve an initial value problem”) takes a function that returns \(\dot{k}\), the time span and the starting value, and returns the path.
def k_dot(t, k):
    """Continuous-time Solow model: dk/dt = s A k^(1/3) - d k with s = 0.4, A = 1, d = 0.1."""
    return 0.4 * k ** (1 / 3) - 0.1 * k

years_solow = np.arange(0, 61)
continuous = integrate.solve_ivp(k_dot, t_span=(0, 60), y0=[1.0], t_eval=years_solow)
discrete = [1.0]
for year in range(60):
    discrete.append(discrete[-1] + 0.4 * discrete[-1] ** (1 / 3) - 0.1 * discrete[-1])
print(f"Year 20: discrete k = {discrete[20]:.2f}, continuous k = {continuous.y[0][20]:.2f}")
Year 20: discrete k = 5.80, continuous k = 5.75time_fig = go.Figure()
time_fig.add_trace(go.Scatter(x=years_solow, y=discrete, mode="lines+markers", name="discrete time (one step a year)",
line=dict(color=BLUE, width=2), marker=dict(size=5)))
time_fig.add_trace(go.Scatter(x=years_solow, y=continuous.y[0], mode="lines", name="continuous time (solve_ivp)",
line=dict(color=TEAL, width=3)))
time_fig.add_trace(go.Scatter(x=[0, 60], y=[8, 8], mode="lines", name="steady state k* = 8", line=dict(color=GRAY, dash="dash")))
time_fig.update_layout(title=f"Both versions approach k* = 8; in year 20, k = {discrete[20]:.2f} (discrete) and "
f"{continuous.y[0][20]:.2f} (continuous)",
xaxis=dict(title="years", range=[0, 60]), yaxis=dict(title="capital per person, k", range=[0, 9], tickvals=[2, 4, 6, 8]),
legend=dict(x=0.99, xanchor="right", y=0.02, yanchor="bottom"))
time_figSource. Illustration of the Solow model’s capital accumulation equation (5.7) in Jones (2024), Macroeconomics, 6th ed., and of its continuous-time version.
What to notice.
- The two paths are close and reach the same steady state: the choice between discrete and continuous time is mostly one of convenience.
- The discrete path runs slightly ahead after the first few years. It adds a whole year of net investment at the rate of the start of the year; in continuous time that rate is updated at every instant, and it falls as diminishing returns set in.
Your turn. Solve the continuous-time Solow model with an investment rate of \(\bar{s}=0.3\). What is the new steady state, and how far is \(k\) from it after 20 years?
Hint
Copy k_dot under a new name with 0.3 instead of 0.4, and call integrate.solve_ivp again. The steady state is \((0.3/0.1)^{3/2}\approx 5.2\).
# Your turn: try it hereC.12 Present value and discounting
Goal. Value payments that arrive in the future, with the formulas of Chapters 7, 16 and 17, and with Python.
A dollar today is worth more than a dollar next year, because a dollar today can be saved at the interest rate \(R\). So the present discounted value (pdv) of a payment \(X\) that arrives in \(T\) years is
\[pdv=\frac{X}{(1+R)^T}. \qquad (7.6)\]
The pdv of a stream of payments is the sum of the pdv of each payment (7.10). For a stream of equal payments, the sum is a geometric series, which has a closed form (7.12):
\[1+a+a^2+\dots+a^n=\frac{1-a^{n+1}}{1-a}.\]
SymPy proves it, and also sums the series to infinity:
a = sp.symbols("a", positive=True)
n, j = sp.symbols("n j", integer=True, nonnegative=True)
R = sp.symbols("R", positive=True)
print("Finite sum:  ", sp.summation(a ** j, (j, 0, n)))
print("Perpetuity:  ", sp.simplify(sp.summation(1 / (1 + R) ** j, (j, 0, sp.oo))), " (payments of 1 from today on)")
Finite sum: Piecewise((n + 1, Eq(a, 1)), ((1 - a**(n + 1))/(1 - a), True))
Perpetuity: (R + 1)/R (payments of 1 from today on)Python note.
sp.summation(term, (j, 0, n))adds uptermforjfrom 0 ton;sp.oo(two letters o) is infinity. APiecewiseresult lists answers for different cases: here, the special case \(a=1\), where all terms equal 1.
Human capital: the value of a working life
Chapter 7 values a working life of 45 years with an income of 100,000 dollars a year, discounted at \(R=3\) percent (7.15). We recompute the book’s 2.53 million dollars (7.16) with the formula and with a NumPy sum:
R_value, years_working, wage = 0.03, 45, 100_000
by_formula = wage * (1 - (1 / (1 + R_value)) ** years_working) / (1 - 1 / (1 + R_value))   # (7.15)
by_sum = np.sum(wage / (1 + R_value) ** np.arange(0, years_working))                     # payments in years 0-44
print(f"Formula: {by_formula:,.0f} dollars;  sum of 45 discounted payments: {by_sum:,.0f} dollars")
Formula: 2,525,427 dollars; sum of 45 discounted payments: 2,525,427 dollarsInteractive: the present value of a stream
Twenty yearly payments of 100, the first one today (the stream of equation 7.11). The light bars are the payments; the dark bars are what each one is worth today.
def pv_chart(R=5.0):
    """Present values of 20 yearly payments of 100, the first one today (equation 7.11), at R percent."""
    years_pv = np.arange(0, 20)
    values = 100 / (1 + R / 100) ** years_pv
    fig = go.Figure()
    fig.add_trace(go.Bar(x=years_pv, y=np.full(20, 100.0), name="payment", marker_color="#d5dde6"))
    fig.add_trace(go.Bar(x=years_pv, y=values, name="present value", marker_color=TEAL))
    fig.update_layout(barmode="overlay", title=f"R = {R:.1f}%: the 20 payments of 100 are worth {values.sum():,.0f} today",
                      xaxis=dict(title="year of the payment", range=[-0.6, 19.6]),
                      yaxis=dict(title="value", range=[0, 110]), legend=dict(orientation="h", x=0, y=1.02, yanchor="bottom"))
    return fig
interact(pv_chart, R=FloatSlider(value=5.0, min=0.0, max=15.0, step=0.5, description="interest rate R (%)", style=WIDE));Show the code of the website version
# @title Website version: the present-value chart with a precomputed slider for the interest rate
slider_figure(pv_chart, "R", [0.0, 1.0, 2.0, 3.0, 5.0, 7.0, 10.0, 15.0], start=5.0, label="interest rate R (%)")
Source. Illustration of the present discounted value of a stream of payments, equations (7.10)–(7.14) in Jones (2024), Macroeconomics, 6th ed.
Bonds, stocks and investment projects
Bond prices. A bond that pays 100 dollars in 10 years is worth \(100/(1+i)^{10}\) today. When interest rates rise, the prices of existing bonds fall, which is why rate hikes hurt bondholders (Chapters 12 and 14).
for i_bond in [0.02, 0.04, 0.06]:
    print(f"i = {100 * i_bond:.0f}%: a 10-year bond paying 100 costs {100 / (1 + i_bond) ** 10:.1f} today")
i = 2%: a 10-year bond paying 100 costs 82.0 today
i = 4%: a 10-year bond paying 100 costs 67.6 today
i = 6%: a 10-year bond paying 100 costs 55.8 todayStocks. A stock pays a dividend that grows at rate \(g\). Its pdv is a growing perpetuity: summing \(D(1+g)^j/(1+R)^{j}\) gives \(P=D(1+R)/(R-g)\) when the first dividend is paid today, or \(P=D/(R-g)\) when it is paid a year from now. Chapter 17 reaches the same form from an arbitrage argument (17.16): the price is the dividend divided by the interest rate minus the capital gain. Turned around, the dividend yield \(D/P\) equals \(R-g\). If firms paid out all their earnings, the earnings yield \(E/P\), the inverse of the price-earnings ratio, would be \(R-g\): a low earnings yield means investors accept a low \(R\) or expect fast growth (17.17).
cape = pd.read_csv(DATA_URL + "fig17-3.csv", parse_dates=["date"])
cape["earnings_yield"] = 100 / cape["cape"]                  # percent: earnings per 100 dollars of stock
latest = cape.iloc[-1]
yield_fig = px.line(cape, x="date", y="earnings_yield",
                    labels={"date": "", "earnings_yield": "earnings yield, 1/CAPE (percent)"},
                    title=f"U.S. earnings yield: {latest['earnings_yield']:.1f}% in {latest['date']:%B %Y}, "
                          f"versus {cape['earnings_yield'].mean():.1f}% on average since 1881")
yield_fig.add_hline(y=cape["earnings_yield"].mean(), line_color=GRAY, line_dash="dash")
yield_fig
Sources. Data: Robert Shiller, Online Data (ie_data.xls), cyclically adjusted price-earnings ratio of the S&P composite. Prepared file: data/appC/fig17-3.csv (see the data notes). Chart: inspired by Fig. 17.3 in Jones (2024), Macroeconomics, 6th ed.
Investment projects. A project costs 100 today and pays 12 a year for 10 years. Its net present value (NPV) is the pdv of the payments minus the cost; it is worth doing when the NPV is positive. The internal rate of return (IRR) is the interest rate at which the NPV is zero, which brentq finds:
def npv(rate):
    """Net present value of a project that costs 100 today and pays 12 a year in years 1-10."""
    return -100 + np.sum(12 / (1 + rate) ** np.arange(1, 11))

print(f"NPV at 3%: {npv(0.03):.2f};  NPV at 5%: {npv(0.05):.2f}")
print(f"Internal rate of return: {100 * optimize.brentq(npv, 0.0001, 0.5):.2f}%")
NPV at 3%: 2.36; NPV at 5%: -7.34
Internal rate of return: 3.46%What to notice.
- At \(R=0\) the 20 payments are worth 2,000; at 5 percent about 1,300; at 15 percent about 720. Distant payments lose the most value.
- The earnings yield moves inversely with stock prices: it was high around 1920, in 1932 and in the early 1980s, when stocks were cheap, and it was low around 2000, in 2021 and again now.
- The project pays if the interest rate is below its internal rate of return of about 3.5 percent. This is the logic of Chapter 17: higher interest rates make fewer investment projects worthwhile.
Your turn. Recompute the value of the working life of Chapter 7 when wages grow 1 percent a year. The payment in year \(j\) is then \(100{,}000 \times 1.01^j\).
Hint
Multiply each payment by 1.01 ** np.arange(0, 45) before discounting. The value rises to about 3.0 million dollars: wage growth works like a lower interest rate, about \(R-g\).
# Your turn: try it hereC.13 Describing macro data: averages, volatility, trends and cycles
Goal. Summarize a series with a few numbers, measure how two series move together, and separate a long-run trend from short-run fluctuations.
Averages and volatility
The mean is the average, the median the middle value, and the standard deviation measures how much a series moves around its mean, its volatility. pandas computes them all with .describe().
growth_stats = nipa[nipa["year"] >= 1930][["year", "g_real"]]
print(growth_stats["g_real"].describe().round(2))
early = growth_stats[growth_stats["year"].between(1950, 1984)]["g_real"]
late = growth_stats[growth_stats["year"].between(1985, 2025)]["g_real"]
print(f"Standard deviation of real GDP growth: {early.std():.2f} points in 1950-1984, {late.std():.2f} in 1985-2025")
count 96.00
mean 3.28
std 4.74
min -12.90
25% 1.87
50% 3.04
75% 4.97
max 18.89
Name: g_real, dtype: float64
Standard deviation of real GDP growth: 2.78 points in 1950-1984, 1.66 in 1985-2025Real GDP growth became much less volatile after the mid-1980s, a change economists call the Great Moderation (Chapter 13 discusses one explanation, better monetary policy), though the 2008–2009 and 2020 recessions interrupted it.
Correlation: the Phillips curve in the data
The correlation coefficient measures how closely two series move together, from \(-1\) (exactly opposite) to \(+1\) (exactly together). The Phillips curve \(\Delta\pi_t=\bar{\nu}\tilde{Y}_t\) (12.6) predicts that inflation rises when output is above potential. A least-squares line fitted through the points estimates the slope \(\bar{\nu}\).
gap_inflation = potential[["year", "gap_percent"]].merge(cpi[["year", "inflation"]], on="year")
gap_inflation["change_in_inflation"] = gap_inflation["inflation"].diff()
gap_inflation = gap_inflation[gap_inflation["year"] >= 1950]
correlation = gap_inflation["gap_percent"].corr(gap_inflation["change_in_inflation"])
slope, intercept = np.polyfit(gap_inflation["gap_percent"], gap_inflation["change_in_inflation"], 1)
print(f"Correlation: {correlation:.2f};  fitted slope ν = {slope:.2f}")
Correlation: 0.37; fitted slope ν = 0.34Python note.
.merge(other, on="year")joins two tables row by row on the year.np.polyfit(x, y, 1)fits a straight line \(y=\text{slope}\cdot x+\text{intercept}\) by least squares and returns the two numbers.
phillips_fig = px.scatter(gap_inflation, x="gap_percent", y="change_in_inflation", hover_name="year",
                          trendline="ols", trendline_color_override=TEAL,
                          labels={"gap_percent": "short-run output, Ỹ (percent)",
                                  "change_in_inflation": "change in CPI inflation (points)"},
                          title=f"U.S. 1950–2025: inflation tends to rise when output is above potential "
                                f"(corr. {correlation:.2f})")
phillips_fig
Sources. Data: U.S. Bureau of Economic Analysis, Real Gross Domestic Product (GDPCA), via FRED; Congressional Budget Office, Real Potential Gross Domestic Product (GDPPOT), via FRED; MeasuringWorth, The Annual Consumer Price Index for the United States. Prepared files: data/appC/fig9-2.csv and data/appC/us_cpi.csv (see the data notes). Chart: inspired by Fig. 9.6 in Jones (2024), Macroeconomics, 6th ed.; our own chart, built from updated data.
Trend and cycle
Chapter 9 splits GDP into a long-run trend (potential output \(\bar{Y}_t\)) and short-run fluctuations (\(\tilde{Y}_t\)). Potential output cannot be observed, so it has to be estimated. Two simple statistical methods:
- A straight line through the logs. Fit \(\ln y_t=\alpha+\beta t\). The slope \(\beta\) is the trend growth rate (in log points), and the distance to the line is the cycle.
- The Hodrick–Prescott (HP) filter. It draws a smooth curve through the data, trading off closeness to the data against smoothness. The parameter \(\lambda\) sets the smoothness; 100 is a common choice for annual data. It lives in
statsmodels, a statistics library that comes with Colab.
trend_slope, trend_intercept = np.polyfit(gdp_pc["year"], np.log(gdp_pc["gdppc"]), 1)
print(f"Trend growth of U.S. GDP per person, 1870-2025: {100 * trend_slope:.2f} log points a year")

from statsmodels.tsa.filters.hp_filter import hpfilter      # imported here, where we first use it
postwar = potential[potential["year"] >= 1950].copy()
cycle, trend = hpfilter(np.log(postwar["gdp_actual"]), lamb=100)
postwar["gap_hp"] = 100 * cycle                              # percent deviation from the HP trend
print(f"Correlation of the HP gap with the CBO gap: {postwar['gap_hp'].corr(postwar['gap_log']):.2f}")
Trend growth of U.S. GDP per person, 1870-2025: 1.95 log points a year
Correlation of the HP gap with the CBO gap: 0.80gaps_long = postwar.melt(id_vars="year", value_vars=["gap_log", "gap_hp"], var_name="method", value_name="gap")
gaps_long["method"] = gaps_long["method"].map({"gap_log": "CBO potential output", "gap_hp": "HP filter (λ = 100)"})
gaps_fig = px.line(gaps_long, x="year", y="gap", color="method",
labels={"year": "", "gap": "output gap (percent of trend)"},
title="Two estimates of the U.S. output gap move together, but differ in size")
gaps_fig.add_hline(y=0, line_color=GRAY, line_width=1)
gaps_fig.update_layout(legend_title_text="", legend=dict(x=0.99, xanchor="right", y=0.02, yanchor="bottom"))
gaps_figSources. Data: U.S. Bureau of Economic Analysis, Real Gross Domestic Product (GDPCA), via FRED; Congressional Budget Office, Real Potential Gross Domestic Product (GDPPOT), via FRED. Prepared file: data/appC/fig9-2.csv (see the data notes). Chart: inspired by Fig. 9.3 in Jones (2024), Macroeconomics, 6th ed.
What to notice.
- The fitted trend, about 2 log points a year, is close to the average growth rate of Section C.4.
- The points of the Phillips-curve scatter are widely spread, so the correlation is positive but far from 1: other forces, such as oil prices and expectations, also move inflation (Chapters 12 and 13).
- The HP gap and the CBO gap rise and fall together, but the HP trend follows the data more closely, so its gaps are smaller and it sees less of a slump after 2008. Every estimate of potential output is a model, not a fact.
Your turn. Recompute the HP gap with a much smoother trend, \(\lambda=6{,}400\), and with a very flexible one, \(\lambda=10\). How does the volatility of the gap (its standard deviation) change?
Hint
Call hpfilter(np.log(postwar["gdp_actual"]), lamb=6400) and compute (100 * cycle).std() for each value of \(\lambda\). A smoother trend (larger \(\lambda\)) leaves more of the movement to the cycle.
# Your turn: try it hereC.14 A formula sheet
| Tool | Formula | Python | Used in |
|---|---|---|---|
| Percent change | \(100(x_1-x_0)/x_0\) | 100 * s.pct_change() |
Ch. 2, 8 |
| Rebase an index | \(100\,x_t/x_{\text{base}}\) | 100 * s / s_base |
Ch. 2, 8 |
| Annualize a monthly change | \((1+m)^{12}-1\) | (1 + m) ** 12 - 1 |
Ch. 8, 12 |
| Constant growth | \(y_t=y_0(1+\bar{g})^t\) (3.7) | y0 * (1 + g) ** t |
Ch. 3, 5, 6 |
| Average annual growth | \(\bar{g}=(y_T/y_0)^{1/T}-1\) (3.9) | (yT / y0) ** (1 / T) - 1 |
Ch. 3, 5 |
| Rule of 70 | doubling time \(\approx 70/g\) | np.log(2) / np.log(1 + g) (exact) |
Ch. 3 |
| Log rules | \(\ln(xy)=\ln x+\ln y\), \(\ln x^a=a\ln x\) | sp.expand_log(...) |
Ch. 3, 5 |
| Growth rules | \(g_{xy}=g_x+g_y\), \(g_{x/y}=g_x-g_y\), \(g_{x^a}=a\,g_x\) | growth_rate(z) (C.11) |
Ch. 3, 4, 6, 8 |
| Fisher equation | \(R=(1+i)/(1+\pi)-1 \approx i-\pi\) (8.6) | (1 + i) / (1 + pi) - 1 |
Ch. 8, 12 |
| Log approximation | \(\ln(1+x)\approx x\) | sp.series(sp.log(1 + x), x, 0, 3) |
Ch. 3, 9 |
| Derivative | \(\frac{d}{dx}x^n=nx^{n-1}\) | sp.diff(f, x), np.gradient(y, x) |
Ch. 4, 16, 17 |
| Elasticity | \((\partial Y/\partial K)(K/Y)\) | sp.simplify(sp.diff(Y, K) * K / Y) |
Ch. 4 |
| Optimum | \(f'(x^*)=0\) | sp.solve(sp.diff(f, x), x), optimize.minimize_scalar |
Ch. 4, 16 |
| Linear system | \(Mz=c\) | np.linalg.solve(M, c), sp.solve([...]) |
Ch. 11–13 |
| Root of an equation | \(f(x)=0\) | optimize.brentq(f, low, high) |
Ch. 5, 7 |
| Difference equation | \(x_{t+1}=ax_t+b\), \(x^*=b/(1-a)\), stable if \(\lvert a\rvert<1\) | a for loop; sp.rsolve |
Ch. 5, 7, 12, 13, 18 |
| Half-life | \(\ln 0.5/\ln\lvert a\rvert\) | math.log(0.5) / math.log(abs(a)) |
Ch. 5, 7 |
| Debt dynamics | \(b_{t+1}=\frac{1+i}{1+g}b_t+\frac{d}{1+g}\), \(b^*=d/(g-i)\) | simulate_linear(...) |
Ch. 18 |
| Differential equation | \(\dot{k}=f(k)\) | integrate.solve_ivp(f, (0, T), [k0]) |
Ch. 15 and beyond |
| Present value | \(X/(1+R)^T\) (7.6) | X / (1 + R) ** T |
Ch. 7, 16, 17, 18 |
| Geometric sum | \(\sum_{j=0}^{n}a^j=\frac{1-a^{n+1}}{1-a}\) (7.12) | sp.summation(a**j, (j, 0, n)) |
Ch. 7 |
| Growing perpetuity | \(P=D/(R-g)\) (17.16) | D / (R - g) |
Ch. 17 |
| Internal rate of return | NPV\((r)=0\) | optimize.brentq(npv, low, high) |
Ch. 17 |
| Trend and cycle | \(\ln y_t=\alpha+\beta t\); HP filter | np.polyfit(t, np.log(y), 1), hpfilter(...) |
Ch. 9 |
Where to learn more
- SymPy: the SymPy tutorial, with sections on solving, calculus and simplification.
- SciPy: the SciPy user guide, in particular Optimization and Integration.
- NumPy: NumPy: the absolute basics for beginners.
- statsmodels: the time-series filters and the regression tools.
- Math and economics in Python: the QuantEcon lectures Python Programming for Economics and Finance and A First Course in Quantitative Economics with Python, which cover difference equations, present values and the Solow model with code.
Concluding remarks
- Most of the math in macroeconomics is about growth and change: percent changes, compound growth, logs, growth rates and the growth rules, and the approximations that make them simple. They work well for the small rates of normal times and break down in high inflation.
- Derivatives give marginal products, elasticities and the first-order conditions of firms and households. Systems of equations give equilibria, and difference equations describe how capital, unemployment, inflation and public debt move from one year to the next; their stability depends on whether \(|a|<1\).
- Present value turns streams of future payments into one number today: the value of a working life, a bond, a stock or an investment project.
- Python offers three complementary ways to do this math: NumPy computes, SymPy does the algebra and calculus with letters, and SciPy solves, optimizes and simulates when there is no formula.
- Every chapter of this book uses these tools. When an equation in a chapter looks hard, come back to the section of this appendix that covers it, and try it in code.