# Libraries used in this appendix
import math                                     # math on single numbers
import numpy as np                              # numbers and arrays
import pandas as pd                             # data tables
import plotly.express as px                     # quick charts from data tables
import plotly.graph_objects as go               # charts built piece by piece
import plotly.io as pio
from plotly.subplots import make_subplots       # several panels in one chart
import statsmodels.formula.api as smf           # regressions written as formulas
from ipywidgets import interact, FloatSlider, ToggleButtons, Dropdown

# One light blue/green look for every chart
BLUE, TEAL, GREEN, GRAY, RUST = "#16528c", "#008070", "#7fb23a", "#8a96a3", "#c4651a"
pio.templates.default = "plotly_white"
pio.templates["plotly_white"].layout.update(width=860, height=480)   # same size in Colab and on the website
px.defaults.color_discrete_sequence = [BLUE, TEAL, GREEN, RUST, "#8e5ea2", "#5aa0d8", "#0b4f47"]
WIDE = {"description_width": "initial"}         # show the full widget labels

# Colab only: let Plotly charts appear inside the interactive widgets
try:
    import google.colab
    google.colab.output.enable_custom_widget_manager()
except ImportError:
    pass                                        # not running in Colab: nothing to do

# The data files of this appendix live in the book's GitHub repository
DATA_URL = "https://raw.githubusercontent.com/quarcs-lab/macro102-site/main/data/appF/"F. Augmented Solow Growth Model
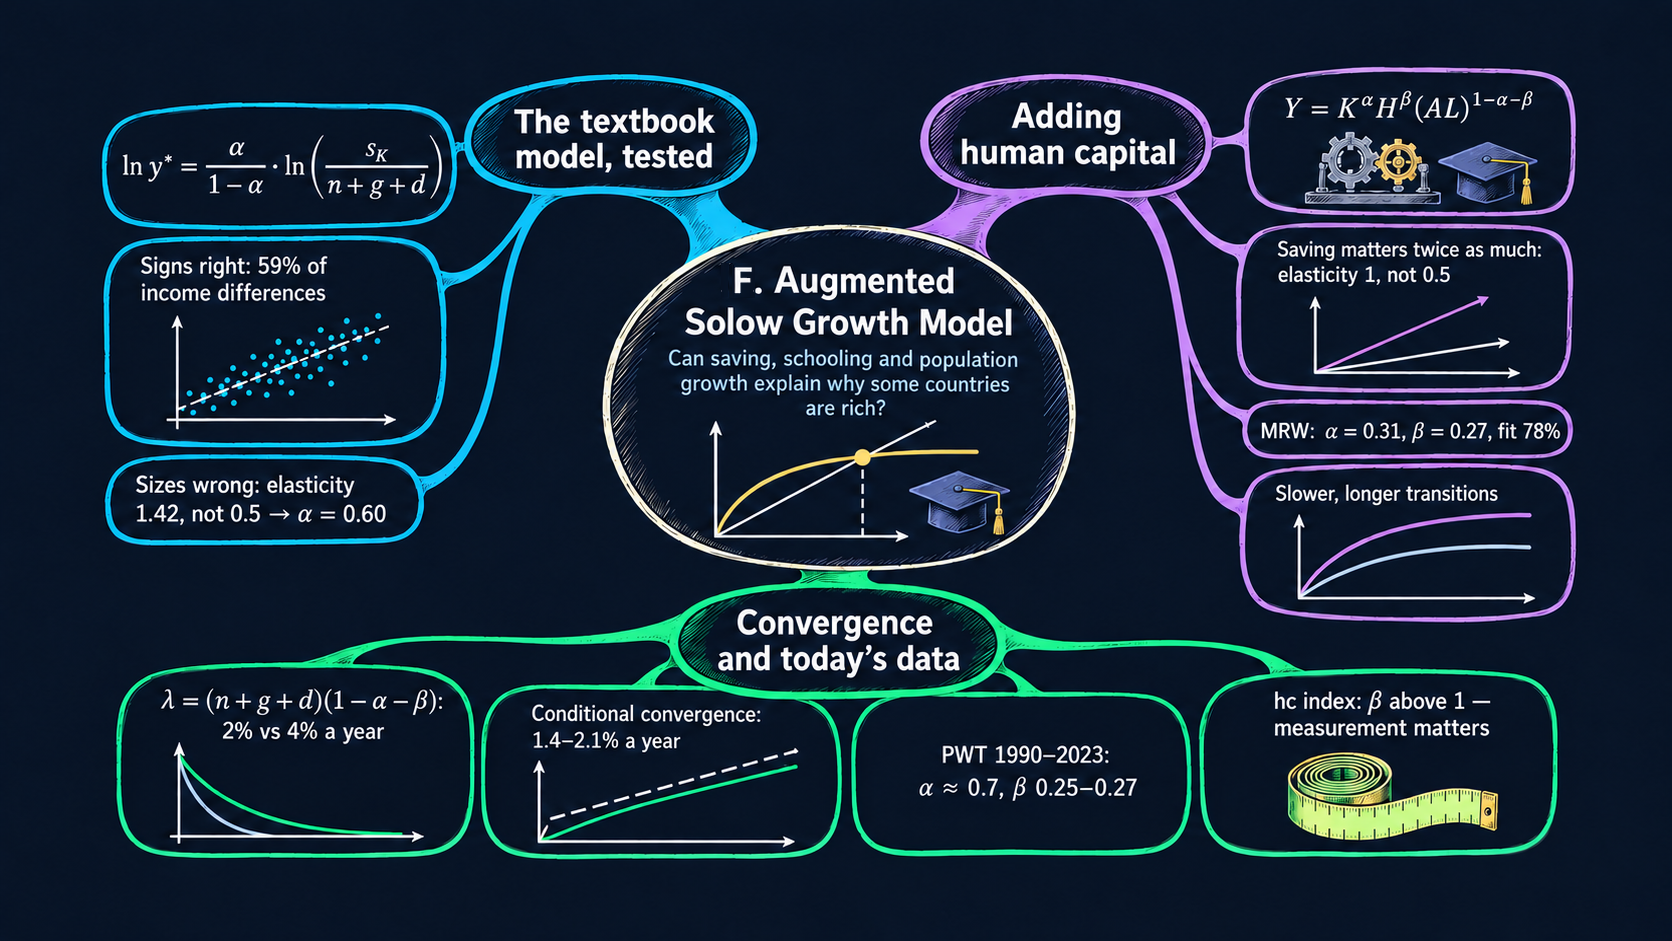


Learning goals
Can a model as simple as Solow’s explain why some countries are rich and others poor? In a famous paper, Mankiw, Romer and Weil (1992), “MRW” from now on, answered: almost, once the model counts human capital, the skills that workers build up through schooling, as well as machines. This appendix rebuilds their argument step by step, runs their regressions on their own data, and then asks whether the answer still holds with today’s data. By the end of it you will be able to:
- derive the steady-state income equation of the textbook Solow model and turn it into a regression of income on the investment rate and population growth;
- derive the steady state of the augmented Solow model, with physical and human capital, in its two forms: with the investment rate in human capital, and with its level;
- estimate both models with OLS in statsmodels, test the restrictions that the theory puts on the coefficients, and recover the capital shares that the estimates imply;
- explain conditional convergence, derive the speed of convergence of the augmented model, and estimate it from growth regressions;
- use interactive simulations to see why human capital makes saving matter more and slows convergence;
- rebuild MRW’s variables from the Penn World Table 11.0 and the World Bank, and check whether their results survive with new data, new countries and a new period.
A map of the appendix
| Section | What you do | Builds on |
|---|---|---|
| F.1 | The question: can saving and population growth explain income? | Chapters 4 and 5 |
| F.2 | Set up the libraries and the regression tools | Appendix A |
| F.3 | Meet MRW’s data | Chapter 3 |
| F.4 | Derive the textbook Solow model’s income equation | Chapter 5, Appendix C.5 |
| F.5 | Test the textbook model | — |
| F.6 | Add human capital: derive the augmented model | Chapter 5 |
| F.7 | Simulation: the steady state with human capital | — |
| F.8 | Test the augmented model | — |
| F.9 | Simulation: the transition after a rise in investment | Chapter 5 |
| F.10 | Convergence: the theory and its speed | Appendix E |
| F.11 | Convergence in MRW’s data | Appendix E |
| F.12 | Simulation: catch-up between two countries | — |
| F.13 | Do MRW’s results hold today? | Appendix D |
| F.14 | Go further | — |
The regressions of Sections F.5, F.8 and F.11 replicate Tables I to VI of MRW. Section F.13 repeats them with the Penn World Table 11.0 and the World Bank’s World Development Indicators.
F.1 Why augment the Solow model?
The Solow model of Chapter 5 says that a country’s income in the long run depends on a few numbers: how much it invests, how fast its population grows, how fast capital wears out, and its technology. Countries differ a lot in the first two. So a natural test of the model is to ask: do countries that invest more and whose populations grow more slowly have higher incomes, and by as much as the model says?
MRW ran this test on 98 countries in 1985. They found three things, which this appendix reproduces:
- The signs are right, the sizes are not. Countries that invest more are richer, and countries with fast population growth are poorer. But the effects in the data are about twice as large as the textbook model predicts with a capital share of one third.
- Human capital fixes the sizes. When workers’ skills are counted as a second kind of capital, the model predicts larger effects, and it explains about 80 percent of the differences in income across countries.
- Convergence is conditional. Poor countries do not grow faster than rich ones in general. But they do once we hold constant the things that set each country’s steady state, and at about the speed the augmented model predicts: some 2 percent of the gap closes each year.
The appendix fits between two others. Appendix D splits income gaps into capital, schooling and productivity without a theory of where capital comes from; here the Solow model supplies that theory. Appendix E studies convergence in depth; Section F.10 adds human capital to its speed of convergence.
F.2 Setup
The setup cell loads the libraries and sets the look of the charts. One library is new compared with the chapters: statsmodels, which runs regressions and reports standard errors and tests, as a statistics package does. It comes with Colab, so there is nothing to install.
Show the helper code
# @title Helper for the website versions with a slider (run this cell; you do not need to read it)
def slider_figure(make_figure, name, values, start, label=None):
    """Precompute make_figure(name=value) for every value and join the results with one slider.

    The website cannot run Python, so each interactive figure also gets this precomputed version.
    """
    figures = [make_figure(**{name: v}) for v in values]
    first = values.index(start)
    fig = go.Figure(layout=figures[first].layout)
    owner = []                                  # which precomputed figure each trace comes from
    for i, f in enumerate(figures):
        for trace in f.data:
            trace.visible = (i == first)
            fig.add_trace(trace)
            owner.append(i)
    steps = []
    for i, f in enumerate(figures):
        layout = {"title": f.layout.title.to_plotly_json(),
                  "annotations": [a.to_plotly_json() for a in f.layout.annotations],
                  "shapes": [s.to_plotly_json() for s in f.layout.shapes]}
        visible = [o == i for o in owner]
        steps.append(dict(method="update", label=str(values[i]), args=[{"visible": visible}, layout]))
    fig.update_layout(sliders=[dict(active=first, steps=steps, pad=dict(t=60),
                                    currentvalue=dict(prefix=(label or name) + " = "))])
    return fig
Show the helper code
# @title Helper for the website versions with buttons (run this cell; you do not need to read it)
def button_figure(make_figure, name, values, start):
    """Like slider_figure, but with one button per value, in a row above the chart; each button also sets the y-axis."""
    figures = [make_figure(**{name: v}) for v in values]
    first = values.index(start)
    fig = go.Figure(layout=figures[first].layout)
    owner = []
    for i, f in enumerate(figures):
        for trace in f.data:
            trace.visible = (i == first)
            fig.add_trace(trace)
            owner.append(i)
    buttons = []
    for i, f in enumerate(figures):
        layout = {"title": f.layout.title.to_plotly_json(), "yaxis": f.layout.yaxis.to_plotly_json(),
                  "annotations": [a.to_plotly_json() for a in f.layout.annotations],
                  "shapes": [s.to_plotly_json() for s in f.layout.shapes]}
        visible = [o == i for o in owner]
        buttons.append(dict(label=str(values[i]), method="update", args=[{"visible": visible}, layout]))
    fig.update_layout(updatemenus=[dict(type="buttons", direction="right", buttons=buttons, active=first,
                                        x=0, y=1.02, xanchor="left", yanchor="bottom")],
                      margin=dict(t=130))
    return fig
Tools for regressions
We run many regressions in this appendix, each on three samples of countries, and we want to read them side by side, as in a published table. Four short functions do the work. reg_table puts several fitted regressions in one table: one column per regression, the coefficient with its standard error in parentheses, then the number of countries and the adjusted \(R^2\).
LABELS = {"Intercept": "Constant", "ln_s": "ln(s_K)", "ln_ngd": "ln(n+g+d)", "ln_school": "ln(SCHOOL)",
          "ln_s_ngd": "ln(s_K) − ln(n+g+d)", "ln_school_ngd": "ln(SCHOOL) − ln(n+g+d)",
          "ln_y60": "ln(y_1960)", "ln_hc": "ln(h)"}

def reg_table(models, names):
    """Coefficients (standard errors) of several regressions, side by side, plus N and adjusted R²."""
    rows = []
    for model in models:
        for term in model.params.index:
            if LABELS[term] not in rows:
                rows.append(LABELS[term])
    columns = {}
    for model, name in zip(models, names):
        cells = {}
        for term in model.params.index:
            cells[LABELS[term]] = f"{model.params[term]:.3f} ({model.bse[term]:.3f})"
        cells["N"] = str(int(model.nobs))
        cells["adjusted R²"] = f"{model.rsquared_adj:.2f}"
        columns[name] = cells
    return pd.DataFrame(columns).reindex(rows + ["N", "adjusted R²"]).fillna("")
Python note. A fitted statsmodels regression keeps its results as attributes:
model.paramsholds the coefficients,model.bsetheir standard errors,model.nobsthe number of observations andmodel.rsquared_adjthe adjusted \(R^2\).paramsandbseare pandas Series indexed by the names of the variables, somodel.params["ln_s"]is the coefficient onln_s.zip(models, names)walks through two lists in step.
The other three tools test a restriction and turn coefficients into the economic parameters behind them. Each is explained in the section that first uses it.
def restriction_test(model, terms):
    """F-test that the coefficients on the listed terms add up to zero; returns F and its p-value."""
    test = model.f_test(" + ".join(terms) + " = 0")
    return float(np.squeeze(test.fvalue)), float(np.squeeze(test.pvalue))

def implied_shares(c_K, c_H=0.0):
    """Equations (3) and (7) turned around: the capital shares alpha and beta behind two coefficients."""
    alpha = c_K / (1 + c_K + c_H)
    beta = c_H / (1 + c_K + c_H)
    return alpha, beta

def implied_speed(b, T):
    """Equation (12): the speed of convergence λ and the half-life behind a slope b over T years."""
    speed = -math.log(1 + b) / T
    return speed, math.log(2) / speed
F.3 The data of Mankiw, Romer and Weil
MRW built their data from an early version of the Penn World Table and from UNESCO’s school enrollment data. The book keeps a copy with readable column names, and one row per country:
| Column | What it measures | Unit |
|---|---|---|
gdp_60, gdp_85 |
real GDP per working-age person (ages 15 to 64), 1960 and 1985 | 1985 international dollars |
inv_gdp |
real investment as a share of real GDP, average 1960–1985: \(s_K\) | percent |
pop_growth |
growth of the working-age population, average 1960–1985: \(n\) | percent a year |
school |
share of the working-age population in secondary school, average 1960–1985: SCHOOL | percent |
gdp_growth |
growth of real GDP, average 1960–1985 | percent a year |
non_oil, intermediate, oecd |
1 if the country is in MRW’s sample | 0 or 1 |
mrw = pd.read_csv(DATA_URL + "mrw1992.csv")
print(len(mrw), "countries")
mrw.head()
121 countries| iso3 | country | region | non_oil | intermediate | oecd | gdp_60 | gdp_85 | gdp_growth | pop_growth | inv_gdp | school | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 0 | DZA | Algeria | Africa | 1 | 1 | 0 | 2485.0 | 4371.0 | 4.8 | 2.6 | 24.1 | 4.5 |
| 1 | AGO | Angola | Africa | 1 | 0 | 0 | 1588.0 | 1171.0 | 0.8 | 2.1 | 5.8 | 1.8 |
| 2 | BEN | Benin | Africa | 1 | 0 | 0 | 1116.0 | 1071.0 | 2.2 | 2.4 | 10.8 | 1.8 |
| 3 | BWA | Botswana | Africa | 1 | 1 | 0 | 959.0 | 3671.0 | 8.6 | 3.2 | 28.3 | 2.9 |
| 4 | BFA | Burkina Faso | Africa | 1 | 0 | 0 | 529.0 | 857.0 | 2.9 | 0.9 | 12.7 | 0.4 |
MRW study three samples. The non-oil sample (98 countries) leaves out the countries where oil production is the main industry: most of their GDP is the extraction of a resource that is already there, which a model of capital accumulation cannot explain. The intermediate sample (75) also leaves out countries with fewer than one million people in 1960 and countries whose data the Penn World Table rated as poor. The OECD sample (22) keeps the rich members of the OECD with more than one million people, whose data are the most reliable.
SAMPLES = {"Non-oil": "non_oil", "Intermediate": "intermediate", "OECD": "oecd"}

def sample(data, name):
    """The rows of one of MRW's samples."""
    return data[data[SAMPLES[name]] == 1]

for name in SAMPLES:
    print(f"{name}: {len(sample(mrw, name))} countries")
Non-oil: 98 countries
Intermediate: 75 countries
OECD: 22 countriesThe variables of the model
The model is about logs of these variables (Section F.4 shows why). Investment and schooling are in percent, so we divide by 100 first. MRW assume that technology grows at \(\bar{g}=0.02\) and capital depreciates at \(\bar{d}=0.03\) a year in every country, so \(\bar{g}+\bar{d}=0.05\) is added to population growth.
G_PLUS_D = 0.05                                  # technology growth + depreciation, as in MRW

mrw["ln_y85"] = np.log(mrw["gdp_85"])
mrw["ln_y60"] = np.log(mrw["gdp_60"])
mrw["growth"] = mrw["ln_y85"] - mrw["ln_y60"]   # log growth of income per worker, 1960-1985
mrw["ln_s"] = np.log(mrw["inv_gdp"] / 100)
mrw["ln_ngd"] = np.log(mrw["pop_growth"] / 100 + G_PLUS_D)
mrw["ln_school"] = np.log(mrw["school"] / 100)
sample(mrw, "Non-oil")[["inv_gdp", "pop_growth", "school", "gdp_85"]].describe().round(1)| inv_gdp | pop_growth | school | gdp_85 | |
|---|---|---|---|---|
| count | 98.0 | 98.0 | 98.0 | 98.0 |
| mean | 17.7 | 2.2 | 5.4 | 5309.8 |
| std | 7.9 | 0.9 | 3.5 | 5277.2 |
| min | 4.1 | 0.3 | 0.4 | 412.0 |
| 25% | 11.7 | 1.7 | 2.4 | 1174.8 |
| 50% | 17.1 | 2.4 | 4.8 | 3150.0 |
| 75% | 23.4 | 2.9 | 8.0 | 7015.0 |
| max | 36.9 | 4.3 | 11.9 | 19723.0 |
What to notice. Even within the non-oil sample the differences are enormous. Investment rates run from about 4 to 37 percent of GDP, and income per worker in 1985 from about 400 dollars to almost 20,000. The question of this appendix is how much of the second spread the first can explain.
Fig. 1: Investment and income across countries
Goal. See the main correlation of the appendix: countries that invest a larger share of GDP are richer.
Both axes are on a ratio scale, so the slope of the fitted line is an elasticity: the percent difference in income that goes with a 1 percent difference in the investment rate. Section F.4 shows that the Solow model predicts this slope.
def investment_figure(name="Non-oil"):
    """Fig. 1: income per worker in 1985 against the investment rate, one MRW sample."""
    d = sample(mrw, name).dropna(subset=["gdp_85"])
    fit = smf.ols("ln_y85 ~ ln_s", data=d).fit()
    fig = px.scatter(d, x="inv_gdp", y="gdp_85", color="region", hover_name="country", log_x=True, log_y=True,
                     range_x=[3, 45], range_y=[250, 40000],
                     labels={"inv_gdp": "Investment share of GDP, 1960–1985 (%)",
                             "gdp_85": "GDP per working-age person, 1985", "region": "Region"},
                     title=f"{name} sample: {len(d)} countries, elasticity of income to investment "
                           f"{fit.params['ln_s']:.2f}")
    s = np.linspace(3, 45, 50)
    fig.add_trace(go.Scatter(x=s, y=np.exp(fit.params["Intercept"]) * (s / 100) ** fit.params["ln_s"],
                             mode="lines", name="Fitted line", line=dict(color="black", dash="dash")))
    fig.update_xaxes(tickvals=[3, 5, 10, 20, 40])
    fig.update_yaxes(tickvals=[300, 1000, 3000, 10000, 30000])
    fig.update_layout(legend=dict(orientation="h", y=-0.18), legend_title_text="", height=520)
    return fig

investment_figure()
interact(investment_figure, name=Dropdown(options=list(SAMPLES), value="Non-oil", description="sample",
style=WIDE));Show the code of the website version
# @title Website version: one button per sample
button_figure(investment_figure, "name", ["Non-oil", "Intermediate", "OECD"], start="Non-oil")
Sources. Data: Mankiw, Romer and Weil (1992), Appendix, from the Penn World Table 4.0 (Summers and Heston 1988). Prepared file: data/appF/mrw1992.csv (see the data notes). Chart: inspired by Fig. 5.3 in Jones (2024), Macroeconomics, 6th ed.
Python note.
smf.ols("ln_y85 ~ ln_s", data=d)writes a regression as a formula: the variable on the left of~is explained by the variables on the right, and a constant is added automatically..fit()estimates it by ordinary least squares. Rows with a missing value in any of the variables are dropped.
What to notice.
- In every sample the cloud slopes upward: richer countries invest more.
- In the non-oil sample the slope is about 1.6: a country that invests twice as much is, on average, about three times as rich (\(2^{1.6}\approx3\)).
- Within the OECD the relation is much weaker. Rich countries invest similar shares, and their income differences are small.
Your turn. The fitted line ignores population growth. Plot income against pop_growth for the non-oil sample. Which way does the cloud slope?
Hint
Use px.scatter(sample(mrw, "Non-oil"), x="pop_growth", y="gdp_85", log_y=True, hover_name="country"). Countries whose working-age population grows fast tend to be poorer: the Solow model says why in Section F.4.
# Your turn: try it hereF.4 The textbook Solow model: from the steady state to a regression
This section derives the equation that MRW estimate first. It is the Solow model of Chapter 5, with population growth and technological progress. Bars mark parameters, and a hat marks a quantity per effective worker, as in Appendix E.
Assumptions
- Output is produced with a Cobb–Douglas function of capital and effective labour, \(AL\): \(Y=K^{\alpha}(AL)^{1-\alpha}\), with capital share \(0<\alpha<1\).
- The labour force grows at rate \(\bar{n}\) and technology at rate \(\bar{g}\): \(L(t)=L(0)e^{\bar{n}t}\) and \(A(t)=A(0)e^{\bar{g}t}\).
- A constant share \(\bar{s}_K\) of output is invested in physical capital, which depreciates at rate \(\bar{d}\): \(\dot{K}=\bar{s}_K Y-\bar{d}K\). A dot over a variable is its change per unit of time.
MRW write \(\delta\) for depreciation and \(s\) for the investment rate. We keep the notation of the book.
Solving the model
Step 1: per effective worker. Define \(\hat{k}=K/(AL)\) and \(\hat{y}=Y/(AL)\). Divide the production function by \(AL\):
\[ \hat{y}=\frac{K^{\alpha}(AL)^{1-\alpha}}{AL}=K^{\alpha}(AL)^{-\alpha}=\left(\frac{K}{AL}\right)^{\alpha}=\hat{k}^{\alpha}. \]
Step 2: the law of motion. The growth rate of a ratio is the growth rate of the numerator minus the growth rate of the denominator (Appendix C.5), so \(\dot{\hat{k}}/\hat{k}=\dot{K}/K-\bar{n}-\bar{g}\). With \(\dot{K}/K=\bar{s}_K Y/K-\bar{d}\) and \(Y/K=\hat{y}/\hat{k}\), multiplying through by \(\hat{k}\) gives
\[ \dot{\hat{k}}=\bar{s}_K\,\hat{k}^{\alpha}-(\bar{n}+\bar{g}+\bar{d})\,\hat{k}. \tag{1} \]
Investment adds capital per effective worker. Depreciation, new workers and better technology all spread it more thinly.
Step 3: the steady state. At the steady state \(\dot{\hat{k}}=0\), so \(\bar{s}_K\hat{k}^{\alpha}=(\bar{n}+\bar{g}+\bar{d})\hat{k}\). Divide by \(\hat{k}^{\alpha}\) and raise both sides to the power \(1/(1-\alpha)\):
\[ \hat{k}^*=\left(\frac{\bar{s}_K}{\bar{n}+\bar{g}+\bar{d}}\right)^{\frac{1}{1-\alpha}},\qquad \hat{y}^*=(\hat{k}^*)^{\alpha}=\left(\frac{\bar{s}_K}{\bar{n}+\bar{g}+\bar{d}}\right)^{\frac{\alpha}{1-\alpha}}. \tag{2} \]
Step 4: back to income per worker. The data measure output per worker, \(Y/L=A\hat{y}\). Take logs, use \(\ln A(t)=\ln A(0)+\bar{g}t\), and the log of a power is the exponent times the log:
\[ \ln\frac{Y(t)}{L(t)}=\ln A(0)+\bar{g}t+\frac{\alpha}{1-\alpha}\ln\bar{s}_K-\frac{\alpha}{1-\alpha}\ln(\bar{n}+\bar{g}+\bar{d}). \tag{3} \]
What the model predicts
Equation (3) holds in each country’s steady state. Countries differ in \(\bar{s}_K\) and \(\bar{n}\), which we observe, and in \(A(0)\), which we do not: it reflects technology but also institutions, geography and climate. MRW write \(\ln A(0)=a+\varepsilon\), a common constant plus a country-specific term. In one year, equation (3) becomes a regression:
\[ \ln\frac{Y}{L}=a+c\,\ln\bar{s}_K-c\,\ln(\bar{n}+\bar{g}+\bar{d})+\varepsilon,\qquad c=\frac{\alpha}{1-\alpha}. \]
The model makes three predictions about it:
| Prediction | Why |
|---|---|
| The coefficient on \(\ln\bar{s}_K\) is positive | more investment, more capital per worker |
| The coefficient on \(\ln(\bar{n}+\bar{g}+\bar{d})\) is negative, equal in size | only the ratio \(\bar{s}_K/(\bar{n}+\bar{g}+\bar{d})\) matters in equation (2) |
| Both are about 0.5 in size | with \(\alpha=1/3\), the capital share in national accounts, \(c=(1/3)/(2/3)=0.5\) |
Intuition. An elasticity of 0.5 means that a country that invests twice as much should be about \(2^{0.5}\approx1.41\) times as rich, all else equal. Diminishing returns keep the effect small: more capital raises output, but by less and less.
The regression is valid only under a strong assumption: the investment rate and population growth must be unrelated to \(\varepsilon\). MRW defend it as the standard assumption of the Solow model, in which saving and population growth are given from outside. Section F.14 returns to it.
The model in code
steady_state computes equation (2). We write it for the augmented model of Section F.6, which has a second capital share \(\beta\); with \(\beta=0\) it is exactly the textbook model. The baseline of every simulation in this appendix is \(\bar{s}_K=0.20\), \(\bar{s}_H=0.10\), \(\bar{n}=0.01\), \(\bar{g}=0.02\), \(\bar{d}=0.03\) and \(\alpha=\beta=1/3\).
def steady_state(s_K=0.20, s_H=0.10, n=0.01, alpha=1/3, beta=1/3, g=0.02, d=0.03):
    """Equations (2) and (6): k*, h* and y* per effective worker (beta = 0 is the textbook model)."""
    dilution = n + g + d
    k = (s_K ** (1 - beta) * s_H ** beta / dilution) ** (1 / (1 - alpha - beta))
    h = (s_K ** alpha * s_H ** (1 - alpha) / dilution) ** (1 / (1 - alpha - beta))
    return k, h, k ** alpha * h ** beta
simulate moves the economy forward one year at a time, with equation (1) and, in the augmented model, its twin for human capital. It starts from any capital stocks, so we can check that the economy really ends up at the steady state.
def simulate(s_K, s_H, k0, h0, n=0.01, alpha=1/3, beta=1/3, years=150, g=0.02, d=0.03):
    """Equations (1) and (5), year by year: paths of k, h and y per effective worker."""
    k = np.zeros(years + 1)
    h = np.zeros(years + 1)
    k[0], h[0] = k0, h0
    for t in range(years):
        y = k[t] ** alpha * h[t] ** beta
        k[t + 1] = k[t] + s_K * y - (n + g + d) * k[t]
        h[t + 1] = h[t] + s_H * y - (n + g + d) * h[t]
    return k, h, k ** alpha * h ** beta
Python note.
np.zeros(years + 1)makes an array of zeros, one for each year, which theforloop fills in.k[t + 1] = ...writes next year’s value from this year’s. A function can return several results at once, andk, h, y = simulate(...)unpacks them.
Check the algebra with numbers. Start the textbook economy far below its steady state, run it for 400 years, and compare where it ends with equation (2). Then raise \(\bar{s}_K\) by 1 percent and check the elasticity of \(\hat{y}^*\), which equation (3) says is \(\alpha/(1-\alpha)=0.5\).
k_star, h_star, y_star = steady_state(beta=0)
k, h, y = simulate(0.20, 0.10, k0=0.5, h0=1.0, beta=0, years=400)
print(f"textbook steady state, equation (2): y* = {y_star:.4f}; simulation after 400 years: {y[-1]:.4f}")
y_up = steady_state(s_K=0.20 * 1.01, beta=0)[2]
print(f"elasticity of y* to s_K: {math.log(y_up / y_star) / math.log(1.01):.3f} (alpha/(1-alpha) = 0.5)")
textbook steady state, equation (2): y* = 1.8257; simulation after 400 years: 1.8257
elasticity of y* to s_K: 0.500 (alpha/(1-alpha) = 0.5)F.5 Testing the textbook model
Goal. Estimate equation (3) on MRW’s three samples, test the equal-and-opposite restriction, and find the capital share \(\alpha\) that the estimates imply.
Unrestricted regressions
We let the data choose the two coefficients freely. fit_all runs one formula on the three samples.
def fit_all(formula, data=mrw):
    """One OLS regression per MRW sample, in the order Non-oil, Intermediate, OECD."""
    models = []
    for name in SAMPLES:
        models.append(smf.ols(formula, data=sample(data, name)).fit())
    return models

solow = fit_all("ln_y85 ~ ln_s + ln_ngd")
reg_table(solow, list(SAMPLES))| Non-oil | Intermediate | OECD | |
|---|---|---|---|
| Constant | 5.430 (1.584) | 5.346 (1.543) | 8.021 (2.518) |
| ln(s_K) | 1.424 (0.143) | 1.318 (0.171) | 0.500 (0.434) |
| ln(n+g+d) | -1.990 (0.563) | -2.017 (0.534) | -0.742 (0.852) |
| N | 98 | 75 | 22 |
| adjusted R² | 0.59 | 0.59 | 0.01 |
What to notice.
- The signs are right in all three samples: investment raises income, and population growth lowers it.
- In the non-oil and intermediate samples, saving and population growth alone explain about 59 percent of the variation in log income (the adjusted \(R^2\)). That is a lot for two variables.
- In the OECD sample the model explains almost nothing, and nothing is significant. Rich countries differ little in their saving and population growth.
- These are the numbers of MRW’s Table I. MRW print −1.97 for the non-oil coefficient on \(\ln(n+g+d)\); the data, rounded to one decimal in their appendix, give −1.99 here.
Testing the restriction
The model says the two coefficients are equal in size and opposite in sign: their sum is zero. An F-test asks whether the data reject that. A small p-value (below 0.05, say) would mean they do.
for name, model in zip(SAMPLES, solow):
    F, p = restriction_test(model, ["ln_s", "ln_ngd"])
    print(f"{name}: F = {F:.2f}, p-value = {p:.2f}")
Non-oil: F = 0.83, p-value = 0.36
Intermediate: F = 1.29, p-value = 0.26
OECD: F = 0.06, p-value = 0.81The data do not reject the restriction in any sample. So we impose it: only the ratio \(\bar{s}_K/(\bar{n}+\bar{g}+\bar{d})\) enters, and its log is \(\ln\bar{s}_K-\ln(\bar{n}+\bar{g}+\bar{d})\).
F.6 The augmented Solow model: adding human capital
Workers are not all alike. A worker with a secondary education produces more than one without it, and schooling, like a machine, is built up by giving up consumption today. MRW therefore add a second kind of capital to the model: human capital \(H\), the stock of skills of the labour force.
Assumptions
- Output is produced with physical capital, human capital and effective labour: \[ Y=K^{\alpha}H^{\beta}(AL)^{1-\alpha-\beta},\qquad \alpha>0,\ \beta>0,\ \alpha+\beta<1. \tag{4} \] The condition \(\alpha+\beta<1\) means diminishing returns to all capital together: doubling both \(K\) and \(H\), with the same effective labour, less than doubles output.
- A share \(\bar{s}_K\) of output is invested in physical capital and a share \(\bar{s}_H\) in human capital.
- Both kinds of capital depreciate at the same rate \(\bar{d}\); \(L\) and \(A\) grow at \(\bar{n}\) and \(\bar{g}\), as before.
With \(\beta=0\) this is the textbook model.
Solving the model
Step 1: per effective worker. Divide equation (4) by \(AL\). The exponents of the denominator add up: \(AL=(AL)^{\alpha}(AL)^{\beta}(AL)^{1-\alpha-\beta}\), so
\[ \hat{y}=\frac{K^{\alpha}H^{\beta}(AL)^{1-\alpha-\beta}}{(AL)^{\alpha}(AL)^{\beta}(AL)^{1-\alpha-\beta}} =\left(\frac{K}{AL}\right)^{\alpha}\left(\frac{H}{AL}\right)^{\beta}=\hat{k}^{\alpha}\hat{h}^{\beta}. \]
Step 2: two laws of motion. The same steps that gave equation (1) give one equation for each kind of capital:
\[ \dot{\hat{k}}=\bar{s}_K\,\hat{y}-(\bar{n}+\bar{g}+\bar{d})\,\hat{k},\qquad \dot{\hat{h}}=\bar{s}_H\,\hat{y}-(\bar{n}+\bar{g}+\bar{d})\,\hat{h}. \tag{5} \]
Step 3: the ratio of the two capitals. At the steady state both changes are zero: \(\bar{s}_K\hat{y}=(\bar{n}+\bar{g}+\bar{d})\hat{k}\) and \(\bar{s}_H\hat{y}=(\bar{n}+\bar{g}+\bar{d})\hat{h}\). Divide the second by the first: \(\hat{h}/\hat{k}=\bar{s}_H/\bar{s}_K\). Each capital is in proportion to the share of output invested in it.
Step 4: solve for \(\hat{k}^*\). Put \(\hat{h}=(\bar{s}_H/\bar{s}_K)\hat{k}\) into the first condition, \(\bar{s}_K\hat{k}^{\alpha}\hat{h}^{\beta}=(\bar{n}+\bar{g}+\bar{d})\hat{k}\):
\[ \bar{s}_K\,\hat{k}^{\alpha}\left(\frac{\bar{s}_H}{\bar{s}_K}\right)^{\beta}\hat{k}^{\beta}=(\bar{n}+\bar{g}+\bar{d})\,\hat{k} \quad\Longrightarrow\quad \hat{k}^{1-\alpha-\beta}=\frac{\bar{s}_K^{1-\beta}\,\bar{s}_H^{\beta}}{\bar{n}+\bar{g}+\bar{d}}. \]
Raising to the power \(1/(1-\alpha-\beta)\), and doing the same for \(\hat{h}\), gives the steady state:
\[ \hat{k}^*=\left(\frac{\bar{s}_K^{1-\beta}\,\bar{s}_H^{\beta}}{\bar{n}+\bar{g}+\bar{d}}\right)^{\frac{1}{1-\alpha-\beta}},\qquad \hat{h}^*=\left(\frac{\bar{s}_K^{\alpha}\,\bar{s}_H^{1-\alpha}}{\bar{n}+\bar{g}+\bar{d}}\right)^{\frac{1}{1-\alpha-\beta}}. \tag{6} \]
Step 5: steady-state income. Put both into \(\hat{y}^*=(\hat{k}^*)^{\alpha}(\hat{h}^*)^{\beta}\) and collect the exponent of each term. For \(\bar{s}_K\) it is \([\alpha(1-\beta)+\beta\alpha]/(1-\alpha-\beta)=\alpha/(1-\alpha-\beta)\); for \(\bar{s}_H\) it is \([\alpha\beta+\beta(1-\alpha)]/(1-\alpha-\beta)=\beta/(1-\alpha-\beta)\); for \(\bar{n}+\bar{g}+\bar{d}\) it is \(-(\alpha+\beta)/(1-\alpha-\beta)\). Back in income per worker, in logs:
\[ \ln\frac{Y}{L}=\ln A(0)+\bar{g}t+\frac{\alpha}{1-\alpha-\beta}\ln\bar{s}_K+\frac{\beta}{1-\alpha-\beta}\ln\bar{s}_H -\frac{\alpha+\beta}{1-\alpha-\beta}\ln(\bar{n}+\bar{g}+\bar{d}). \tag{7} \]
Step 6: the form with the level of human capital. We may observe the stock of human capital rather than the investment in it. Solve the condition for \(\hat{k}\) alone, for a given \(\hat{h}\): \(\hat{k}^*=\left(\bar{s}_K\hat{h}^{\beta}/(\bar{n}+\bar{g}+\bar{d})\right)^{1/(1-\alpha)}\). Then \(\hat{y}=\hat{k}^{\alpha}\hat{h}^{\beta}\) has the exponent \(\alpha\beta/(1-\alpha)+\beta=\beta/(1-\alpha)\) on \(\hat{h}\), and
\[ \ln\frac{Y}{L}=\ln A(0)+\bar{g}t+\frac{\alpha}{1-\alpha}\ln\bar{s}_K-\frac{\alpha}{1-\alpha}\ln(\bar{n}+\bar{g}+\bar{d}) +\frac{\beta}{1-\alpha}\ln\hat{h}^*. \tag{8} \]
What the model predicts
Compare equations (3) and (7) with \(\alpha=\beta=1/3\):
| Elasticity of steady-state income to | Textbook, equation (3) | Augmented, equation (7) |
|---|---|---|
| the investment rate \(\bar{s}_K\) | \(\alpha/(1-\alpha)=0.5\) | \(\alpha/(1-\alpha-\beta)=1\) |
| the investment rate in skills \(\bar{s}_H\) | — | \(\beta/(1-\alpha-\beta)=1\) |
| \(\bar{n}+\bar{g}+\bar{d}\) | \(-0.5\) | \(-(\alpha+\beta)/(1-\alpha-\beta)=-2\) |
- Saving matters more. With the same \(\alpha\), the effect of \(\bar{s}_K\) doubles. A country that invests more in machines is richer, so it also invests more in schooling (a fixed share of a larger income), which makes it richer still.
- Population growth matters much more. Fast population growth now dilutes both kinds of capital.
- The three coefficients of equation (7) add up to zero. This is the restriction we test in Section F.8.
- Omitting human capital biases the textbook regression. If \(\bar{s}_H\) is correlated with \(\bar{s}_K\) and \(\bar{n}\), the textbook regression credits their coefficients with part of the effect of schooling. This is one reason why its implied \(\alpha\) is too large.
The model in code
steady_state and simulate of Section F.4 already cover the augmented model (their default is \(\beta=1/3\)). We check equation (6) by simulation, the ratio \(\hat{h}^*/\hat{k}^*=\bar{s}_H/\bar{s}_K\) of Step 3, and the elasticity of 1 in the table.
k_star, h_star, y_star = steady_state()
k, h, y = simulate(0.20, 0.10, k0=0.5, h0=0.5, years=600)
print(f"augmented steady state, equation (6): k* = {k_star:.3f}, h* = {h_star:.3f}, y* = {y_star:.3f}")
print(f"simulation after 600 years:           k  = {k[-1]:.3f}, h  = {h[-1]:.3f}, y  = {y[-1]:.3f}")
print(f"h*/k* = {h_star / k_star:.3f} (s_H/s_K = {0.10 / 0.20:.3f})")
y_up = steady_state(s_K=0.20 * 1.01)[2]
print(f"elasticity of y* to s_K: {math.log(y_up / y_star) / math.log(1.01):.3f} (alpha/(1-alpha-beta) = 1)")
augmented steady state, equation (6): k* = 18.519, h* = 9.259, y* = 5.556
simulation after 600 years: k = 18.518, h = 9.259, y = 5.556
h*/k* = 0.500 (s_H/s_K = 0.500)
elasticity of y* to s_K: 1.000 (alpha/(1-alpha-beta) = 1)F.7 Simulation: the steady state with human capital
Fig. 2: How much does investment matter?
Goal. See why adding human capital makes the investment rate matter more for income.
The chart compares two economies with the same capital share \(\alpha\) and the same baseline investment rate of 20 percent. One has no human capital (the textbook model) and one has human capital with share \(\beta\). For each, it plots steady-state income at other investment rates, relative to its income at 20 percent. Both axes are on a ratio scale, so each line is straight and its slope is the elasticity of the table in Section F.6.
def steady_state_figure(alpha=0.33, beta=0.33):
    """Fig. 2: steady-state income against s_K, relative to s_K = 0.20; equations (2) and (6)."""
    s_K = np.linspace(0.05, 0.40, 50)
    fig = go.Figure()
    for b, label, color in [(0, "Textbook (β = 0)", BLUE), (beta, f"Augmented (β = {beta:.2f})", TEAL)]:
        base = steady_state(s_K=0.20, alpha=alpha, beta=b)[2]
        y = steady_state(s_K=s_K, alpha=alpha, beta=b)[2] / base
        fig.add_trace(go.Scatter(x=s_K, y=y, mode="lines", name=label, line=dict(color=color, width=3)))
    elastic_text = alpha / (1 - alpha)
    elastic_aug = alpha / (1 - alpha - beta)
    fig.add_trace(go.Scatter(x=[0.20], y=[1], mode="markers", name="Baseline, s_K = 0.20",
                             marker=dict(color="black", size=10)))
    fig.update_layout(title=f"Elasticity of income to s_K: textbook {elastic_text:.2f}, "
                            f"augmented {elastic_aug:.2f}",
                      xaxis=dict(title="Investment rate in physical capital, s_K", type="log",
                                 range=[np.log10(0.045), np.log10(0.44)], tickvals=[0.05, 0.1, 0.2, 0.3, 0.4]),
                      yaxis=dict(title="Steady-state income relative to s_K = 0.20", type="log",
                                 range=[np.log10(0.01), np.log10(10)], tickvals=[0.01, 0.03, 0.1, 0.3, 1, 3, 10]),
                      legend=dict(x=0.02, y=0.98))
    return fig

steady_state_figure()
interact(steady_state_figure,
alpha=FloatSlider(value=0.33, min=0.20, max=0.45, step=0.01, description="physical capital share α",
style=WIDE),
beta=FloatSlider(value=0.33, min=0.0, max=0.40, step=0.01, description="human capital share β",
style=WIDE));Show the code of the website version
# @title Website version: move the human capital share β
slider_figure(steady_state_figure, "beta", [0.0, 0.1, 0.2, 0.33, 0.4], start=0.33, label="human capital share β")
Source. Model: the textbook and augmented Solow models, equations (2) and (6) of this appendix, with \(\bar{s}_H=0.10\), \(\bar{n}=0.01\), \(\bar{g}=0.02\) and \(\bar{d}=0.03\). Adapted from the Solow model of Chapter 5 in Jones (2024), Macroeconomics, 6th ed.
What to notice.
- With \(\alpha=\beta=1/3\) the augmented line is twice as steep: doubling the investment rate from 20 to 40 percent doubles steady-state income, against 41 percent more in the textbook model.
- At \(\beta=0\) the two lines coincide. Each step up in \(\beta\) makes the augmented line steeper, because \(1-\alpha-\beta\), the strength of diminishing returns, gets smaller.
- The values of \(\bar{s}_H\), \(\bar{n}\), \(\bar{g}\) and \(\bar{d}\) move the level of income but not the slopes, which is why the chart can measure both lines relative to the baseline.
Your turn. MRW’s textbook regression implied an elasticity of about 1.4. With \(\alpha=1/3\), which human capital share \(\beta\) gives that elasticity in the augmented model?
Hint
Solve \(\alpha/(1-\alpha-\beta)=1.4\) with \(\alpha=1/3\): \(1-\alpha-\beta=0.333/1.4\approx0.24\), so \(\beta\approx0.43\), just above the slider’s range. Close values, such as \(\beta=0.40\), give an elasticity of about 1.25: move the slider and read the title.
# Your turn: try it hereF.8 Testing the augmented model
Goal. Estimate equation (7) on MRW’s three samples, test its restriction, and recover \(\alpha\) and \(\beta\).
We measure the investment rate in human capital \(\bar{s}_H\) with MRW’s SCHOOL: the share of the working-age population that is in secondary school. It is a rough measure: it leaves out primary and university education, learning on the job, and the time and money spent on health. But it is available for almost every country.
Unrestricted regressions
augmented = fit_all("ln_y85 ~ ln_s + ln_school + ln_ngd")
names = []
for model_name in ["Textbook", "Augmented"]:
    for name in SAMPLES:
        names.append(model_name + ": " + name)
reg_table(solow + augmented, names)| Textbook: Non-oil | Textbook: Intermediate | Textbook: OECD | Augmented: Non-oil | Augmented: Intermediate | Augmented: OECD | |
|---|---|---|---|---|---|---|
| Constant | 5.430 (1.584) | 5.346 (1.543) | 8.021 (2.518) | 6.844 (1.177) | 7.791 (1.192) | 8.637 (2.214) |
| ln(s_K) | 1.424 (0.143) | 1.318 (0.171) | 0.500 (0.434) | 0.697 (0.133) | 0.700 (0.151) | 0.276 (0.389) |
| ln(n+g+d) | -1.990 (0.563) | -2.017 (0.534) | -0.742 (0.852) | -1.745 (0.416) | -1.500 (0.403) | -1.076 (0.756) |
| ln(SCHOOL) | 0.654 (0.073) | 0.731 (0.095) | 0.768 (0.293) | |||
| N | 98 | 75 | 22 | 98 | 75 | 22 |
| adjusted R² | 0.59 | 0.59 | 0.01 | 0.78 | 0.77 | 0.24 |
Python note.
solow + augmentedjoins two lists into one, soreg_tableshows all six regressions, and the two nested loops build the six column names in the same order.
What to notice. These are the numbers of MRW’s Table II.
- Schooling enters with a large, positive coefficient in all three samples.
- Adding it halves the coefficient on physical investment, from about 1.4 to about 0.7 in the non-oil sample: part of what looked like the effect of investment was the effect of schooling, which goes with it.
- The adjusted \(R^2\) jumps from 0.59 to 0.78 in the non-oil and intermediate samples. Saving, schooling and population growth explain almost four fifths of the variation in income across countries.
Fig. 3: How much do the two models explain?
Goal. See the gain in fit: compare each country’s actual income with the income the model predicts from its saving, population growth and, in the augmented model, schooling.
def fit_figure(name="Non-oil"):
    """Fig. 3: actual against predicted log income, textbook and augmented models, one MRW sample."""
    d = sample(mrw, name).dropna(subset=["ln_y85", "ln_ngd", "ln_school"])
    models = [smf.ols("ln_y85 ~ ln_s + ln_ngd", data=d).fit(),
              smf.ols("ln_y85 ~ ln_s + ln_school + ln_ngd", data=d).fit()]
    titles = []
    for label, model in zip(["Textbook", "Augmented"], models):
        titles.append(f"{label} model: adjusted R² = {model.rsquared_adj:.2f}")
    fig = make_subplots(rows=1, cols=2, subplot_titles=titles, horizontal_spacing=0.1)
    for col, model in [(1, models[0]), (2, models[1])]:
        fig.add_trace(go.Scatter(x=model.fittedvalues, y=d["ln_y85"], mode="markers", text=d["country"],
                                 hovertemplate="%{text}<br>predicted %{x:.2f}<br>actual %{y:.2f}",
                                 marker=dict(color=TEAL if col == 2 else BLUE, size=8), showlegend=False),
                      row=1, col=col)
        fig.add_trace(go.Scatter(x=[5.5, 10.5], y=[5.5, 10.5], mode="lines", line=dict(color=GRAY, dash="dot"),
                                 hoverinfo="skip", showlegend=False), row=1, col=col)
    fig.update_xaxes(title="Predicted log income, 1985", range=[5.5, 10.5])
    fig.update_yaxes(title="Actual log income, 1985", range=[5.5, 10.5])
    fig.update_layout(title=f"{name} sample: {len(d)} countries; dots on the dotted line are predicted exactly")
    return fig

fit_figure()
interact(fit_figure, name=Dropdown(options=list(SAMPLES), value="Non-oil", description="sample", style=WIDE));Show the code of the website version
# @title Website version: one button per sample
fig = button_figure(fit_figure, "name", ["Non-oil", "Intermediate", "OECD"], start="Non-oil")
fig.layout.updatemenus[0].y = 1.12                 # above the panel titles
fig.update_layout(margin=dict(t=160))
Sources. Data: Mankiw, Romer and Weil (1992), Appendix. Prepared file: data/appF/mrw1992.csv (see the data notes). Regressions: MRW’s Tables I and II, unrestricted. Chart: inspired by Fig. 5.3 in Jones (2024), Macroeconomics, 6th ed.
Python note.
model.fittedvaluesholds the regression’s prediction for every country it used. Hover text comes fromtext=and is laid out byhovertemplate:%{x:.2f}prints the x value with two decimals.
What to notice.
- In the textbook panel the dots spread widely around the dotted line; in the augmented panel they hug it more closely. The gain is largest among the poorest countries, where schooling is lowest.
- Some countries stay far from the line in both panels. The model leaves out their \(A(0)\): technology, institutions and history.
Your turn. Which country of the non-oil sample is the furthest below the augmented model’s prediction? Is it poorer or richer than its saving, schooling and population growth would suggest?
Hint
The gap is the regression’s residual: model.resid in statsmodels. Fit the augmented model on the non-oil sample, then sort: d.assign(gap=model.resid).sort_values("gap")[["country", "gap"]].head(). A negative gap means the country is poorer than predicted.
# Your turn: try it hereF.9 Simulation: the transition after a rise in investment
Fig. 4: Moving to a new steady state
Goal. Watch an economy move to its new steady state after it starts to invest more, in physical or in human capital, and compare the textbook and augmented models.
The economy starts on its balanced growth path with the baseline rates. In year 10 one investment rate rises. The chart plots output per worker relative to the path it would have followed without the change, in log points: 100 times the difference in logs, which is close to the percent difference for small gaps.
def transition_path(rise, capital, beta, years=150):
    """Equation (5): log points of income per worker above the old path, rise in s_K or s_H in year 10."""
    k0, h0, y0 = steady_state(beta=beta)
    s_K, s_H = 0.20, 0.10
    if capital == "physical":
        s_K = s_K + rise
    else:
        s_H = s_H + rise
    k, h, y = simulate(s_K, s_H, k0, h0, beta=beta, years=years - 10)
    gap = np.concatenate([np.zeros(10), 100 * np.log(y / y0)])
    return np.arange(years + 1), gap, 100 * math.log(steady_state(s_K, s_H, beta=beta)[2] / y0)
def transition_figure(rise=0.05, capital="physical", beta=0.33):
"""Fig. 4: the transition after a rise in one investment rate, textbook and augmented models."""
fig = go.Figure()
gains = []
for b, label, color in [(0, "Textbook (β = 0)", BLUE), (beta, f"Augmented (β = {beta:.2f})", TEAL)]:
t, gap, gain = transition_path(rise, capital, b)
gains.append(gain)
fig.add_trace(go.Scatter(x=t, y=gap, mode="lines", name=label, line=dict(color=color, width=3)))
fig.add_trace(go.Scatter(x=[0, 150], y=[gain, gain], mode="lines", line=dict(color=color, dash="dot"),
hoverinfo="skip", showlegend=False))
rate = "s_K" if capital == "physical" else "s_H"
fig.update_layout(title=f"{rate} up by {rise:.2f}: long-run gain {gains[0]:.0f} (textbook) "
f"and {gains[1]:.0f} (augmented) log points",
xaxis=dict(title="Years", range=[0, 150]),
yaxis=dict(title="Income per worker above the old path (log points)", range=[-5, 110]),
legend=dict(x=0.01, y=0.98))
return fig
transition_figure()interact(transition_figure,
rise=FloatSlider(value=0.05, min=0.02, max=0.10, step=0.01, description="rise in the investment rate",
style=WIDE),
capital=ToggleButtons(options=["physical", "human"], value="physical", description="capital"),
beta=FloatSlider(value=0.33, min=0.0, max=0.40, step=0.01, description="human capital share β",
style=WIDE));Show the code of the website version
# @title Website version: move the rise in the investment rate in physical capital
slider_figure(transition_figure, "rise", [0.02, 0.04, 0.05, 0.06, 0.08, 0.1], start=0.05,
              label="rise in s_K")
Source. Model: the textbook and augmented Solow models, equations (2), (5) and (6) of this appendix, from the baseline \(\bar{s}_K=0.20\), \(\bar{s}_H=0.10\), \(\bar{n}=0.01\), \(\bar{g}=0.02\), \(\bar{d}=0.03\), \(\alpha=1/3\). Adapted from Fig. 5.5 in Jones (2024), Macroeconomics, 6th ed.
What to notice.
- A rise in \(\bar{s}_K\) from 0.20 to 0.25 raises long-run income by about 11 log points in the textbook model and about 22 in the augmented model: twice as much, as the elasticities of Section F.6 say.
- The augmented economy also takes much longer to get there. Human capital keeps rising as income rises, which keeps pushing income up after the textbook economy has settled.
- Choose human capital: the textbook line stays flat, because the textbook model has no place for schooling.
Your turn. With \(\beta=1/3\), which raises long-run income more: a rise of 0.05 in \(\bar{s}_K\) (from 0.20) or the same rise in \(\bar{s}_H\) (from 0.10)? Why?
Hint
Both elasticities are 1 with \(\alpha=\beta=1/3\), but the same rise of 0.05 is a 25 percent increase in \(\bar{s}_K\) and a 50 percent increase in \(\bar{s}_H\). Check with the toggle, or with transition_path(0.05, "human", 1/3)[2].
# Your turn: try it hereF.10 Convergence: the theory and its speed
So far we have compared countries in their steady states. But a country that starts below its steady state grows faster than \(\bar{g}\) while it catches up: the principle of transition dynamics of Chapter 5. This section derives how fast the gap closes in the augmented model and turns the result into a regression.
Appendix E derives the speed of convergence of the textbook model and writes it as β. In this appendix β is the human capital share, as in MRW, so we write the speed as λ.
Solving the model
Step 1: logs. Write \(x=\ln\hat{k}\) and \(z=\ln\hat{h}\). Dividing each equation (5) by its capital, the growth rates are
\[ \dot{x}=\bar{s}_K\,e^{(\alpha-1)x+\beta z}-D,\qquad \dot{z}=\bar{s}_H\,e^{\alpha x+(\beta-1)z}-D, \qquad D\equiv\bar{n}+\bar{g}+\bar{d}. \]
Step 2: straight lines near the steady state. As in Appendix E, replace each right-hand side by its tangent at the steady state \((x^*,z^*)\). At the steady state each exponential term equals \(D\), so the derivatives are simple:
\[ \begin{pmatrix}\dot{x}\\ \dot{z}\end{pmatrix}\approx D \begin{pmatrix}\alpha-1 & \beta\\ \alpha & \beta-1\end{pmatrix} \begin{pmatrix}x-x^*\\ z-z^*\end{pmatrix}. \]
Step 3: the two speeds. A two-variable system like this one moves along two directions, each at its own speed, given by the eigenvalues of the matrix. Their sum is the trace, \(D(\alpha+\beta-2)\), and their product is the determinant, \(D^2[(1-\alpha)(1-\beta)-\alpha\beta]=D^2(1-\alpha-\beta)\). The two numbers with that sum and product are \(-D\) and \(-D(1-\alpha-\beta)\). The first, fast one, closes any gap in the ratio of the two capitals. The second, slow one, governs income once the ratio is right, and it sets the speed of convergence:
\[ \lambda=(\bar{n}+\bar{g}+\bar{d})(1-\alpha-\beta). \tag{9} \]
With \(\beta=0\) this is the textbook speed of Appendix E.
Step 4: the path of income. Log income per effective worker closes a share λ of its gap each year:
\[ \ln\hat{y}(t)-\ln\hat{y}^*=e^{-\lambda t}\left[\ln\hat{y}(0)-\ln\hat{y}^*\right], \tag{10} \]
and half of the gap is gone after \(\ln 2/\lambda\) years, the half-life.
What the model predicts
How fast? With \(\bar{n}+\bar{g}+\bar{d}=0.06\) and \(\alpha=1/3\), the textbook model gives \(\lambda=0.06\times2/3=0.04\): half of the gap closes in about 17 years. With \(\alpha=\beta=1/3\), the augmented model gives \(\lambda=0.06\times1/3=0.02\) and a half-life of about 35 years. Human capital halves the speed, because diminishing returns to all capital together set in more slowly.
A regression. Subtract \(\ln\hat{y}(0)\) from both sides of equation (10) at \(t=T\), replace \(\ln\hat{y}^*\) by the right-hand side of equation (7), and move from effective workers to workers (the terms in \(A(0)\) and \(\bar{g}\) go into the constant \(a\)):
\[ \ln\frac{y(T)}{y(0)}=a+\left(1-e^{-\lambda T}\right)\left[\frac{\alpha\ln\bar{s}_K+\beta\ln\bar{s}_H-(\alpha+\beta)\ln(\bar{n}+\bar{g}+\bar{d})}{1-\alpha-\beta}-\ln y(0)\right]+\varepsilon. \tag{11} \]
Growth over \(T\) years depends on the determinants of the steady state and on initial income. The coefficient on \(\ln y(0)\) is \(b=-(1-e^{-\lambda T})\), which is negative. Turning it around gives the speed:
\[ \lambda=-\frac{\ln(1+b)}{T}. \tag{12} \]
This is what implied_speed computes.
Two kinds of convergence.
- Unconditional (absolute) convergence: poor countries grow faster than rich ones, without any controls. The model predicts it only if all countries share the same steady state.
- Conditional convergence: poor countries grow faster than rich ones with the same steady state, that is, holding constant \(\bar{s}_K\), \(\bar{s}_H\) and \(\bar{n}\). This is what the model predicts in general, and what equation (11) tests.
The model in code
The eigenvalue argument is an approximation near the steady state. We check it: start an economy below its steady-state income, with the two capitals in the steady-state ratio, simulate equation (5), and compare the year in which half of the log gap has closed with \(\ln 2/\lambda\). We try two starts: 80 percent of the steady state, and a quarter of it.
def start_below(fraction, alpha=1/3, beta=1/3, n=0.01):
    """Capital stocks that put income at a fraction of its steady state, with the steady-state ratio h/k."""
    k_star, h_star, y_star = steady_state(n=n, alpha=alpha, beta=beta)
    scale = fraction ** (1 / (alpha + beta))         # scaling both capitals by this scales y by fraction
    return k_star * scale, h_star * scale

for beta in [0, 1/3]:
    speed = (0.01 + 0.02 + 0.03) * (1 - 1/3 - beta)
    print(f"beta = {beta:.2f}: λ = {speed:.3f}; half-life by equation (9): {math.log(2) / speed:.1f} years")
    for fraction in [0.8, 0.25]:
        k0, h0 = start_below(fraction, beta=beta)
        k, h, y = simulate(0.20, 0.10, k0, h0, beta=beta, years=300)
        gap = np.log(steady_state(beta=beta)[2] / y)
        print(f"   starting at {fraction:.0%} of the steady state: {np.argmax(gap <= gap[0] / 2)} years")
beta = 0.00: λ = 0.040; half-life by equation (9): 17.3 years
starting at 80% of the steady state: 15 years
starting at 25% of the steady state: 6 years
beta = 0.33: λ = 0.020; half-life by equation (9): 34.7 years
starting at 80% of the steady state: 34 years
starting at 25% of the steady state: 27 yearsPython note.
np.argmax(gap <= gap[0] / 2)finds the first year in which the condition is true: the comparison gives an array ofFalseandTrue, andargmaxreturns the position of the firstTrue.
From 80 percent of the steady state, the simulated half-lives are close to the formula. From a quarter of it, they are much shorter, above all in the textbook model: far below the steady state the returns to capital are very high, and the economy grows faster than the straight line says. The speed λ describes the last part of the journey, not the first.
Fig. 5: The speed of convergence with and without human capital
Goal. See how the human capital share slows down convergence.
def speed_figure(alpha=0.33, beta=0.33, n=0.01):
    """Fig. 5: the log gap to the steady state after starting at 80 percent of it; equations (9) and (10)."""
    fig = go.Figure()
    title = []
    for b, label, color in [(0, "Textbook (β = 0)", BLUE), (beta, f"Augmented (β = {beta:.2f})", TEAL)]:
        k0, h0 = start_below(0.8, alpha=alpha, beta=b, n=n)
        k, h, y = simulate(0.20, 0.10, k0, h0, n=n, alpha=alpha, beta=b, years=150)
        gap = np.log(steady_state(n=n, alpha=alpha, beta=b)[2] / y)
        speed = (n + 0.05) * (1 - alpha - b)
        fig.add_trace(go.Scatter(x=np.arange(151), y=gap, mode="lines", name=label, line=dict(color=color, width=3)))
        fig.add_trace(go.Scatter(x=[math.log(2) / speed] * 2, y=[0, 0.24], mode="lines", hoverinfo="skip",
                                 line=dict(color=color, dash="dot"), showlegend=False))
        title.append(f"{100 * speed:.1f}% ({math.log(2) / speed:.0f} years)")
    fig.update_layout(title="λ and half-life: textbook " + title[0] + ", augmented " + title[1],
                      xaxis=dict(title="Years", range=[0, 150]),
                      yaxis=dict(title="Log gap to the steady state", range=[0, 0.24]),
                      legend=dict(x=0.99, xanchor="right", y=0.98))
    return fig

speed_figure()
interact(speed_figure,
alpha=FloatSlider(value=0.33, min=0.20, max=0.45, step=0.01, description="physical capital share α",
style=WIDE),
beta=FloatSlider(value=0.33, min=0.0, max=0.40, step=0.01, description="human capital share β",
style=WIDE),
n=FloatSlider(value=0.01, min=0.0, max=0.03, step=0.005, description="population growth n",
style=WIDE, readout_format=".3f"));Show the code of the website version
# @title Website version: move the human capital share β
slider_figure(speed_figure, "beta", [0.0, 0.1, 0.2, 0.33, 0.4], start=0.33, label="human capital share β")
Source. Model: the textbook and augmented Solow models, equations (5), (9) and (10) of this appendix, with \(\bar{g}+\bar{d}=0.05\); each economy starts at 80 percent of its steady-state income per effective worker (log gap 0.22), and the dotted lines mark the half-lives of equation (9). Adapted from the transition dynamics of Chapter 5 in Jones (2024), Macroeconomics, 6th ed.
What to notice.
- With α and β at 0.33, the textbook economy closes half of its gap in about 17 years, the augmented one in about 34. The dotted half-lives of equation (9) fall close to where each simulated gap has halved.
- Raising β slows convergence further, and at β = 0 the two lines coincide.
- Faster population growth speeds up convergence: it raises \(\bar{n}+\bar{g}+\bar{d}\), the force that pulls capital per effective worker back to its steady state.
Your turn. Many studies, including MRW’s below, find a speed of about 2 percent a year. Which combinations of α and β give that speed with \(\bar{n}=0.01\)?
Hint
Equation (9) with \(\bar{n}+\bar{g}+\bar{d}=0.06\) gives \(0.06(1-\alpha-\beta)=0.02\), so \(\alpha+\beta=2/3\). Any pair that adds up to two thirds works, for example α = 0.33 and β = 0.33, or α = 0.4 and β = 0.27.
# Your turn: try it hereF.11 Convergence in MRW’s data
Goal. Estimate equation (11) on MRW’s samples in three steps: without controls (unconditional convergence), with saving and population growth (conditional convergence in the textbook model), and with schooling too (conditional convergence in the augmented model). Then turn each slope into a speed with equation (12), over \(T=25\) years.
Three growth regressions
unconditional = fit_all("growth ~ ln_y60")
conditional = fit_all("growth ~ ln_y60 + ln_s + ln_ngd")
conditional_h = fit_all("growth ~ ln_y60 + ln_s + ln_ngd + ln_school")
names = []
for label in ["No controls", "With controls"]:
    for name in SAMPLES:
        names.append(label + ": " + name)
reg_table(unconditional + conditional_h, names)| No controls: Non-oil | No controls: Intermediate | No controls: OECD | With controls: Non-oil | With controls: Intermediate | With controls: OECD | |
|---|---|---|---|---|---|---|
| Constant | -0.267 (0.380) | 0.588 (0.433) | 3.686 (0.685) | 3.022 (0.827) | 3.709 (0.909) | 2.755 (1.201) |
| ln(y_1960) | 0.094 (0.050) | -0.004 (0.055) | -0.341 (0.079) | -0.288 (0.062) | -0.366 (0.067) | -0.398 (0.070) |
| ln(s_K) | 0.524 (0.087) | 0.538 (0.102) | 0.332 (0.173) | |||
| ln(n+g+d) | -0.506 (0.289) | -0.545 (0.288) | -0.863 (0.338) | |||
| ln(SCHOOL) | 0.231 (0.059) | 0.270 (0.080) | 0.228 (0.145) | |||
| N | 98 | 75 | 22 | 98 | 75 | 22 |
| adjusted R² | 0.03 | -0.01 | 0.46 | 0.46 | 0.43 | 0.65 |
What to notice. These are MRW’s Tables III and V.
- No controls: in the non-oil and intermediate samples the slope on initial income is about zero, or even positive. Poor countries did not grow faster than rich ones from 1960 to 1985: there is no unconditional convergence in the world as a whole. Only among the OECD countries is the slope clearly negative.
- With controls: the slope turns clearly negative in every sample, and the fit improves a lot. Among countries with the same saving, schooling and population growth, the poorer ones did grow faster: conditional convergence.
From slopes to speeds
Equation (12) turns each slope \(b\) into a speed λ and a half-life. We collect them in one table, for the three regressions above.
rows = []
for label, models in [("No controls", unconditional), ("Saving, population", conditional),
                      ("Saving, population, schooling", conditional_h)]:
    for name, model in zip(SAMPLES, models):
        b = model.params["ln_y60"]
        speed, half_life = implied_speed(b, 25)
        rows.append({"Controls": label, "Sample": name, "slope b": round(b, 3),
                     "speed λ (% a year)": round(100 * speed, 2), "half-life (years)": round(half_life)})
speeds = pd.DataFrame(rows)
speeds| Controls | Sample | slope b | speed λ (% a year) | half-life (years) | |
|---|---|---|---|---|---|
| 0 | No controls | Non-oil | 0.094 | -0.36 | -192 |
| 1 | No controls | Intermediate | -0.004 | 0.02 | 4083 |
| 2 | No controls | OECD | -0.341 | 1.67 | 42 |
| 3 | Saving, population | Non-oil | -0.141 | 0.61 | 114 |
| 4 | Saving, population | Intermediate | -0.228 | 1.03 | 67 |
| 5 | Saving, population | OECD | -0.350 | 1.72 | 40 |
| 6 | Saving, population, schooling | Non-oil | -0.288 | 1.36 | 51 |
| 7 | Saving, population, schooling | Intermediate | -0.366 | 1.82 | 38 |
| 8 | Saving, population, schooling | OECD | -0.398 | 2.03 | 34 |
What to notice.
- Without controls, the slope is positive or near zero outside the OECD, so the “speed” is negative or close to zero: no catching up at all, and half-lives that are negative or meaningless.
- With all three controls the speed is about 1.4 to 2 percent a year, and the half-life 34 to 50 years. That is close to the 2 percent of the augmented model with \(\alpha=\beta=1/3\), and far from the 4 percent of the textbook model (Fig. 5).
The restricted regression
Equation (11) also says that the coefficients on \(\ln\bar{s}_K\), \(\ln\bar{s}_H\) and \(\ln(\bar{n}+\bar{g}+\bar{d})\) add up to zero. We test this, then impose it. In the restricted regression the coefficients on the two investment terms are \((1-e^{-\lambda T})\alpha/(1-\alpha-\beta)\) and \((1-e^{-\lambda T})\beta/(1-\alpha-\beta)\); dividing them by \(-b=1-e^{-\lambda T}\) gives the \(c_K\) and \(c_H\) of Section F.8, and with them α and β.
restricted = fit_all("growth ~ ln_y60 + ln_s_ngd + ln_school_ngd")
for name, model, free in zip(SAMPLES, restricted, conditional_h):
    F, p = restriction_test(free, ["ln_s", "ln_school", "ln_ngd"])
    b = model.params["ln_y60"]
    alpha, beta = implied_shares(model.params["ln_s_ngd"] / -b, model.params["ln_school_ngd"] / -b)
    speed, half_life = implied_speed(b, 25)
    print(f"{name}: test p-value {p:.2f}; λ = {100 * speed:.2f}% a year; alpha = {alpha:.2f}, beta = {beta:.2f}")
reg_table(restricted, list(SAMPLES))
Non-oil: test p-value 0.41; λ = 1.41% a year; alpha = 0.48, beta = 0.23
Intermediate: test p-value 0.40; λ = 1.86% a year; alpha = 0.44, beta = 0.23
OECD: test p-value 0.44; λ = 2.06% a year; alpha = 0.38, beta = 0.23| Non-oil | Intermediate | OECD | |
|---|---|---|---|
| Constant | 2.457 (0.473) | 3.090 (0.530) | 3.554 (0.634) |
| ln(y_1960) | -0.298 (0.060) | -0.372 (0.067) | -0.402 (0.069) |
| ln(s_K) − ln(n+g+d) | 0.501 (0.082) | 0.506 (0.095) | 0.395 (0.152) |
| ln(SCHOOL) − ln(n+g+d) | 0.235 (0.059) | 0.266 (0.080) | 0.241 (0.142) |
| N | 98 | 75 | 22 |
| adjusted R² | 0.47 | 0.44 | 0.66 |
What to notice. These are the numbers of MRW’s Table VI. The restriction is not rejected. The speeds are about 1.4, 1.9 and 2.1 percent a year. The implied α of about 0.4 to 0.5 is higher than in the levels regressions of Section F.8: the growth regressions are noisier, and MRW read the two sets of results as broadly in line with \(\alpha\) and \(\beta\) near one third.
Fig. 6: Unconditional and conditional convergence
Goal. See conditional convergence in a chart. Panel A plots growth against initial income, with no controls. Panels B and C plot the same relation after removing the part of both variables that the controls explain.
How do we “remove” the controls? Regress growth on the controls and keep the residual, the part they do not explain; do the same for initial income; then plot one residual against the other. The slope of that cloud is exactly the coefficient on initial income in the multiple regression: this is the Frisch–Waugh theorem. We add back each variable’s mean, so the axes keep their units.
def partial_out(d, column, controls):
    """The part of a column that the controls do not explain, plus its mean (Frisch-Waugh)."""
    if len(controls) == 0:
        return d[column]
    fit = smf.ols(column + " ~ " + " + ".join(controls), data=d).fit()
    return fit.resid + d[column].mean()

PANELS = [("A: no controls", []), ("B: saving, population", ["ln_s", "ln_ngd"]),
          ("C: and schooling", ["ln_s", "ln_ngd", "ln_school"])]
d = sample(mrw, "Intermediate").dropna(subset=["growth", "ln_ngd", "ln_school"])
x = partial_out(d, "ln_y60", PANELS[2][1])
y = partial_out(d, "growth", PANELS[2][1])
print(f"slope of panel C: {np.polyfit(x, y, 1)[0]:.4f}; "
      f"coefficient in the regression: {conditional_h[1].params['ln_y60']:.4f}")
slope of panel C: -0.3660; coefficient in the regression: -0.3660Python note.
" + ".join(controls)glues a list of names into one string,"ln_s + ln_ngd", to build a formula.np.polyfit(x, y, 1)fits a straight line and returns its slope and intercept.
def convergence_figure(name="Intermediate"):
    """Fig. 6: growth against initial income, without and with controls, one MRW sample."""
    d = sample(mrw, name).dropna(subset=["growth", "ln_ngd", "ln_school"])
    panels, titles = [], []
    for label, controls in PANELS:
        x = partial_out(d, "ln_y60", controls)
        y = partial_out(d, "growth", controls)
        slope, intercept = np.polyfit(x, y, 1)
        panels.append((x, y, slope, intercept))
        titles.append(f"{label}<br>slope {round(slope, 2) + 0.0:.2f}")     # + 0.0 avoids printing -0.00
    fig = make_subplots(rows=1, cols=3, shared_yaxes=True, horizontal_spacing=0.04, subplot_titles=titles)
    for col, (x, y, slope, intercept) in enumerate(panels, start=1):
        fig.add_trace(go.Scatter(x=x, y=y, mode="markers", text=d["country"], hovertemplate="%{text}",
                                 marker=dict(color=[BLUE, TEAL, GREEN][col - 1], size=7), showlegend=False),
                      row=1, col=col)
        fig.add_trace(go.Scatter(x=[5.5, 10.5], y=[intercept + slope * 5.5, intercept + slope * 10.5], mode="lines",
                                 line=dict(color="black", dash="dash"), hoverinfo="skip", showlegend=False),
                      row=1, col=col)
    fig.update_xaxes(range=[5.5, 10.5], title="Log income, 1960")
    fig.update_yaxes(range=[-0.9, 1.9])
    fig.update_yaxes(title="Log growth, 1960–1985", col=1)
    fig.update_layout(title=f"{name} sample: poor countries catch up only once the controls are in",
                      margin=dict(t=120))
    return fig

convergence_figure()
interact(convergence_figure, name=Dropdown(options=list(SAMPLES), value="Intermediate", description="sample",
style=WIDE));Show the code of the website version
# @title Website version: one button per sample
fig = button_figure(convergence_figure, "name", ["Non-oil", "Intermediate", "OECD"], start="Intermediate")
fig.layout.updatemenus[0].y = 1.2                  # above the two-line panel titles
fig.update_layout(margin=dict(t=180))
Sources. Data: Mankiw, Romer and Weil (1992), Appendix. Prepared file: data/appF/mrw1992.csv (see the data notes). Chart: inspired by Figure I of Mankiw, Romer and Weil (1992) and by Fig. 5.9 in Jones (2024), Macroeconomics, 6th ed.
What to notice.
- Panel A has no downward slope: the poorest countries of 1960 did not grow faster than the richest.
- Panels B and C slope down clearly. Among countries with the same saving and population growth (B), and also the same schooling (C), the poorer ones grew faster.
- In the OECD sample all three panels slope down: these countries have similar steady states, so unconditional and conditional convergence look alike.
Your turn. The controls compress the horizontal spread in panels B and C. Why? What does that tell you about how much of the income differences of 1960 the controls already account for?
Hint
The horizontal axis of panel C is the part of log income in 1960 that saving, population growth and schooling do not explain. A narrower spread means they explain much of it: countries that were poor in 1960 were mostly poor because their steady states were low. Compare d["ln_y60"].std() with the standard deviation of partial_out(d, "ln_y60", PANELS[2][1]).
# Your turn: try it hereF.12 Simulation: catch-up between two countries
Fig. 7: Conditional and unconditional convergence in the model
Goal. See why the model predicts conditional, not unconditional, convergence, with two countries that share the same technology.
A rich country invests the baseline rates, \(\bar{s}_K=0.20\) and \(\bar{s}_H=0.10\), and sits on its balanced growth path. A poor country starts at a fraction of the rich country’s income and invests a share of the rich country’s rates, in both kinds of capital. Both have \(\alpha=\beta=1/3\), so the poor country’s steady state is that share squared times the rich country’s (the elasticities of Section F.6 add up to 2). The chart follows income per worker for 100 years, relative to the rich country’s in year 0, on a ratio scale.
def catch_up_figure(rates=1.0, start=0.1):
    """Fig. 7: income per worker of a rich and a poor country; equations (5) and (6)."""
    t = np.arange(101)
    k_rich, h_rich, y_rich = steady_state()
    scale = start ** (1 / (2 / 3))                    # alpha + beta = 2/3
    k, h, y = simulate(0.20 * rates, 0.10 * rates, k_rich * scale, h_rich * scale, years=100)
    poor = y / y_rich * np.exp(0.02 * t)              # technology grows at g = 0.02 in both countries
    rich = np.exp(0.02 * t)
    path = steady_state(0.20 * rates, 0.10 * rates)[2] / y_rich * np.exp(0.02 * t)
    g_poor = 100 * math.log(poor[25] / poor[0]) / 25
    fig = go.Figure()
    fig.add_trace(go.Scatter(x=t, y=rich, mode="lines", name="Rich country", line=dict(color=BLUE, width=3)))
    fig.add_trace(go.Scatter(x=t, y=poor, mode="lines", name="Poor country", line=dict(color=RUST, width=3)))
    fig.add_trace(go.Scatter(x=t, y=path, mode="lines", name="Poor country's own balanced growth path",
                             line=dict(color=RUST, dash="dot")))
    fig.update_layout(title=f"Growth in the first 25 years: poor {g_poor:.1f}%, rich 2.0% a year",
                      xaxis=dict(title="Years", range=[0, 100]),
                      yaxis=dict(title="Income per worker (rich country in year 0 = 1)", type="log",
                                 range=[np.log10(0.02), np.log10(10)], tickvals=[0.03, 0.1, 0.3, 1, 3, 10]),
                      legend=dict(x=0.99, xanchor="right", y=0.02, yanchor="bottom"))
    return fig

catch_up_figure()
interact(catch_up_figure,
rates=FloatSlider(value=1.0, min=0.2, max=1.0, step=0.1, description="poor's investment rates / rich's",
style=WIDE),
start=FloatSlider(value=0.1, min=0.05, max=0.5, step=0.05, description="poor's starting income / rich's",
style=WIDE));Show the code of the website version
# @title Website version: move the poor country's investment rates
slider_figure(catch_up_figure, "rates", [0.2, 0.3, 0.4, 0.5, 0.7, 1.0], start=1.0,
              label="poor's investment rates / rich's")
Source. Model: the augmented Solow model, equations (5) and (6) of this appendix, with \(\alpha=\beta=1/3\), \(\bar{n}=0.01\), \(\bar{g}=0.02\) and \(\bar{d}=0.03\) in both countries. Adapted from the transition dynamics of Chapter 5 in Jones (2024), Macroeconomics, 6th ed.
What to notice.
- With the same investment rates (the slider at 1.0), the poor country grows much faster than the rich one and closes the gap: unconditional and conditional convergence are the same thing.
- With half the rich country’s rates, its own path is a quarter of the rich country’s. It still grows faster at first, while it catches up with its own path, then settles a fixed distance below.
- With rates below about a third of the rich country’s, its steady state lies below where it starts, and it grows slower than the rich country: a poor country that falls further behind, as many did in panel A of Fig. 6. This is exactly what conditional convergence allows.
Your turn. With the poor country’s starting income at 0.1 of the rich country’s, what share of the rich country’s investment rates makes it grow at exactly 2 percent a year, neither catching up nor falling behind?
Hint
It grows at the rich country’s rate when it starts on its own balanced growth path: when its steady state, the share squared times the rich one, equals its starting income. Solve \(\text{share}^2=0.1\): \(\text{share}=\sqrt{0.1}\approx0.32\). Check with catch_up_figure(rates=0.32).
# Your turn: try it hereF.13 Do MRW’s results hold today?
MRW’s data end in 1985 and come from an early version of the Penn World Table. Thirty years of new data, better price surveys and many more countries are now available. This section rebuilds MRW’s variables from the Penn World Table 11.0 and the World Bank’s World Development Indicators (WDI), and runs the regressions again for two windows: 1960–1985, MRW’s own years, and 1990–2023.
The data
The book’s data script (build_data.py) computes, for every economy and window:
| Column | How it is built | MRW’s version |
|---|---|---|
gdppc_start, gdppc_end |
real GDP (rgdpe) / population (pop), first and last year |
GDP per working-age person |
s_k |
100 × average of csh_i, investment as a share of GDP at current PPPs |
real investment share |
n |
average growth of population | growth of working-age population |
school |
WDI secondary enrollment × population aged 15–19 / population aged 15–64, averaged | the same recipe, from UNESCO |
hc_end |
PWT’s human capital index, from years of schooling and their returns, last year | — |
It also flags each economy’s MRW samples and a full sample: every economy with data, except 27 oil producers and the economies with fewer than one million people at the start of the window.
pwt = pd.read_csv(DATA_URL + "pwt_mrw.csv")
pwt["full"] = ((pwt["oil"] == 0) & (pwt["small"] == 0)).astype(int)
pwt["ln_y"] = np.log(pwt["gdppc_end"])
pwt["ln_y0"] = np.log(pwt["gdppc_start"])
pwt["growth"] = pwt["ln_y"] - pwt["ln_y0"]
pwt["ln_s"] = np.log(pwt["s_k"] / 100)
pwt["ln_ngd"] = np.log(pwt["n"] / 100 + G_PLUS_D)
pwt["ln_school"] = np.log(pwt["school"] / 100)
pwt["ln_hc"] = np.log(pwt["hc_end"])
pwt["ln_s_ngd"] = pwt["ln_s"] - pwt["ln_ngd"]
pwt["ln_school_ngd"] = pwt["ln_school"] - pwt["ln_ngd"]
pwt.groupby("window")[["full", "mrw_non_oil", "mrw_intermediate", "mrw_oecd"]].sum()| full | mrw_non_oil | mrw_intermediate | mrw_oecd | |
|---|---|---|---|---|
| window | ||||
| 1960-1985 | 84 | 91 | 74 | 22 |
| 1990-2023 | 123 | 97 | 75 | 22 |
Look at your data first
Before any regression, look at the extremes of each variable. Two stand out.
pwt.sort_values("growth")[["country", "window", "gdppc_start", "gdppc_end", "growth"]].head(3)| country | window | gdppc_start | gdppc_end | growth | |
|---|---|---|---|---|---|
| 286 | Venezuela (Bolivarian Republic of) | 1990-2023 | 10275.0 | 89.326 | -4.745176 |
| 292 | Zimbabwe | 1990-2023 | 6168.5 | 3198.100 | -0.656899 |
| 273 | Tajikistan | 1990-2023 | 7752.2 | 4069.400 | -0.644481 |
Venezuela’s GDP per person falls from about 10,000 dollars in 1990 to under 100 dollars in 2023. That is not a real fall of 99 percent: PWT’s price comparisons broke down during Venezuela’s hyperinflation. Venezuela is in MRW’s non-oil sample, so we drop it from the 1990–2023 window, as Chapter 5 and Appendix D do.
pwt = pwt[~((pwt["iso3"] == "VEN") & (pwt["window"] == "1990-2023"))]
pwt.sort_values("s_k", ascending=False)[["country", "window", "s_k", "small", "oil"]].head(4)| country | window | s_k | small | oil | |
|---|---|---|---|---|---|
| 133 | Bermuda | 1990-2023 | 332.270 | 1 | 0 |
| 269 | Turks and Caicos Islands | 1990-2023 | 76.126 | 1 | 0 |
| 76 | Nigeria | 1960-1985 | 64.652 | 0 | 1 |
| 23 | Cabo Verde | 1960-1985 | 53.157 | 1 | 0 |
PWT’s investment share is measured at current PPP prices, and in a few economies it is implausible: Bermuda’s average is above 300 percent of GDP. The tiny economies are outside the full sample, and Nigeria, an oil producer, is outside it too. Nigeria stays in MRW’s non-oil sample, as MRW had it.
Finally, the WDI’s secondary enrollment rate starts in 1970 and is missing before 1986 for most OECD members.
pwt[pwt["school"].notna()].groupby("window")[["full", "mrw_non_oil", "mrw_intermediate", "mrw_oecd"]].sum()| full | mrw_non_oil | mrw_intermediate | mrw_oecd | |
|---|---|---|---|---|
| window | ||||
| 1960-1985 | 52 | 60 | 43 | 2 |
| 1990-2023 | 121 | 95 | 73 | 22 |
With only 2 OECD economies, the 1960–1985 OECD regressions with school cannot be run. That is one reason to use a second measure of human capital, PWT’s hc index, in the form of equation (8).
Fig. 8: MRW’s data and today’s data, for the same countries
Goal. Check how much the data themselves have changed: compare MRW’s investment rates and 1985 incomes with the PWT 11.0 numbers for the same countries.
both = mrw.merge(pwt[pwt["window"] == "1960-1985"], on="iso3", suffixes=("", "_pwt")).dropna(subset=["gdp_85"])
investment = pd.DataFrame({"country": both["country"], "MRW (1992)": both["inv_gdp"],
                           "PWT 11.0": both["s_k"], "variable": "Investment share of GDP (%)"})
income = pd.DataFrame({"country": both["country"], "MRW (1992)": both["gdp_85"],
                       "PWT 11.0": both["gdppc_end"], "variable": "Income in 1985 (dollars)"})
compare = pd.concat([investment, income])
r_inv = np.corrcoef(np.log(investment["MRW (1992)"]), np.log(investment["PWT 11.0"]))[0, 1]
r_inc = np.corrcoef(np.log(income["MRW (1992)"]), np.log(income["PWT 11.0"]))[0, 1]
fig = px.scatter(compare, x="MRW (1992)", y="PWT 11.0", facet_col="variable", hover_name="country",
                 log_x=True, log_y=True, color_discrete_sequence=[BLUE], facet_col_spacing=0.1,
                 title=f"{len(both)} countries; correlation of the logs: investment {r_inv:.2f}, "
                       f"income {r_inc:.2f}")
fig.update_xaxes(matches=None)
fig.update_yaxes(matches=None, showticklabels=True)
fig.update_xaxes(tickvals=[3, 5, 10, 20, 40], col=1)
fig.update_yaxes(tickvals=[3, 5, 10, 20, 40], col=1)
fig.update_xaxes(tickvals=[300, 1000, 3000, 10000, 30000], col=2)
fig.update_yaxes(tickvals=[300, 1000, 3000, 10000, 30000], col=2)
for panel_title in fig.layout.annotations:
    panel_title.text = panel_title.text.split("=")[-1]     # "variable=Income ..." -> "Income ..."
fig
Sources. Data: Mankiw, Romer and Weil (1992), Appendix; Penn World Table 11.0 (Feenstra, Inklaar and Timmer 2015). Prepared files: data/appF/mrw1992.csv and data/appF/pwt_mrw.csv (see the data notes). Chart: inspired by the discussion of the Penn World Table in Chapter 3 of Jones (2024), Macroeconomics, 6th ed.
Python note.
merge(..., on="iso3")joins two tables by their country codes and keeps the countries found in both.facet_col="variable"draws one panel per value ofvariable;matches=Nonegives each panel its own axes, because investment rates and incomes are in different units.
What to notice.
- Incomes line up closely: the ranking of countries in 1985 has hardly changed, even though PWT 11.0 measures in 2021 dollars and per person, not per working-age person.
- Investment rates agree much less. PWT 11.0 measures investment at current PPP prices, where MRW used constant prices, and the price of machines relative to other goods is much higher in poor countries. So by today’s measure many poor countries invested a larger share than MRW thought.
The regressions again
pwt_estimates runs, for one window, one sample and one measure of human capital, the restricted regressions of this appendix on the same set of countries: the textbook levels regression, the augmented levels regression (equation (7) with school, or equation (8) with the hc index) and the augmented convergence regression (equation (11)). It returns the implied α, β and λ and the fit. A sample with fewer than 15 economies is skipped.
HUMAN = {"ln_school": "School enrollment, eq. (7)", "ln_hc": "PWT hc index, eq. (8)"}
PWT_SAMPLES = {"MRW non-oil": "mrw_non_oil", "MRW intermediate": "mrw_intermediate", "MRW OECD": "mrw_oecd",
               "Full sample": "full"}
LABELS["ln_y0"] = "ln(initial income)"

def pwt_estimates(window, name, human):
    """Implied alpha, beta and λ in PWT 11.0, for one window, sample and measure of human capital."""
    d = pwt[(pwt["window"] == window) & (pwt[PWT_SAMPLES[name]] == 1)].dropna(subset=[human])
    row = {"window": window, "sample": name, "human capital": HUMAN[human], "N": len(d)}
    if len(d) < 15:
        return row
    terms = "ln_s_ngd + ln_school_ngd" if human == "ln_school" else "ln_s_ngd + ln_hc"
    textbook = smf.ols("ln_y ~ ln_s_ngd", data=d).fit()
    levels = smf.ols("ln_y ~ " + terms, data=d).fit()
    growth = smf.ols("growth ~ ln_y0 + " + terms, data=d).fit()
    c_K, c_H = levels.params[terms.split(" + ")[0]], levels.params[terms.split(" + ")[1]]
    if human == "ln_school":
        alpha, beta = implied_shares(c_K, c_H)
    else:
        alpha = c_K / (1 + c_K)                       # equation (8): c_K = alpha/(1-alpha), c_H = beta/(1-alpha)
        beta = c_H * (1 - alpha)
    row.update({"alpha, textbook": implied_shares(textbook.params["ln_s_ngd"])[0],
                "alpha": alpha, "beta": beta, "R², textbook": textbook.rsquared_adj,
                "R², augmented": levels.rsquared_adj,
                "speed (%)": 100 * implied_speed(growth.params["ln_y0"], int(window[-4:]) - int(window[:4]))[0]})
    return row
rows = []
for window in ["1960-1985", "1990-2023"]:
for name in PWT_SAMPLES:
for human in HUMAN:
rows.append(pwt_estimates(window, name, human))
estimates = pd.DataFrame(rows)
estimates.round(2)| window | sample | human capital | N | alpha, textbook | alpha | beta | R², textbook | R², augmented | speed (%) | |
|---|---|---|---|---|---|---|---|---|---|---|
| 0 | 1960-1985 | MRW non-oil | School enrollment, eq. (7) | 60 | 0.37 | 0.19 | 0.28 | 0.20 | 0.54 | 1.66 |
| 1 | 1960-1985 | MRW non-oil | PWT hc index, eq. (8) | 90 | 0.52 | 0.28 | 1.67 | 0.46 | 0.81 | 2.15 |
| 2 | 1960-1985 | MRW intermediate | School enrollment, eq. (7) | 43 | 0.40 | 0.22 | 0.27 | 0.27 | 0.47 | 1.24 |
| 3 | 1960-1985 | MRW intermediate | PWT hc index, eq. (8) | 74 | 0.54 | 0.35 | 1.30 | 0.53 | 0.78 | 2.03 |
| 4 | 1960-1985 | MRW OECD | School enrollment, eq. (7) | 2 | NaN | NaN | NaN | NaN | NaN | NaN |
| 5 | 1960-1985 | MRW OECD | PWT hc index, eq. (8) | 22 | 0.40 | 0.13 | 1.37 | 0.13 | 0.77 | 3.23 |
| 6 | 1960-1985 | Full sample | School enrollment, eq. (7) | 52 | 0.32 | 0.13 | 0.30 | 0.13 | 0.46 | 1.30 |
| 7 | 1960-1985 | Full sample | PWT hc index, eq. (8) | 83 | 0.54 | 0.23 | 1.91 | 0.50 | 0.81 | 2.03 |
| 8 | 1990-2023 | MRW non-oil | School enrollment, eq. (7) | 95 | 0.70 | 0.46 | 0.27 | 0.63 | 0.77 | 1.31 |
| 9 | 1990-2023 | MRW non-oil | PWT hc index, eq. (8) | 94 | 0.70 | 0.53 | 1.26 | 0.61 | 0.84 | 1.76 |
| 10 | 1990-2023 | MRW intermediate | School enrollment, eq. (7) | 73 | 0.69 | 0.47 | 0.27 | 0.62 | 0.72 | 1.45 |
| 11 | 1990-2023 | MRW intermediate | PWT hc index, eq. (8) | 74 | 0.69 | 0.53 | 1.22 | 0.60 | 0.81 | 1.77 |
| 12 | 1990-2023 | MRW OECD | School enrollment, eq. (7) | 22 | 0.03 | 0.05 | 0.15 | -0.05 | -0.09 | 1.80 |
| 13 | 1990-2023 | MRW OECD | PWT hc index, eq. (8) | 22 | 0.03 | 0.15 | 1.21 | -0.05 | 0.20 | 2.87 |
| 14 | 1990-2023 | Full sample | School enrollment, eq. (7) | 121 | 0.69 | 0.47 | 0.25 | 0.62 | 0.73 | 1.54 |
| 15 | 1990-2023 | Full sample | PWT hc index, eq. (8) | 114 | 0.69 | 0.53 | 1.19 | 0.61 | 0.82 | 1.98 |
Python note.
row.update({...})adds several entries to a dictionary at once. A dictionary that misses a key becomes a missing value (NaN) in the table, which is how the skipped samples show up.
Fig. 9: MRW’s estimates, then and now
Goal. Compare the implied parameters across windows, samples and measures of human capital, with MRW’s own estimates as a benchmark.
PARAMETERS = {"alpha": ("Implied α", [0, 1.2]), "beta": ("Implied β", [0, 2.2]),
              "speed (%)": ("Implied speed of convergence λ, % a year", [0, 4]),
              "R², augmented": ("Adjusted R², augmented model", [-0.1, 1])}
# Our replication of MRW's non-oil estimates (Sections F.8 and F.11) as the benchmark
mrw_alpha, mrw_beta = implied_shares(augmented_r[0].params["ln_s_ngd"], augmented_r[0].params["ln_school_ngd"])
MRW_BENCHMARK = {"alpha": round(mrw_alpha, 2), "beta": round(mrw_beta, 2),
                 "speed (%)": round(100 * implied_speed(restricted[0].params["ln_y60"], 25)[0], 2),
                 "R², augmented": round(augmented_r[0].rsquared_adj, 2)}

def estimates_figure(parameter="alpha"):
    """Fig. 9: one implied parameter by sample, window and measure of human capital."""
    label, y_range = PARAMETERS[parameter]
    fig = px.bar(estimates, x="sample", y=parameter, color="human capital", barmode="group", facet_col="window",
                 color_discrete_sequence=[TEAL, RUST], range_y=y_range,
                 labels={parameter: label, "sample": "", "human capital": "Human capital"},
                 title=f"{label}: MRW's non-oil estimate is {MRW_BENCHMARK[parameter]}")
    fig.add_hline(y=MRW_BENCHMARK[parameter], line=dict(color="black", dash="dot"))
    short = []
    for name in PWT_SAMPLES:
        short.append(name.replace(" ", "<br>"))      # two-line labels fit under the bars
    fig.update_xaxes(tickangle=0, tickvals=list(PWT_SAMPLES), ticktext=short)
    for panel_title in fig.layout.annotations:
        panel_title.text = panel_title.text.split("=")[-1]
    fig.update_layout(legend=dict(orientation="h", y=-0.2))
    return fig

estimates_figure()
interact(estimates_figure, parameter=Dropdown(options=list(PARAMETERS), value="alpha", description="parameter",
style=WIDE));Show the code of the website version
# @title Website version: one button per parameter
fig = button_figure(estimates_figure, "parameter", ["alpha", "beta", "speed (%)", "R², augmented"], start="alpha")
fig.layout.updatemenus[0].y = 1.1                  # above the panel titles
fig.update_layout(margin=dict(t=160))
Sources. Data: Penn World Table 11.0 (Feenstra, Inklaar and Timmer 2015); World Bank, World Development Indicators, School enrollment, secondary (SE.SEC.ENRR) and Population ages 15–64 (SP.POP.1564.TO). Prepared file: data/appF/pwt_mrw.csv (see the data notes). Benchmarks: Mankiw, Romer and Weil (1992), Tables II and VI, non-oil sample. Chart: inspired by the discussion of the Solow model in Chapter 5 of Jones (2024), Macroeconomics, 6th ed.
What to notice.
- The textbook puzzle is still there, and larger. In 1990–2023 the textbook regression implies α of about 0.7 in every sample outside the OECD (the column
alpha, textbookof the table), even higher than MRW’s 0.6. Saving and population growth still matter far more than a capital share of one third allows. - With MRW’s schooling measure, β is remarkably stable. In 1990–2023 the implied β is 0.25 to 0.27 in the non-oil, intermediate and full samples, next to MRW’s 0.28. The implied α, about 0.47, is higher than MRW’s 0.31. In 1960–1985, with enrollment only for 43 to 60 economies, β is again 0.27 to 0.30 and α is lower.
- With the
hcindex, β is far too large. The coefficient on ln(h) is about 2.5 in the full samples, so the implied β is 1.2 to 1.9, above \(1-\alpha\): impossible in the model. The log of the index varies little across countries (a standard deviation of about 0.3, against 1.2 for log income), so the regression needs a large coefficient to match income gaps with it. This is the measurement problem that Section F.14 discusses. - The fit holds up. With either measure, the augmented model explains 72 to 84 percent of the variation in log income outside the OECD in 1990–2023, close to MRW’s 78 percent.
- So does the speed of convergence. Outside the OECD, every window, sample and measure gives λ between 1.2 and 2.2 percent a year, around MRW’s 1.4 percent and the model’s 2 percent.
- Within the OECD, nothing fits in 1990–2023: the adjusted \(R^2\) is near zero or negative. Rich countries have become too similar in saving, schooling and population growth for these variables to explain their remaining differences.
Your turn. Run the 1990–2023 regressions on the full sample with the textbook model only. Is the implied α still far above one third?
Hint
The column alpha, textbook of estimates already has it. To run it yourself: d = pwt[(pwt["window"] == "1990-2023") & (pwt["full"] == 1)], then smf.ols("ln_y ~ ln_s_ngd", data=d).fit().params and implied_shares(c)[0] for the coefficient c.
# Your turn: try it hereF.14 Go further
- Is saving really unrelated to \(A(0)\)? The regressions assume that \(\bar{s}_K\) and \(\bar{n}\) are unrelated to the country’s technology and institutions. But a country with good institutions may both invest more and use its capital better, which would bias the coefficients up. Panel-data studies, such as Islam (1995), let each country have its own \(A(0)\) and find faster convergence and a smaller role for capital.
- Better measures of human capital. SCHOOL measures the flow into secondary school, and the
hcindex the years of schooling, not what students learn. Hanushek and Woessmann (2012) use test scores and find that cognitive skills matter far more for growth than years in school. - How much is left for technology? Klenow and Rodríguez-Clare (1997) argue that MRW’s SCHOOL varies much more across countries than years of schooling do, which overstates the role of human capital. With better measures, differences in productivity explain about half of income differences, as the development accounting of Appendix D finds.
- Is growth exogenous? Bernanke and Gürkaynak (2001) re-run MRW on later data and find that the levels results hold up, but that long-run growth rates are correlated with saving, which the Solow model, with its exogenous \(\bar{g}\), cannot explain. Chapter 6 turns to the models of ideas that can.
Common errors and how to fix them
| Error or symptom | What it usually means | What to do |
|---|---|---|
PatsyError: Error evaluating factor |
a name in the formula is not a column of the data | print data.columns and copy the exact name |
| a regression has fewer countries than its sample | rows with a missing value in any variable of the formula are dropped | count them with d[["ln_y85", "ln_school"]].isna().sum() |
KeyError: 'ln_school' in reg_table |
a coefficient name that LABELS does not know |
add it: LABELS["new_name"] = "readable name" |
ValueError: math domain error in implied_speed |
the slope \(b\) is −1 or less, so \(\ln(1+b)\) is undefined | check the regression; such a slope means more than full convergence |
| an implied β above 1 | the coefficient on human capital is too large for the model’s restriction \(\alpha+\beta<1\) | read it as a sign that the measure of human capital, not the model, is off |
| a panel of Fig. 6 is empty | the sample has no countries with all the variables | choose another sample |
Concluding remarks
- The textbook Solow model, equation (3), predicts the signs of the effects of saving and population growth on income, and they explain about 59 percent of income differences across countries in 1985. But the size of the effects implies a capital share of about 0.6, twice capital’s share of income.
- The augmented model, equation (7), adds human capital. With \(\alpha=\beta=1/3\) it doubles the elasticity of income to saving (Fig. 2), and in MRW’s data it fits with α and β of about 0.3 each and explains almost 80 percent of income differences.
- The model predicts conditional, not unconditional, convergence, at the speed of equation (9): about 2 percent a year with human capital, half the textbook speed (Figs. 5 and 7). MRW’s growth regressions, turned into speeds with equation (12), find 1.4 to 2.1 percent a year.
- With PWT 11.0 and the WDI, for 1990–2023 and many more countries, the main results survive: a large textbook α, a β near 0.27 with MRW’s schooling measure, a fit of about three quarters and a speed of 1.3 to 2 percent. How we measure human capital matters, and PWT’s
hcindex gives implausibly large shares. - The model takes the investment rates, schooling and population growth as given, and leaves the technology term \(A(0)\) unexplained. Chapter 6 turns to the ideas behind technology, and Appendix D measures how much of income differences it accounts for.
References
- Bernanke, B. S., and Gürkaynak, R. S. (2001). Is Growth Exogenous? Taking Mankiw, Romer, and Weil Seriously. NBER Macroeconomics Annual 16, 11–57.
- Feenstra, R. C., Inklaar, R., and Timmer, M. P. (2015). The Next Generation of the Penn World Table. American Economic Review 105(10), 3150–3182. Data: Penn World Table 11.0, doi:10.34894/FABVLR.
- Hanushek, E. A., and Woessmann, L. (2012). Do Better Schools Lead to More Growth? Cognitive Skills, Economic Outcomes, and Causation. Journal of Economic Growth 17(4), 267–321.
- Islam, N. (1995). Growth Empirics: A Panel Data Approach. Quarterly Journal of Economics 110(4), 1127–1170.
- Jones, C. I. (2024). Macroeconomics, 6th ed. W. W. Norton.
- Klenow, P. J., and Rodríguez-Clare, A. (1997). The Neoclassical Revival in Growth Economics: Has It Gone Too Far? NBER Macroeconomics Annual 12, 73–103.
- Mankiw, N. G., Romer, D., and Weil, D. N. (1992). A Contribution to the Empirics of Economic Growth. Quarterly Journal of Economics 107(2), 407–437. doi:10.2307/2118477.
- Solow, R. M. (1956). A Contribution to the Theory of Economic Growth. Quarterly Journal of Economics 70(1), 65–94.
- Summers, R., and Heston, A. (1988). A New Set of International Comparisons of Real Product and Price Levels Estimates for 130 Countries, 1950–1985. Review of Income and Wealth 34(1), 1–25.
- World Bank. World Development Indicators, School enrollment, secondary (% gross) and Population ages 15–64.