# Install the two regression libraries of this appendix (Colab does not have them)
%pip install -q --disable-pip-version-check pyfixest linearmodels
Note: you may need to restart the kernel to use updated packages.
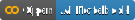

Rich countries have more capital and more schooling than poor ones. But Chapter 4 and Appendix D showed that most of the gap comes from total factor productivity (TFP): rich countries also use their capital and their workers much better. Why? A leading answer is institutions, the rules that decide whether people can keep what they build, sign contracts that courts enforce, and invest without fear that a ruler will take it away. Countries with good institutions are clearly richer. The hard question is whether the institutions cause the prosperity, or only go together with it. In a famous paper, Acemoglu, Johnson and Robinson (2001), “AJR” from now on, proposed a way to answer it, with a clever use of history and a tool from econometrics called instrumental variables (IV). This appendix rebuilds their argument and runs their regressions on their data. By the end of it you will be able to:
This appendix builds on my tutorial Do Institutions Cause Prosperity? An IV Tutorial in Python, which goes further into the robustness checks of AJR (Section G.11 lists them).
| Section | What you do | Builds on |
|---|---|---|
| G.1 | The question: do institutions cause prosperity? | Chapter 4, Appendix D |
| G.2 | Set up the libraries and the regression tools | Appendix A |
| G.3 | Derive the model: institutions, income, and why a regression can mislead | Chapters 4 and 5, Appendix C |
| G.4 | Simulation: when OLS fails and IV works | — |
| G.5 | Meet AJR’s data | Chapter 3 |
| G.6 | Run the naive OLS regressions | Appendix F |
| G.7 | The instrument: settler mortality, the first stage and the reduced form | — |
| G.8 | The 2SLS estimate and its tests | — |
| G.9 | OLS against IV: what the gap means | — |
| G.10 | Discussion and limits | — |
| G.11 | Go further | — |
The regressions of Sections G.6 to G.9 replicate the main columns of Tables 2 and 4 of AJR. The robustness tables 5 to 8 of the paper are left for Section G.11 and the tutorial.
Economists distinguish two kinds of causes of income differences. The proximate causes are the ones the production model of Chapter 4 measures: capital per worker, schooling, and TFP. But they only push the question back. Why do some countries invest so little, school their children so little, and use what they have so badly? The fundamental causes are the answers to that question. Three are discussed most: geography (climate, disease, soils, access to the sea), culture (values and beliefs), and institutions.
The economic historian Douglass North called institutions “the rules of the game in a society”. Good economic institutions protect property, enforce contracts, and give a broad part of the population the chance to invest and innovate. Bad ones let a small elite take what others produce. Two examples make the case vivid. North and South Korea share their history, culture and geography, but not their institutions since 1945; the satellite photograph of the Korean peninsula at night, discussed in Chapter 4, shows the result. And Botswana, which kept secure property rights and stable rules after independence, grew faster than almost any country in the world for three decades, while many of its neighbors stagnated.
Examples are not proof. Across all countries, a better measure of institutions goes with higher income (Fig. 2 shows it). But the correlation alone cannot tell us which way the arrow points. Rich countries can afford good courts. And something else, such as a healthy climate, may give a country both good institutions and high income. AJR’s idea was to find a piece of history that changed the institutions of some countries and not others, for reasons that have nothing to do with their income today. Section G.3 shows why such a piece of history, an instrument, solves the problem, and Sections G.7 and G.8 put AJR’s choice to work.
The setup cells install two libraries, load the others, and set the look of the charts. The two new libraries run regressions with the standard errors and tests that economists report:
They do not come with Colab, so the first cell installs them. It takes a few seconds.
# Install the two regression libraries of this appendix (Colab does not have them)
%pip install -q --disable-pip-version-check pyfixest linearmodelsNote: you may need to restart the kernel to use updated packages.# Libraries used in this appendix
import numpy as np # numbers and arrays
import pandas as pd # data tables
import plotly.express as px # quick charts from data tables
import plotly.graph_objects as go # charts built piece by piece
import plotly.io as pio
import pyfixest as pf # regressions as formulas, including IV
from linearmodels.iv import IV2SLS # IV regressions with tests of the instrument
from ipywidgets import interact, FloatSlider, Dropdown, ToggleButtons
# One light blue/green look for every chart
BLUE, TEAL, GREEN, GRAY, RUST = "#16528c", "#008070", "#7fb23a", "#8a96a3", "#c4651a"
pio.templates.default = "plotly_white"
# the same size in Colab and on the website
pio.templates["plotly_white"].layout.update(width=860, height=480)
px.defaults.color_discrete_sequence = [BLUE, TEAL, GREEN, RUST, "#8e5ea2", "#5aa0d8"]
WIDE = {"description_width": "initial"} # show the full widget labels
# Colab only: let Plotly charts appear inside the interactive widgets
try:
import google.colab
google.colab.output.enable_custom_widget_manager()
except ImportError:
pass # not running in Colab: nothing to do
# The data file of this appendix lives in the book's GitHub repository
DATA_URL = "https://raw.githubusercontent.com/quarcs-lab/macro102-site/main/data/appG/"# @title Helper for the website versions (run this cell; you do not need to read it)
def button_figure(make_figure, name, values, start):
"""Precompute make_figure(name=value) for each value; one button per value.
The website cannot run Python, so each interactive figure also gets this
precomputed version.
"""
figures = [make_figure(**{name: v}) for v in values]
first = values.index(start)
fig = go.Figure(layout=figures[first].layout)
owner = [] # which precomputed figure each trace comes from
for i, f in enumerate(figures):
for trace in f.data:
trace.visible = i == first
fig.add_trace(trace)
owner.append(i)
buttons = []
for i, f in enumerate(figures):
layout = {
"title": f.layout.title.to_plotly_json(),
"yaxis": f.layout.yaxis.to_plotly_json(),
"annotations": [a.to_plotly_json() for a in f.layout.annotations],
"shapes": [s.to_plotly_json() for s in f.layout.shapes],
}
visible = [o == i for o in owner]
buttons.append(
dict(
label=str(values[i]),
method="update",
args=[{"visible": visible}, layout],
)
)
fig.update_layout(
updatemenus=[
dict(
type="buttons",
direction="right",
buttons=buttons,
active=first,
x=0,
y=1.02,
xanchor="left",
yanchor="bottom",
)
],
margin=dict(t=130),
)
return figWe run the same few kinds of regression many times. Four short functions do the work. ols_fit runs OLS with pyfixest. Like AJR, it uses robust standard errors (called HC1), which stay valid when the spread of the errors differs from country to country. coef_table puts several OLS regressions side by side.
def ols_fit(formula, data):
    """OLS with robust (HC1) standard errors; rows with a missing value are dropped."""
    return pf.feols(formula, data=data, vcov="HC1")


def coef_table(models, names, term="avexpr"):
    """One row per regression: the coefficient on term, its standard error and N."""
    rows = []
    for model, name in zip(models, names):
        rows.append(
            {
                "regression": name,
                "coefficient": model.coef()[term],
                "std. error": model.se()[term],
                "countries": len(model.resid()),
            }
        )
    return pd.DataFrame(rows).set_index("regression").round(3)
Python note.
pf.feols("logpgp95 ~ avexpr", data=d)reads like the regression equation: the variable on the left of~is explained by the variables on the right, and a constant is added automatically. The fitted model answers questions through its methods:.coef()gives the coefficients,.se()their standard errors and.resid()the residuals, one per country used. Each is a pandas Series indexed by the variable names, somodel.coef()["avexpr"]is the coefficient onavexpr.
iv_fit runs the IV regression of AJR with linearmodels: log income on institutions, with institutions instrumented by log settler mortality, plus any control variables. add_line draws a fitted line on a chart, and first_stage_F reads off the test of the instrument that Section G.8 explains.
def iv_fit(data, controls=()):
    """2SLS of logpgp95 on avexpr, instrumented by logem4 (linearmodels)."""
    controls = list(controls)
    d = data.dropna(subset=["logpgp95", "avexpr", "logem4"] + controls)
    exog = d[controls].assign(const=1.0)  # the controls and a constant
    return IV2SLS(d["logpgp95"], exog, d[["avexpr"]], d[["logem4"]]).fit(
        cov_type="robust"
    )


def add_line(fig, x, y, name="OLS line"):
    """Add a dashed black line through the points (x, y) to a figure."""
    fig.add_trace(
        go.Scatter(x=x, y=y, mode="lines", name=name, line=dict(color="black", dash="dash"))
    )


def first_stage_F(result):
    """The robust F statistic of the first stage: how strongly Z moves institutions."""
    return float(result.first_stage.diagnostics.loc["avexpr", "f.stat"])
Python note.
IV2SLS(y, exog, endog, instruments)takes four pieces: the outcome, the exogenous variables (the constant and the controls), the endogenous variable that needs an instrument, and the instruments. linearmodels does not add a constant by itself, so.assign(const=1.0)adds a column of ones.cov_type="robust"asks for robust standard errors.
Picture Islandia again, but this time not alone. It sits in an archipelago of many island countries that make the same goods with the same kind of boats and tools. On some islands a boat builder can be sure that the boat she builds stays hers. On others a chief can seize it, and the courts do nothing. Islanders on the secure islands build more boats and try new ways to fish; on the insecure ones they do neither. This section turns that story into the models of Chapters 4 and 5, derives the regression that AJR estimate, and shows why running it the simple way can mislead.
The question. Do better institutions cause higher income, and by how much?
The answer in one sentence. In the growth models, institutions raise income through productivity and investment, which gives a straight line between log income and institutions. A simple regression gets its slope wrong whenever institutions are tied to other causes of income or measured with error, but an instrument, a force that moved institutions and nothing else, recovers it as a ratio of two slopes.
What goes in and what comes out. We choose how strongly institutions raise productivity and investment. The model gives back the effect of institutions on long-run income, the slope that OLS finds, and the slope that IV finds.
Road map.
Notation. A bar over a letter marks a parameter. Subscript \(i\) is an island (or, in the data, a country).
| Symbol | Meaning | Type |
|---|---|---|
| \(y_i\) | output per worker in the steady state | endogenous |
| \(\bar{A}_i\), \(\bar{s}_i\) | productivity (TFP) and the investment rate | depend on institutions |
| \(R_i\) | institutions: how secure property is, on a 0 to 10 scale | data |
| \(\bar{\phi}\), \(\bar{\psi}\) | the effects of institutions on \(\ln \bar{A}\) and \(\ln \bar{s}\) | parameters |
| \(\beta\) | the total effect of institutions on log income | parameter we want |
| \(u_i\) | everything else that moves log income | error term |
| \(Z_i\) | the instrument (in the data: log settler mortality) | data |
| \(\pi\), \(\rho\) | the slopes of the first stage and of the reduced form | parameters |
| \(\widehat{b}\) | a hat marks an estimate computed from data | estimate |
1. Production. Each island makes output with capital and workers, with the production function of Chapter 4. Per worker it reads
\[y_i = \bar{A}_i k_i^{1/3}.\]
2. Capital accumulation. Each island invests a share \(\bar{s}_i\) of output, and capital wears out at the rate \(\bar{d}\), the same everywhere. As in Chapter 5, capital per worker settles where investment just covers depreciation, and steady-state output per worker is
\[y_i^* = \bar{A}_i^{3/2}\left(\frac{\bar{s}_i}{\bar{d}}\right)^{1/2}.\]
3. Institutions raise productivity and investment. An island with more secure property uses its tools and workers better and invests more. We write both effects in logs, with \(R_i\) the security of property:
\[\ln \bar{A}_i = a_0 + \bar{\phi}R_i + \varepsilon_i^A, \qquad \ln \bar{s}_i = s_0 + \bar{\psi}R_i + \varepsilon_i^s.\]
The terms \(\varepsilon_i^A\) and \(\varepsilon_i^s\) hold everything else that makes an island productive or thrifty: its soil, its harbors, its climate, its luck.
Institutions matter twice: they decide how well an island uses its tools, and how many tools it builds.
Step 1: take logs. The log of a product is the sum of the logs, and the log of a power is the exponent times the log (Appendix C):
\[\ln y_i^* = \tfrac{3}{2}\ln \bar{A}_i + \tfrac{1}{2}\ln \bar{s}_i - \tfrac{1}{2}\ln \bar{d}.\]
Step 2: put in the two rules of assumption 3. Collect the terms that are the same on every island into a constant \(\mu\), the terms with \(R_i\), and the rest:
\[\ln y_i^* = \underbrace{\tfrac{3}{2}a_0 + \tfrac{1}{2}s_0 - \tfrac{1}{2}\ln \bar{d}}_{\mu} + \underbrace{\left(\tfrac{3}{2}\bar{\phi} + \tfrac{1}{2}\bar{\psi}\right)}_{\beta}R_i + \underbrace{\tfrac{3}{2}\varepsilon_i^A + \tfrac{1}{2}\varepsilon_i^s}_{u_i}.\]
\[\ln y_i = \mu + \beta R_i + u_i \tag{1}\]
\[\beta = \tfrac{3}{2}\bar{\phi} + \tfrac{1}{2}\bar{\psi} \tag{2}\]
Equation (1) is the regression that AJR estimate, with log GDP per person for \(\ln y_i\). Equation (2) says what its slope means: the total long-run effect of institutions, through productivity (weighted by \(3/2\)) and through investment (weighted by \(1/2\)).
Islandia in numbers. In this appendix’s baseline, \(\bar{\phi} = \bar{\psi} = 0.5\), so \(\beta = 0.75 + 0.25 = 1\). One more point of secure property raises log income by 1, which multiplies income by \(e^1 \approx 2.7\).
Productivity gets the larger weight for the same reason as in Chapter 5: better productivity raises output directly, and the extra output is partly invested, which raises capital and output again. A higher investment rate works only through capital, and diminishing returns damp it.
Comparing two islands. Write equation (1) for two islands and subtract. The constant cancels:
\[\ln y_1 - \ln y_2 = \beta\,(R_1 - R_2) + (u_1 - u_2).\]
With \(\beta = 1\), an island whose institutions score 2 points higher is, other things equal, \(e^2 \approx 7.4\) times as rich. Institutions that differ by a few points can explain income gaps of the size we see between rich and poor countries.
A line through the cloud. If we plot \(\ln y_i\) against \(R_i\) for many islands, equation (1) says the points scatter around a straight line with slope \(\beta\). The scatter comes from \(u_i\): the islands differ in many ways besides their institutions.
In the model, log income is a straight line in institutions, and the slope is the effect we are after.
1. Suppose institutions raise productivity (\(\bar{\phi} = 0.5\)) but do not change the investment rate (\(\bar{\psi} = 0\)). What is \(\beta\)?
Equation (2) gives \(\beta = \tfrac{3}{2}\times 0.5 + 0 = 0.75\). Institutions still matter a lot, through productivity alone.
2. Two islands differ by 1 point in \(R\), and \(\beta = 1\). Is the richer island exactly \(e \approx 2.7\) times as rich?
Only on average. The gap is \(\beta(R_1-R_2) + (u_1-u_2)\), and the second term can be positive or negative: the islands also differ in soil, harbors and luck.
The obvious way to estimate \(\beta\) is to fit a line through the cloud of countries by OLS. The OLS slope is the covariance of log income with institutions divided by the variance of institutions. Put equation (1) into the covariance, and use \(\text{Cov}(R, R) = \text{Var}(R)\):
\[\widehat{b}_{OLS} = \frac{\text{Cov}(\ln y, R)}{\text{Var}(R)} = \frac{\text{Cov}(\mu + \beta R + u,\, R)}{\text{Var}(R)} = \beta + \frac{\text{Cov}(R, u)}{\text{Var}(R)}. \tag{3}\]
OLS finds \(\beta\) only when institutions are unrelated to everything else in \(u\). A regressor that is related to the error term is called endogenous. There are three reasons why institutions may be endogenous.
Omitted variables. Suppose a healthy climate makes an island productive (it is in \(u\)) and also lets its people build good institutions. Then \(\text{Cov}(R, u) > 0\), and OLS gives the climate’s credit to the institutions: the slope is too steep.
Reverse causality. Suppose income also shapes institutions, because rich islands can pay for honest judges. Then a lucky year, a high \(u_i\), raises income and through it \(R_i\). Again \(\text{Cov}(R, u) > 0\), and OLS is too steep.
Measurement error. We never see the true security of property, only an index \(\tilde{R}_i = R_i + m_i\), built from the judgment of experts, with an error \(m_i\) that is unrelated to everything else. Regress log income on the index instead of the truth. The numerator becomes \(\text{Cov}(\ln y, \tilde{R}) = \beta\,\text{Var}(R)\), the denominator \(\text{Var}(\tilde{R}) = \text{Var}(R) + \text{Var}(m)\), so
\[\widehat{b}_{OLS} = \beta\,\frac{\text{Var}(R)}{\text{Var}(R) + \text{Var}(m)}. \tag{4}\]
The fraction is below one: noise in the index flattens the line. This is called attenuation bias.
The first two biases make OLS too large, the third makes it too small. Which one wins is an empirical question, and the answer in Section G.9 is a surprise: OLS turns out to be too small.
OLS measures how institutions and income move together, which is the causal effect only when nothing else moves with them.
1. The noise in the index has half the variance of the true institutions, and \(\beta = 1\). Where does OLS end up?
Equation (4) gives \(1 \times 1/(1 + 0.5) = 2/3 \approx 0.67\): a third of the effect is lost.
2. Why does collecting more countries not fix any of the three biases?
Equations (3) and (4) do not depend on the number of countries. More data make the OLS slope more precise, but precisely wrong: it settles on \(\beta\) plus the bias, not on \(\beta\).
Long ago, sailors explored the archipelago. On some islands deadly fevers killed most newcomers, so the sailors did not stay. They set up a few trading posts with harsh rules, built to ship goods away, and left. On the healthy islands they settled with their families and wrote rules that protected their own property. The rules outlived the sailors. Let \(Z_i\) be how deadly the fevers were. Two assumptions make \(Z_i\) an instrument:
Relevance can be checked in the data. Exclusion cannot: it is an argument about history, and Section G.10 weighs it.
Step 1: the reduced form. Put the first stage (5) into equation (1):
\[\ln y_i = \mu + \beta(\pi_0 + \pi Z_i + v_i) + u_i = (\mu + \beta\pi_0) + \beta\pi\,Z_i + (\beta v_i + u_i).\]
So log income is a straight line in \(Z_i\) too, the reduced form, with slope \(\rho = \beta\pi\).
Step 2: divide. The first-stage slope \(\pi\) says how much the fevers moved institutions; the reduced-form slope \(\rho\) says how much they moved income. If the fevers reach income only through institutions, the second is the first times \(\beta\), so \(\beta\) is their ratio. Each slope is a covariance with \(Z\) divided by \(\text{Var}(Z)\), which cancels:
\[\rho = \beta\pi \tag{6}\]
\[\widehat{b}_{IV} = \frac{\widehat{\rho}}{\widehat{\pi}} = \frac{\text{Cov}(\ln y, Z)}{\text{Cov}(\tilde{R}, Z)} \tag{7}\]
The IV estimate is the reduced-form slope divided by the first-stage slope. It uses only the part of the differences in institutions that the instrument created.
Step 3: why measurement error does no harm. In equation (7) the index \(\tilde{R} = R + m\) appears only in a covariance with \(Z\). The noise \(m\) is unrelated to the old fevers, so \(\text{Cov}(\tilde{R}, Z) = \text{Cov}(R, Z)\), and the IV estimate is not flattened. This is one reason IV and OLS can differ.
Step 4: two stages give the same number. The name two-stage least squares describes another way to compute (7). First regress \(\tilde{R}\) on \(Z\) and keep the fitted values \(\widehat{R}_i = \widehat{\pi}_0 + \widehat{\pi}Z_i\). Then regress \(\ln y\) on \(\widehat{R}\) by OLS. Since \(\text{Cov}(\ln y, \widehat{R}) = \widehat{\pi}\,\text{Cov}(\ln y, Z)\) and \(\text{Var}(\widehat{R}) = \widehat{\pi}^2\,\text{Var}(Z)\), the slope of the second stage is \(\widehat{\rho}/\widehat{\pi}\) again.
An instrument is like a natural experiment. History “assigned” deadly fevers to some islands and not others, and the fevers changed their rules. Comparing the incomes of fever and healthy islands, and scaling by how much their rules differ, gives the effect of the rules, with the climate, the luck and the noise in the index all left out.
A weak instrument amplifies small problems. Suppose exclusion fails a little, \(\text{Cov}(Z, u) \neq 0\). Put equation (1) into the numerator of (7):
\[\widehat{b}_{IV} = \beta + \frac{\text{Cov}(Z, u)}{\text{Cov}(R, Z)}. \tag{8}\]
The bias is a small number divided by \(\text{Cov}(R, Z)\). If the instrument moves institutions only a little, the denominator is small, and a small violation, or plain bad luck in a sample of 64 countries, becomes a large error. That is why Section G.8 tests how strong the instrument is.
A local effect. If institutions matter more in some countries than in others, the IV estimate averages the effect over the countries whose institutions the instrument actually moved: the former colonies whose rules were set by how deadly they were for settlers. It is a local average treatment effect (LATE), not a statement about every country in the world.
IV trades one strong assumption, exclusion, for the many weak ones that OLS needs, and it is only as good as that assumption and the strength of the instrument.
1. The fevers lower institutions by 0.6 points per unit (\(\pi = -0.6\)) and lower log income by 0.57 per unit (\(\rho = -0.57\)). What is the IV estimate?
Equation (7): \(-0.57/-0.6 = 0.95\). Both slopes are negative, so the ratio is positive: better institutions raise income.
2. Suppose the old fevers still make islanders sick today, and sick workers produce less. Which assumption fails, and in which direction does the IV estimate move?
Exclusion fails: the fevers now also sit in \(u\), lowering income, so \(\text{Cov}(Z, u) < 0\). The first stage is negative too, \(\text{Cov}(R, Z) < 0\), so the ratio in (8) is positive: the IV estimate is too large. Part of the health effect is counted as an effect of institutions.
Now we turn the key results into Python and check them with numbers. First equation (2), for Islandia’s baseline.
PHI, PSI = 0.5, 0.5  # effects of institutions on ln A and on ln s


def total_effect(phi, psi):
    """Equation (2): the long-run effect of institutions on log income per worker."""
    return 1.5 * phi + 0.5 * psi


BETA = total_effect(PHI, PSI)
print(f"beta = {BETA:.2f}: one more point multiplies income by {np.exp(BETA):.2f}")
print(f"two islands 2 points apart: one is {np.exp(2 * BETA):.1f} times as rich")
beta = 1.00: one more point multiplies income by 2.72
two islands 2 points apart: one is 7.4 times as richNext, an archipelago we can build ourselves. simulate_islands draws n islands that follow equations (1) and (5): an instrument fever, an omitted factor other (say, a healthy climate) that raises both institutions and income, the true institutions R, an index R_obs measured with noise, and log income ln_y. Three arguments set the three problems: confound (how strongly the omitted factor shapes institutions), noise (the measurement error) and strength (how strongly the fevers moved institutions).
def simulate_islands(n, beta=1.0, confound=0.5, noise=1.0, strength=0.6, seed=0):
    """An archipelago of n islands that follows equations (1) and (5): a data table."""
    rng = np.random.default_rng(seed)
    fever = rng.normal(size=n)  # the instrument Z
    other = rng.normal(size=n)  # an omitted factor, part of u
    R = 5 - strength * fever + confound * other + rng.normal(scale=0.8, size=n)
    ln_y = 2 + beta * R + 0.5 * other + rng.normal(scale=0.5, size=n)  # equation (1)
    R_obs = R + rng.normal(scale=noise, size=n)  # the measured index
    return pd.DataFrame({"fever": fever, "R": R, "R_obs": R_obs, "ln_y": ln_y})


def ols_slope(y, x):
    """The OLS slope Cov(y, x) / Var(x), as in equation (3)."""
    return np.cov(x, y)[0, 1] / np.var(x, ddof=1)


def iv_slope(y, x, z):
    """Equation (7): the IV slope Cov(y, z) / Cov(x, z)."""
    return np.cov(z, y)[0, 1] / np.cov(z, x)[0, 1]


def ols_limit(beta=1.0, confound=0.5, noise=1.0, strength=0.6):
    """Where OLS ends up in a huge archipelago: equations (3) and (4).

    The numbers are those of simulate_islands.
    """
    var_R = strength**2 + confound**2 + 0.8**2  # variance of the true institutions
    return (beta * var_R + 0.5 * confound) / (var_R + noise**2)
Python note.
np.random.default_rng(seed)makes a random number generator; the sameseedalways gives the same numbers, so your results match the book’s.rng.normal(size=n)drawsnnumbers from a standard normal distribution.np.cov(x, y)returns a 2 by 2 table of covariances, and[0, 1]picks the covariance ofxwithy.
Now the checks. In an archipelago of 200,000 islands, sampling noise is tiny, so the estimates should land on the formulas.
big = simulate_islands(200_000)
pi_hat = ols_slope(big["R_obs"], big["fever"])  # first stage, equation (5)
rho_hat = ols_slope(big["ln_y"], big["fever"])  # reduced form
print(
    f"OLS slope {ols_slope(big['ln_y'], big['R_obs']):.3f}   "
    f"formula {ols_limit():.3f}   true beta {BETA}"
)
print(f"IV slope  {iv_slope(big['ln_y'], big['R_obs'], big['fever']):.3f}")
print(f"ratio rho/pi = {rho_hat:.3f} / {pi_hat:.3f} = {rho_hat / pi_hat:.3f}   (eq. 7)")

# Two-stage least squares by hand: regress ln_y on the fitted values of the first stage
R_hat = big["R_obs"].mean() + pi_hat * (big["fever"] - big["fever"].mean())
print(f"second stage slope {ols_slope(big['ln_y'], R_hat):.3f}   (the same number)")
OLS slope 0.668 formula 0.667 true beta 1.0
IV slope 1.003
ratio rho/pi = -0.605 / -0.604 = 1.003 (eq. 7)
second stage slope 1.003 (the same number)What to notice. OLS lands on about 0.67, as the formula predicts, a third below the true effect of 1: in the baseline the measurement error, which flattens the line, outweighs the omitted factor, which steepens it. The IV slope, the ratio of the two slopes and the second stage of two-stage least squares all give the same number, close to 1.
AJR have 64 countries, not 200,000. With so few, every estimate also has sampling noise: a different set of 64 countries would give a different number. A simulation shows both problems at once. We build 1,000 archipelagos of 64 islands each, run OLS and IV in each, and look at the spread of the 1,000 estimates.
Goal. See when OLS misses the true effect, and when IV finds it.
def sampling_estimates(confound=0.5, noise=1.0, strength=0.6, reps=1000, n=64):
    """OLS and IV estimates from reps archipelagos of n islands (true effect: BETA)."""
    ols_est, iv_est = [], []
    for r in range(reps):
        d = simulate_islands(n, BETA, confound, noise, strength, seed=r)
        ols_est.append(ols_slope(d["ln_y"], d["R_obs"]))
        iv_est.append(iv_slope(d["ln_y"], d["R_obs"], d["fever"]))
    return np.array(ols_est), np.array(iv_est)
simulation_figure draws the two histograms, a dashed line at the true effect, and reports in the title where each histogram is centered (its median).
def simulation_figure(confound=0.5, noise=1.0, strength=0.6):
    """Fig. 1: histograms of the OLS and IV estimates from 1,000 archipelagos."""
    ols_est, iv_est = sampling_estimates(confound, noise, strength)
    off = np.mean((iv_est < -1) | (iv_est > 3)) * 100  # IV estimates outside the chart
    bins = dict(start=-1, end=3, size=0.05)  # bars 0.05 wide
    fig = go.Figure()
    fig.add_trace(
        go.Histogram(x=ols_est, xbins=bins, name="OLS", marker_color=RUST, opacity=0.6)
    )
    fig.add_trace(
        go.Histogram(
            x=iv_est, xbins=bins, name="IV (2SLS)", marker_color=BLUE, opacity=0.6
        )
    )
    fig.add_vline(
        x=BETA,
        line=dict(color="black", dash="dash"),
        annotation_text="true effect",
        annotation_position="top right",
    )
    title = f"OLS centers on {np.median(ols_est):.2f}, IV on {np.median(iv_est):.2f}"
    if off >= 1:
        title += f" ({off:.0f}% of the IV estimates are off the chart)"
    fig.update_layout(
        title=title,
        barmode="overlay",
        legend=dict(orientation="h", y=-0.2),
        xaxis=dict(
            title="Estimated effect of institutions on log income",
            range=[-1, 3],
            tickvals=[-0.5, 0, 0.5, 1, 1.5, 2, 2.5, 3],
        ),
        yaxis=dict(title="Number of archipelagos", range=[0, 450]),
    )
    return fig


simulation_figure()
interact(
simulation_figure,
confound=FloatSlider(
min=-1, max=1, step=0.25, value=0.5, description="omitted factor", style=WIDE
),
noise=FloatSlider(
min=0,
max=1.5,
step=0.25,
value=1.0,
description="measurement error",
style=WIDE,
),
strength=FloatSlider(
min=0.1,
max=1,
step=0.05,
value=0.6,
description="instrument strength",
style=WIDE,
),
);# @title Website version: one button per scenario
SCENARIOS = {
"Omitted factor only": dict(confound=0.5, noise=0.0, strength=0.6),
"Measurement error only": dict(confound=0.0, noise=1.0, strength=0.6),
"Both (baseline)": dict(confound=0.5, noise=1.0, strength=0.6),
"Weak instrument": dict(confound=0.5, noise=1.0, strength=0.15),
}
def scenario_figure(scenario="Both (baseline)"):
"""Fig. 1 for one of the four scenarios."""
return simulation_figure(**SCENARIOS[scenario])
button_figure(scenario_figure, "scenario", list(SCENARIOS), start="Both (baseline)")Source. Simulation with simulate_islands (Section G.3.4): 1,000 archipelagos of 64 islands, true effect of institutions \(\beta = 1\).
What to notice.
strength 0.15 the IV histogram spreads out widely, some estimates fall off the chart, and its center slides toward OLS. A weak instrument gives no reliable answer in a sample of 64.Your turn. In Colab, set the omitted factor to \(-0.5\) (the factor now weakens institutions while it still raises income) and the measurement error to 0. Which way does OLS miss now? Check your answer with ols_limit.
ols_limit(confound=-0.5, noise=0) gives about 0.8: with a negative confound, \(\text{Cov}(R, u) < 0\) in equation (3), so OLS is too small even without any measurement error. The IV histogram does not move.
# Your turn: try it hereAJR built their data from many sources. The book keeps one file with the variables of their Tables 1, 2 and 4, one row per country:
| Column | What it measures | Unit |
|---|---|---|
logpgp95 |
log GDP per person in 1995, at purchasing power parity: \(\ln y\) | log of dollars |
avexpr |
average protection against expropriation risk, 1985–1995: \(\tilde{R}\) | 0 (none) to 10 (full) |
extmort4, logem4 |
settler mortality: annual deaths per 1,000 settlers, and its log: \(Z\) | deaths, log |
lat_abst |
distance from the equator (absolute latitude divided by 90) | 0 to 1 |
africa, asia, other |
continent dummies (other: Australia, Malta, New Zealand) |
0 or 1 |
base |
1 for the 64 former colonies of AJR’s base sample | 0 or 1 |
euro1900, cons00a, democ00a, cons1 |
European settlers in 1900, and early institutions | percent, scores |
The measure of institutions comes from Political Risk Services, a firm that rates for investors how likely a government is to seize private property. Settler mortality is AJR’s compilation of the death rates of soldiers, bishops and sailors stationed in the colonies, mostly in the 17th to 19th centuries.
ajr = pd.read_csv(DATA_URL + "ajr2001.csv")
ajr["region"] = ajr["continent"].replace({"Other": "Australia, Malta, NZ"})
base = ajr[ajr["base"] == 1]  # the 64 former colonies
print(len(ajr), "countries;", len(base), "former colonies in the base sample")
ajr.head()
163 countries; 64 former colonies in the base sample| code | iso3 | country | continent | base | logpgp95 | avexpr | logem4 | extmort4 | lat_abst | africa | asia | other | euro1900 | cons00a | democ00a | cons1 | loghjypl | region | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 0 | AFG | AFG | Afghanistan | Asia | 0 | NaN | NaN | 4.54010 | 93.7 | 0.366667 | 0 | 1 | 0 | 0.0 | 1.0 | 1.0 | 1.0 | NaN | Asia |
| 1 | AGO | AGO | Angola | Africa | 1 | 7.77065 | 5.36364 | 5.63479 | 280.0 | 0.136667 | 1 | 0 | 0 | 8.0 | 1.0 | 0.0 | 3.0 | -3.411250 | Africa |
| 2 | ARE | ARE | United Arab Emirates | Asia | 0 | 9.80422 | 7.18182 | NaN | NaN | 0.266667 | 0 | 1 | 0 | 0.0 | NaN | NaN | NaN | NaN | Asia |
| 3 | ARG | ARG | Argentina | Americas | 1 | 9.13346 | 6.38636 | 4.23266 | 68.9 | 0.377778 | 0 | 0 | 0 | 60.0 | 3.0 | 3.0 | 1.0 | -0.872274 | Americas |
| 4 | ARM | ARM | Armenia | Asia | 0 | 7.68248 | NaN | NaN | NaN | 0.444444 | 0 | 1 | 0 | 0.0 | NaN | NaN | NaN | NaN | Asia |
Table 1 of AJR describes the data. Here are the three main variables, for all countries and for the base sample:
VARS = ["logpgp95", "avexpr", "logem4"]
print("All countries")
print(ajr[VARS].describe().T[["count", "mean", "std", "min", "max"]].round(2))
print("\nBase sample: 64 former colonies")
print(
    base[VARS + ["extmort4"]]
    .describe()
    .T[["count", "mean", "std", "min", "max"]]
    .round(2)
)
All countries
count mean std min max
logpgp95 148.0 8.30 1.11 6.11 10.29
avexpr 121.0 7.07 1.80 1.64 10.00
logem4 87.0 4.60 1.30 0.94 7.99
Base sample: 64 former colonies
count mean std min max
logpgp95 64.0 8.06 1.04 6.11 10.22
avexpr 64.0 6.52 1.47 3.50 10.00
logem4 64.0 4.66 1.26 2.15 7.99
extmort4 64.0 245.91 472.62 8.55 2940.00What to notice.
Goal. See the correlation that starts the debate: countries with more secure property are richer.
The vertical axis shows GDP per person on a ratio scale, so equal distances are equal percentage gaps, and a straight line on the chart is a straight line in \(\ln y\), as in equation (1).
SAMPLES = ["All countries", "Base sample"]


def income_figure(sample="All countries"):
    """Fig. 2: GDP per person in 1995 against institutions, with the OLS line."""
    d = ajr.dropna(subset=["logpgp95", "avexpr"])
    if sample == "Base sample":
        d = d[d["base"] == 1]
    fit = ols_fit("logpgp95 ~ avexpr", d)
    a, b = fit.coef()["Intercept"], fit.coef()["avexpr"]
    d = d.assign(
        gdp=np.exp(d["logpgp95"]),
        group=np.where(d["base"] == 1, "Former colony (base sample)", "Other country"),
    )
    fig = px.scatter(
        d,
        x="avexpr",
        y="gdp",
        color="group",
        hover_name="country",
        log_y=True,
        color_discrete_map={"Former colony (base sample)": BLUE, "Other country": GRAY},
        range_x=[1, 10.5],
        range_y=[300, 50000],
        labels={
            "avexpr": "Protection against expropriation, 1985–1995 (0 to 10)",
            "gdp": "GDP per person, 1995 (PPP dollars)",
            "group": "",
        },
        title=f"{len(d)} countries: one more point goes with {b:.2f} more log income",
    )
    x = np.linspace(1.5, 10, 50)
    add_line(fig, x, np.exp(a + b * x))
    fig.update_yaxes(tickvals=[500, 1000, 2000, 5000, 10000, 20000, 50000])
    fig.update_layout(legend=dict(orientation="h", y=-0.2), height=520)
    return fig


income_figure()
interact(
income_figure,
sample=Dropdown(
options=SAMPLES, value="All countries", description="sample", style=WIDE
),
);# @title Website version: one button per sample
button_figure(income_figure, "sample", SAMPLES, start="All countries")Source. Data: Acemoglu, Johnson and Robinson (2001), replication files (Table 2), from the World Bank (GDP) and Political Risk Services (institutions). Prepared file: data/appG/ajr2001.csv (see the data notes). Chart: inspired by Figure 2 in Acemoglu, Johnson and Robinson (2001).
What to notice.
Your turn. AJR also use log output per worker, loghjypl, from Hall and Jones (1999), measured relative to the United States. Run the OLS regression of loghjypl on avexpr for the base sample. Is the slope similar?
ols_fit("loghjypl ~ avexpr", base).coef() gives a slope of about 0.45, a little below the 0.52 for GDP per person. Countries with good institutions are also richer per worker.
# Your turn: try it hereBefore we instrument anything, we run the regression of equation (1) by OLS, as in Table 2 of AJR. We try four versions: all countries with data, the base sample, and all countries with two sets of controls, variables added to the regression to hold other causes of income constant. The controls are distance from the equator and the continent dummies.
ols_models = [
    ols_fit("logpgp95 ~ avexpr", ajr),
    ols_fit("logpgp95 ~ avexpr", base),
    ols_fit("logpgp95 ~ avexpr + lat_abst", ajr),
    ols_fit("logpgp95 ~ avexpr + lat_abst + africa + asia + other", ajr),
]
coef_table(
    ols_models,
    ["All countries", "Base sample", "+ latitude", "+ latitude and continents"],
)| coefficient | std. error | countries | |
|---|---|---|---|
| regression | |||
| All countries | 0.532 | 0.029 | 111 |
| Base sample | 0.522 | 0.050 | 64 |
| + latitude | 0.463 | 0.052 | 111 |
| + latitude and continents | 0.390 | 0.051 | 111 |
What to notice.
AJR’s instrument is the island story of Section G.3.3 with real history. Where European settlers faced high death rates, from malaria and yellow fever, they did not settle. Instead they set up extractive states, built to move gold, rubber or slaves to Europe, with few protections for anyone else. Where settlers could survive, as in North America, Australia and New Zealand, they settled in large numbers and demanded the rights they had at home. Those early institutions persisted after independence. AJR summarize the argument as a chain:
\[\text{settler mortality} \;\Rightarrow\; \text{settlements} \;\Rightarrow\; \text{early institutions} \;\Rightarrow\; \text{current institutions} \;\Rightarrow\; \text{current income}.\]
The first stage, equation (5), tests the first links of the chain: does log settler mortality predict the expropriation risk of 1985–1995? The reduced form tests the whole chain: does it predict income in 1995? The two charts below show both, for the 64 former colonies.
Goal. Check relevance: did settler mortality move institutions?
The horizontal axis is on a ratio scale, so the slope is the change in institutions for a 1 log point (about 2.7-fold) rise in mortality. The menu drops groups of countries, to see whether the slope depends on a few of them. The neo-Europes are the four settler colonies with the lowest mortality and the best institutions: the United States, Canada, Australia and New Zealand.
NEO_EUROPES = ["USA", "CAN", "AUS", "NZL"]
SUBSAMPLES = [
    "All 64",
    "Without the neo-Europes",
    "Without Africa",
    "Without the Americas",
    "Without Asia",
]
COLORS = {"Africa": BLUE, "Americas": TEAL, "Asia": GREEN, "Australia, Malta, NZ": RUST}
MORTALITY_TICKS = [5, 10, 20, 50, 100, 200, 500, 1000, 3000]
# countries labeled on the charts (the others show their name when you hover over them)
LABELED = ["AUS", "NZL", "USA", "SGP", "HKG", "MLT", "CHL", "IND", "PAK", "ETH", "TZA",
           "GAB", "GMB", "NGA", "MLI", "SLE", "NER", "ZAR", "HTI", "BGD", "ZAF"]


def subsample(name):
    """The rows of the base sample that one menu choice keeps."""
    if name == "Without the neo-Europes":
        return base[~base["code"].isin(NEO_EUROPES)]
    if name.startswith("Without"):
        continent = name.replace("Without the ", "").replace("Without ", "")
        return base[base["continent"] != continent]
    return base


def sample_name(name, d):
    """The menu choice with its number of countries, for the chart titles."""
    return "64 former colonies" if name == "All 64" else f"{name} ({len(d)})"
add_highlight marks one country with an arrow, if it is in the data shown.
def add_highlight(fig, d, y, highlight):
    """Mark the country named highlight with an arrow (nothing if it is not in d)."""
    if highlight not in list(d["country"]):
        return
    row = d[d["country"] == highlight].iloc[0]
    fig.add_annotation(
        x=np.log10(row["extmort4"]),
        y=row[y],
        text=highlight,
        showarrow=True,
        arrowhead=2,
        ax=40,
        ay=-40,
        font=dict(color=RUST, size=13),
    )
mortality_scatter draws both charts of this section: the countries, colored by region, with the codes of some of them, and the OLS line through them. The highlight argument marks one country with an arrow.
def mortality_scatter(d, y, y_label, title, highlight):
    """A scatter of y against settler mortality (ratio scale), with the OLS line.

    Colored by region; the countries in LABELED show their codes.
    """
    fit = ols_fit(f"{y} ~ logem4", d)
    d = d.assign(label=np.where(d["code"].isin(LABELED), d["iso3"], ""))
    fig = px.scatter(
        d,
        x="extmort4",
        y=y,
        color="region",
        text="label",
        hover_name="country",
        log_x=True,
        hover_data={"label": False},
        color_discrete_map=COLORS,
        range_x=[4, 4000],
        labels={
            "extmort4": "Settler mortality (deaths per 1,000 a year, ratio scale)",
            y: y_label,
            "region": "",
        },
        title=title,
    )
    fig.update_traces(textposition="top center", textfont_size=9, marker_size=8)
    m = np.linspace(np.log(6), np.log(3500), 50)
    add_line(fig, np.exp(m), fit.coef()["Intercept"] + fit.coef()["logem4"] * m)
    add_highlight(fig, d, y, highlight)
    fig.update_xaxes(tickvals=MORTALITY_TICKS)
    fig.update_layout(legend=dict(orientation="h", y=-0.2), height=540)
    return fig
Python note. On a ratio-scale axis (
log_x=True),px.scattertakes the data andrange_xin deaths per 1,000, as they are. But an annotation added afterwards is placed in powers of ten, so a point at 200 deaths sits at \(\log_{10}(200) \approx 2.3\). That is why the annotation, and only the annotation, usesnp.log10.
def first_stage_figure(sample="All 64", highlight="(none)"):
    """Fig. 3: protection against expropriation against settler mortality."""
    d = subsample(sample)
    res = iv_fit(d)
    slope = res.first_stage.individual["avexpr"].params["logem4"]
    title = (
        f"{sample_name(sample, d)}: slope {slope:.2f}, F = {first_stage_F(res):.1f}, "
        f"IV estimate {res.params['avexpr']:.2f}"
    )
    fig = mortality_scatter(
        d, "avexpr", "Protection against expropriation, 1985–1995", title, highlight
    )
    fig.update_yaxes(range=[3, 10.5])
    return fig


first_stage_figure()
interact(
first_stage_figure,
sample=Dropdown(
options=SUBSAMPLES, value="All 64", description="countries", style=WIDE
),
highlight=Dropdown(
options=["(none)"] + sorted(base["country"]),
value="(none)",
description="highlight",
style=WIDE,
),
);# @title Website version: one button per group of countries
button_figure(first_stage_figure, "sample", SUBSAMPLES, start="All 64")Source. Data: Acemoglu, Johnson and Robinson (2001), replication files (Table 4). Prepared file: data/appG/ajr2001.csv. Chart: inspired by Figure 3 in Acemoglu, Johnson and Robinson (2001).
What to notice.
Your turn. Highlight Gambia in Colab. It had very high settler mortality but scores 8.3 on institutions. How far is it from the line? Then find the residual of the first stage for every country and list the five largest.
fit = ols_fit("avexpr ~ logem4", base) and base.assign(resid=fit.resid()).nlargest(5, "resid")[["country", "avexpr", "logem4", "resid"]]. Gambia sits about 3.4 points above the line, the largest residual of all: a reminder that the first stage is a tendency, not a law.
# Your turn: try it hereGoal. See the whole chain at once: did settler mortality long ago predict income in 1995?
def reduced_form_figure(sample="All 64", highlight="(none)"):
    """Fig. 4: log GDP per person in 1995 against settler mortality, one subsample."""
    d = subsample(sample)
    rho = ols_fit("logpgp95 ~ logem4", d).coef()["logem4"]
    pi = ols_fit("avexpr ~ logem4", d).coef()["logem4"]
    title = (
        f"{sample_name(sample, d)}: slope {rho:.2f}; "
        f"divided by the first stage {pi:.2f} gives {rho / pi:.2f}"
    )
    fig = mortality_scatter(d, "logpgp95", "Log GDP per person, 1995", title, highlight)
    fig.update_yaxes(range=[6, 10.6])
    return fig


reduced_form_figure()
interact(
reduced_form_figure,
sample=Dropdown(
options=SUBSAMPLES, value="All 64", description="countries", style=WIDE
),
highlight=Dropdown(
options=["(none)"] + sorted(base["country"]),
value="(none)",
description="highlight",
style=WIDE,
),
);# @title Website version: one button per group of countries
button_figure(reduced_form_figure, "sample", SUBSAMPLES, start="All 64")Source. Data: Acemoglu, Johnson and Robinson (2001), replication files (Table 4). Prepared file: data/appG/ajr2001.csv. Chart: inspired by Figure 1 in Acemoglu, Johnson and Robinson (2001).
What to notice.
Your turn. Check equation (7) with the regressions themselves: run the reduced form and the first stage for the base sample with ols_fit, and divide the two slopes. Then compare the result with iv_fit(base).params["avexpr"].
rho = ols_fit("logpgp95 ~ logem4", base).coef()["logem4"] gives \(-0.573\) and pi = ols_fit("avexpr ~ logem4", base).coef()["logem4"] gives \(-0.607\). Their ratio, 0.944, is exactly the 2SLS estimate: with one instrument and one endogenous variable, 2SLS is this division.
# Your turn: try it hereNow the headline result of AJR, column 1 of their Table 4. We compute it three ways: by hand in two stages, with pyfixest and with linearmodels. Then we test the instrument and the need for it.
The first stage regresses institutions on the instrument and keeps the fitted values. The second regresses income on the fitted values.
stage1 = ols_fit("avexpr ~ logem4", base)
by_hand = base.assign(
    avexpr_hat=stage1.predict()
)  # the part of institutions the instrument predicts
stage2 = ols_fit("logpgp95 ~ avexpr_hat", by_hand)
print(
    f"first stage:  avexpr = {stage1.coef()['Intercept']:.3f} "
    f"+ ({stage1.coef()['logem4']:.3f}) x logem4"
)
print(
    f"second stage: logpgp95 = {stage2.coef()['Intercept']:.3f} "
    f"+ {stage2.coef()['avexpr_hat']:.3f} x avexpr_hat"
    f"   (standard error {stage2.se()['avexpr_hat']:.3f})"
)
first stage: avexpr = 9.341 + (-0.607) x logem4
second stage: logpgp95 = 1.910 + 0.944 x avexpr_hat (standard error 0.120)The coefficient, 0.944, is the right one. Its standard error is not: the second stage treats the fitted values as if they were data, and forgets that they were estimated in the first stage. The IV commands below compute the standard error correctly.
pyfixest writes an IV regression as a formula in three parts: the outcome, the exogenous variables (1, just a constant here), and after a second | the endogenous variable with its instrument, avexpr ~ logem4.
iv_pf = pf.feols("logpgp95 ~ 1 | avexpr ~ logem4", data=base, vcov="HC1")
iv_pf.tidy().round(3)| Estimate | Std. Error | t value | Pr(>|t|) | 2.5% | 97.5% | |
|---|---|---|---|---|---|---|
| Coefficient | ||||||
| Intercept | 1.910 | 1.193 | 1.601 | 0.114 | -0.475 | 4.294 |
| avexpr | 0.944 | 0.179 | 5.278 | 0.000 | 0.587 | 1.302 |
iv_lm = iv_fit(base)
ci = iv_lm.conf_int().loc["avexpr"]
print(
    f"pyfixest:     beta = {iv_pf.coef()['avexpr']:.4f}   "
    f"(standard error {iv_pf.se()['avexpr']:.4f})"
)
print(
    f"linearmodels: beta = {iv_lm.params['avexpr']:.4f}   "
    f"(standard error {iv_lm.std_errors['avexpr']:.4f})"
)
print(f"95% confidence interval (linearmodels): {ci['lower']:.2f} to {ci['upper']:.2f}")
print(f"OLS on the same 64 countries: {ols_models[1].coef()['avexpr']:.3f}")
pyfixest: beta = 0.9443 (standard error 0.1789)
linearmodels: beta = 0.9443 (standard error 0.1761)
95% confidence interval (linearmodels): 0.60 to 1.29
OLS on the same 64 countries: 0.522What to notice.
Equation (8) showed that a weak instrument turns small problems into large errors. The standard check is the first-stage F statistic: the test that the instrument’s coefficient in the first stage is zero. A common rule of thumb (Staiger and Stock 1997) asks for an F above 10. Stock and Yogo (2005) give a stricter threshold, 16.38, for an instrument whose IV tests are at most a little distorted.
print(f"first-stage F (robust, linearmodels):          {first_stage_F(iv_lm):.2f}")
r2 = iv_lm.first_stage.diagnostics.loc["avexpr", "rsquared"]
print(f"first-stage R-squared:                          {r2:.2f}")
iv_pf.IV_Diag()  # pyfixest computes its IV tests and stores them in the model
print(f"effective F (Olea and Pflueger 2013, pyfixest): {iv_pf._eff_F:.2f}")
first-stage F (robust, linearmodels): 16.85
first-stage R-squared: 0.27
effective F (Olea and Pflueger 2013, pyfixest): 16.32The F statistic is about 16 to 17, depending on the small-sample correction: above the rule of thumb of 10, and right at the Stock–Yogo threshold. The instrument is strong enough, but not by a wide margin. With controls that are themselves related to mortality, the F statistic falls, as Fig. 5 shows.
If institutions were not endogenous, OLS and IV would estimate the same thing, and OLS, being more precise, would be better. The Wu–Hausman test asks whether the gap between them is too large to be chance.
wh = iv_lm.wu_hausman()
print(f"Wu-Hausman test: statistic {wh.stat:.2f}, p-value {wh.pval:.6f}")
Wu-Hausman test: statistic 24.22, p-value 0.000007The p-value is far below 0.01: the gap between OLS and IV is not chance. The data reject that OLS and IV estimate the same thing, so institutions are endogenous, as Section G.3 warned, and IV is needed. (The test assumes that the instrument itself is valid: it compares OLS with IV, not IV with the truth.)
Your turn. pyfixest and linearmodels gave standard errors of 0.179 and 0.176. Refit the linearmodels regression with cov_type="unadjusted", the textbook standard errors that assume the same spread of errors in every country. Is the standard error larger or smaller?
Use IV2SLS(base["logpgp95"], base[[]].assign(const=1.0), base[["avexpr"]], base[["logem4"]]).fit(cov_type="unadjusted") and read .std_errors["avexpr"]. It is smaller, about 0.154: in these data the spread of the errors differs across countries, and the robust standard error allows for it. The point estimate is the same 0.944. Libraries agree on estimates and differ on corrections, so always say which standard errors you report.
# Your turn: try it hereIs the IV estimate fragile? AJR add controls that might explain both mortality and income: distance from the equator and the continent dummies. Fig. 5 puts OLS and IV side by side for each set of controls, the main columns of their Table 4.
Goal. See whether the IV estimate survives controls, and how its precision changes.
CONTROLS = {
    "None": [],
    "Latitude": ["lat_abst"],
    "Continents": ["africa", "asia", "other"],
    "Latitude and continents": ["lat_abst", "africa", "asia", "other"],
}


def estimates_table():
    """OLS and IV estimates with 95% intervals, for each set of controls."""
    rows = []
    for name, controls in CONTROLS.items():
        ols_m = ols_fit(" + ".join(["logpgp95 ~ avexpr"] + controls), base)
        iv_m = iv_fit(base, controls)
        rows.append(
            {
                "controls": name,
                "OLS": ols_m.coef()["avexpr"],
                "OLS low": ols_m.confint().loc["avexpr", "2.5%"],
                "OLS high": ols_m.confint().loc["avexpr", "97.5%"],
                "IV": iv_m.params["avexpr"],
                "IV low": iv_m.conf_int().loc["avexpr", "lower"],
                "IV high": iv_m.conf_int().loc["avexpr", "upper"],
                "first-stage F": first_stage_F(iv_m),
            }
        )
    return pd.DataFrame(rows).set_index("controls")


estimates = estimates_table()
estimates.round(2)| OLS | OLS low | OLS high | IV | IV low | IV high | first-stage F | |
|---|---|---|---|---|---|---|---|
| controls | |||||||
| None | 0.52 | 0.42 | 0.62 | 0.94 | 0.60 | 1.29 | 16.85 |
| Latitude | 0.47 | 0.34 | 0.59 | 1.00 | 0.52 | 1.47 | 9.99 |
| Continents | 0.42 | 0.31 | 0.53 | 0.98 | 0.33 | 1.63 | 5.52 |
| Latitude and continents | 0.40 | 0.27 | 0.53 | 1.11 | 0.12 | 2.09 | 3.28 |
def estimates_trace(e, method, color, controls):
    """The estimates of one method (OLS or IV) with their 95% intervals."""
    opacity = []  # the chosen row in full color, the others faded
    for c in e["controls"]:
        opacity.append(1.0 if c == controls else 0.25)
    return go.Scatter(
        x=e[method],
        y=e["controls"],
        mode="markers",
        name=method,
        marker=dict(color=color, size=12, opacity=opacity),
        error_x=dict(
            type="data",
            symmetric=False,
            color=color,
            array=e[method + " high"] - e[method],
            arrayminus=e[method] - e[method + " low"],
        ),
    )
estimates_figure draws the two sets of estimates and writes the chosen row’s numbers in the title.
def estimates_figure(controls="None"):
    """Fig. 5: OLS and IV estimates with 95% intervals; the chosen row highlighted."""
    e = estimates.reset_index()
    fig = go.Figure()
    for method, color in [("OLS", RUST), ("IV", BLUE)]:
        fig.add_trace(estimates_trace(e, method, color, controls))
    row = estimates.loc[controls]
    fig.update_layout(
        title=f"Controls: {controls.lower()}. OLS {row['OLS']:.2f}, IV {row['IV']:.2f} "
        f"(first-stage F = {row['first-stage F']:.1f})",
        xaxis=dict(
            title="Effect of one more point of institutions on log income (95% CI)",
            range=[-0.2, 2.6],
            zeroline=True,
        ),
        yaxis=dict(title="", autorange="reversed"),
        legend=dict(orientation="h", y=-0.2),
    )
    return fig


estimates_figure()
interact(
estimates_figure,
controls=ToggleButtons(
options=list(CONTROLS), value="None", description="controls", style=WIDE
),
);# @title Website version: one button per set of controls
button_figure(estimates_figure, "controls", list(CONTROLS), start="None")Source. Data: Acemoglu, Johnson and Robinson (2001), replication files (Table 4). Prepared file: data/appG/ajr2001.csv. Chart: inspired by Table 4 in Acemoglu, Johnson and Robinson (2001) and Figure 3 of the tutorial Do Institutions Cause Prosperity?.
What to notice.
Your turn. Add a fifth set of controls: the share of Europeans in the population in 1900, euro1900. Does the IV estimate change? What happens to the first-stage F, and why might it?
r = iv_fit(base, ["euro1900"]), then r.params["avexpr"] and first_stage_F(r). The estimate barely moves (0.99), but the F statistic drops to about 5, because the share of Europeans in 1900 is one of the links of AJR’s chain: settlers settled where mortality was low. Controlling for a link of the chain takes away the variation the instrument works with.
# Your turn: try it hereAn estimate of 0.94 means that one more point of protection against expropriation raises log income by 0.94, so income by \(e^{0.94} - 1 \approx 156\) percent. AJR’s own example compares Nigeria and Chile:
nga = base.loc[base["code"] == "NGA", "avexpr"].iloc[0]
chl = base.loc[base["code"] == "CHL", "avexpr"].iloc[0]
beta_iv = iv_lm.params["avexpr"]
gap = beta_iv * (chl - nga)
print(
    f"institutions: Nigeria {nga:.2f}, Chile {chl:.2f}, a gap of {chl - nga:.2f} points"
)
print(f"IV:  log income gap {gap:.2f}, a factor of {np.exp(gap):.1f}")
ols_gap = ols_models[1].coef()["avexpr"] * (chl - nga)
print(f"OLS: log income gap {ols_gap:.2f}, a factor of {np.exp(ols_gap):.1f}")
institutions: Nigeria 5.55, Chile 7.82, a gap of 2.27 points
IV: log income gap 2.15, a factor of 8.6
OLS: log income gap 1.19, a factor of 3.3If Nigeria had Chile’s institutions, the IV estimate predicts that it would be about 8 to 9 times as rich, close to the actual gap between the two countries. OLS would predict a factor of about 3.
Why is IV larger than OLS? Section G.3 gave two biases that push OLS up (omitted variables and reverse causality) and one that pulls it down (measurement error). IV is larger, so the downward pull must be the stronger. AJR argue that the index of expropriation risk is a noisy measure of the institutions that matter, which are broader and older than an investor rating of 1985–1995. The simulation of Fig. 1 showed exactly this pattern in the scenario “Measurement error only”.
A second reason is the local nature of the IV estimate (Section G.3.3): it is the effect for the former colonies whose institutions were shaped by settler mortality. If institutions matter more for them than for the average country, IV is larger than an OLS slope that averages over all.
AJR’s paper changed how economists think about growth. It also started a long debate. Four questions are at its center.
Is exclusion credible? The key assumption is that settler mortality affects income today only through institutions. The most serious doubt is disease: the malaria that killed settlers still makes workers sick today, and it might lower income directly. AJR control for malaria and life expectancy today and find a smaller, but still large, effect of institutions (about 0.6 to 0.7, in their Table 7). But today’s health is also partly an outcome of institutions, so controlling for it may hide part of their effect. Others argue that settlers brought human capital, their skills and schooling, not only institutions (Glaeser and coauthors 2004). Then mortality would affect income through schooling too, and the IV estimate would mix the two effects.
Are the mortality data reliable? Albouy (2012) went back to AJR’s sources. He found that 36 of the 64 countries in the base sample are assigned mortality rates from other countries, often neighbors, and that rates from very different groups, soldiers in barracks, soldiers on campaign, laborers and bishops, are combined. When he corrects for these problems, the first stage weakens, and the IV estimates become fragile. AJR (2012) reply that limiting the influence of the outliers, such as capping mortality at 250, leaves their results intact. The debate is a lesson for every data project: an instrument is only as good as the data it is built from.
What does the coefficient mean for policy? The IV estimate is a local effect of institutions that were set long ago by history. It does not tell a government how to raise its expropriation score, or how fast income would respond. Reforms change institutions in ways that history did not, and they can fail.
What does it mean for the growth models? In the model of Section G.3, institutions work through productivity and investment. AJR’s estimate is large enough to account for a big share of the income differences across former colonies, and so for much of the TFP gap that Chapter 4 and Appendix D measure. Institutions are a candidate answer to the question the production model leaves open: why some countries use their capital and workers so much better than others. Hall and Jones (1999), with the author of our textbook, reached a similar conclusion with a different instrument: what they called social infrastructure explains much of the differences in output per worker.
The tutorial behind this appendix, Do Institutions Cause Prosperity? An IV Tutorial in Python, reproduces the rest of AJR’s paper with the same tools. It comes with slides, a web app and a Stata version. There you can:
iv_fit as a control, and ask whether it is a cause of mortality (a real threat) or a result of institutions (a “bad control”).IV2SLS does, and reports the Hansen J test (.sargan). Why can the test be computed here, but not with one instrument?The original data and programs are in Daron Acemoglu’s data archive. The documentation of pyfixest and linearmodels has many more IV examples.
| Error or symptom | What it usually means | What to do |
|---|---|---|
ModuleNotFoundError: No module named 'pyfixest' |
the install cell was not run in this session | run the first cell of Section G.2 again, then the imports |
KeyError: 'avexpr' after .coef() |
the formula names another variable, or misspells one | print model.coef() to see the names |
| a regression has fewer countries than expected | rows with a missing value in any variable are dropped | count them with base[["logpgp95", "lat_abst"]].isna().sum() |
| the second stage by hand gives a different standard error | it ignores that the fitted values are estimated | use pf.feols(... \| avexpr ~ logem4 ...) or IV2SLS for the standard error |
ValueError from IV2SLS about the constant |
the exogenous table has no constant, or two | build it with d[controls].assign(const=1.0), as iv_fit does |
| a huge or negative IV estimate | the first stage is weak in that sample | look at first_stage_F before the estimate |