# Libraries used in this appendix
import math                                     # math on single numbers
import numpy as np                              # numbers and arrays
import pandas as pd                             # data tables
import plotly.express as px                     # quick charts from data tables
import plotly.graph_objects as go               # charts built piece by piece
import plotly.io as pio
from plotly.subplots import make_subplots       # several panels in one chart
import statsmodels.api as sm                    # regressions with standard errors
from scipy import optimize, stats               # nonlinear least squares; t and chi-squared distributions
from ipywidgets import interact, FloatSlider, IntSlider, ToggleButtons, Dropdown

# One light blue/green look for every chart
BLUE, TEAL, GREEN, GRAY, ORANGE = "#16528c", "#008070", "#7fb23a", "#8a96a3", "#c4651a"
pio.templates.default = "plotly_white"
pio.templates["plotly_white"].layout.update(width=860, height=480)   # same size in Colab and on the website
px.defaults.color_discrete_sequence = [BLUE, TEAL, GREEN, ORANGE, "#8e5ea2", "#5aa0d8", "#0b4f47"]
WIDE = {"description_width": "initial"}         # show the full widget labels

# Colab only: let Plotly charts appear inside the interactive widgets
try:
    import google.colab
    google.colab.output.enable_custom_widget_manager()
except ImportError:
    pass                                        # not running in Colab: nothing to do

# The data file of this appendix lives in the book's GitHub repository
DATA_URL = "https://raw.githubusercontent.com/quarcs-lab/macro102-site/main/data/appE/"E. Growth and Convergence Across Countries
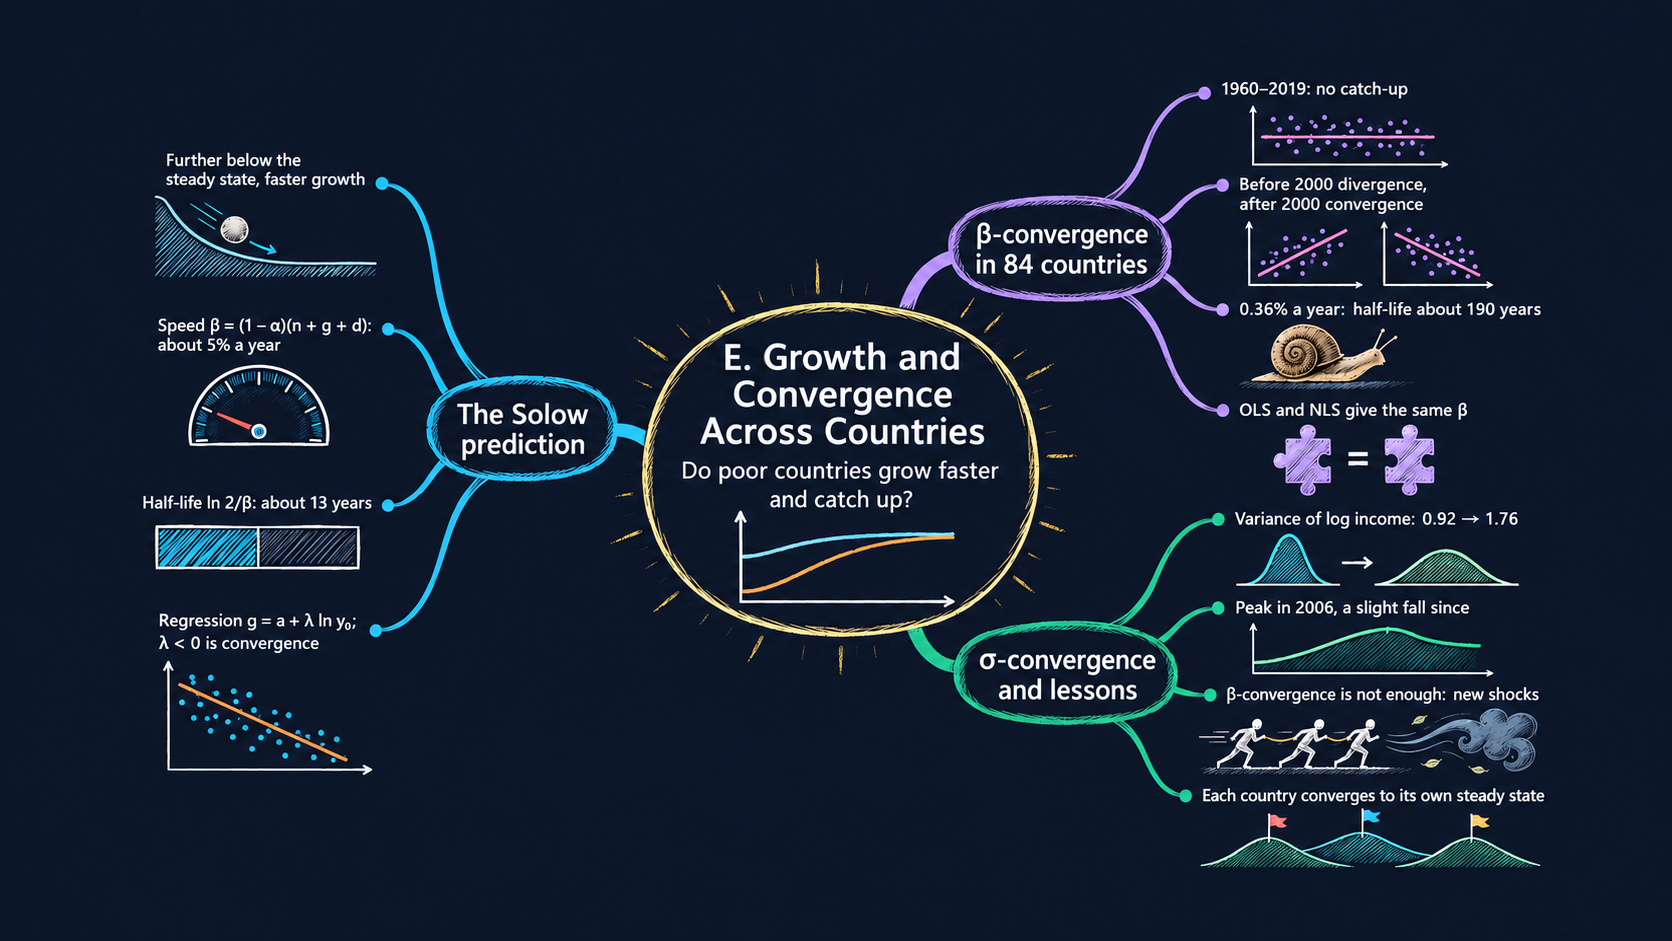


Learning goals
Do poor countries grow faster than rich ones and catch up? The Solow model says they should, at least when they share the same steady state. This appendix tests that prediction on 84 countries from 1960 to 2019. By the end of it you will be able to:
- derive the speed of convergence \(\beta=(1-\alpha)(\bar{n}+\bar{g}+\bar{d})\) and the half-life \(\ln 2/\beta\) from the Solow model, and turn the model into a regression of growth on initial income;
- tell β-convergence (poor countries grow faster) from σ-convergence (incomes become more equal), and explain why the first does not guarantee the second;
- estimate β-convergence by OLS with robust standard errors, convert the slope into a speed and a half-life, and estimate the speed directly by nonlinear least squares (NLS);
- check whether the answer depends on the period, with a structural break, rolling windows and a heatmap of every start and end year;
- measure σ-convergence with the variance of log income and its confidence interval;
- do all of this in Python with pandas, statsmodels, SciPy and interactive Plotly charts.
Setup
The setup cell loads the libraries and sets the look of the charts. Two libraries are new compared with the chapters. statsmodels runs regressions and reports standard errors, p-values and confidence intervals, as a statistics package does. SciPy holds numerical tools: here, a solver for nonlinear least squares and the \(t\) and \(\chi^2\) distributions. Both come with Colab, so there is nothing to install.
Show the helper code
# @title Helpers for the website versions (run this cell; you do not need to read it)
def slider_figure(make_figure, name, values, start, label=None):
    """Precompute make_figure(name=value) for every value and join the results with one slider.

    The website cannot run Python, so each interactive figure also gets this precomputed version.
    """
    figures = [make_figure(**{name: v}) for v in values]
    first = values.index(start)
    fig = go.Figure(layout=figures[first].layout)
    owner = []                                  # which precomputed figure each trace comes from
    for i, f in enumerate(figures):
        for trace in f.data:
            trace.visible = (i == first)
            fig.add_trace(trace)
            owner.append(i)
    steps = []
    for i, f in enumerate(figures):
        layout = {"title": f.layout.title.to_plotly_json(),
                  "annotations": [a.to_plotly_json() for a in f.layout.annotations],
                  "shapes": [s.to_plotly_json() for s in f.layout.shapes]}
        visible = [o == i for o in owner]
        steps.append(dict(method="update", label=str(values[i]), args=[{"visible": visible}, layout]))
    fig.update_layout(sliders=[dict(active=first, steps=steps, pad=dict(t=60),
                                    currentvalue=dict(prefix=(label or name) + " = "))])
    return fig
Show the helper code
# @title Helper for the website versions with buttons (run this cell; you do not need to read it)
def button_figure(make_figure, name, values, start):
    """Like slider_figure, but with one button per value; each button also sets the y-axis."""
    figures = [make_figure(**{name: v}) for v in values]
    first = values.index(start)
    fig = go.Figure(layout=figures[first].layout)
    owner = []
    for i, f in enumerate(figures):
        for trace in f.data:
            trace.visible = (i == first)
            fig.add_trace(trace)
            owner.append(i)
    buttons = []
    for i, f in enumerate(figures):
        layout = {"title": f.layout.title.to_plotly_json(), "yaxis": f.layout.yaxis.to_plotly_json(),
                  "annotations": [a.to_plotly_json() for a in f.layout.annotations],
                  "shapes": [s.to_plotly_json() for s in f.layout.shapes]}
        visible = [o == i for o in owner]
        buttons.append(dict(label=str(values[i]), method="update", args=[{"visible": visible}, layout]))
    fig.update_layout(updatemenus=[dict(type="buttons", direction="right", buttons=buttons, active=first,
                                        x=0, y=1.02, xanchor="left", yanchor="bottom")],
                      margin=dict(t=130))
    return fig
E.1 Why convergence?
In the Solow model of Chapter 5, an economy that starts below its steady state grows fast, and its growth slows down as it gets closer. This is the principle of transition dynamics: the further below its steady state an economy is, the faster it grows. Two economies with the same saving rate, population growth, depreciation and technology have the same steady state, so the poorer one should grow faster and catch up. Chapter 5 found this pattern among OECD countries, but not in a large sample of countries around the world.
This appendix turns that picture into numbers. It asks four questions:
- Do poor countries grow faster? Regress growth on initial income: a negative slope is β-convergence.
- How fast do they catch up? Convert the slope into a speed of convergence β, the share of the gap to the steady state that closes each year, and into a half-life, the number of years it takes to close half of the gap.
- Does the answer depend on the period? Split the sample in 2000, roll the start year forward, and look at every pair of start and end years.
- Are incomes becoming more equal? Track the cross-country variance of log income: a falling variance is σ-convergence.
| Concept | Meaning | Section |
|---|---|---|
| β-convergence | Poorer countries grow faster: negative slope of growth on log initial income | E.4, E.5 |
| Speed of convergence β | Share of the remaining log gap closed each year | E.2, E.6, E.7 |
| Half-life | Years needed to close half of the gap, \(\ln 2/\beta\) | E.2, E.6 |
| NLS | Estimating β directly from the nonlinear equation | E.7 |
| Rolling window | Re-estimating with a start year that moves forward | E.8 |
| σ-convergence | The cross-country variance of log income falls over time | E.9, E.11 |
E.2 From the Solow model to a convergence regression
This section derives, step by step, the equation that the rest of the appendix estimates. We use the Solow model with population growth and technological progress, in continuous time. Bars mark parameters, as in the chapters.
Assumptions
- Production is Cobb–Douglas with labor-augmenting technology: \(Y=K^{\alpha}(AL)^{1-\alpha}\), with capital share \(0<\alpha<1\). Chapters 4 and 5 use \(\alpha=1/3\).
- Workers grow at rate \(\bar{n}\) and technology at rate \(\bar{g}\): \(\dot{L}/L=\bar{n}\) and \(\dot{A}/A=\bar{g}\). A dot over a variable is its change per unit of time (Appendix C.11).
- A constant share \(\bar{s}\) of output is invested and capital depreciates at rate \(\bar{d}\): \(\dot{K}=\bar{s}Y-\bar{d}K\).
Because output per worker grows forever when technology grows, we measure everything per effective worker, \(AL\): \(\hat{k}\equiv K/(AL)\) and \(\hat{y}\equiv Y/(AL)\). Dividing the production function by \(AL\) gives \(\hat{y}=\hat{k}^{\alpha}\).
Solving the model
Step 1: the law of motion. The growth rate of a ratio is the growth rate of the numerator minus that of the denominator (Appendix C.5):
\[\frac{\dot{\hat{k}}}{\hat{k}}=\frac{\dot{K}}{K}-\bar{n}-\bar{g}.\]
The growth rate of capital is \(\dot{K}/K=\bar{s}Y/K-\bar{d}\), and \(Y/K=\hat{y}/\hat{k}=\hat{k}^{\alpha-1}\). So
\[\frac{\dot{\hat{k}}}{\hat{k}}=\bar{s}\,\hat{k}^{\alpha-1}-(\bar{n}+\bar{g}+\bar{d}). \tag{1}\]
Investment per effective worker pushes \(\hat{k}\) up. Depreciation, new workers and better technology all spread the capital stock more thinly and push it down. When the two forces are equal, \(\hat{k}\) stops changing. That is the steady state:
\[\hat{k}^*=\left(\frac{\bar{s}}{\bar{n}+\bar{g}+\bar{d}}\right)^{1/(1-\alpha)},\qquad \hat{y}^*=(\hat{k}^*)^{\alpha}.\]
Step 2: logs. Write \(x\equiv\ln\hat{k}\). The growth rate of \(\hat{k}\) is the time derivative of its log, \(\dot{x}=\dot{\hat{k}}/\hat{k}\), and \(\hat{k}^{\alpha-1}=e^{-(1-\alpha)x}\). Equation (1) becomes
\[\dot{x}=f(x)\equiv\bar{s}\,e^{-(1-\alpha)x}-(\bar{n}+\bar{g}+\bar{d}).\]
Step 3: a straight-line approximation near the steady state. Close to \(x^*=\ln\hat{k}^*\), replace \(f\) by its tangent: \(f(x)\approx f(x^*)+f'(x^*)(x-x^*)\). At the steady state \(f(x^*)=0\), which also tells us that \(\bar{s}\,e^{-(1-\alpha)x^*}=\bar{n}+\bar{g}+\bar{d}\). The derivative is
\[f'(x^*)=-(1-\alpha)\,\bar{s}\,e^{-(1-\alpha)x^*}=-(1-\alpha)(\bar{n}+\bar{g}+\bar{d}).\]
So \(\dot{x}\approx-\beta\,(x-x^*)\), with the speed of convergence
\[\beta\equiv(1-\alpha)(\bar{n}+\bar{g}+\bar{d}). \tag{2}\]
A note on notation. We follow Barro and Sala-i-Martin: β is the speed and, below, λ is the regression slope. Appendix F, which follows Mankiw, Romer and Weil (1992), writes the speed as λ, because there β is the share of human capital.
Step 4: from capital to output. Since \(\ln\hat{y}=\alpha x\), the log gap of output is \(\alpha\) times the log gap of capital, and it shrinks at the same speed: \(\frac{d}{dt}\left(\ln\hat{y}-\ln\hat{y}^*\right)=-\beta\left(\ln\hat{y}-\ln\hat{y}^*\right)\).
Step 5: solve the differential equation. A variable whose change is \(-\beta\) times its level decays exponentially (Appendix C.11):
\[\ln\hat{y}(t)-\ln\hat{y}^*=e^{-\beta t}\left[\ln\hat{y}(0)-\ln\hat{y}^*\right]. \tag{3}\]
Each year, a share β of the remaining log gap closes. Half of the gap is gone when \(e^{-\beta t}=1/2\), so the half-life is
\[t_{1/2}=\frac{\ln 2}{\beta}. \tag{4}\]
This is the continuous-time cousin of the half-life of a difference equation in Appendix C.10.
Step 6: back to output per worker. The data measure output per person, \(y=Y/L=A\hat{y}\), so \(\ln y(t)=\ln A(0)+\bar{g}t+\ln\hat{y}(t)\). Growth over \(T\) years is
\[\ln y(T)-\ln y(0)=\bar{g}T+\ln\hat{y}(T)-\ln\hat{y}(0)=\bar{g}T+\left(1-e^{-\beta T}\right)\left[\ln\hat{y}^*-\ln\hat{y}(0)\right],\]
where the second step uses equation (3) at \(t=T\). Now replace \(\ln\hat{y}(0)\) by \(\ln y(0)-\ln A(0)\) and divide by \(T\):
\[\frac{1}{T}\ln\frac{y(T)}{y(0)}=a-\frac{1-e^{-\beta T}}{T}\,\ln y(0),\qquad a\equiv\bar{g}+\frac{1-e^{-\beta T}}{T}\left[\ln\hat{y}^*+\ln A(0)\right]. \tag{5}\]
This is the Barro–Sala-i-Martin equation. Average annual growth falls with log initial income, and the slope depends only on the speed β and the length of the period \(T\).
What the model predicts
A regression. For a cross-section of countries \(i\), equation (5) becomes a linear regression of growth on log initial income,
\[g_i\equiv\frac{1}{T}\ln\frac{y_{i,T}}{y_{i,0}}=a+\lambda\,\ln y_{i,0}+\varepsilon_i,\qquad \lambda=-\frac{1-e^{-\beta T}}{T}. \tag{6}\]
A positive speed β gives a negative slope λ. Solving the second equation for β turns an estimated slope into a speed:
\[\beta=-\frac{\ln(1+\lambda T)}{T},\qquad\text{which needs } 1+\lambda T>0. \tag{7}\]
For short periods, \(\lambda\approx-\beta\). Over long periods λ is smaller in absolute value than β, because most of the gap has already closed. With β = 0.02 and \(T=59\), λ = −0.0117.
Absolute or conditional? The intercept \(a\) holds the steady state \(\hat{y}^*\), the technology level \(A(0)\) and its growth rate \(\bar{g}\). A single regression line fits all countries only if these are the same everywhere. Then the model predicts absolute (unconditional) convergence, and this is what we test. If countries have different steady states, each converges to its own. That is conditional convergence, which needs controls for the steady state in the regression.
How fast? With \(\alpha=1/3\), \(\bar{n}=0.01\), \(\bar{g}=0.02\) and \(\bar{d}=0.05\), equation (2) gives β = (2/3)(0.08) ≈ 0.053: the gap closes by about 5.3 percent a year, with a half-life of about 13 years. Studies of conditional convergence usually find a speed near 2 percent a year, a half-life of about 35 years. The model matches this only with a much larger capital share, near \(\alpha=0.75\). One reading is that “capital” should include human capital, which raises the share of output paid to accumulated factors.
The model in code
speed_of_convergence computes equation (2). solow_gap_path simulates the exact, nonlinear law of motion, equation (1), with small time steps, so we can see how good the straight-line approximation is.
Python note. A
forloop with a small stepdtapproximates a differential equation: each step adds the change per unit of time timesdt. This is Euler’s method.np.zeros(n)makes an array ofnzeros that the loop fills in.
def speed_of_convergence(alpha, n, g, d):
    """Equation (2): beta = (1 - alpha)(n + g + d)."""
    return (1 - alpha) * (n + g + d)


def solow_gap_path(alpha=1/3, n=0.01, g=0.02, d=0.05, s=0.2, start=0.75, years=150, dt=0.05):
    """Simulate equation (1) from y-hat = start * y-hat*; return the years and the log gap ln(y-hat*/y-hat)."""
    k_star = (s / (n + g + d)) ** (1 / (1 - alpha))
    k = k_star * start ** (1 / alpha)            # so that y-hat(0) = start * y-hat*
    steps = int(years / dt)
    t = np.zeros(steps + 1)
    gap = np.zeros(steps + 1)
    for i in range(steps + 1):
        t[i] = i * dt
        gap[i] = alpha * (math.log(k_star) - math.log(k))
        k = k + dt * (s * k ** alpha - (n + g + d) * k)
    return t, gap
Check the algebra with numbers. Start an economy at three-quarters of its steady-state output per effective worker. The approximation predicts a half-life of \(\ln 2/\beta\). The simulation tells us when the gap really halves.
beta = speed_of_convergence(1/3, 0.01, 0.02, 0.05)
t, gap = solow_gap_path()
simulated = t[np.argmax(gap <= gap[0] / 2)]     # first year in which the gap has halved
print(f"speed of convergence beta = {beta:.4f} ({100 * beta:.1f} percent a year)")
print(f"half-life from equation (4): {math.log(2) / beta:.1f} years")
print(f"half-life in the simulation: {simulated:.1f} years")
speed of convergence beta = 0.0533 (5.3 percent a year)
half-life from equation (4): 13.0 years
half-life in the simulation: 10.5 yearsThe two half-lives are close but not equal: the simulated economy closes half of its gap in about 10.5 years, not 13. The straight line is exact only near the steady state. Further below it, capital is scarce and very productive, so the exact economy grows faster than the approximation says. Try solow_gap_path(start=0.25): an economy at a quarter of its steady state halves its gap in about 4 years. The saving rate \(\bar{s}\) moves the steady state but not the speed, which is why speed_of_convergence has no s.
Seeing the speed of convergence
Goal. See how the capital share and the three “dilution” rates set the speed at which the gap closes.
def convergence_figure(alpha=0.33, n=0.01, g=0.02, d=0.05):
    """The log gap to the steady state: exact simulation of equation (1) and the approximation, equation (3)."""
    beta = speed_of_convergence(alpha, n, g, d)
    t, gap = solow_gap_path(alpha, n, g, d)
    t, gap = t[::20], gap[::20]                  # plot one point a year (the simulation step is 0.05)
    fig = go.Figure()
    fig.add_trace(go.Scatter(x=t, y=gap, mode="lines", name="Exact (simulation)",
                             line=dict(color=BLUE, width=3)))
    fig.add_trace(go.Scatter(x=t, y=gap[0] * np.exp(-beta * t), mode="lines", name="Approximation",
                             line=dict(color=TEAL, width=2, dash="dash")))
    half = math.log(2) / beta
    if half < 150:
        fig.add_vline(x=half, line=dict(color=GRAY, dash="dot"))
        fig.add_annotation(x=half, y=0.27, text=f"half-life {half:.0f} years", xanchor="left",
                           xshift=4, showarrow=False)
    fig.update_layout(title=f"β = (1 − α)(n + g + d) = {100 * beta:.1f}% a year, half-life {half:.0f} years",
                      xaxis=dict(title="Years", range=[0, 150]),
                      yaxis=dict(title="Log gap to the steady state", range=[0, 0.31]),
                      legend=dict(x=0.99, xanchor="right", y=0.98))
    return fig
interact(convergence_figure,
alpha=FloatSlider(value=0.33, min=0.1, max=0.9, step=0.01, description="capital share α", style=WIDE),
n=FloatSlider(value=0.01, min=0.0, max=0.04, step=0.005, description="population growth n",
style=WIDE, readout_format=".3f"),
g=FloatSlider(value=0.02, min=0.0, max=0.04, step=0.005, description="technology growth g",
style=WIDE, readout_format=".3f"),
d=FloatSlider(value=0.05, min=0.01, max=0.1, step=0.01, description="depreciation d", style=WIDE));Show the code of the website version
# @title Website version: move the capital share α
slider_figure(convergence_figure, "alpha", [0.2, 0.33, 0.4, 0.5, 0.6, 0.75, 0.9], start=0.33,
              label="capital share α")
Source. Model: the Solow model with population growth and technology, equations (1) to (4) of this appendix; the economy starts at three-quarters of its steady-state output per effective worker (log gap 0.29).
What to notice.
- With the textbook capital share of about 1/3, the approximation says half of the gap closes in about 13 years, and the exact economy is even faster. Convergence in the Solow model is fast. (The slider starts at α = 0.33, so the title shows 5.4% a year rather than the 5.3% of α = 1/3.)
- A larger capital share slows convergence: diminishing returns set in more slowly, so the pull back to the steady state is weaker. At α = 0.9 the half-life is over 80 years.
- The exact path lies below the dashed approximation: away from the steady state, convergence is faster than the linear formula says. The gap between the two shrinks as α rises, because the law of motion becomes closer to a straight line.
Your turn. Keep \(\bar{n}=0.01\), \(\bar{g}=0.02\) and \(\bar{d}=0.05\). Which capital share gives a speed of 2 percent a year, the speed found in many studies? What is the half-life then?
Hint
Solve \((1-\alpha)(0.08)=0.02\) for α, or move the α slider until the title shows 2.0%. Check with speed_of_convergence(0.75, 0.01, 0.02, 0.05) and math.log(2) / 0.02.
# Your turn: try it hereE.3 The data: 84 countries, 1960–2019
We use the Penn World Table 10.0 (PWT), the standard source for comparing real income across countries. Output is real GDP at purchasing-power parities (rgdpe), and income per person is gdppc = rgdpe / pop. The prepared file applies four sample rules:
- No oil producers. Their income depends on oil prices and reserves, not on the capital accumulation that the Solow model describes.
- No very small countries. Country-years with fewer than 1 million people are dropped.
- 1960 to 2019. Reliable data for many countries start around 1960; 2019 is the last year before the pandemic in PWT 10.0.
- A balanced panel. Only countries with data in 1960 are kept. Every country is then observed in every year, so the sample does not change from one period to the next. The cost: 40 countries are dropped because their data start later, most of them in Eastern Europe and the former Soviet Union, and in Africa.
data = pd.read_csv(DATA_URL + "pwt100_convergence.csv")
print(data.shape, "|", data["country"].nunique(), "countries |", data["year"].min(), "to", data["year"].max())
data.head()
(5040, 6) | 84 countries | 1960 to 2019| ccode | country | year | pop | rgdpe | gdppc | |
|---|---|---|---|---|---|---|
| 0 | ARG | Argentina | 1960 | 20.5457 | 67106.2 | 3266.19 |
| 1 | ARG | Argentina | 1961 | 20.8791 | 70319.2 | 3367.92 |
| 2 | ARG | Argentina | 1962 | 21.2112 | 67003.7 | 3158.89 |
| 3 | ARG | Argentina | 1963 | 21.5427 | 66493.9 | 3086.62 |
| 4 | ARG | Argentina | 1964 | 21.8744 | 70992.7 | 3245.48 |
The columns are the country code (ccode), the name, the year, population in millions (pop), real GDP in millions of 2017 dollars (rgdpe) and real GDP per person (gdppc).
Look at your data. The distribution of income is very skewed: the mean is far above the median, because a few rich countries pull it up. This is one reason to work with the log of income.
print(data["gdppc"].describe().round(0))
print("skewness of gdppc:     ", round(data["gdppc"].skew(), 2))
print("skewness of log gdppc: ", round(np.log(data["gdppc"]).skew(), 2))
count 5040.0
mean 11951.0
std 14403.0
min 514.0
25% 1971.0
50% 5197.0
75% 17415.0
max 102938.0
Name: gdppc, dtype: float64
skewness of gdppc: 1.76
skewness of log gdppc: 0.12A wide table. For cross-country comparisons it is easier to have one row per country and one column per year.
Python note.
pivotreshapes a long table (one row per country-year) into a wide one.wide[1960]is then the column of all countries in 1960, andwide.loc["Japan"]the row of Japan in all years.
wide = data.pivot(index="country", columns="year", values="gdppc")
print(wide.shape)
wide[[1960, 2000, 2019]].round(0).sort_values(1960).iloc[[0, 1, 2, -3, -2, -1]]
(84, 60)| year | 1960 | 2000 | 2019 |
|---|---|---|---|
| country | |||
| Ethiopia | 514.0 | 554.0 | 2550.0 |
| Mozambique | 627.0 | 789.0 | 1169.0 |
| Mali | 641.0 | 1319.0 | 2413.0 |
| Australia | 15411.0 | 38372.0 | 50771.0 |
| United States | 18903.0 | 50090.0 | 63381.0 |
| Switzerland | 22510.0 | 48357.0 | 71859.0 |
E.4 β-convergence: do poor countries grow faster?
We now estimate equation (6) for 1960–2019. Each country gives one point: log GDP per person in 1960 on the horizontal axis and its average annual growth from 1960 to 2019 on the vertical axis.
cross_section builds this table for any start and end year, and beta_ols runs the regression. We use robust standard errors (HC1), which stay valid when the spread of the errors differs across countries.
Python note.
sm.add_constant(x)adds a column of ones, so the regression has an intercept \(a\).sm.OLS(y, X).fit(cov_type="HC1", use_t=True)runs ordinary least squares with robust standard errors and \(t\)-based p-values. The result holds.params(the estimates),.bse(standard errors),.pvaluesand.conf_int().
def cross_section(start, end):
    """One row per country: log GDP per person in the start year and average annual growth to the end year."""
    T = end - start
    table = pd.DataFrame({"country": wide.index,
                          "log_y0": np.log(wide[start]).values,
                          "growth": (np.log(wide[end] / wide[start]) / T).values})
    return table


table = cross_section(1960, 2019)
fit = sm.OLS(table["growth"], sm.add_constant(table["log_y0"])).fit(cov_type="HC1", use_t=True)
print(fit.summary().tables[1])
print(f"R-squared = {fit.rsquared:.4f}, N = {int(fit.nobs)}")
==============================================================================
coef std err t P>|t| [0.025 0.975]
------------------------------------------------------------------------------
const 0.0177 0.011 1.565 0.121 -0.005 0.040
log_y0 0.0006 0.001 0.441 0.661 -0.002 0.003
==============================================================================
R-squared = 0.0013, N = 84The slope is λ = 0.00057, positive but tiny, with a p-value of 0.66. Over the whole period, poor countries did not grow faster than rich ones: initial income explains almost none of the differences in growth (R² = 0.001).
beta_ols wraps the regression in a function that also converts the slope into the speed β with equation (7) and the half-life with equation (4). The conversion needs \(1+\lambda T>0\), and a half-life exists only for a positive speed. Otherwise the functions return “not a number” (nan).
def to_speed(lam, T):
    """Equation (7): the speed beta implied by the slope lam over T years."""
    if 1 + lam * T <= 0:
        return np.nan
    return -math.log(1 + lam * T) / T


def half_life(beta):
    """Equation (4): years to close half of the gap (only for convergence, beta > 0)."""
    return math.log(2) / beta if beta > 0 else np.nan
def beta_ols(start, end):
"""OLS of growth on log initial income (robust errors), converted to the speed and the half-life."""
table = cross_section(start, end)
fit = sm.OLS(table["growth"], sm.add_constant(table["log_y0"])).fit(cov_type="HC1", use_t=True)
T = end - start
lam = fit.params["log_y0"]
lam_lo, lam_hi = fit.conf_int().loc["log_y0"]
beta = to_speed(lam, T)
return {"start": start, "end": end, "a": fit.params["const"], "lam": lam, "se": fit.bse["log_y0"],
"p": fit.pvalues["log_y0"], "lam_lo": lam_lo, "lam_hi": lam_hi, "r2": fit.rsquared,
"beta": beta, "beta_lo": to_speed(lam_hi, T), "beta_hi": to_speed(lam_lo, T),
"half_life": half_life(beta)}Notice the last line: the upper end of the confidence interval for λ gives the lower end for β, and the other way round. A larger slope means slower convergence, so the bounds swap places.
def verdict(res):
    """Read the sign and the significance (5 percent) of the slope."""
    if res["p"] >= 0.05:
        return "no significant relation"
    return "convergence" if res["lam"] < 0 else "divergence"
def beta_figure(start=1960, end=2019):
"""Growth from start to end against log GDP per person in the start year, with the OLS line."""
if end - start < 5:
return go.Figure().update_layout(title="Choose an end year at least 5 years after the start year")
table = cross_section(start, end)
res = beta_ols(start, end)
big = table["growth"].abs().max() > 0.1 # widen the axis only when a point would leave it
fig = px.scatter(table, x="log_y0", y="growth", hover_name="country",
labels={"log_y0": f"Log GDP per person in {start}",
"growth": f"Average annual growth, {start}–{end}"},
range_x=[6, 11.6], range_y=[-0.2, 0.2] if big else [-0.04, 0.11])
fig.update_traces(marker=dict(color=BLUE, size=8, opacity=0.75))
x = np.array([6.0, 11.6])
fig.add_trace(go.Scatter(x=x, y=res["a"] + res["lam"] * x, mode="lines", name="OLS line",
line=dict(color=ORANGE, width=3)))
fig.update_layout(showlegend=False,
title=f"{start}–{end}: slope λ = {res['lam']:+.5f} (p = {res['p']:.2f}), "
f"{verdict(res)}")
return figinteract(beta_figure,
start=IntSlider(value=1960, min=1960, max=2014, step=1, description="start year", style=WIDE),
end=IntSlider(value=2019, min=1965, max=2019, step=1, description="end year", style=WIDE));Show the code of the website version
# @title Website version: move the start year (the end year is 2019)
slider_figure(beta_figure, "start", [1960, 1970, 1980, 1990, 2000, 2010], start=1960, label="start year")
Sources. Data: Penn World Table 10.0 (Feenstra, Inklaar and Timmer 2015), real GDP per person (rgdpe/pop) in 2017 dollars, 84-country balanced panel. Prepared file: data/appE/pwt100_convergence.csv (see the data notes).
Hover over a point to see the country. On the website, the slider moves the start year, and the end year stays at 2019.
What to notice.
- From 1960, the cloud of points has no slope. South Korea, Singapore and Taiwan were poor and grew by about 5 to 6 percent a year, but many other poor countries grew slowly or not at all.
- Move the start year to 2000: the line now slopes down, and the slope is significant. Since 2000, poorer countries have grown faster on average.
- The points are scattered widely around the line in every period. Initial income alone explains little of why some countries grow faster than others.
Your turn. Use beta_ols to estimate the slope for 1970–2019 and for 1980–2019. Is either significant at 5 percent? Then change the sample: keep only the countries whose 1960 income was above the median (a “club” of richer countries) and rerun the 1960–2019 regression.
Hint
beta_ols(1970, 2019)["lam"] and ["p"] give the slope and its p-value. For the club, build table = cross_section(1960, 2019), keep table[table["log_y0"] > table["log_y0"].median()], and run sm.OLS(...) on it as in the first regression cell.
# Your turn: try it hereE.5 A structural break at 2000
A single regression over 60 years can hide two different stories. We split the sample at a breakpoint, 2000 by default, and estimate equation (6) separately before and after it.
for start, end in [(1960, 2000), (2000, 2019)]:
    res = beta_ols(start, end)
    print(f"{start}-{end}: slope = {res['lam']:+.5f} (SE {res['se']:.5f}, p = {res['p']:.3f}), "
          f"speed beta = {res['beta']:+.5f}  ->  {verdict(res)}")
1960-2000: slope = +0.00437 (SE 0.00158, p = 0.007), speed beta = -0.00402 -> divergence
2000-2019: slope = -0.00352 (SE 0.00147, p = 0.019), speed beta = +0.00365 -> convergenceBefore 2000 the slope is positive and significant: rich countries grew faster, and incomes drifted apart. After 2000 it is negative and significant: poor countries grew faster. The full-period slope of about zero averages these two eras.
Python note.
make_subplots(rows=1, cols=2)makes a chart with two panels side by side. Traces go into a panel withfig.add_trace(trace, row=1, col=2).
def era_traces(start, end):
    """Scatter points and the OLS line for one era."""
    table = cross_section(start, end)
    res = beta_ols(start, end)
    points = go.Scatter(x=table["log_y0"], y=table["growth"], mode="markers", text=table["country"],
                        hovertemplate="%{text}<br>log income %{x:.2f}<br>growth %{y:.3f}<extra></extra>",
                        marker=dict(color=BLUE, size=7, opacity=0.7))
    x = np.array([6.0, 11.6])
    line = go.Scatter(x=x, y=res["a"] + res["lam"] * x, mode="lines", line=dict(color=ORANGE, width=3),
                      hoverinfo="skip")
    return points, line, res
def break_figure(breakpoint=2000):
"""beta-convergence before and after a breakpoint year, in two panels."""
titles = (f"1960–{breakpoint}", f"{breakpoint}–2019")
fig = make_subplots(rows=1, cols=2, subplot_titles=titles, shared_yaxes=True, horizontal_spacing=0.06)
words = []
for col, (start, end) in enumerate([(1960, breakpoint), (breakpoint, 2019)], start=1):
points, line, res = era_traces(start, end)
fig.add_trace(points, row=1, col=col)
fig.add_trace(line, row=1, col=col)
words.append(f"λ = {res['lam']:+.4f} ({verdict(res)})")
fig.update_xaxes(title="Log GDP per person at the start", range=[6, 11.6])
fig.update_yaxes(range=[-0.06, 0.13])
fig.update_yaxes(title="Average annual growth", col=1)
fig.update_layout(showlegend=False, title=f"Before: {words[0]}<br>After: {words[1]}",
margin=dict(t=110))
return figinteract(break_figure,
breakpoint=IntSlider(value=2000, min=1970, max=2010, step=1, description="breakpoint year", style=WIDE));Show the code of the website version
# @title Website version: move the breakpoint
fig = slider_figure(break_figure, "breakpoint", [1970, 1975, 1980, 1985, 1990, 1995, 2000, 2005, 2010],
                    start=2000, label="breakpoint year")
fig.layout.sliders[0].pad.t = 90                 # keep the slider label clear of the x-axis titles
fig
Sources. Data: Penn World Table 10.0 (Feenstra, Inklaar and Timmer 2015), real GDP per person (rgdpe/pop). Prepared file: data/appE/pwt100_convergence.csv (see the data notes).
What to notice.
- With a breakpoint at 2000, the left panel slopes up (divergence) and the right panel slopes down (convergence).
- Move the breakpoint: the right-hand panel shows significant convergence only for breakpoints between 2000 and 2008. With earlier breakpoints the slope is negative from 1990 on, but not significant. The turn to catch-up growth is recent.
- Hover over the right-hand panel: Ethiopia, Romania, India and Bangladesh were among the fastest growers after 2000, at about 6 to 8 percent a year.
Your turn. Choosing a breakpoint after looking at the data is risky: we may find a “break” that is only noise. Try breakpoints of 1990 and 2008. Is the post-break slope significant in each case? What does this tell you about how sure we can be that 2000 is “the” turning point?
Hint
beta_ols(1990, 2019) and beta_ols(2008, 2019) give the post-break slopes and p-values. Compare them with beta_ols(2000, 2019).
# Your turn: try it hereE.6 From the slope to the speed: the OLS route
The slope λ depends on the length of the period, so slopes from periods of different lengths cannot be compared directly. The speed β can: it is a rate per year. We convert each slope with equation (7) and add the half-life from equation (4), for six periods.
periods = [(1960, 2019), (1960, 2000), (1980, 2019), (1990, 2019), (1995, 2019), (2000, 2019)]
rows = []
for start, end in periods:
    res = beta_ols(start, end)
    rows.append({"period": f"{start}–{end}", "slope": res["lam"], "p-value": res["p"],
                 "speed": res["beta"], "speed (% a year)": 100 * res["beta"],
                 "half-life (years)": res["half_life"], "verdict": verdict(res)})
speeds = pd.DataFrame(rows)
speeds.round({"slope": 5, "p-value": 3, "speed": 5, "speed (% a year)": 2, "half-life (years)": 0})| period | slope | p-value | speed | speed (% a year) | half-life (years) | verdict | |
|---|---|---|---|---|---|---|---|
| 0 | 1960–2019 | 0.00057 | 0.661 | -0.00056 | -0.06 | NaN | no significant relation |
| 1 | 1960–2000 | 0.00437 | 0.007 | -0.00402 | -0.40 | NaN | divergence |
| 2 | 1980–2019 | 0.00113 | 0.415 | -0.00111 | -0.11 | NaN | no significant relation |
| 3 | 1990–2019 | -0.00008 | 0.954 | 0.00008 | 0.01 | 8530.0 | no significant relation |
| 4 | 1995–2019 | -0.00178 | 0.206 | 0.00182 | 0.18 | 381.0 | no significant relation |
| 5 | 2000–2019 | -0.00352 | 0.019 | 0.00365 | 0.36 | 190.0 | convergence |
fig = px.bar(speeds, x="period", y="speed (% a year)", color="verdict", text_auto=".2f",
             color_discrete_map={"convergence": BLUE, "divergence": ORANGE,
                                 "no significant relation": GRAY},
             labels={"period": "Period", "speed (% a year)": "Speed of convergence β (% a year)"},
             category_orders={"period": list(speeds["period"])},         # keep the periods in table order
             title="The speed of convergence is far below the 2 percent benchmark", range_y=[-1, 2.5])
fig.add_hline(y=2, line=dict(color=TEAL, dash="dash"))
fig.add_annotation(x=5, y=2, text="2% benchmark (half-life 35 years)", yshift=12, showarrow=False,
                   xanchor="right")
fig.update_layout(legend_title_text="")
fig
Sources. Data: Penn World Table 10.0 (Feenstra, Inklaar and Timmer 2015), real GDP per person (rgdpe/pop). Prepared file: data/appE/pwt100_convergence.csv (see the data notes). The 2 percent benchmark is the speed of conditional convergence in Barro and Sala-i-Martin (1992).
What to notice.
- Only 2000–2019 shows significant convergence, at 0.36 percent a year: a half-life of about 190 years. At this pace it would take almost two centuries to close half of today’s income gaps.
- 1960–2000 shows divergence: a negative speed of −0.40 percent a year.
- The Solow model with α = 1/3 predicts more than 5 percent a year. Absolute convergence in the data is more than ten times slower. Countries do not share one steady state.
Your turn. Compute the speed and the half-life for 2005–2019. Is it faster or slower than for 2000–2019?
Hint
res = beta_ols(2005, 2019), then print res["beta"], res["half_life"] and res["p"].
# Your turn: try it hereE.7 Estimating the speed directly: nonlinear least squares
Equation (6) is linear in λ but nonlinear in β: β sits inside an exponential. OLS can only estimate λ, which is why we converted. Nonlinear least squares (NLS) estimates β directly. It searches for the values of \(a\) and β that make the sum of squared errors as small as possible:
\[\min_{a,\beta}\ \sum_i\left[g_i-a+\frac{1-e^{-\beta T}}{T}\ln y_{i,0}\right]^2.\]
There is no formula for the answer, so the computer finds it step by step, starting from a first guess. SciPy’s optimize.curve_fit does this.
Robust standard errors for NLS. Near the solution, NLS behaves like OLS on the derivatives of the model with respect to its parameters. We collect them in a matrix \(J\) (one row per country, one column per parameter) and apply the same robust “sandwich” formula that statsmodels uses for HC1: \((J'J)^{-1}\,J'\,\text{diag}(e_i^2)\,J\,(J'J)^{-1}\) times \(N/(N-2)\), where \(e_i\) are the residuals.
Python note. A function can be defined inside another function. Here
bsm(for Barro–Sala-i-Martin) needsT, which it takes from the outer function.optimize.curve_fit(f, x, y, p0=...)returns the best parameters and a covariance matrix, starting from the guessp0. In NumPy,@multiplies matrices,.Ttransposes, andnp.linalg.invinverts.
def beta_nls(start, end):
    """Estimate the speed beta directly by NLS (the slope formula of equation (6)), with robust errors."""
    table = cross_section(start, end)
    x, growth = table["log_y0"].values, table["growth"].values
    T = end - start

    def bsm(x, a, beta):
        """Average growth predicted by equation (6)."""
        return a - (1 - np.exp(-beta * T)) / T * x

    (a, beta), _ = optimize.curve_fit(bsm, x, growth, p0=[0.0, 0.0])
    resid = growth - bsm(x, a, beta)
    J = np.column_stack([np.ones_like(x), -x * np.exp(-beta * T)])   # d(bsm)/da and d(bsm)/d(beta)
    bread = np.linalg.inv(J.T @ J)
    meat = (J * resid[:, None] ** 2).T @ J
    N = len(x)
    se = math.sqrt((bread @ meat @ bread)[1, 1] * N / (N - 2))
    t_crit = stats.t.ppf(0.975, N - 2)
    p = 2 * stats.t.sf(abs(beta / se), N - 2)
    return {"beta": beta, "se": se, "p": p, "beta_lo": beta - t_crit * se, "beta_hi": beta + t_crit * se}


res = beta_nls(2000, 2019)
print(f"NLS, 2000-2019: beta = {res['beta']:.5f} (SE {res['se']:.5f}, p = {res['p']:.3f}), "
      f"95% CI [{res['beta_lo']:.5f}, {res['beta_hi']:.5f}], half-life {half_life(res['beta']):.0f} years")
NLS, 2000-2019: beta = 0.00365 (SE 0.00157, p = 0.023), 95% CI [0.00052, 0.00678], half-life 190 yearsDo the two routes agree? Equation (7) is an exact one-to-one transformation of λ. So NLS must find the same β as the OLS route, up to the tolerance of the numerical search.
rows = []
for start, end in periods:
    ols_res, nls_res = beta_ols(start, end), beta_nls(start, end)
    rows.append({"period": f"{start}–{end}", "speed, OLS route": ols_res["beta"],
                 "speed, NLS": nls_res["beta"], "difference": nls_res["beta"] - ols_res["beta"],
                 "NLS p-value": nls_res["p"], "NLS low": nls_res["beta_lo"], "NLS high": nls_res["beta_hi"]})
compare = pd.DataFrame(rows)
compare| period | speed, OLS route | speed, NLS | difference | NLS p-value | NLS low | NLS high | |
|---|---|---|---|---|---|---|---|
| 0 | 1960–2019 | -0.000560 | -0.000560 | -6.522648e-10 | 0.655292 | -0.003044 | 0.001925 |
| 1 | 1960–2000 | -0.004024 | -0.004024 | -1.011096e-12 | 0.003753 | -0.006707 | -0.001341 |
| 2 | 1980–2019 | -0.001105 | -0.001105 | -3.819854e-10 | 0.405438 | -0.003734 | 0.001524 |
| 3 | 1990–2019 | 0.000081 | 0.000081 | -3.696454e-10 | 0.953811 | -0.002701 | 0.002863 |
| 4 | 1995–2019 | 0.001818 | 0.001818 | -6.337513e-11 | 0.216045 | -0.001083 | 0.004718 |
| 5 | 2000–2019 | 0.003646 | 0.003646 | 1.433467e-11 | 0.023018 | 0.000515 | 0.006777 |
The point estimates agree to about nine decimal places, as they must. The standard errors and p-values differ a little: NLS measures the uncertainty of β directly, while the OLS route measures it for λ.
fig = px.scatter(compare, x="period", y=100 * compare["speed, NLS"],
                 error_y=100 * (compare["NLS high"] - compare["speed, NLS"]),
                 labels={"period": "Period", "y": "Speed of convergence β (% a year)"},
                 title="NLS estimates of the speed of convergence with 95% confidence intervals",
                 range_y=[-1, 2.5])
fig.update_traces(marker=dict(color=BLUE, size=12), error_y=dict(color=BLUE, thickness=2))
fig.add_hline(y=0, line=dict(color=GRAY))
fig.add_hline(y=2, line=dict(color=TEAL, dash="dash"))
fig.add_annotation(x=5, y=2, text="2% benchmark", yshift=12, showarrow=False, xanchor="right")
fig
Sources. Data: Penn World Table 10.0 (Feenstra, Inklaar and Timmer 2015), real GDP per person (rgdpe/pop). Prepared file: data/appE/pwt100_convergence.csv (see the data notes).
What to notice.
- Only the 2000–2019 interval lies entirely above zero. Even its upper end, about 0.7 percent a year, is far below the 2 percent benchmark.
- 1960–2000 lies entirely below zero: significant divergence.
Your turn. NLS starts its search from a guess, p0=[0.0, 0.0]. Copy the body of beta_nls for 2000–2019 and start from p0=[0.1, 0.05] instead. Do you get the same β?
Hint
For a well-behaved problem such as this one, the search ends at the same minimum from any reasonable start. Compare the results to five decimals.
# Your turn: try it hereE.8 Rolling windows: when did convergence start?
The breakpoint of E.5 was chosen by us. A rolling window lets the data speak: keep the end year at 2019, move the start year forward one year at a time from 1960 to 2010, and re-estimate each time. The shortest window is 9 years. For each window we keep the slope λ with its 95% confidence interval, the speed β from the OLS route with the swapped bounds, and the NLS speed with its own interval.
Python note. Building a table row by row is a common pattern: start with an empty list
rows, add one dictionary per window withrows.append({...}), and turn the list into a DataFrame at the end.
def rolling_table(end=2019, shortest=9):
    """Slope, OLS-route speed and NLS speed for every start year from 1960 to end - shortest."""
    rows = []
    for start in range(1960, end - shortest + 1):
        ols_res, nls_res = beta_ols(start, end), beta_nls(start, end)
        rows.append({"start": start, "lam": ols_res["lam"], "lam_lo": ols_res["lam_lo"],
                     "lam_hi": ols_res["lam_hi"], "beta": ols_res["beta"], "beta_lo": ols_res["beta_lo"],
                     "beta_hi": ols_res["beta_hi"], "nls": nls_res["beta"], "nls_lo": nls_res["beta_lo"],
                     "nls_hi": nls_res["beta_hi"], "p": ols_res["p"], "half_life": ols_res["half_life"]})
    return pd.DataFrame(rows)


rolling = rolling_table()
rolling[rolling["start"] % 5 == 0][["start", "lam", "p", "beta", "beta_lo", "beta_hi", "half_life"]].round(5)| start | lam | p | beta | beta_lo | beta_hi | half_life | |
|---|---|---|---|---|---|---|---|
| 0 | 1960 | 0.00057 | 0.66056 | -0.00056 | -0.00288 | 0.00213 | NaN |
| 5 | 1965 | 0.00055 | 0.66336 | -0.00054 | -0.00284 | 0.00208 | NaN |
| 10 | 1970 | 0.00099 | 0.44651 | -0.00097 | -0.00329 | 0.00165 | NaN |
| 15 | 1975 | 0.00130 | 0.32467 | -0.00127 | -0.00361 | 0.00135 | NaN |
| 20 | 1980 | 0.00113 | 0.41544 | -0.00111 | -0.00361 | 0.00167 | NaN |
| 25 | 1985 | 0.00210 | 0.16471 | -0.00202 | -0.00468 | 0.00089 | NaN |
| 30 | 1990 | -0.00008 | 0.95376 | 0.00008 | -0.00259 | 0.00298 | 8530.35592 |
| 35 | 1995 | -0.00178 | 0.20615 | 0.00182 | -0.00099 | 0.00482 | 381.33562 |
| 40 | 2000 | -0.00352 | 0.01872 | 0.00365 | 0.00060 | 0.00687 | 190.09962 |
| 45 | 2005 | -0.00428 | 0.01309 | 0.00441 | 0.00093 | 0.00807 | 157.17236 |
| 50 | 2010 | -0.00305 | 0.13541 | 0.00309 | -0.00097 | 0.00730 | 224.33946 |
MEASURES = {"slope λ (OLS)": ("lam", "Slope λ"),
            "speed β (OLS route)": ("beta", "Speed of convergence β"),
            "speed β (NLS)": ("nls", "Speed of convergence β")}


def rolling_figure(measure="speed β (OLS route)", end=2019):
    """One estimate per start year (end year fixed), with its 95% confidence band."""
    table = rolling_table(end)
    col, axis_title = MEASURES[measure]
    fig = go.Figure()
    fig.add_trace(go.Scatter(x=list(table["start"]) + list(table["start"])[::-1],
                             y=list(table[col + "_hi"]) + list(table[col + "_lo"])[::-1],
                             fill="toself", fillcolor="rgba(22, 82, 140, 0.15)", line=dict(width=0),
                             hoverinfo="skip", name="95% confidence interval"))
    fig.add_trace(go.Scatter(x=table["start"], y=table[col], mode="lines+markers", name=measure,
                             line=dict(color=BLUE, width=3), marker=dict(size=5),
                             hovertemplate="start %{x}<br>%{y:.5f}<extra></extra>"))
    fig.add_hline(y=0, line=dict(color=GRAY))
    big = table[[col + "_lo", col + "_hi"]].abs().max().max() > 0.012
    fig.update_layout(title=f"Rolling {measure}, start year moves forward, end year {end}",
                      xaxis=dict(title="Start year", range=[1959, 2011]),
                      yaxis=dict(title=axis_title, range=[-0.03, 0.03] if big else [-0.012, 0.012]),
                      showlegend=False)
    return fig
interact(rolling_figure,
measure=ToggleButtons(options=list(MEASURES), value="speed β (OLS route)", description="estimate",
style=WIDE),
end=Dropdown(options=[2000, 2005, 2008, 2010, 2015, 2019], value=2019, description="end year",
style=WIDE));Show the code of the website version
# @title Website version: switch between the three estimates (end year 2019)
button_figure(rolling_figure, "measure", list(MEASURES), start="speed β (OLS route)")
Sources. Data: Penn World Table 10.0 (Feenstra, Inklaar and Timmer 2015), real GDP per person (rgdpe/pop). Prepared file: data/appE/pwt100_convergence.csv (see the data notes).
What to notice.
- The slope λ is the mirror image of the speed β: when one is above zero, the other is below.
- For start years up to the late 1980s, the band contains zero: no significant convergence. From the late 1990s on, the whole band lies above zero for the speed.
- The speed peaks for windows that start in 2008, at about 0.5 percent a year (half-life about 130 years), and falls for later starts, whose windows are short and noisy.
- The OLS-route and NLS lines are identical. Only their bands differ slightly.
Your turn. Set the end year to 2008 in the widget, before the global financial crisis. Does convergence still show up for start years around 2000?
Hint
In code: rolling_table(2008), then look at the rows with start from 1995 to 1999 and their p-values p.
# Your turn: try it hereE.9 σ-convergence: are incomes becoming more equal?
β-convergence asks whether poor countries grow faster. σ-convergence asks a different question: is the spread of incomes across countries shrinking? We measure the spread with the sample variance of log GDP per person across the \(N\) countries in year \(t\):
\[\sigma_t^2=\frac{1}{N-1}\sum_{i=1}^{N}\left(\ln y_{i,t}-\overline{\ln y_t}\right)^2. \tag{8}\]
Logs make the measure independent of units and of the overall level of income: if every country became twice as rich, the variance would not change.
How precise is it? If log incomes are roughly normal, \((N-1)\sigma_t^2\) divided by the true variance follows a \(\chi^2\) distribution with \(N-1\) degrees of freedom. This gives a 95% confidence interval:
\[\left[\frac{(N-1)\,\sigma_t^2}{\chi^2_{0.975,\,N-1}},\ \frac{(N-1)\,\sigma_t^2}{\chi^2_{0.025,\,N-1}}\right]. \tag{9}\]
def variance_ci(values):
    """Equations (8) and (9): sample variance of log income and its 95% chi-squared interval."""
    logs = np.log(values)
    N = len(logs)
    v = logs.var()                               # pandas divides by N - 1
    low = (N - 1) * v / stats.chi2.ppf(0.975, N - 1)
    high = (N - 1) * v / stats.chi2.ppf(0.025, N - 1)
    return v, low, high


rows = []
for year in wide.columns:
    v, low, high = variance_ci(wide[year])
    rows.append({"year": year, "variance": v, "low": low, "high": high, "sd": math.sqrt(v)})
sigma = pd.DataFrame(rows)
sigma[sigma["year"].isin([1960, 2019])].round(3)| year | variance | low | high | sd | |
|---|---|---|---|---|---|
| 0 | 1960 | 0.924 | 0.697 | 1.285 | 0.961 |
| 59 | 2019 | 1.764 | 1.330 | 2.452 | 1.328 |
The variance rose from 0.92 in 1960 to 1.76 in 2019, an increase of 91 percent. The standard deviation rose from 0.96 to 1.33 log points. The two confidence intervals do not overlap: incomes in 2019 were clearly more unequal across these countries than in 1960.
def sigma_bar_figure(year_a=1960, year_b=2019):
    """The variance of log GDP per person in two years, with 95% confidence intervals."""
    if year_a >= year_b:
        return go.Figure().update_layout(title="Choose a second year after the first year")
    two = sigma[sigma["year"].isin([year_a, year_b])].copy()
    two["label"] = two["year"].astype(str)
    two["plus"] = two["high"] - two["variance"]
    two["minus"] = two["variance"] - two["low"]
    change = 100 * (two["variance"].iloc[-1] / two["variance"].iloc[0] - 1)
    fig = px.bar(two, x="label", y="variance", error_y="plus", error_y_minus="minus", text_auto=".3f",
                 labels={"label": "Year", "variance": "Variance of log GDP per person"},
                 range_y=[0, 2.8], title=f"Variance of log GDP per person, {year_a} to {year_b}: {change:+.0f}%")
    fig.update_traces(marker_color=[GRAY, BLUE], textposition="inside", insidetextanchor="start", width=0.5)
    fig.update_xaxes(type="category")            # the years are labels, not numbers
    return fig
interact(sigma_bar_figure,
year_a=IntSlider(value=1960, min=1960, max=2018, step=1, description="first year", style=WIDE),
year_b=IntSlider(value=2019, min=1961, max=2019, step=1, description="second year", style=WIDE));Show the code of the website version
# @title Website version: compare 1960 with a later year
slider_figure(sigma_bar_figure, "year_b", [1970, 1980, 1990, 2000, 2006, 2010, 2019], start=2019,
              label="second year")
Sources. Data: Penn World Table 10.0 (Feenstra, Inklaar and Timmer 2015), real GDP per person (rgdpe/pop). Prepared file: data/appE/pwt100_convergence.csv (see the data notes).
What to notice.
- Compared with 1960, the variance is higher in every later year: there was σ-divergence over the whole period.
- Comparing 2006 with 2019 (set the first year to 2006 in the widget) shows a small fall in the variance. The confidence intervals overlap widely, so this recent narrowing is not yet statistically clear.
Your turn. The variance is one measure of spread. Compute another one: the ratio of GDP per person of the 90th to the 10th percentile country in 1960 and in 2019. Does it tell the same story?
Hint
wide[1960].quantile(0.9) / wide[1960].quantile(0.1), and the same for 2019.
# Your turn: try it hereE.10 Why β-convergence is not enough
Since 2000, poor countries have grown faster, so why has the variance fallen so little? Because β-convergence is necessary for σ-convergence, but not sufficient. Write equation (6) as a statement about levels: \(\ln y_{i,T}=\ln y_{i,0}+T g_i=Ta+(1+\lambda T)\ln y_{i,0}+T\varepsilon_i\). OLS residuals are uncorrelated with the regressor, so the variance across countries splits into two parts:
\[\sigma_T^2=(1+\lambda T)^2\,\sigma_0^2+T^2\,\text{Var}(\varepsilon). \tag{10}\]
The first term shrinks the spread when λ < 0: catch-up pulls countries together. The second term spreads them apart: new country-specific shocks (wars, crises, booms, good or bad policies) keep pushing countries away from the line. The variance falls only if catch-up is strong enough to beat the new shocks.
Check equation (10) with the data, for 2000–2019.
start, end = 2000, 2019
T = end - start
table = cross_section(start, end)
res = beta_ols(start, end)
resid = table["growth"] - (res["a"] + res["lam"] * table["log_y0"])
pull = (1 + res["lam"] * T) ** 2 * table["log_y0"].var()
push = T ** 2 * resid.var()
print(f"variance in {start}:                 {table['log_y0'].var():.4f}")
print(f"catch-up term (1 + lam T)^2 * var_0: {pull:.4f}")
print(f"shock term T^2 * var(residuals):     {push:.4f}")
print(f"sum = predicted variance in {end}:   {pull + push:.4f}")
print(f"actual variance in {end}:            {np.log(wide[end]).var():.4f}")
variance in 2000: 1.8937
catch-up term (1 + lam T)^2 * var_0: 1.6487
shock term T^2 * var(residuals): 0.1148
sum = predicted variance in 2019: 1.7635
actual variance in 2019: 1.7635Catch-up alone would have lowered the variance from 1.89 to about 1.65. New shocks added about 0.11, so the variance ended at 1.76. The identity holds exactly.
Decade by decade. The table shows the slope for each decade next to the variance at the start of the decade. The last decade is nine years long, because the data end in 2019.
rows = []
for start in range(1960, 2020, 10):
    end = min(start + 10, 2019)
    res = beta_ols(start, end)
    rows.append({"decade": f"{start}–{end}", "slope": res["lam"], "p-value": res["p"],
                 "verdict": verdict(res), "variance at start": sigma.loc[sigma["year"] == start, "variance"].iloc[0]})
decades = pd.DataFrame(rows)
decades.round({"slope": 5, "p-value": 3, "variance at start": 3})| decade | slope | p-value | verdict | variance at start | |
|---|---|---|---|---|---|
| 0 | 1960–1970 | 0.00594 | 0.001 | divergence | 0.924 |
| 1 | 1970–1980 | 0.00555 | 0.009 | divergence | 1.082 |
| 2 | 1980–1990 | 0.00686 | 0.000 | divergence | 1.289 |
| 3 | 1990–2000 | 0.00882 | 0.000 | divergence | 1.538 |
| 4 | 2000–2010 | -0.00379 | 0.055 | no significant relation | 1.894 |
| 5 | 2010–2019 | -0.00305 | 0.135 | no significant relation | 1.826 |
fig = make_subplots(rows=1, cols=2, subplot_titles=("Slope λ in each decade", "Variance at the start"))
colors = []
for lam in decades["slope"]:
    colors.append(ORANGE if lam > 0 else BLUE)            # orange = divergence, blue = convergence
fig.add_trace(go.Bar(x=decades["decade"], y=decades["slope"], marker_color=colors,
                     hovertemplate="%{x}<br>slope %{y:.5f}<extra></extra>"), row=1, col=1)
fig.add_trace(go.Bar(x=decades["decade"], y=decades["variance at start"], marker_color=TEAL,
                     hovertemplate="%{x}<br>variance %{y:.3f}<extra></extra>"), row=1, col=2)
fig.update_yaxes(range=[-0.006, 0.0105], row=1, col=1)
fig.update_yaxes(range=[0, 2.2], row=1, col=2)
fig.update_layout(showlegend=False, title="Divergence until 2000 and convergence after; the variance stopped rising")
fig
Sources. Data: Penn World Table 10.0 (Feenstra, Inklaar and Timmer 2015), real GDP per person (rgdpe/pop). Prepared file: data/appE/pwt100_convergence.csv (see the data notes).
What to notice.
- Every decade from 1960 to 2000 had a positive, significant slope (orange): divergence, and a rising variance.
- The slopes of the 2000s and 2010s are negative (blue), and the variance stopped rising. The p-values of these two decades, 0.055 and 0.135, show that a single decade of data is a weak test.
Your turn. The Solow model predicts conditional convergence. Add a control for the steady state: the average population growth rate of each country, \(\bar{n}_i\), which lowers \(\hat{y}^*\) in the model. Following Mankiw, Romer and Weil (1992), regress growth from 1960 to 2019 on \(\ln y_{i,1960}\) and \(\ln(\bar{n}_i+0.05)\). Is the slope on initial income now negative?
Hint
Build pop = data.pivot(index="country", columns="year", values="pop") and n_avg = np.log(pop[2019] / pop[1960]) / 59. Add the column np.log(n_avg + 0.05).values to the table from cross_section(1960, 2019), and pass both regressors: sm.add_constant(table[["log_y0", "log_ngd"]]).
# Your turn: try it hereE.11 σ over time
The two-year comparison hides the path in between. This chart plots the variance in every year with its 95% confidence band.
peak = sigma.loc[sigma["variance"].idxmax()]
fig = px.line(sigma, x="year", y="variance", markers=True,
              labels={"year": "Year", "variance": "Variance of log GDP per person"},
              title=f"σ-divergence until {int(peak['year'])}, a slight narrowing since", range_y=[0, 2.9])
fig.add_trace(go.Scatter(x=list(sigma["year"]) + list(sigma["year"])[::-1],
                         y=list(sigma["high"]) + list(sigma["low"])[::-1], fill="toself",
                         fillcolor="rgba(22, 82, 140, 0.15)", line=dict(width=0), hoverinfo="skip",
                         showlegend=False))
fig.update_traces(line=dict(color=BLUE, width=3), marker=dict(size=5), selector=dict(mode="lines+markers"))
fig.add_annotation(x=peak["year"], y=peak["variance"], text=f"peak {peak['variance']:.3f} in {int(peak['year'])}",
                   ay=-40, ax=-60, arrowcolor=GRAY)
fig
Sources. Data: Penn World Table 10.0 (Feenstra, Inklaar and Timmer 2015), real GDP per person (rgdpe/pop). Prepared file: data/appE/pwt100_convergence.csv (see the data notes).
What to notice.
- The variance roughly doubled between 1960 and the mid-2000s, rising in most years.
- It peaked at 1.93 in 2006 and was about 8 percent lower by 2019. This matches the β-convergence found since
- Even after the decline, the 2019 variance is far above its 1960 level. At a speed of 0.4 percent a year, it would take generations to undo the divergence of 1960–2000.
Your turn. Plot the standard deviation (sd) instead of the variance. In which year was it highest?
Hint
px.line(sigma, x="year", y="sd"), and sigma.loc[sigma["sd"].idxmax()].
# Your turn: try it hereE.12 Convergence heatmaps: every start and end year
Rolling windows fix the end year. A heatmap goes all the way: it estimates the speed for every pair of start and end years between 1960 and 2019, \(60\times59/2=1{,}770\) regressions. Each cell is one period, colored blue for convergence and red for divergence.
Python note. Two nested loops visit every pair: the outer loop runs over start years, and the inner loop over the end years after it.
try/except RuntimeErrorcatches the rare case in which the NLS search does not converge, and recordsnaninstead of stopping the whole loop. This cell runs a few seconds.
rows = []
for start in range(1960, 2019):
    for end in range(start + 1, 2020):
        table = cross_section(start, end)
        lam = np.polyfit(table["log_y0"], table["growth"], 1)[0]   # OLS slope (no standard errors needed)
        try:
            nls = beta_nls(start, end)["beta"]
        except RuntimeError:
            nls = np.nan
        rows.append({"start": start, "end": end, "lam": lam, "beta_ols": to_speed(lam, end - start),
                     "beta_nls": nls})
heat = pd.DataFrame(rows)
print(len(heat), "periods;", heat["beta_nls"].isna().sum(), "failed NLS searches")
print("largest gap between the two routes:", (heat["beta_nls"] - heat["beta_ols"]).abs().max())
print(f"share of periods with convergence (beta > 0): {(heat['beta_ols'] > 0).mean():.0%}")
1770 periods; 0 failed NLS searches
largest gap between the two routes: 1.46004948631262e-07
share of periods with convergence (beta > 0): 16%HEAT = {"speed β (OLS route)": ("beta_ols", "β, % a year"), "speed β (NLS)": ("beta_nls", "β, % a year"),
"slope λ (OLS)": ("lam", "λ × 100")}
def heatmap_figure(measure="speed β (OLS route)"):
"""One cell per start and end year, colored by the estimate (blue = convergence)."""
col, unit = HEAT[measure]
grid = heat.pivot(index="start", columns="end", values=col) * 100
scale = "RdBu_r" if col == "lam" else "RdBu" # blue is convergence in both cases
fig = go.Figure(go.Heatmap(z=grid.values, x=grid.columns, y=grid.index, colorscale=scale, zmid=0,
zmin=-1, zmax=1, colorbar=dict(title=unit),
hovertemplate="start %{y}, end %{x}<br>%{z:.2f}<extra></extra>"))
fig.update_layout(title=f"Convergence heatmap: {measure}, every period from 1960 to 2019",
xaxis=dict(title="End year", range=[1960.5, 2019.5]),
yaxis=dict(title="Start year", range=[1959.5, 2018.5]), height=600)
return figinteract(heatmap_figure,
measure=ToggleButtons(options=list(HEAT), value="speed β (OLS route)", description="estimate",
style=WIDE));Show the code of the website version
# @title Website version: switch between the three estimates
button_figure(heatmap_figure, "measure", list(HEAT), start="speed β (OLS route)")
Sources. Data: Penn World Table 10.0 (Feenstra, Inklaar and Timmer 2015), real GDP per person (rgdpe/pop). Prepared file: data/appE/pwt100_convergence.csv (see the data notes).
Colors are capped at ±1 percent a year, so that the many small values stay visible; hover over a cell for its exact value.
What to notice.
- Most of the triangle is red: only about one period in six shows convergence. Periods that start before the 1990s are divergent almost everywhere.
- The blue region is the top-right corner: periods that start around or after 2000. This is the convergence era of E.5 and E.8, seen from every angle.
- Cells near the diagonal are periods of one or a few years. Their colors jump around, because short-run shocks dominate short periods.
- The OLS-route and NLS heatmaps are identical, and the λ heatmap is their mirror image.
Your turn. Which period of at least 10 years shows the fastest convergence, and which the fastest divergence?
Hint
Keep long = heat[heat["end"] - heat["start"] >= 10], then use long.loc[long["beta_ols"].idxmax()] and long.loc[long["beta_ols"].idxmin()].
# Your turn: try it hereE.13 Discussion and summary
What we found.
- No absolute convergence over 1960–2019. The slope of growth on initial income is about zero. Poor countries as a group did not catch up.
- Two eras. From 1960 to 2000 incomes diverged: richer countries grew faster. From 2000 on, poorer countries grew faster, a shift that rolling windows and heatmaps confirm from every angle.
- Slow convergence. Even in the recent era, the speed is about 0.4 percent a year, a half-life of almost two centuries. That is far below the 2 percent of conditional-convergence studies, and the more than 5 percent of the Solow model with α = 1/3.
- OLS and NLS agree. The two routes to β give the same estimate, because equation (7) is an exact transformation.
- σ-divergence, then a pause. The variance of log income nearly doubled up to 2006 and has fallen only about 8 percent since. β-convergence is necessary for σ-convergence, but new shocks can offset it, as equation (10) shows.
What this means for the Solow model. The model does not predict that all countries converge. It predicts that each country converges to its own steady state, set by its investment rate, population growth and technology (Chapter 5 and Chapter 6). Absolute convergence is a test of the extra assumption that steady states are the same everywhere. The data reject that assumption for 1960–2000.
Limitations and next steps.
- Conditional convergence. Adding controls for the steady state (investment, schooling, population growth, institutions) usually turns the slope negative; the Your-turn task in E.10 is a first step.
- Sample selection. The balanced panel drops 40 countries whose data start after 1960, many of them poor. Results for an unbalanced or larger sample can differ.
- Convergence clubs. Groups of countries may converge to different steady states: rich countries to one, poor countries to another. Club-convergence methods look for these groups in the data.
- Galton’s fallacy. A negative slope can arise from regression toward the mean, even when the distribution is not narrowing. This is why σ-convergence must be checked separately (Quah 1993).
Common errors and how to fix them
| Problem | Why it happens | Fix |
|---|---|---|
| The slope is positive, but you expected convergence | A positive λ means divergence in equation (6) | Convergence means λ < 0 and β > 0 |
to_speed returns nan |
\(1+\lambda T\le 0\): the slope is too negative for its period length | Check the period length; this happens only with extreme slopes |
The half-life is nan |
There is no half-life under divergence (β ≤ 0) | Report the speed and say “divergence” |
| The β confidence interval is upside down | The bounds of λ map to the opposite bounds of β | Take beta_lo from lam_hi, as beta_ols does |
| Different p-values from another program | Robust standard errors come in several versions (HC0 to HC3) | Use cov_type="HC1" and use_t=True, the common default |
curve_fit warns or fails |
A poor starting guess or a flat sum of squares | Start from p0=[0.0, 0.0] or from the OLS-route β |
| Growth computed in percent and in decimals mixed | λ and β depend on the units of growth | Keep growth in decimals (0.02 = 2 percent) |
KeyError: 2020 |
The data end in 2019 | Use years from 1960 to 2019 |
Where to learn more
- The Stata original: Carlos Mendez, Beta and Sigma Convergence Across Countries: A Stata Tutorial, which this appendix follows with Python code.
- The classic paper on convergence speeds: Barro, R. J., and X. Sala-i-Martin (1992), “Convergence,” Journal of Political Economy 100(2), 223–251. Their book Economic Growth (MIT Press, 2nd ed. 2004) derives the speed of convergence in detail.
- Conditional convergence and the augmented Solow model: Mankiw, N. G., D. Romer and D. N. Weil (1992), “A Contribution to the Empirics of Economic Growth,” Quarterly Journal of Economics 107(2), 407–437.
- Why β is not enough: Quah, D. (1993), “Galton’s Fallacy and Tests of the Convergence Hypothesis,” Scandinavian Journal of Economics 95(4), 427–443.
- The data: Feenstra, R. C., R. Inklaar and M. P. Timmer (2015), “The Next Generation of the Penn World Table,” American Economic Review 105(10), 3150–3182.
- The tools: the statsmodels regression guide and SciPy’s
curve_fit.
Concluding remarks
- The Solow model predicts that an economy closes a share \(\beta=(1-\alpha)(\bar{n}+\bar{g}+\bar{d})\) of its log gap to the steady state each year, equation (2), with a half-life of \(\ln 2/\beta\), equation (4). With α = 1/3 this is fast: a half-life of about 13 years.
- The Barro–Sala-i-Martin equation (5) turns the prediction into a regression of growth on log initial income, and equation (7) converts the slope into a speed. NLS estimates the speed directly and gives the same answer.
- In 84 countries, there was no absolute convergence over 1960–2019: divergence until 2000, and slow convergence, about 0.4 percent a year, since then.
- The variance of log income, equation (8), nearly doubled until 2006 and has barely fallen since. Equation (10) explains why β-convergence does not guarantee σ-convergence.
- Countries do not share one steady state. Growth policy is about raising a country’s own steady state (its investment, education, technology and institutions), which is the subject of Chapters 4 to 6.